Phonon TTS: Gradium's Offline Voice Model Explained
Gradium's Phonon is a family of small open text-to-speech models that run on your device. Which model to pick, licenses, benchmarks and how to try it.
Gradium's Phonon is a family of small open text-to-speech models that run on your device. Which model to pick, licenses, benchmarks and how to try it.
Viggle Remake adds two open LoRAs to MiniMax H3 that recast people and edit objects, weather and light in existing video, plus an MCP agent for whole films.
Video Rebirth's HyperFlow H3 Flash shrinks MiniMax H3 to about 14B parameters and 6 steps, for video with stereo audio on one 24 GB or 32 GB GPU.
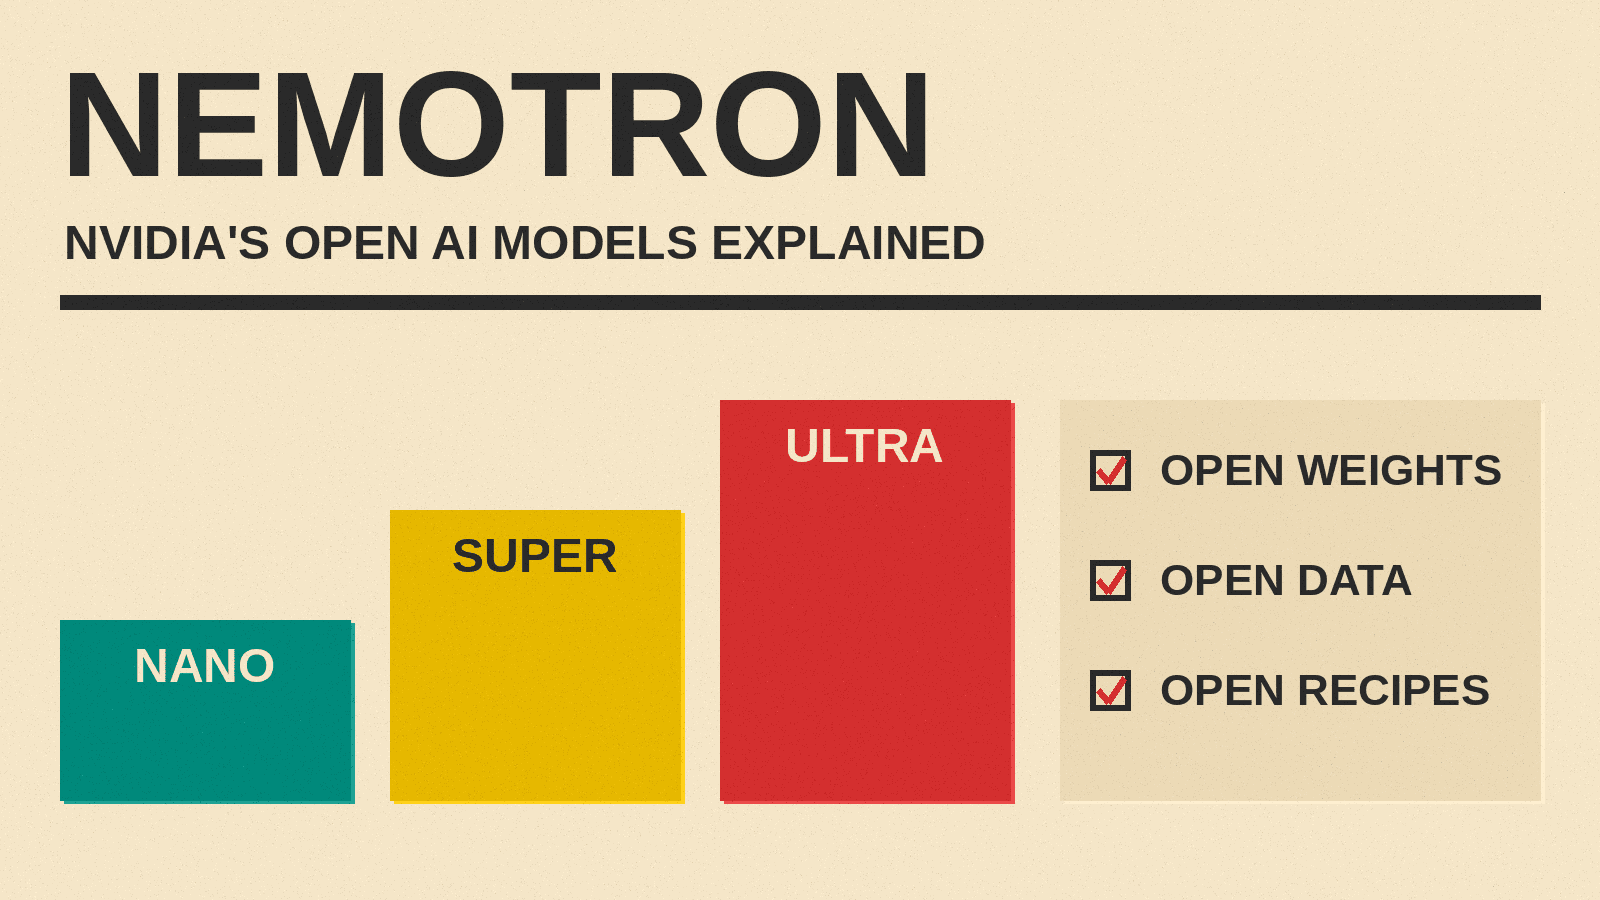
Nemotron is NVIDIA's family of open models for AI agents. See the Nano, Super and Ultra tiers, the open training data NVIDIA shares, and the license terms.
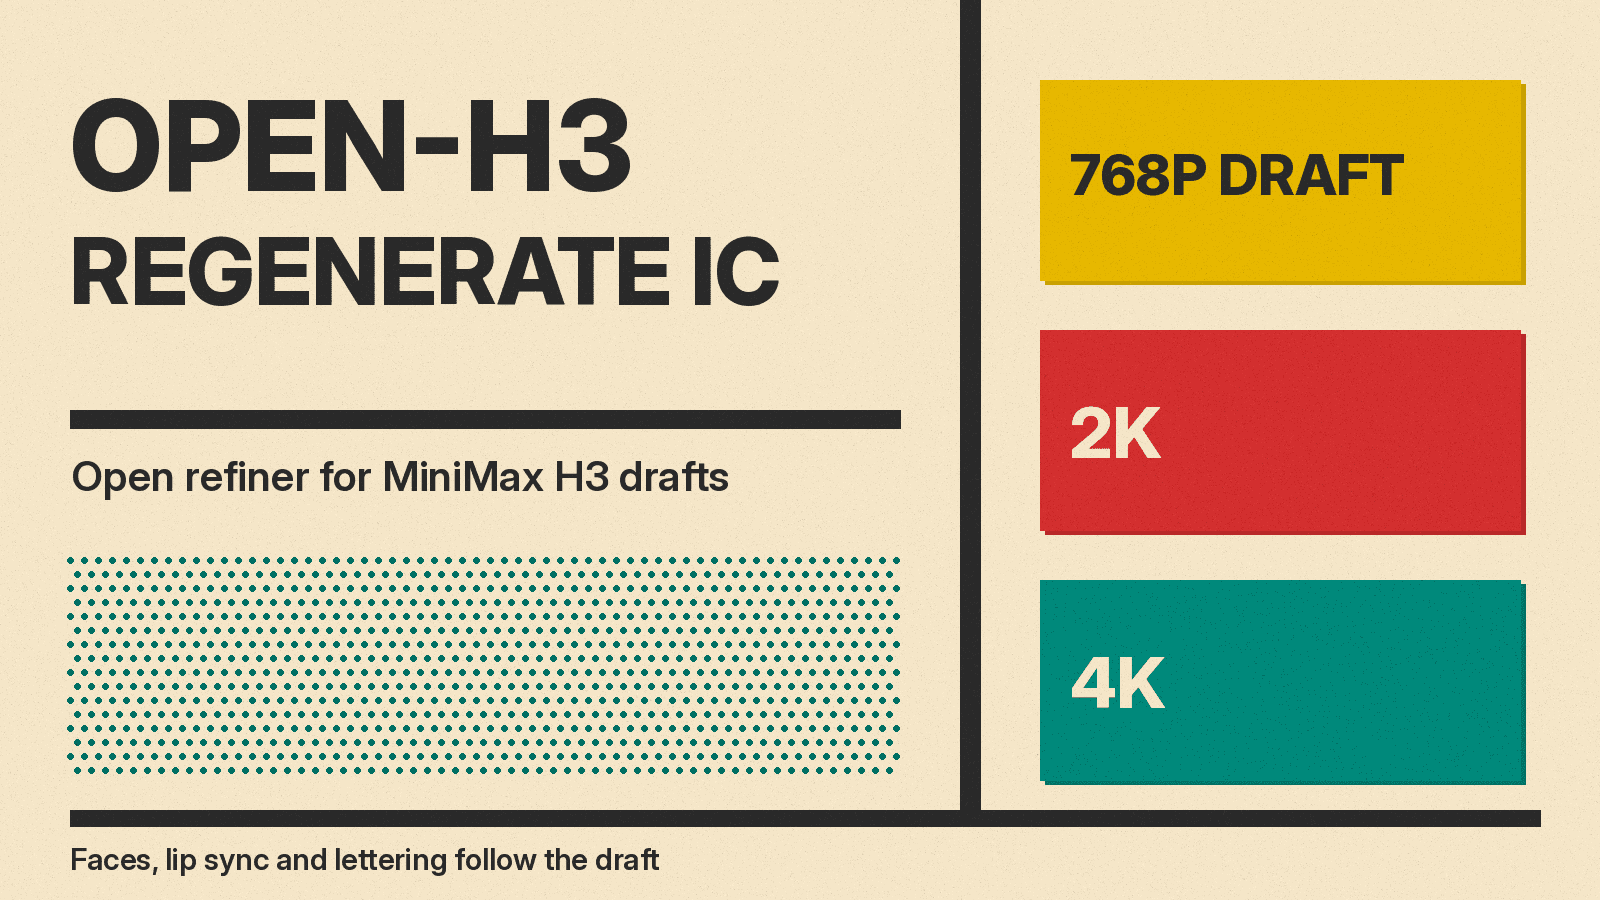
NVlabs researchers released Open-H3-Regenerate-2K-IC, an open LoRA that refines MiniMax H3 drafts to 2K or 4K. Its license excludes the US, UK, EU and Korea.
Underdog Woof is an English text-to-speech model of 31.7 MB or 40.6 MB that runs on a laptop CPU or in a browser, offline. Accuracy claims and license.
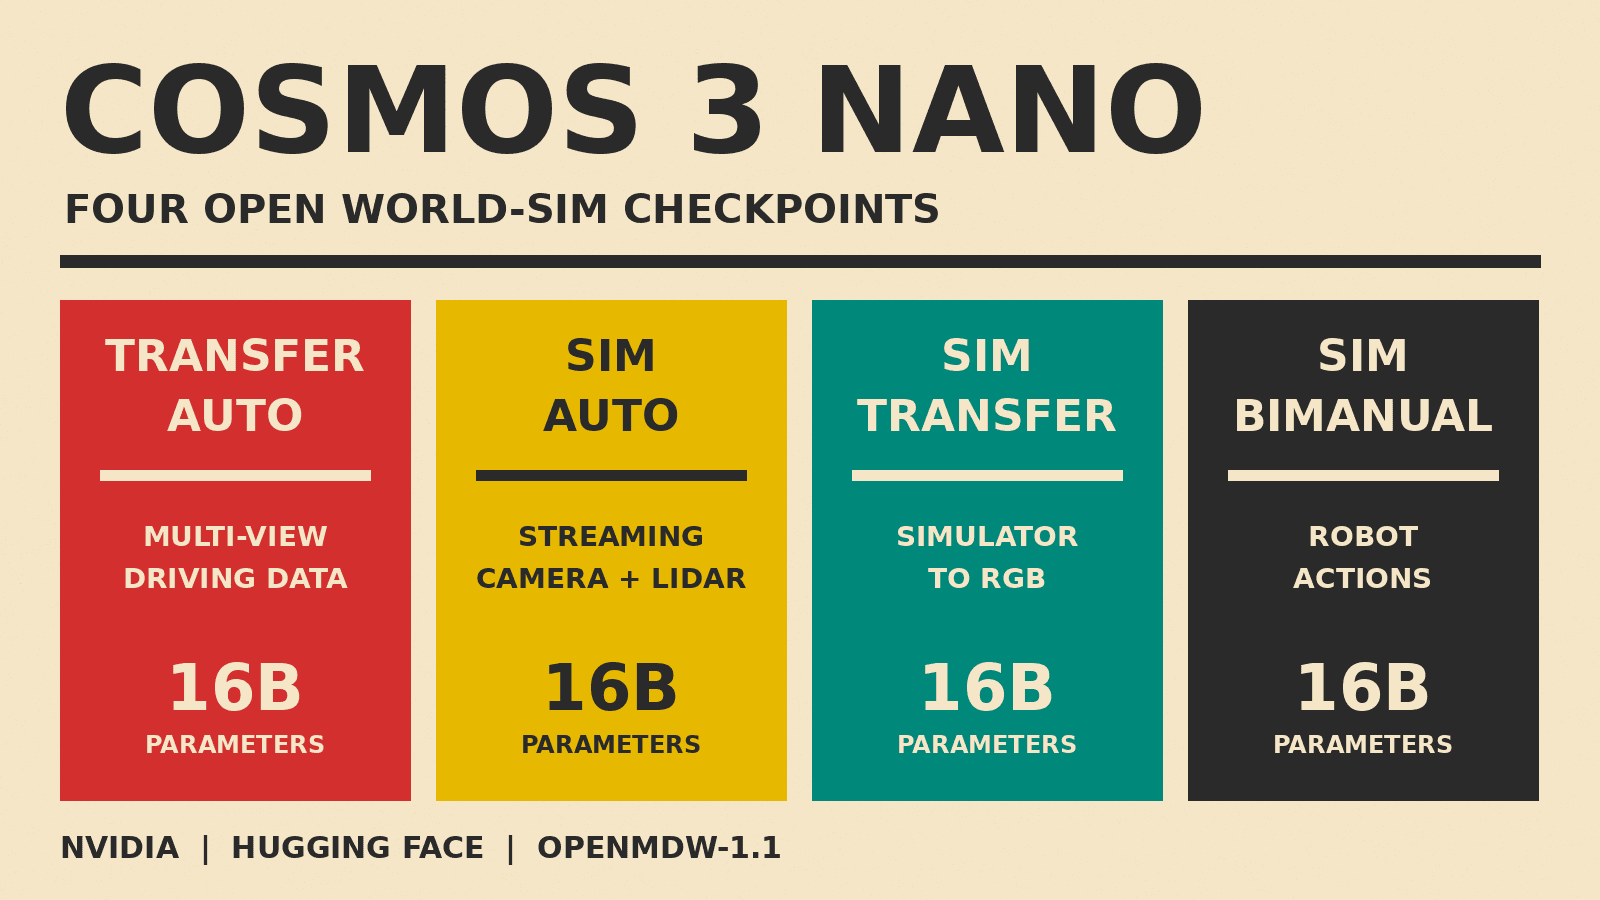
NVIDIA posted four 16B Cosmos 3 Nano open checkpoints for interactive world simulation on Hugging Face under OpenMDW-1.1, for driving and robot sims.
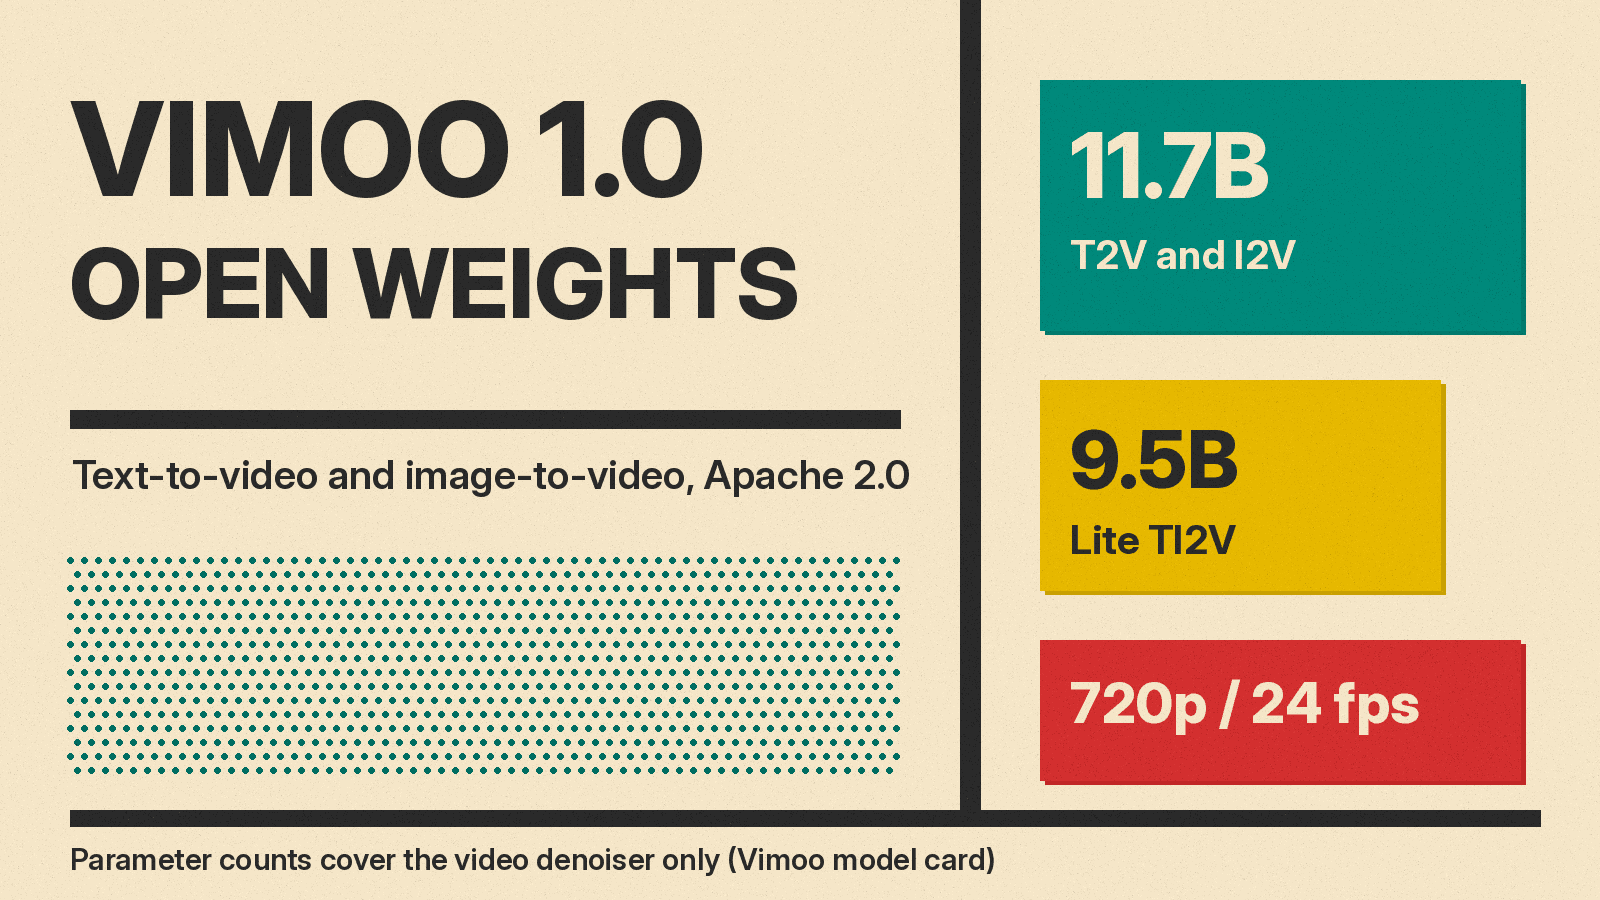
Vimoo 1.0 is an Apache 2.0 open-weight video model in 11.7B and 9.5B Lite versions. What is open, vendor benchmarks, GPU needs and limits.
Preferred Networks released PLaMo 3.0 Fin, an 8B Japanese finance model with reasoning and tool calls, as open weights under the PLaMo Community License.
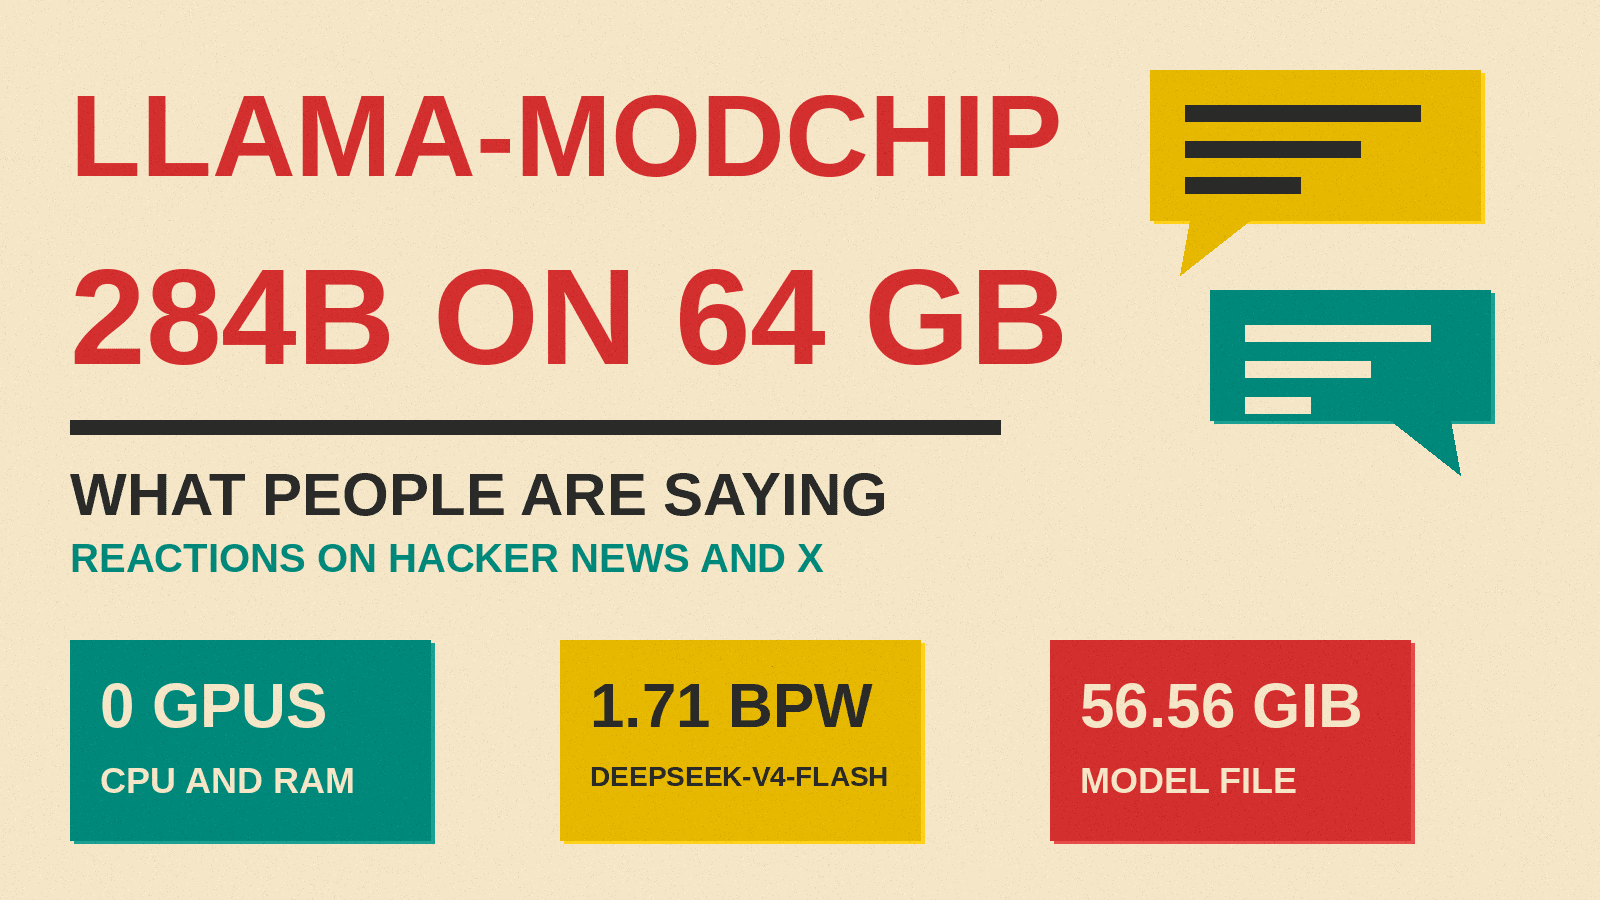
llama-modchip says it runs the 284B DeepSeek-V4-Flash on 64 GB of RAM with no GPU. Hacker News questioned its 1.71-bit compression and slow prefill.
Nous Research fine-tuned Qwen3.8-27B into Arete-27B. On its own test, answers with propaganda fell from 22% to 0.9%, with no meaningful loss on skill tests.
Find a GGUF repo on Hugging Face, check the card and license, pick a quant file, then run it in Ollama or LM Studio. Commands from the docs, plus real errors.
A plain-English guide to ERNIE: the name, ERNIE 4.5, 5.0, 5.1, the new 5.5 Flash Base weights, the open image model, and three ways to use Baidu's models as of November 2026.
Mistral is a European AI lab that releases open-weight models. See the Large 4, Small 4 and Ministral 3 lineup, what each license allows, and how to try them.
A plain-English guide to GLM: who makes it, what GLM-5.3 and GLM-5.3-Flash are, three ways to use it, the licenses, and Z.ai's privacy terms.
A plain-English guide to DeepSeek: who runs the Chinese AI lab, what V3, R1 and V4 are, what open weights means, and three ways people use it.
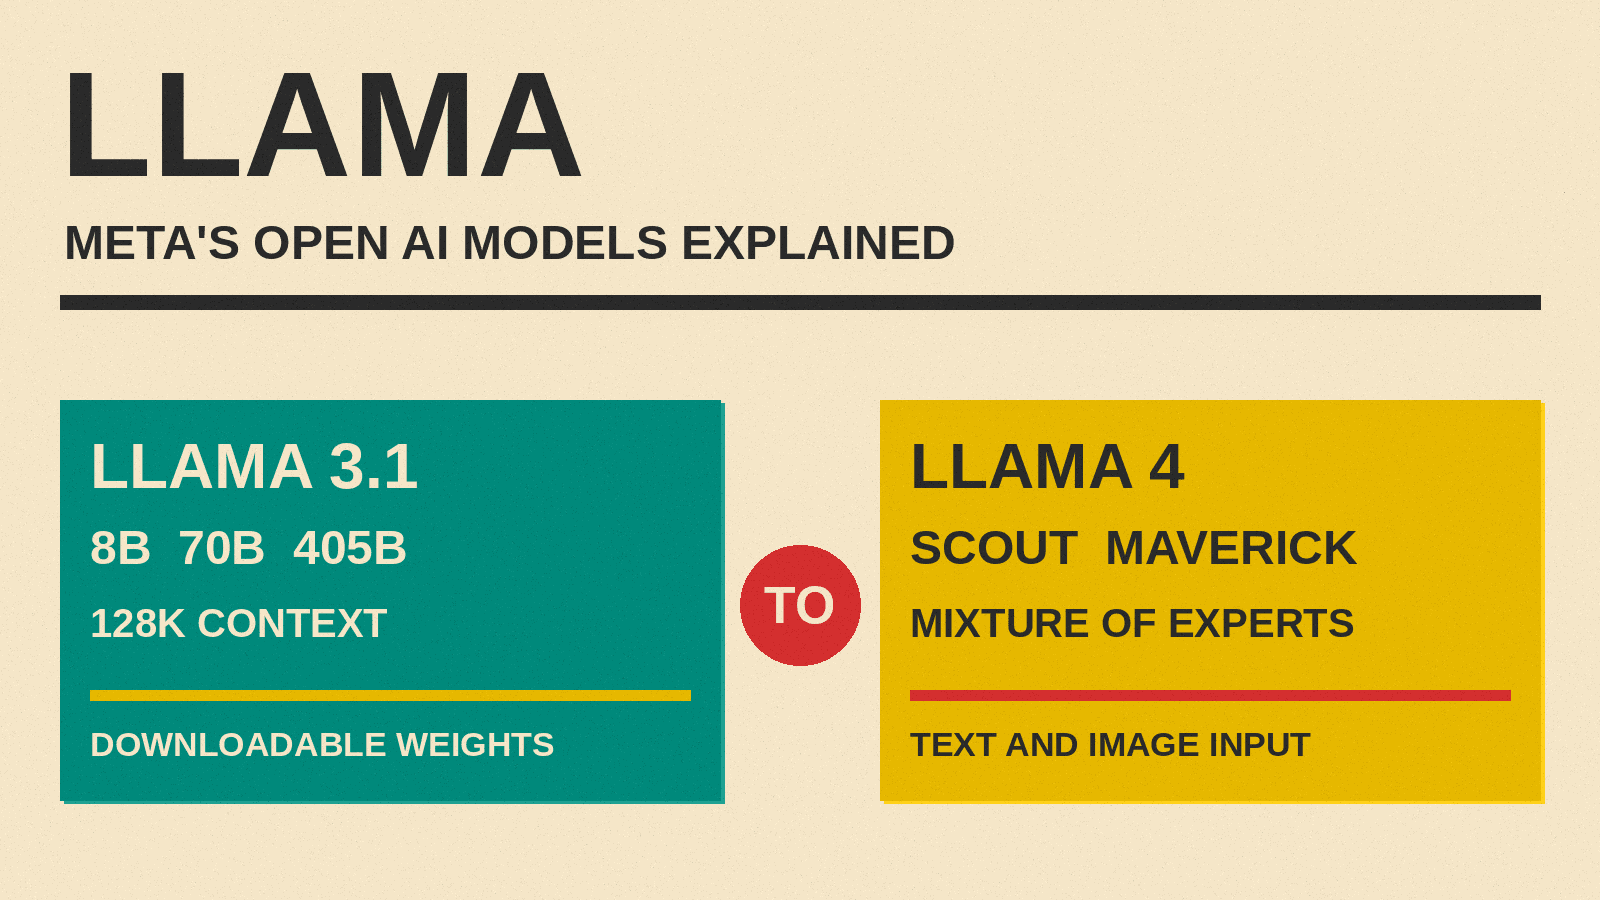
Llama is Meta's family of AI models with downloadable weights. See how Llama 3.1 and Llama 4 differ, what the license requires, and where Muse fits in now.
Qwen is Alibaba's AI model family. The Qwen3.8 lineup, how its licenses differ, how to try it, and what Alibaba has said about Qwen 4.
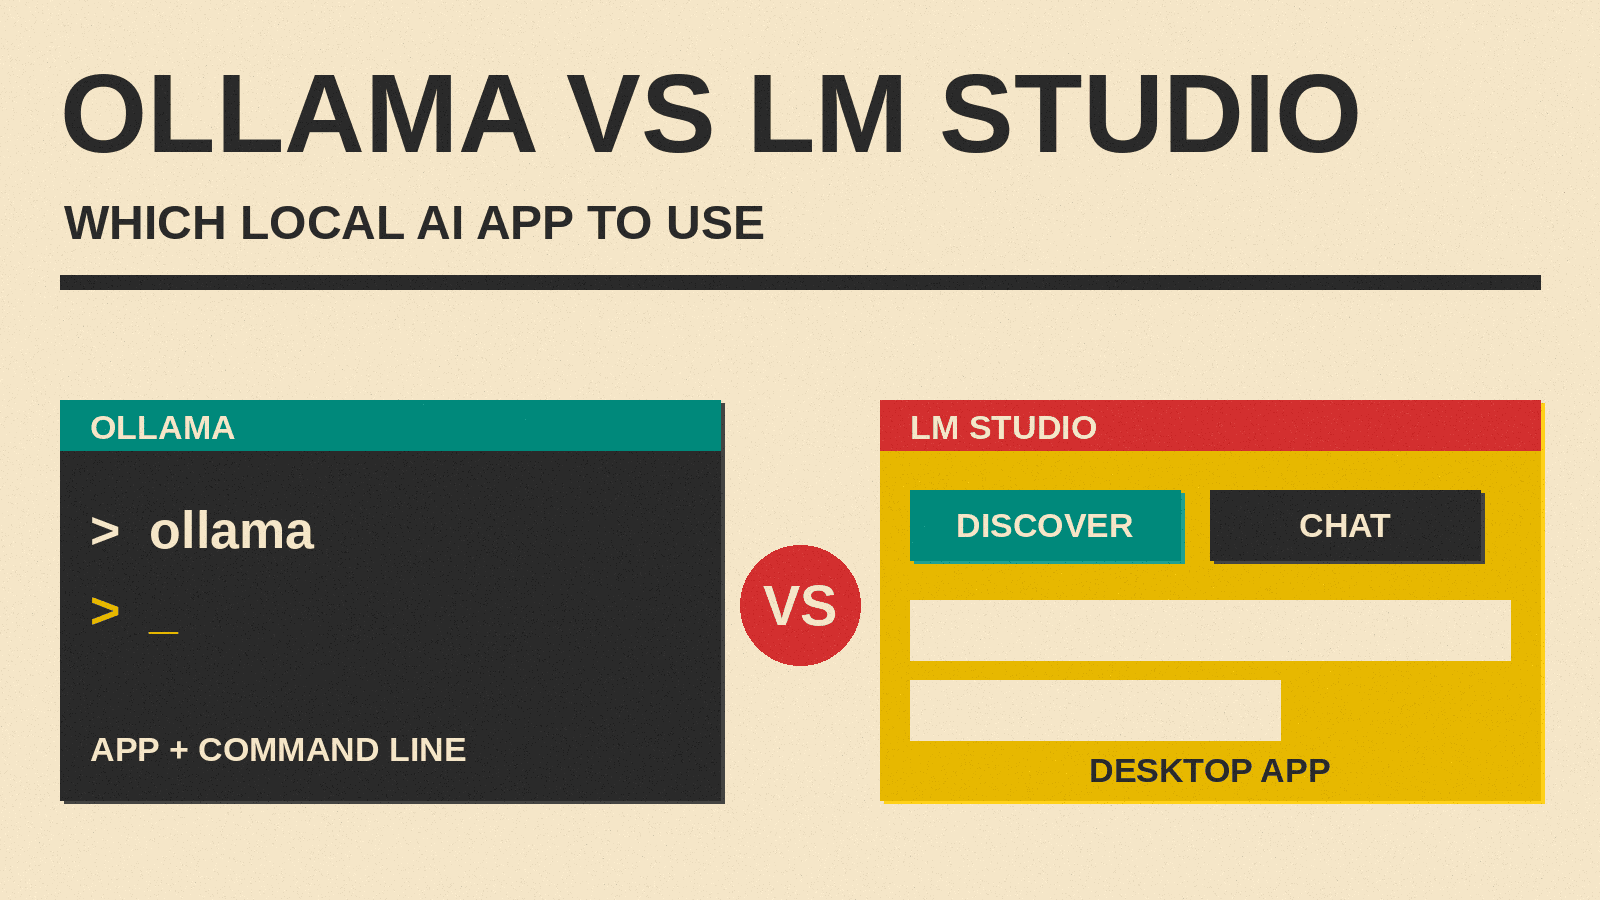
Ollama or LM Studio? A plain comparison for beginners: install, interface, models, local API, license and price, hardware and privacy, from official sources.
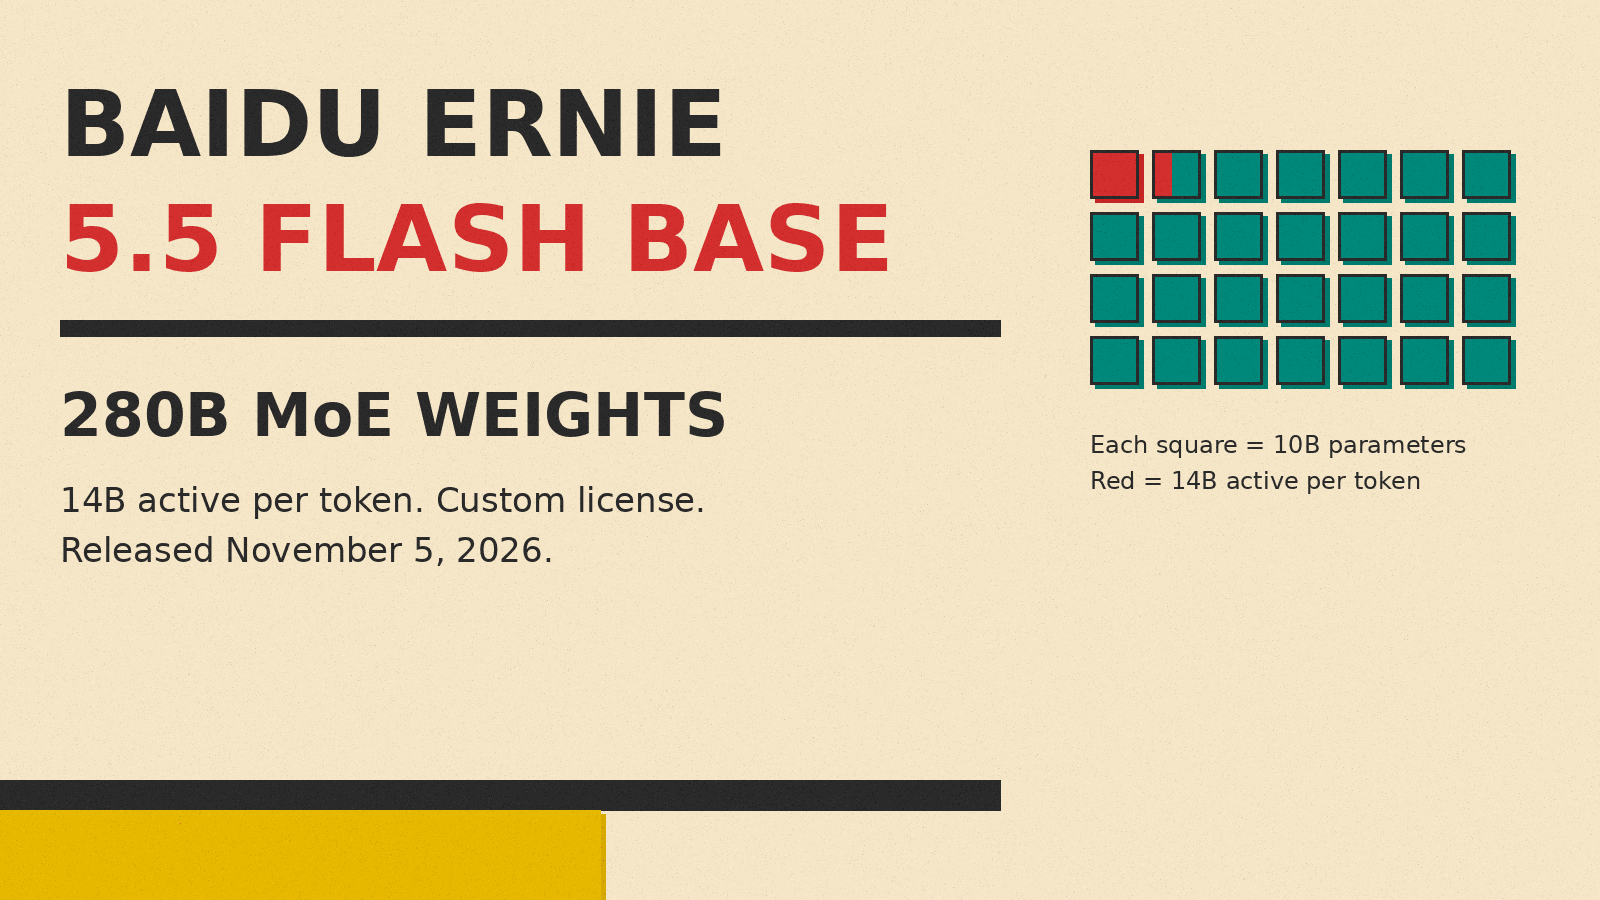
Baidu released ERNIE-5.5-Flash-Base on Nov 5, 2026: a 280B MoE with 14B active per token, 1M context and a custom license that excludes the EU and UK.