What Is Model Distillation? How Small AI Models Learn
Model distillation trains a small student model to copy a large teacher. How it works, where DeepSeek, Gemma 2 and DistilBERT used it, and its limits.
Model distillation trains a small student model to copy a large teacher. How it works, where DeepSeek, Gemma 2 and DistilBERT used it, and its limits.
Mistral Large 4, DeepSeek-V4.1-Flash and Qwen3.8-2.4T-A95B compared on cost per task, license, hardware and fit, from model cards and Artificial Analysis.
Open-weight models let you download and run the model; closed models run on the developer's service. How they differ, what licenses allow, and how to choose.
MPO trains LLM agents with RL credit per turn, then per token. It topped GRPO, PPO and SAO on all nine reported metrics at 4B and 30B-A3B scale.
ByteDance's Doubao Work now lets Team and Enterprise customers use Kimi K3.1 Pro, GLM-5.3 and DeepSeek V4.1 Flash, billed from existing AI points.

OpenAI's copy-paste prompts for GPT-6 Astra, Sol and Terra: fewer clarifying questions, user instructions over skill files, plainer prose and effort tips.
GPT-6.1 Terra costs $1 input and $5 output per million tokens. How it compares with Claude Sonnet 5.5 and Gemini 4 Argon on price, specs and cost per task.
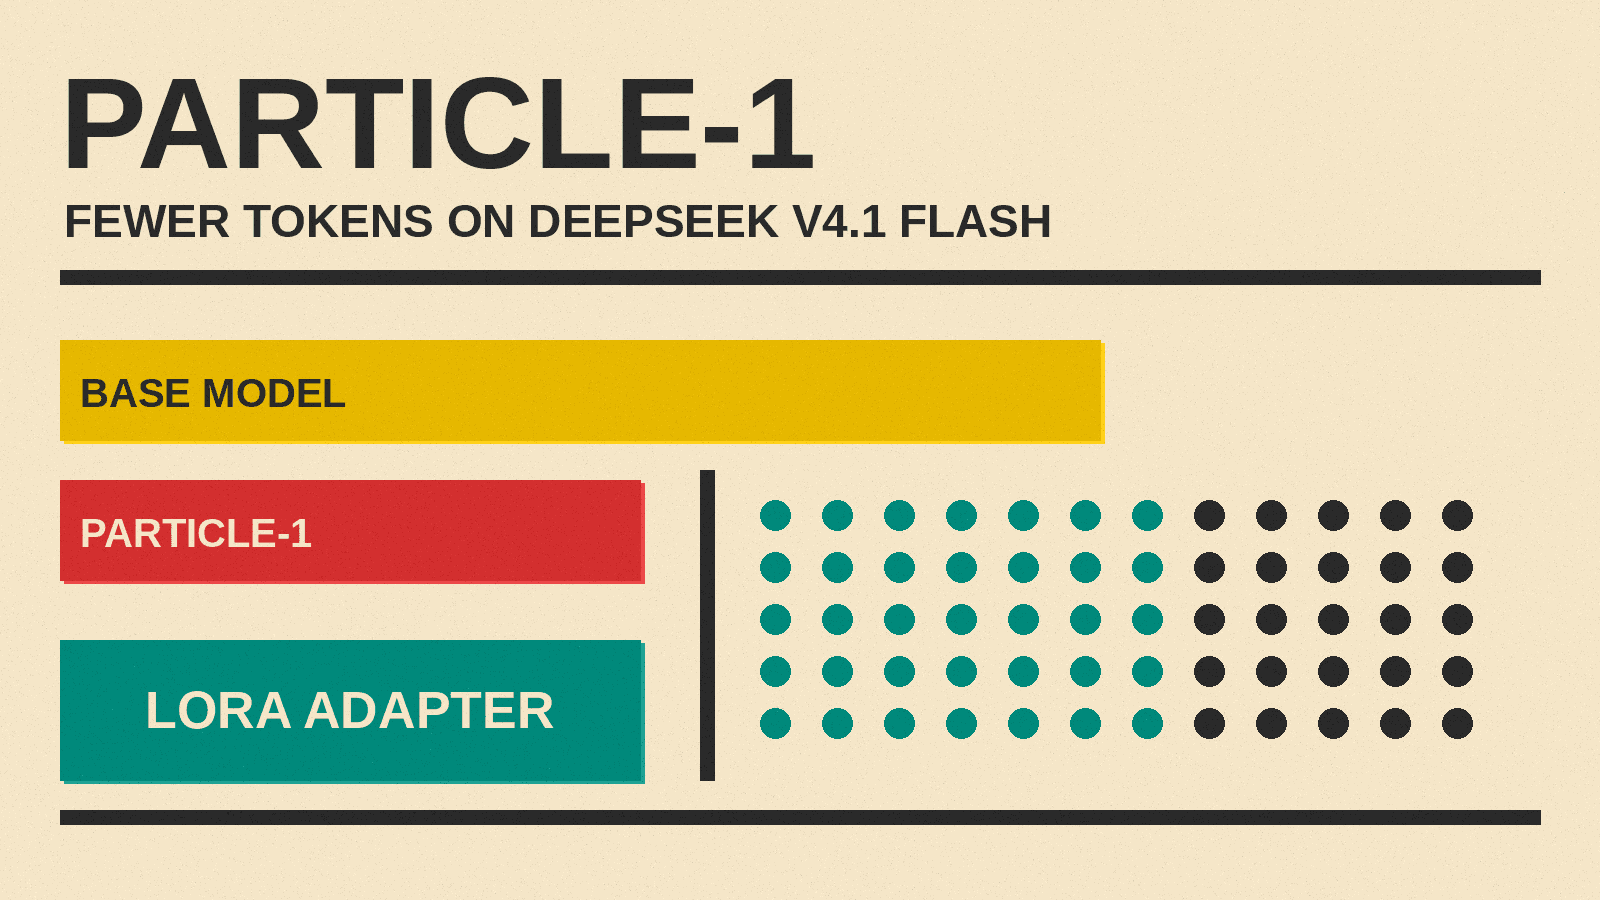
Particle post-trained DeepSeek V4.1 Flash with RL and LoRA. It says Particle-1 uses about 45% fewer tokens with comparable accuracy, at the same price.
Lausanne lab Giotto launched Alto and Solo, reasoning models for European cloud and on-premises use. Alto runs on eight B300 GPUs. The weights are not open.
Tencent says Hunyuan Hy4 and a value-focused Hy4 Flash are coming soon, adding vision understanding for the first time. No date, benchmarks or prices yet.
A study of 11 agent memory systems found many score below plain RAG over the raw chat history. Why it happens, and the cheap fix the authors tested.
API-TAIL checks from returned text alone whether an LLM API swaps in a cheaper model. It caught most simulated 10% swaps at 200 requests in the paper's tests.
Gemini 4 Carbon vs GPT-6 Astra vs Claude Opus 5.5: access, token prices, cost per task, specs and Index v5 scores. Checked Oct 28, updated Nov 11, 2026.
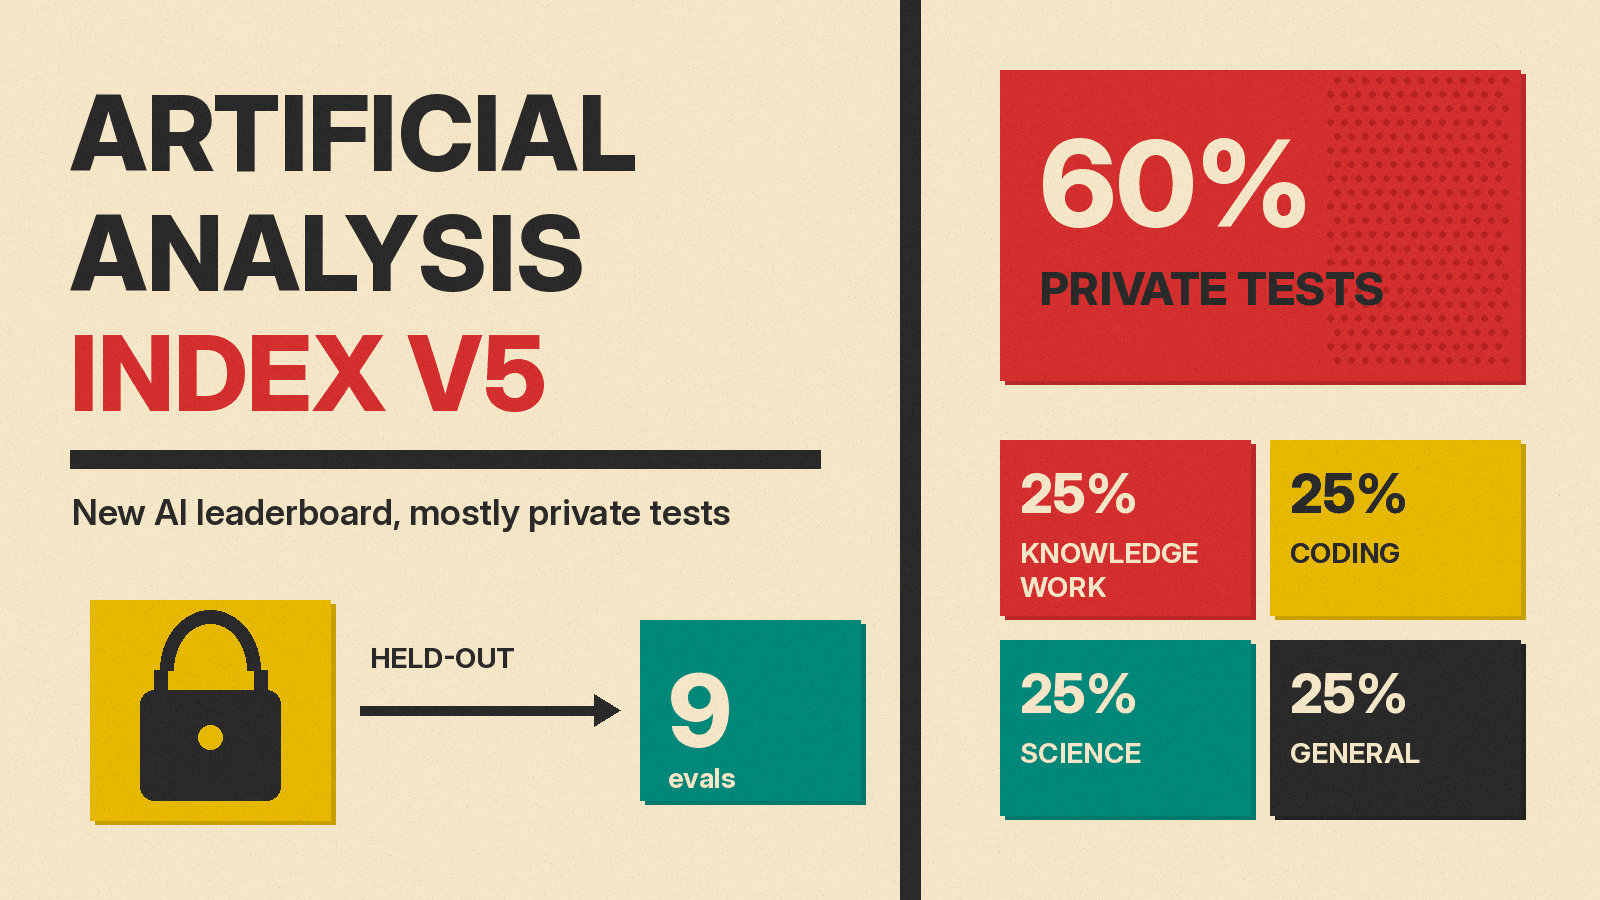
Artificial Analysis rebuilt its Intelligence Index so 60% runs on private or held-out tests. Gemini 4 Carbon now leads at 59, and the open-weight gap grew to 12.
Tokens are the chunks of text AI models read and write. How tokenizers split words, why counts differ by model and language, how images and audio count too, and how pay-per-use billing works, with sources from Google, IBM, Hugging Face and Anthropic.
A context window is how much text an AI model can look at in one go, including its own reply. What fills it, what happens when it runs out, why bigger is not automatically better, and how to work within it, with sources from IBM, Anthropic, Google and the Lost in the Middle paper.
A top spot on an AI leaderboard reads like a verdict. A study of Chatbot Arena shows why it is only a hint: best-of-many testing and practice data can lift a score without making a model better at your work.
A plain-English guide to the 2017 paper that introduced the Transformer: queries, keys and values, multi-head attention, the encoder and decoder, positional encoding, the original translation results, and how the design spread to BERT, GPT-3 and vision models.
Multimodal AI works with text, images, audio and video. How CLIP, LLaVA, Chameleon and GPT-4o are built, the three main designs, and where they still fail.
A Google paper finds AI agents drop correct work under wrong pushback. Writing claims and confidence first cut patch-review false reversals from 12.2% to 0.02%.