Tokenizer Tax: Why AI Costs More in Non-English Languages
A CLEAR study of 19 model families finds a model's costliest language can need up to 17 times the tokens of its cheapest for the same text. Google's Gemini family earns a B.
A CLEAR study of 19 model families finds a model's costliest language can need up to 17 times the tokens of its cheapest for the same text. Google's Gemini family earns a B.
A Télécom Paris and Nokia Bell Labs study of 11 open models finds constrained decoding matches or beats free decoding when prompts and formats match.
DeepSeek raised about 100 billion yuan ($15 billion), Bloomberg reported, with Tencent and CATL among top backers. Who else is in and what is still unconfirmed.
Six open-weight coding models to download as of October 2026, from GLM-5.3 to Recursive Flint, with self-reported benchmarks, hardware needs and licenses.
Kimi K3.1 Pro (64) and DeepSeek V4.1 Flash 1017 (57) lead public models on the Artificial Analysis Cyber Index. What it measures and how China's rules apply.
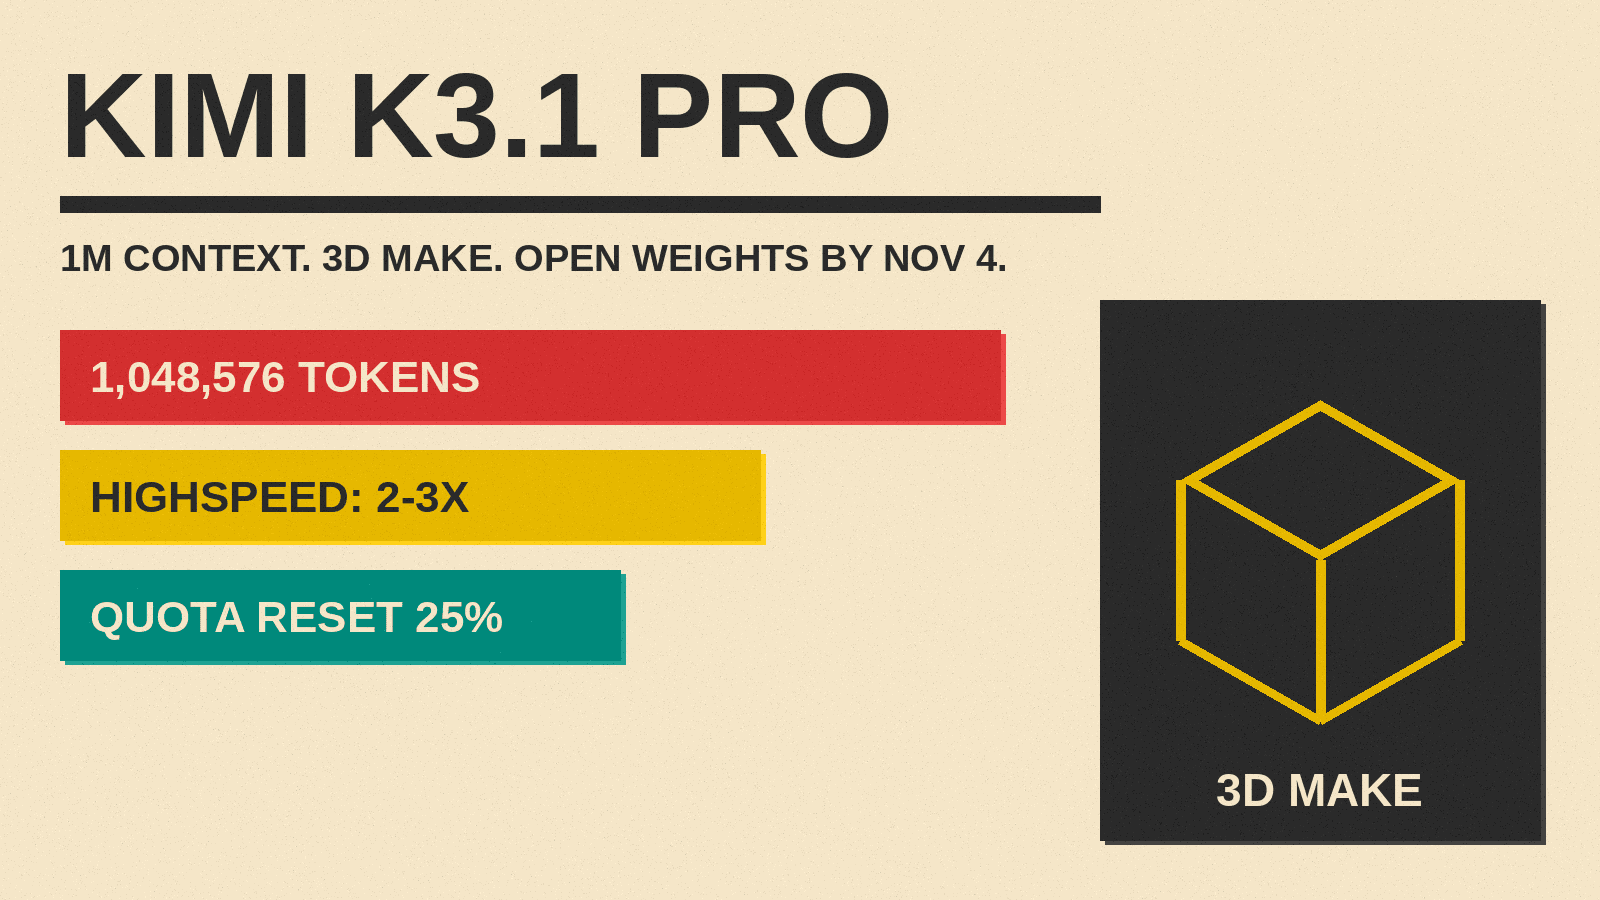
Moonshot AI launched Kimi K3.1 Pro on October 23 with a 1M-token context, 3D Make and open weights, which it has since published on Hugging Face. Three days later it apologized for rate limits and reset 25% of subscriber quotas. What the model is, what it costs and what Moonshot's numbers say.
OpenAI's GPT-6.1 Terra is a fast, cheaper model built for computer use and everyday work. Its API costs $1 per million input tokens and $5 per million output tokens. Here is what OpenAI's tests show, where you can use it, and when Sol or Astra is the better pick.
OpenAI's GPT-6.1 Terra launched at $1 input and $5 output per million tokens. Early testers praise fast, cheap 3D and computer-use runs, but a bug-fixing test found big gains only at max effort, and several asked why not just use GPT-6.1 Sol.
Mercury 3, Claude Haiku 5.5 and GPT-6 Luna compared on speed, API price, context and quality, using only figures from Inception, Anthropic, OpenAI and Artificial Analysis.
DeepSeek open-sourced DeepInfer, the Apache 2.0 inference engine behind DeepSeek-V4.1-Flash, for NVIDIA SM100 and Huawei Ascend 950. What it includes, what it leaves out, and what DeepSeek's claim of 155 trillion tokens a day and $38 per GPU-hour does and does not show.
Inception's Mercury 3 is a diffusion LLM the company says beats GPT-6 Luna and Claude Haiku 5.5 on a range of benchmarks while running 4 to 8 times faster. It has a 1M-token context and costs $0.10 input and $0.35 output per million tokens at launch.
A new paper replaces Gemma 3 270M's 168M-parameter embedding table with frozen 512-bit codes. Trained on the same 2.05B tokens, it ties or beats the learned table on LAMBADA, HellaSwag and PIQA, and a ternary version is a 46 MB file running 615 to 740 tokens per second on a laptop CPU.
The best open-weight LLMs as of October 2026, sorted by hardware: GLM-5.3, Kimi K3, DeepSeek V4.1-Flash, Muse Spark Open and Beam for servers; Nemotron 3.5 and GLM-5.3-Flash for one node; Qwen3.8-27B, Gemma 4, LFM2.5 and MiniCPM-V 4.7 for your own computer.
Alibaba's Qwen3.8 covers a 2.4T-parameter API flagship, its first Max-class open weights, a 27B Apache 2.0 model, Flash at $0.15 per million input tokens, omni-modal models, and Flash-Next, a preview of the Qwen 4 architecture. Which model is which, what each costs, and what is next.
What an AI engineer does, how it differs from ML engineering and research, what BLS pay data says (software developers $134,040 median in 2025), and a six-stage roadmap from Foundations to Ship and Portfolio, with free courses from Hugging Face, Anthropic, Microsoft, Google and fast.ai.
Why do chatbots invent facts? OpenAI says tests reward guessing, Anthropic found a default "can't answer" circuit that misfires, and a Stanford and Yale study found RAG legal tools still hallucinate 17% to 33% of the time. What causes hallucinations and how to catch them.
Claude Sonnet 5.5 ($2/$10), GPT-6.1 Sol ($2.00/$10.00), and Gemini 3.8 Flash ($0.75/$3.75 introductory through December 31, 2026) compared as of October 2026: model IDs, API prices, context and output limits, vendor-reported benchmarks, and where to use each.
The Information reports Anthropic is preparing an unnamed model that a tester says is better at reasoning, intuition, and reading unstated goals than current commercial Claudes. No release date, price, or Anthropic comment in the verified text.
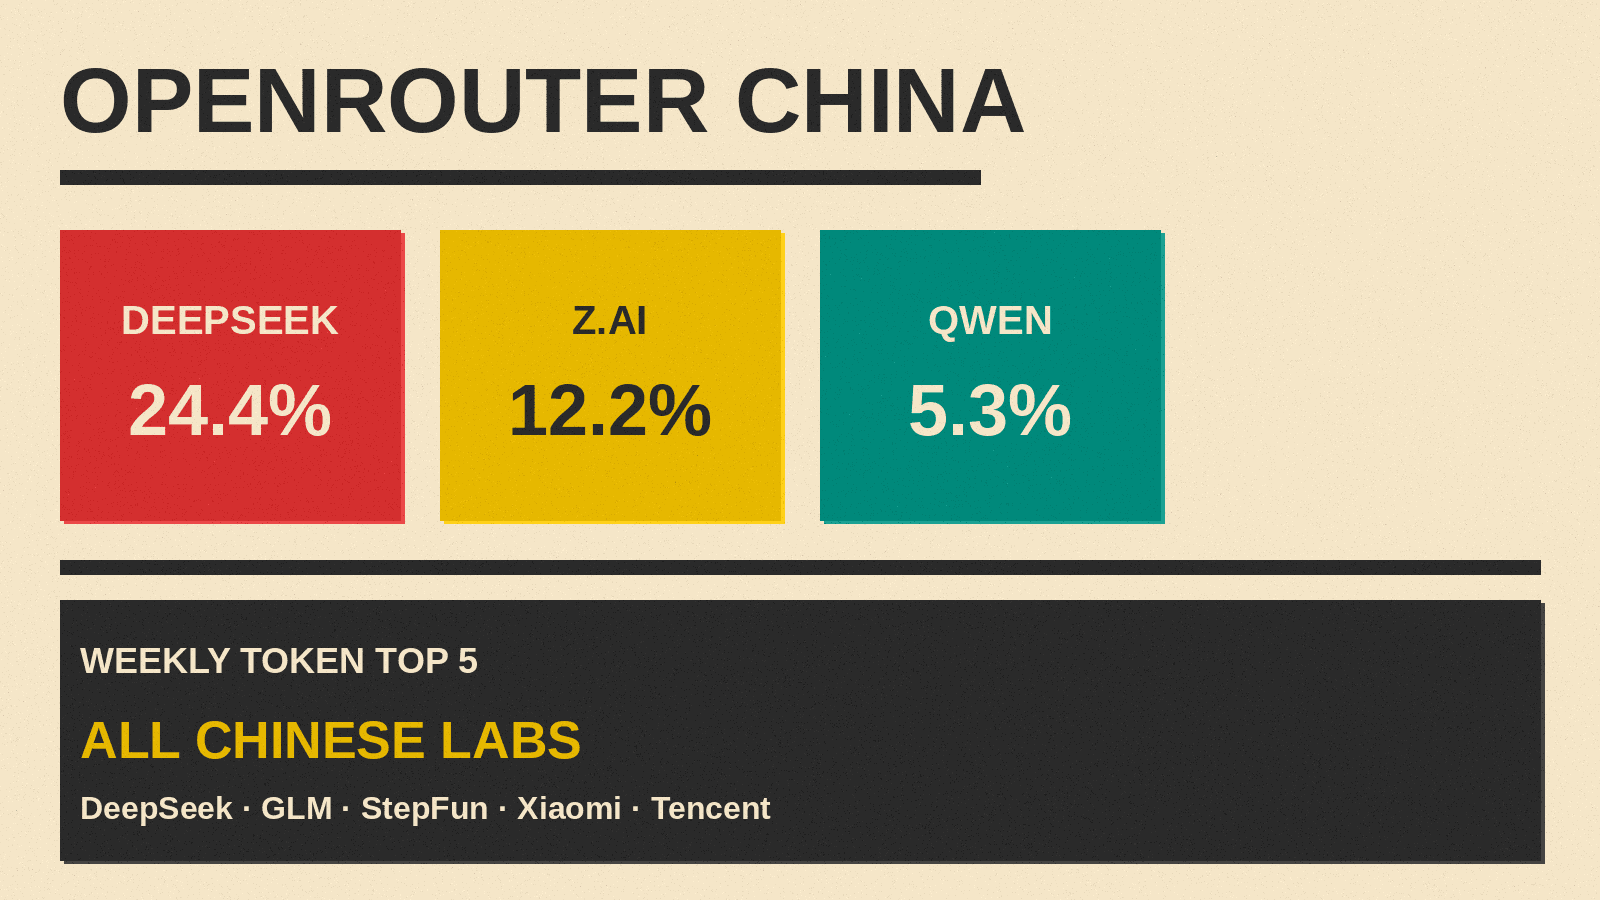
OpenRouter rankings through Oct 18 show DeepSeek at 24.4% of text requests in the week beginning Oct 12, with Z.ai, Qwen and Xiaomi also in the top nine. The five highest weekly token models are all Chinese. Dong-A reports Chinese providers at about 48% of requests the week of Oct 5 to 11.
Apple's M5 Ultra Mac Studio starts at $5,499, with up to 512GB of unified memory coming in late October and Thunderbolt 5 clustering for running large AI models at home. What ships now, what the memory and clustering claims mean, and who it is for.