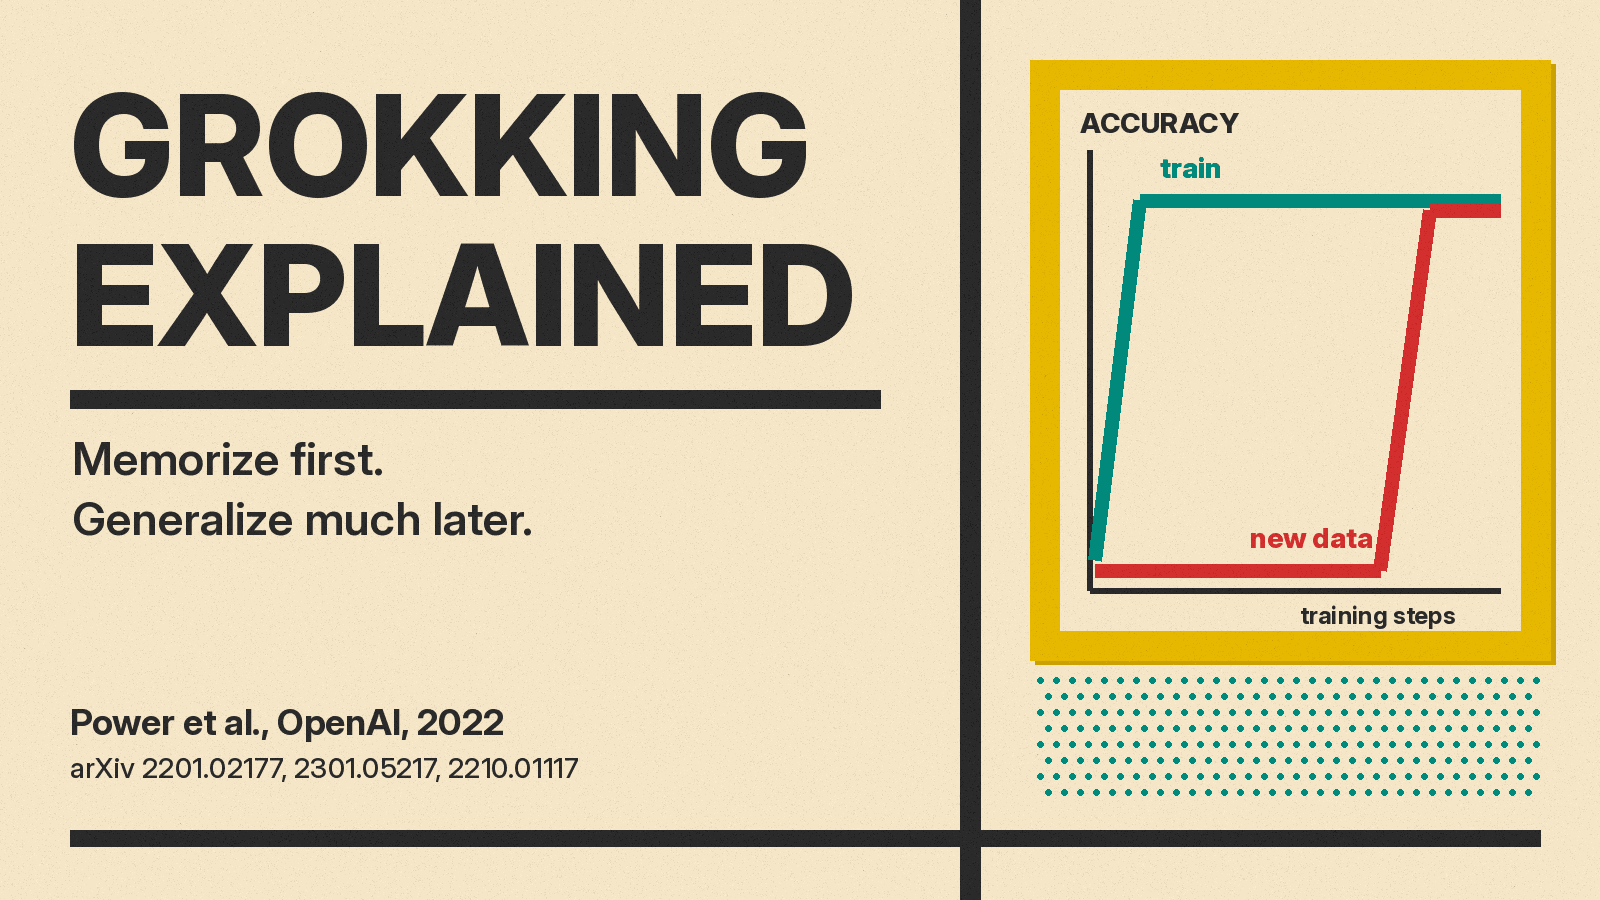
Grokking Explained: When AI Suddenly Starts to Generalize
Grokking is when a model memorizes its training data, then much later learns the real rule. What three research papers found, and what it means for LLMs.
Deep dives into the transformer architecture behind today's LLMs and its newer variants. Recent posts explain Multi-Head Latent Attention, the Differential Transformer, FlashAttention 1 to 3, and how Mamba state space models compare.
Grokking is when a model memorizes its training data, then much later learns the real rule. What three research papers found, and what it means for LLMs.
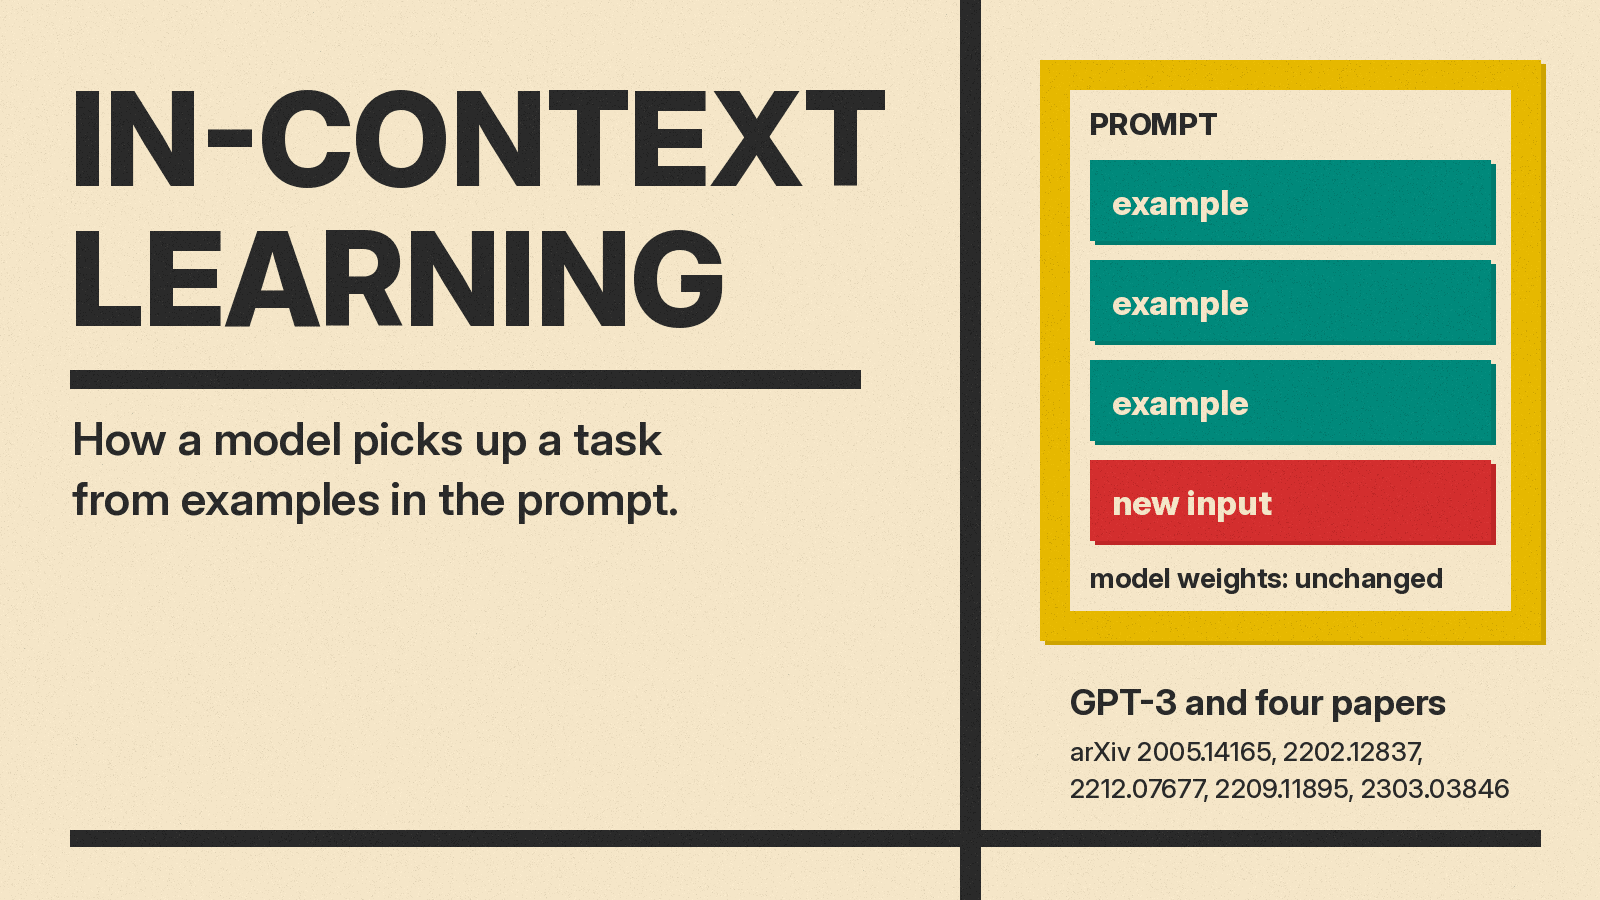
In-context learning is how a chatbot picks up a task from the examples in your prompt. What five research papers found, and what they do not prove.
What a large language model is, how it is trained, how it writes an answer one token at a time, where it goes wrong, and how it differs from a chatbot or agent.
What is LoRA? A way to customize an AI model by training a small patch, not every weight. How it works, what the 2021 paper found, and where QLoRA fits in.
Why AI labs built ever larger models, and why the 2022 Chinchilla paper changed course: a plain-English guide to scaling laws, how to split a compute budget between model size and data, and the newer research on scaling the time a model spends answering.
Nearly 600 runs show truncated backprop pays only at a fixed loop count. With both counts free, fewer fully trained loops win at equal compute.
A developer compiled a RISC-V CPU into Qwen3.5-4B's weights. Reactions from the Qwen team, X users who tested it, and skeptics on Hacker News.
A plain-English guide to the 2017 paper that introduced the Transformer: queries, keys and values, multi-head attention, the encoder and decoder, positional encoding, the original translation results, and how the design spread to BERT, GPT-3 and vision models.
Multimodal AI works with text, images, audio and video. How CLIP, LLaVA, Chameleon and GPT-4o are built, the three main designs, and where they still fail.
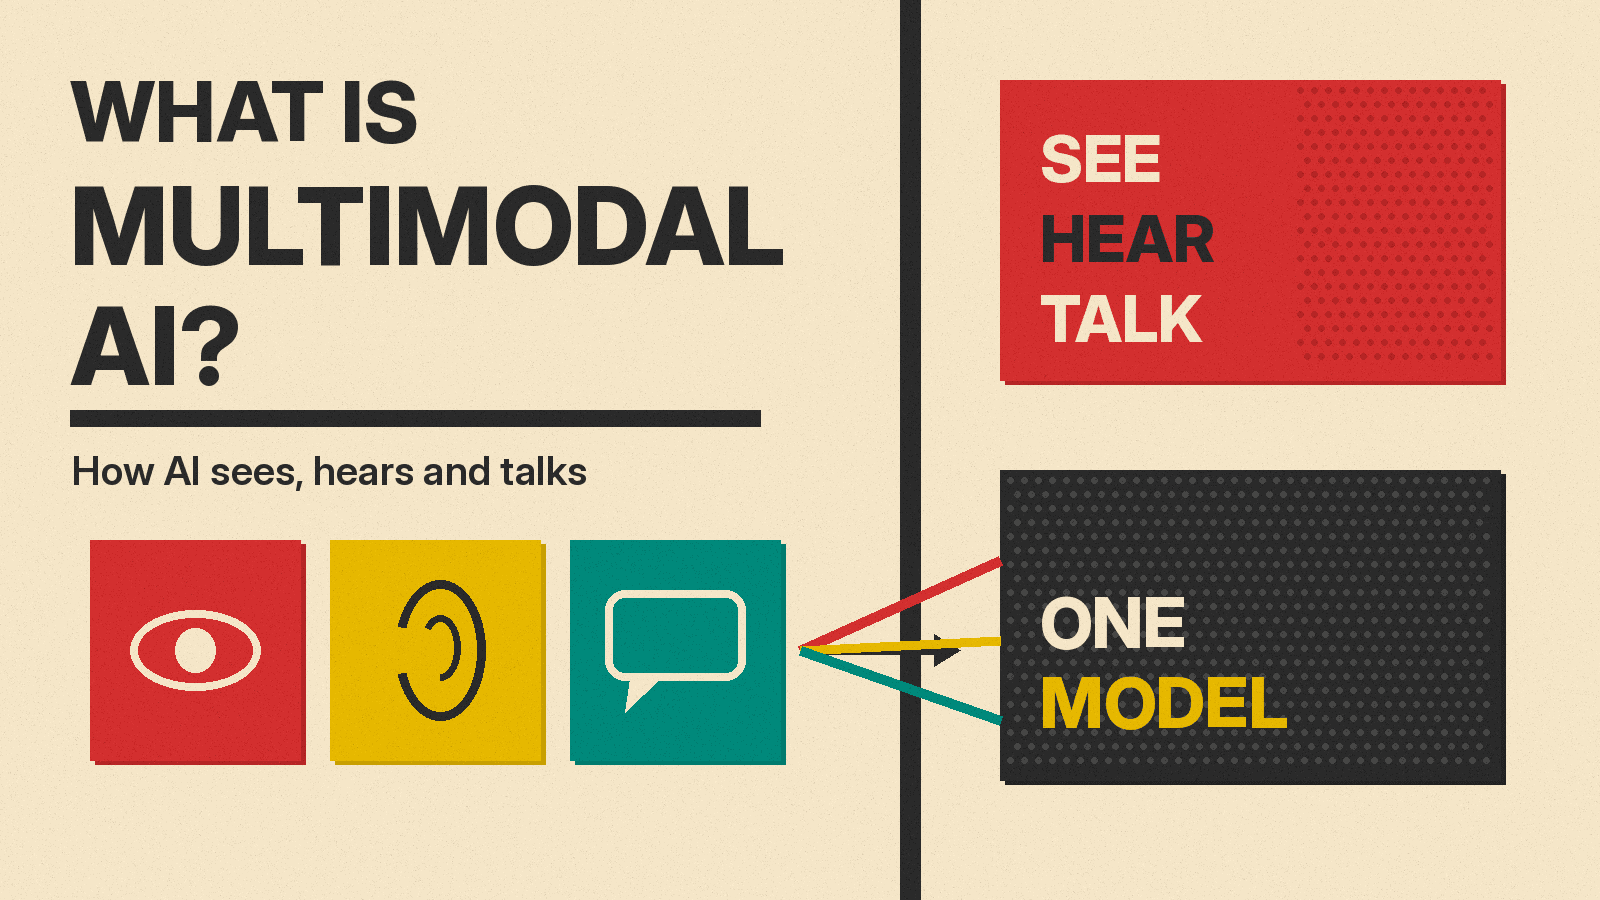
Neural music and sound generation architectures in production have diverged into two competing paradigms: discrete autoregressive sequence modeling and continuous latent diffusion. While early research relied on cascaded pipelines with separate acoustic and semantic models, modern open-source systems unify generation into single-stage or dual-stage foundations capable of synthesizing high-fidelity instrumentals, sound effects, and full polyphonic songs with vocals. Deploying generative audio in
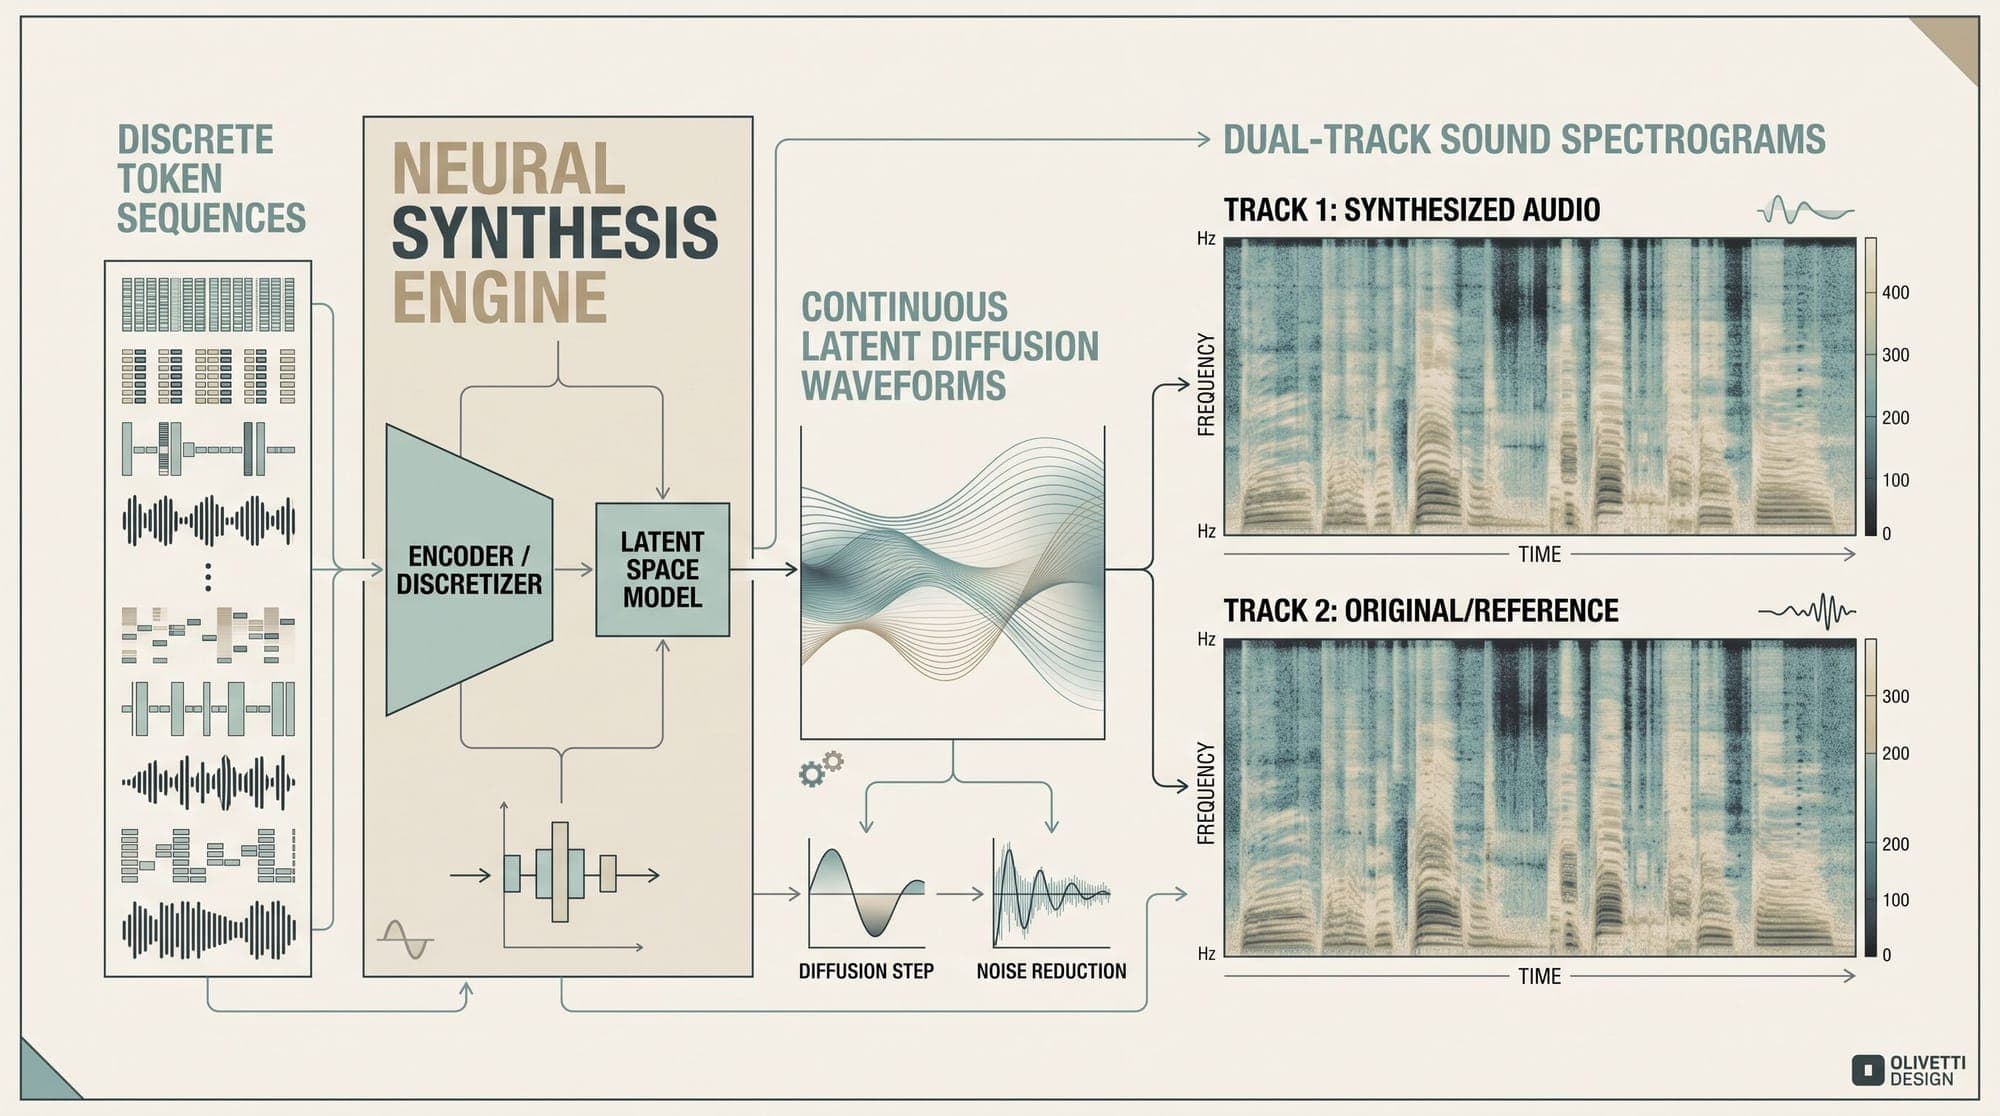
Generative foundation models have historically operated under two distinct mathematical paradigms: autoregressive sequence modeling over discrete vocabularies (used in text and code generation) and iterative denoising diffusion over continuous vector spaces (used in image and video synthesis). Early attempts to unify both modalities in a single end-to-end transformer forced continuous perceptual data into discrete codebooks using vector quantization (such as VQ-VAE or VQGAN). While discretizatio
Differential Transformer (Diff Transformer): Mathematical Foundations of Differential Attention, Noise Cancellation, and Hallucination Suppression Standard Transformer architectures rely on softmax attention to route information between tokens in an autoregressive sequence. While effective across scale, softmax attention suffers from a structural tendency to allocate non-trivial probability mass to irrelevant context tokens. In long-context retrieval, multi-hop reasoning, and document summariza
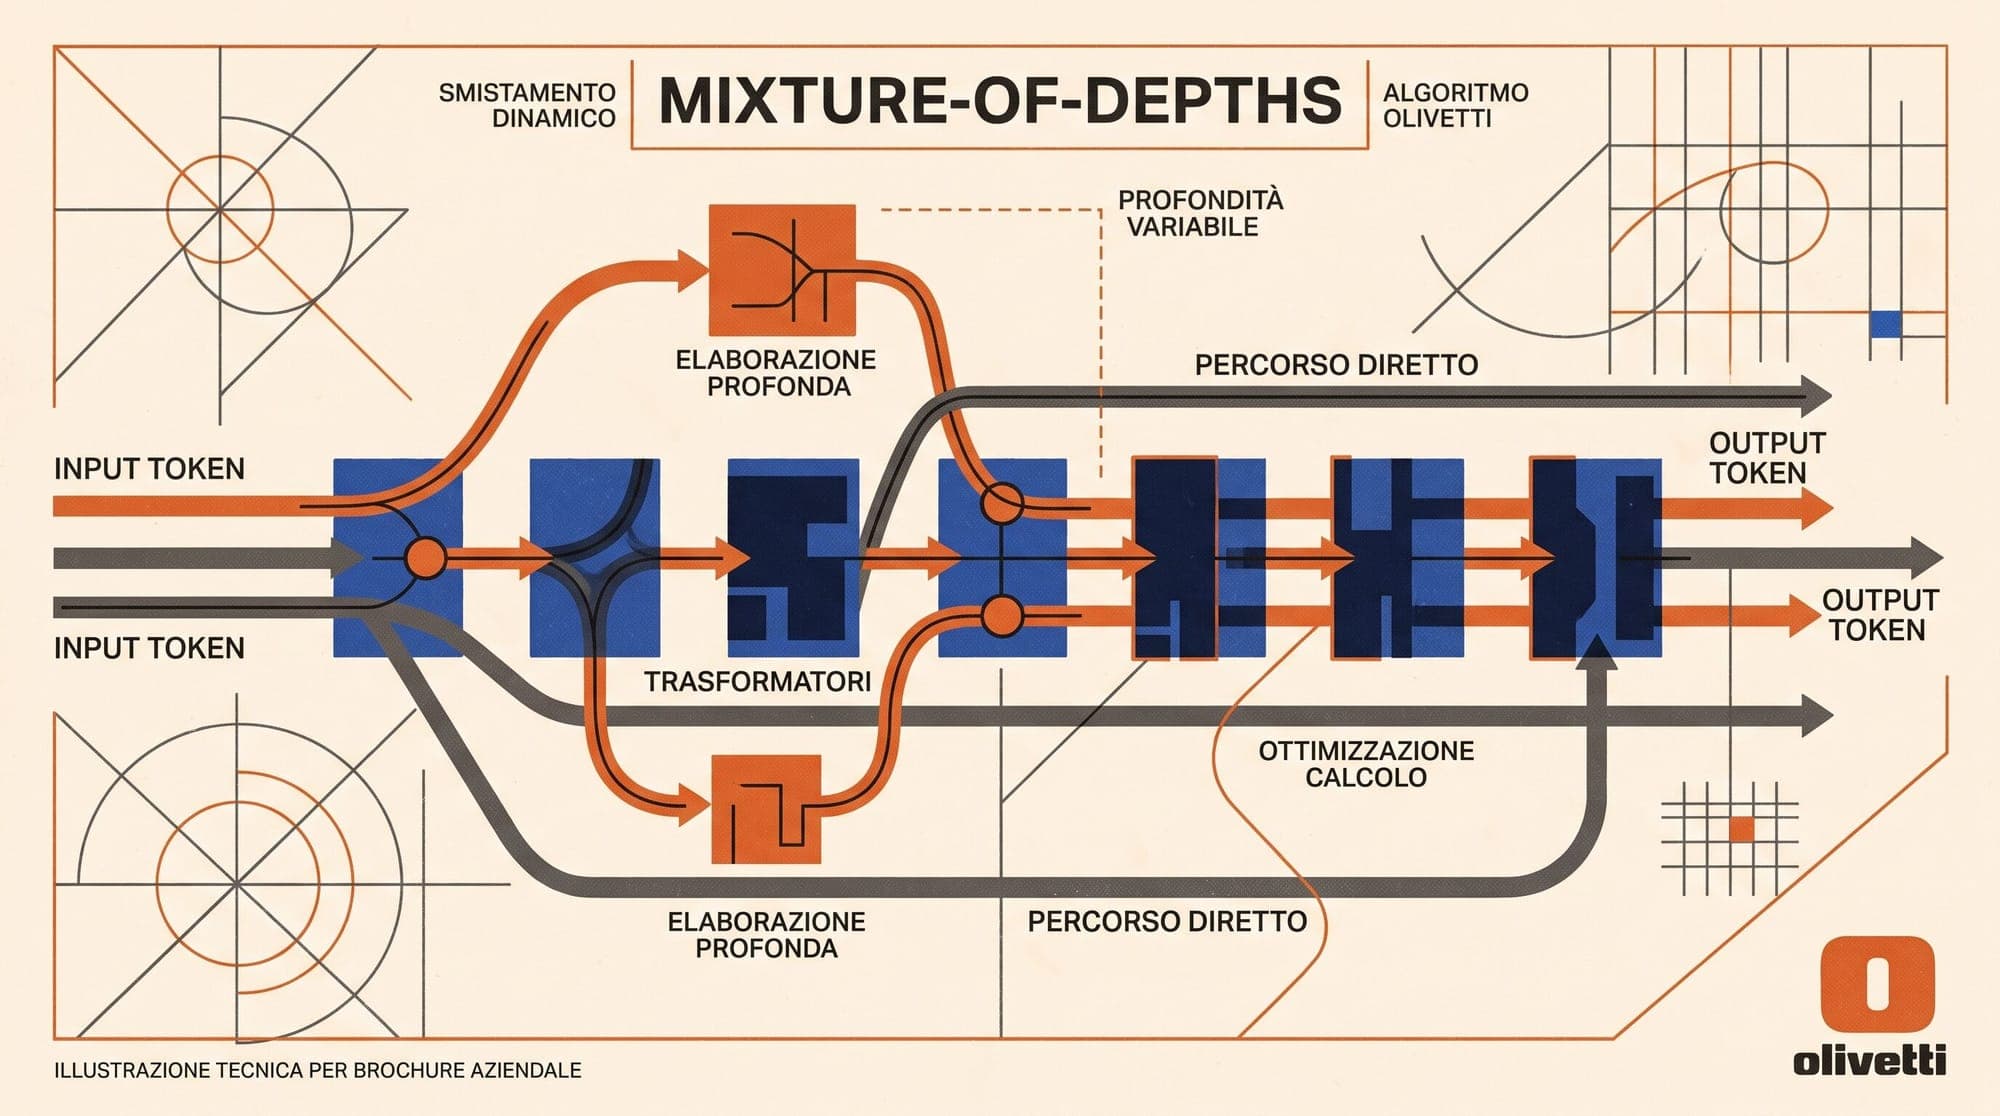
Standard autoregressive Transformers allocate an identical compute budget to every token in a sequence. Regardless of whether a token represents a trivial punctuation mark, a common grammatical function word, or a complex semantic reasoning step, the model applies the exact same sequence of multi-head self-attention and multilayer perceptron (MLP) operations across all $L$ layers. In Mixture-of-Depths: Dynamically allocating compute in transformer-based language models, researchers at Google De
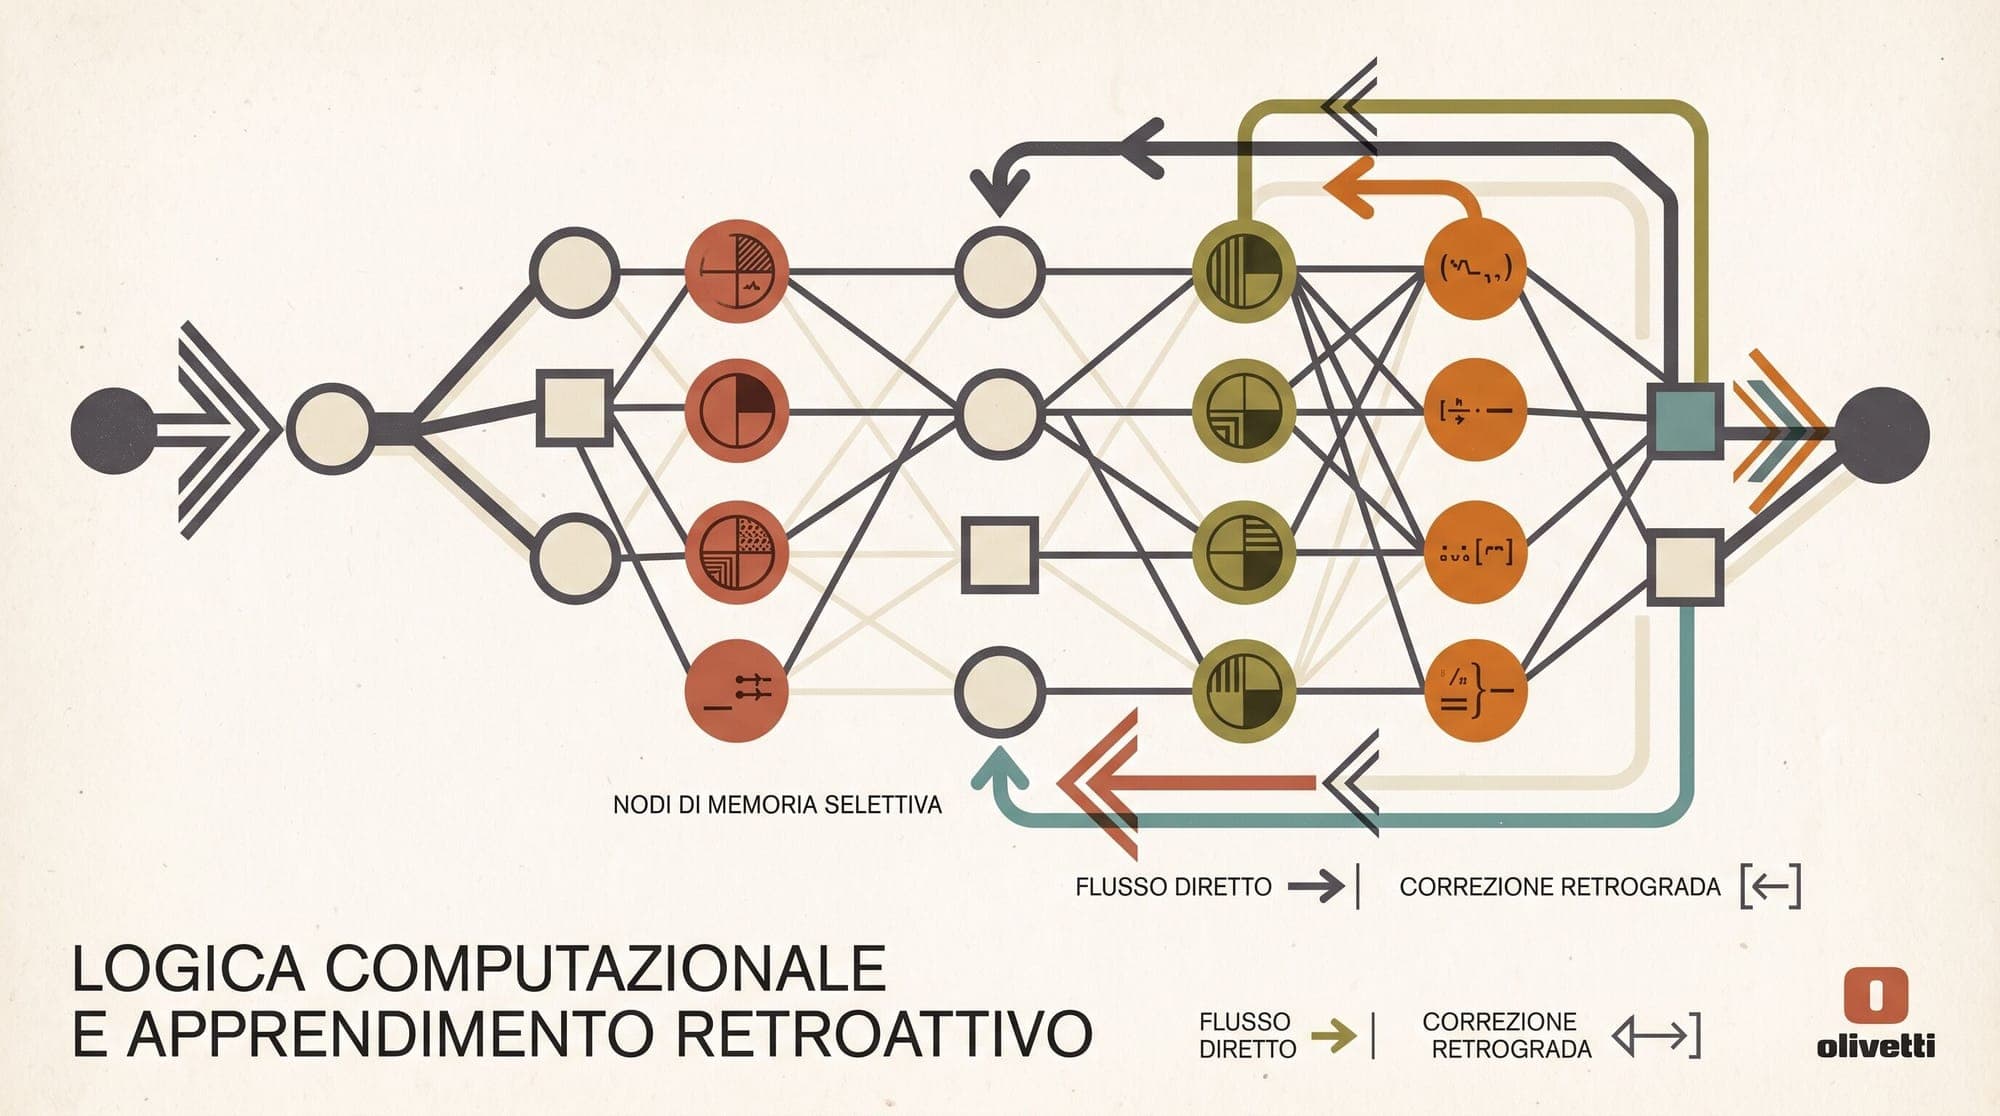
Activation Checkpointing and Selective Rematerialization: Mathematical Foundations, Sub-Linear Memory Scaling, Recomputation Trade-Offs, and Megatron-LM Attention Partitioning Training modern large language models requires orchestrating hundreds of billions of parameters across distributed GPU clusters. While parameter counts and optimizer states are fixed for a given model architecture, the activation memory generated during forward passes scales directly with sequence length, batch size, and
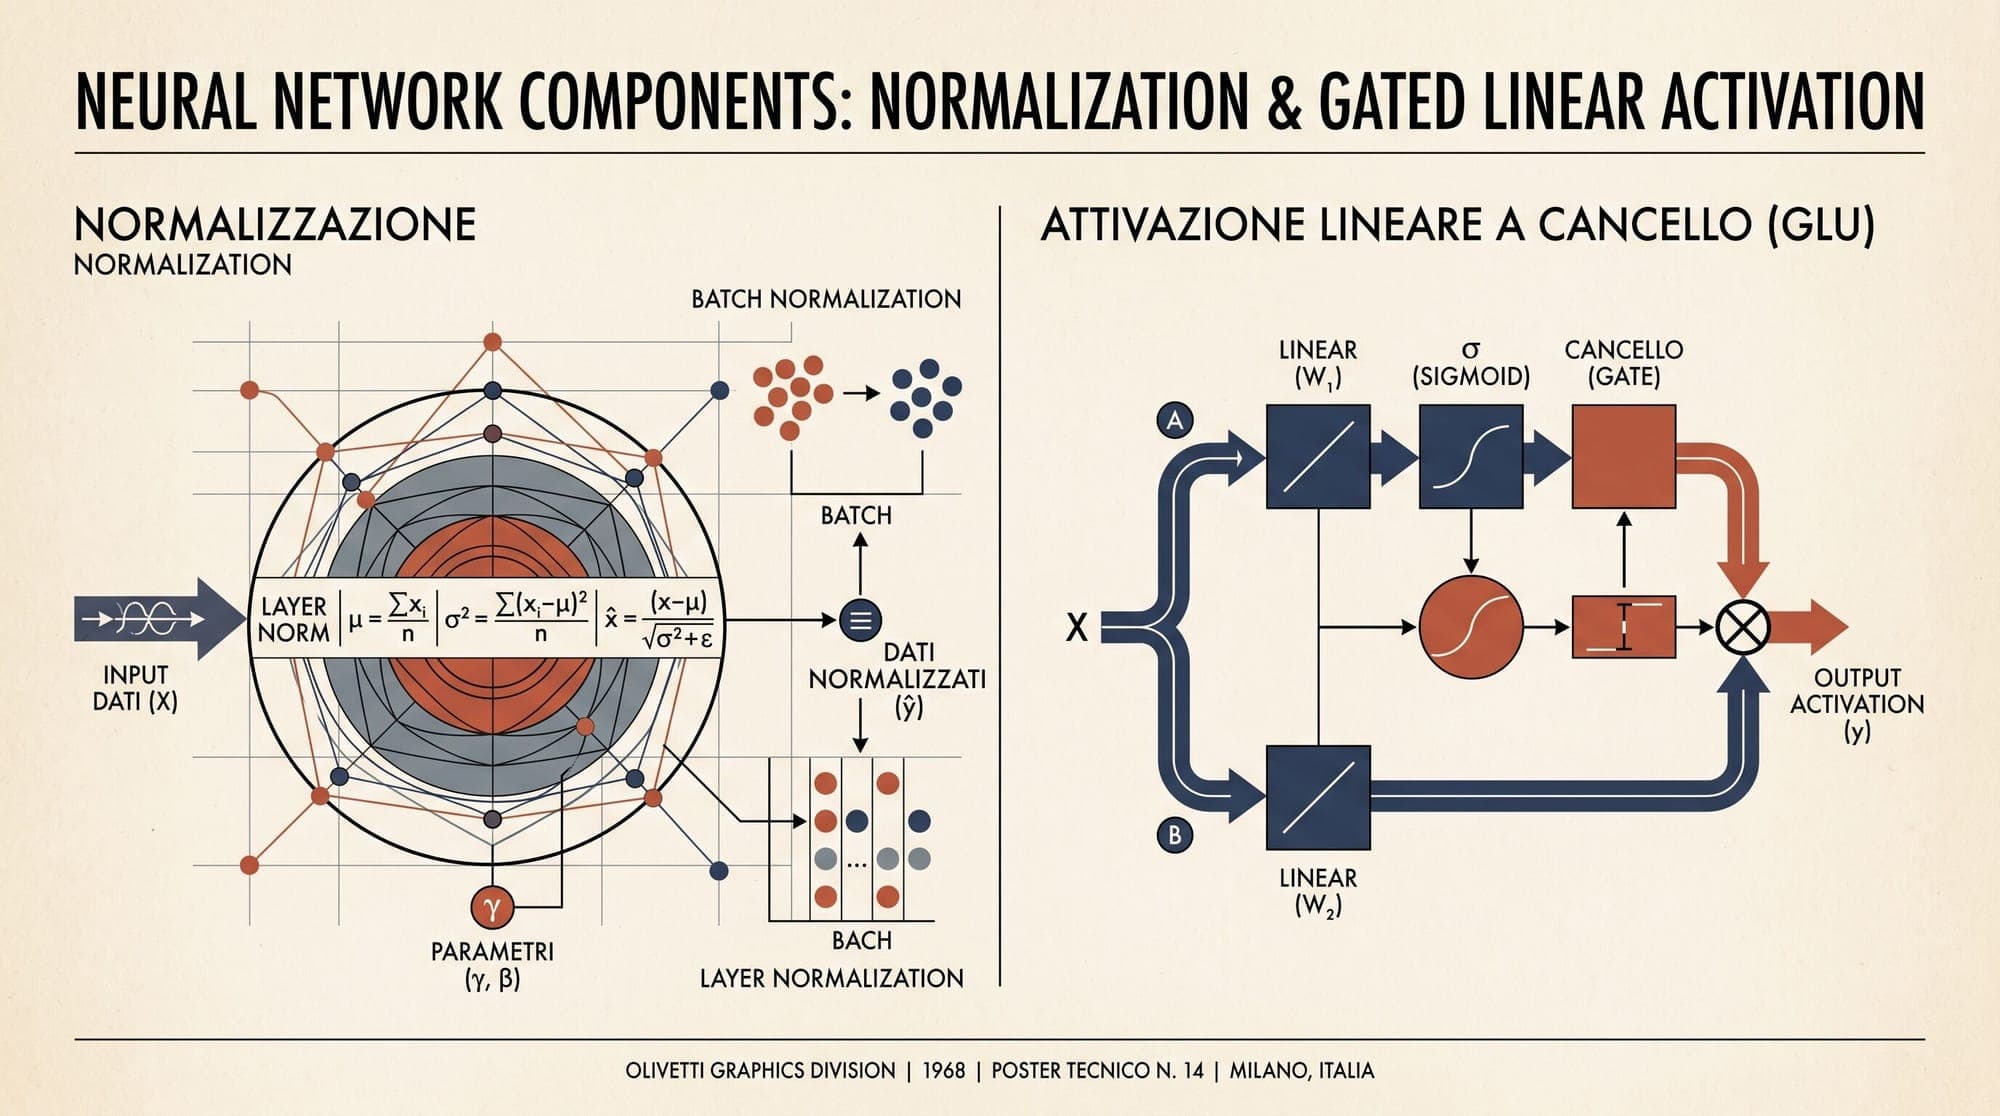
The architectural baseline of modern autoregressive large language models has converged on a distinct set of mathematical primitives. While early Transformer architectures relied on standard Layer Normalization, Post-LN residual routing, and two-layer Multi-Layer Perceptrons with ReLU or GELU activations, state-of-the-art open-weights models such as LLaMA, Mistral, Gemma, Qwen, and DeepSeek utilize a different combination: Root Mean Square Layer Normalization (RMSNorm), Pre-LN residual connectio
Scaling modern large language models beyond tens of billions of parameters quickly exhausts the physical memory and compute throughput of individual graphics processing units. A 70-billion-parameter model stored in 16-bit floating-point (FP16 or BF16) requires 140 GB of VRAM solely for model weights. During full-precision training with the Adam optimizer, parameter states, gradients, and optimizer momentum terms demand approximately 16 to 18 bytes per parameter (amounting to 1.12 TB to 1.26 TB f
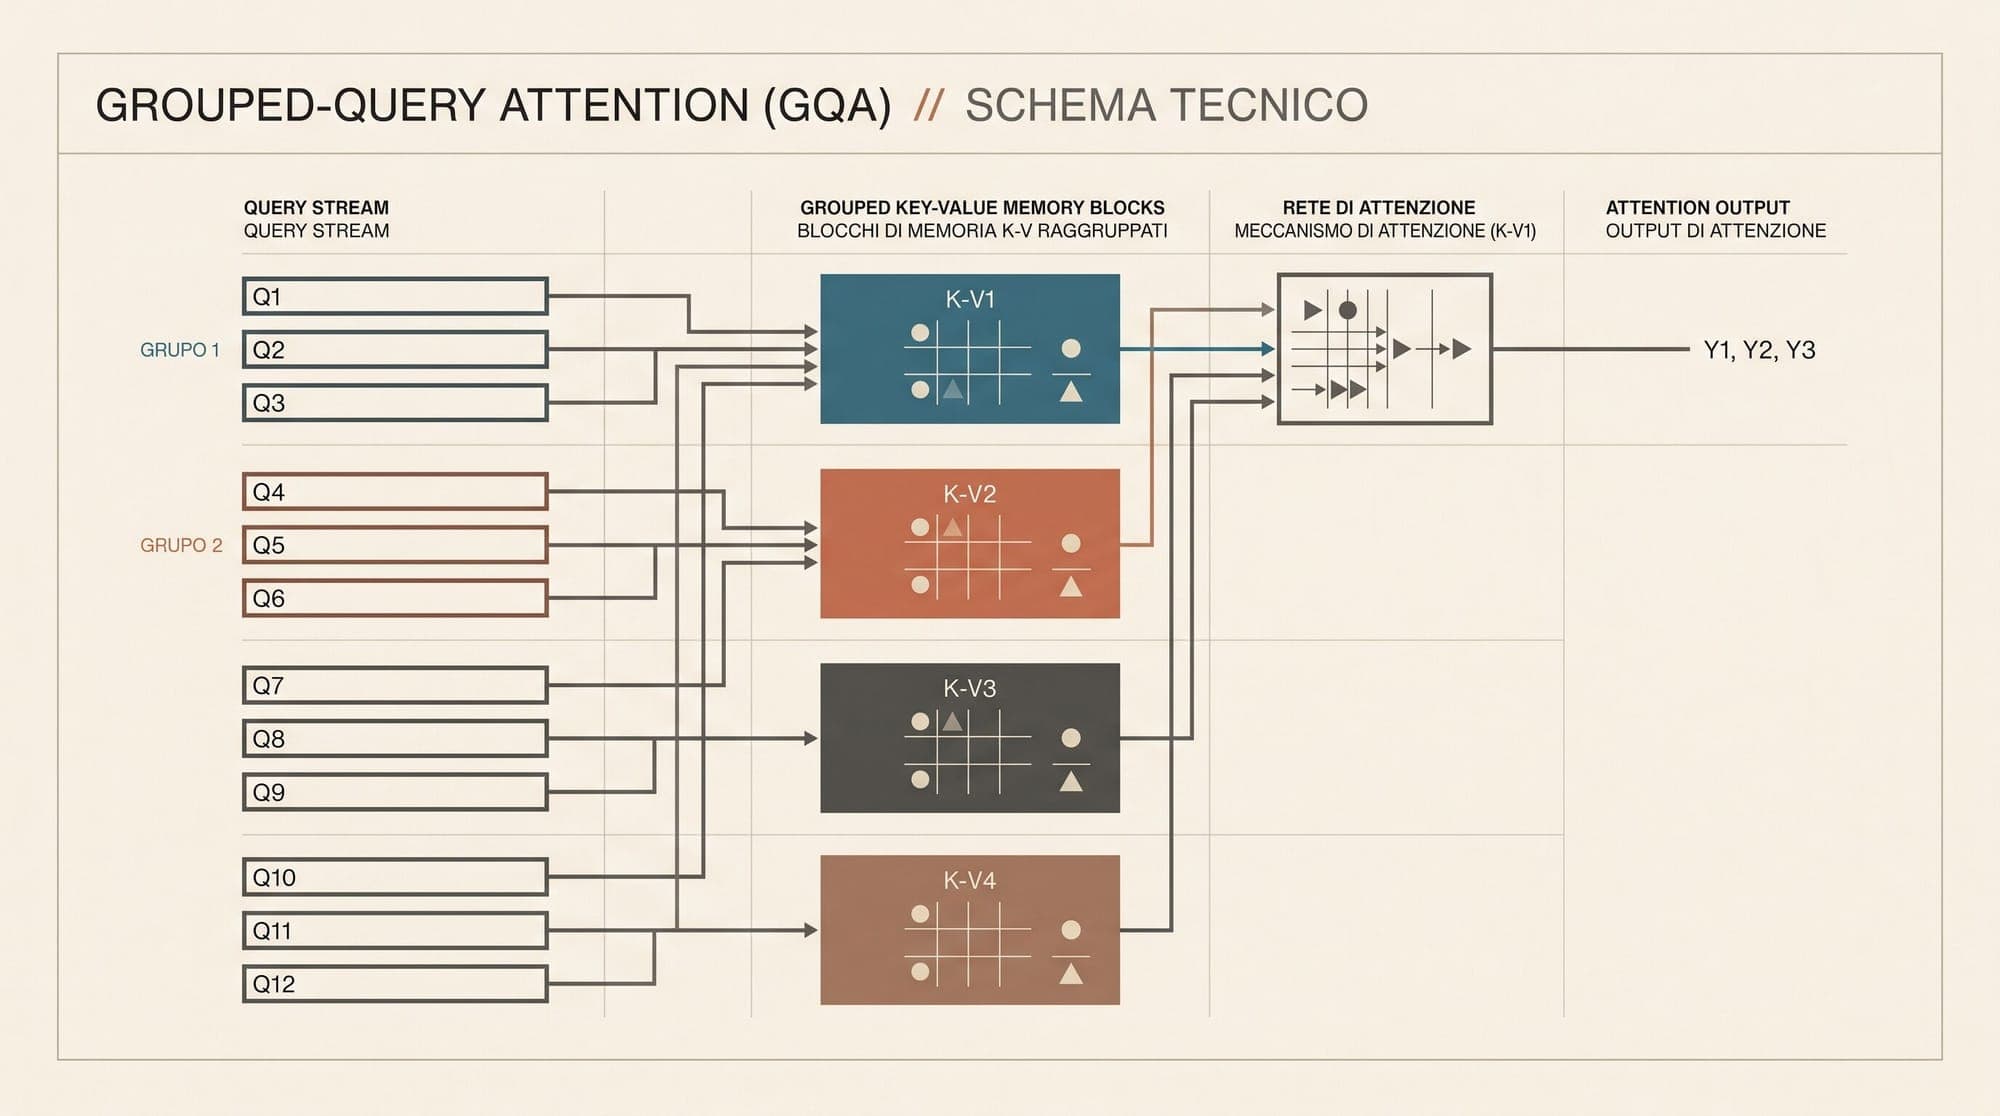
Grouped-Query Attention (GQA) and Multi-Query Attention (MQA): Mathematical Foundations, Arithmetic Intensity, and KV-Cache Scaling Mechanics Autoregressive large language model inference is governed by a fundamental hardware asymmetry. During the initial prompt processing phase (prefill), computation is compute-bound because matrix multiplications process entire sequences in parallel. During sequential token generation (decoding), execution becomes strictly memory-bandwidth bound. For each gen
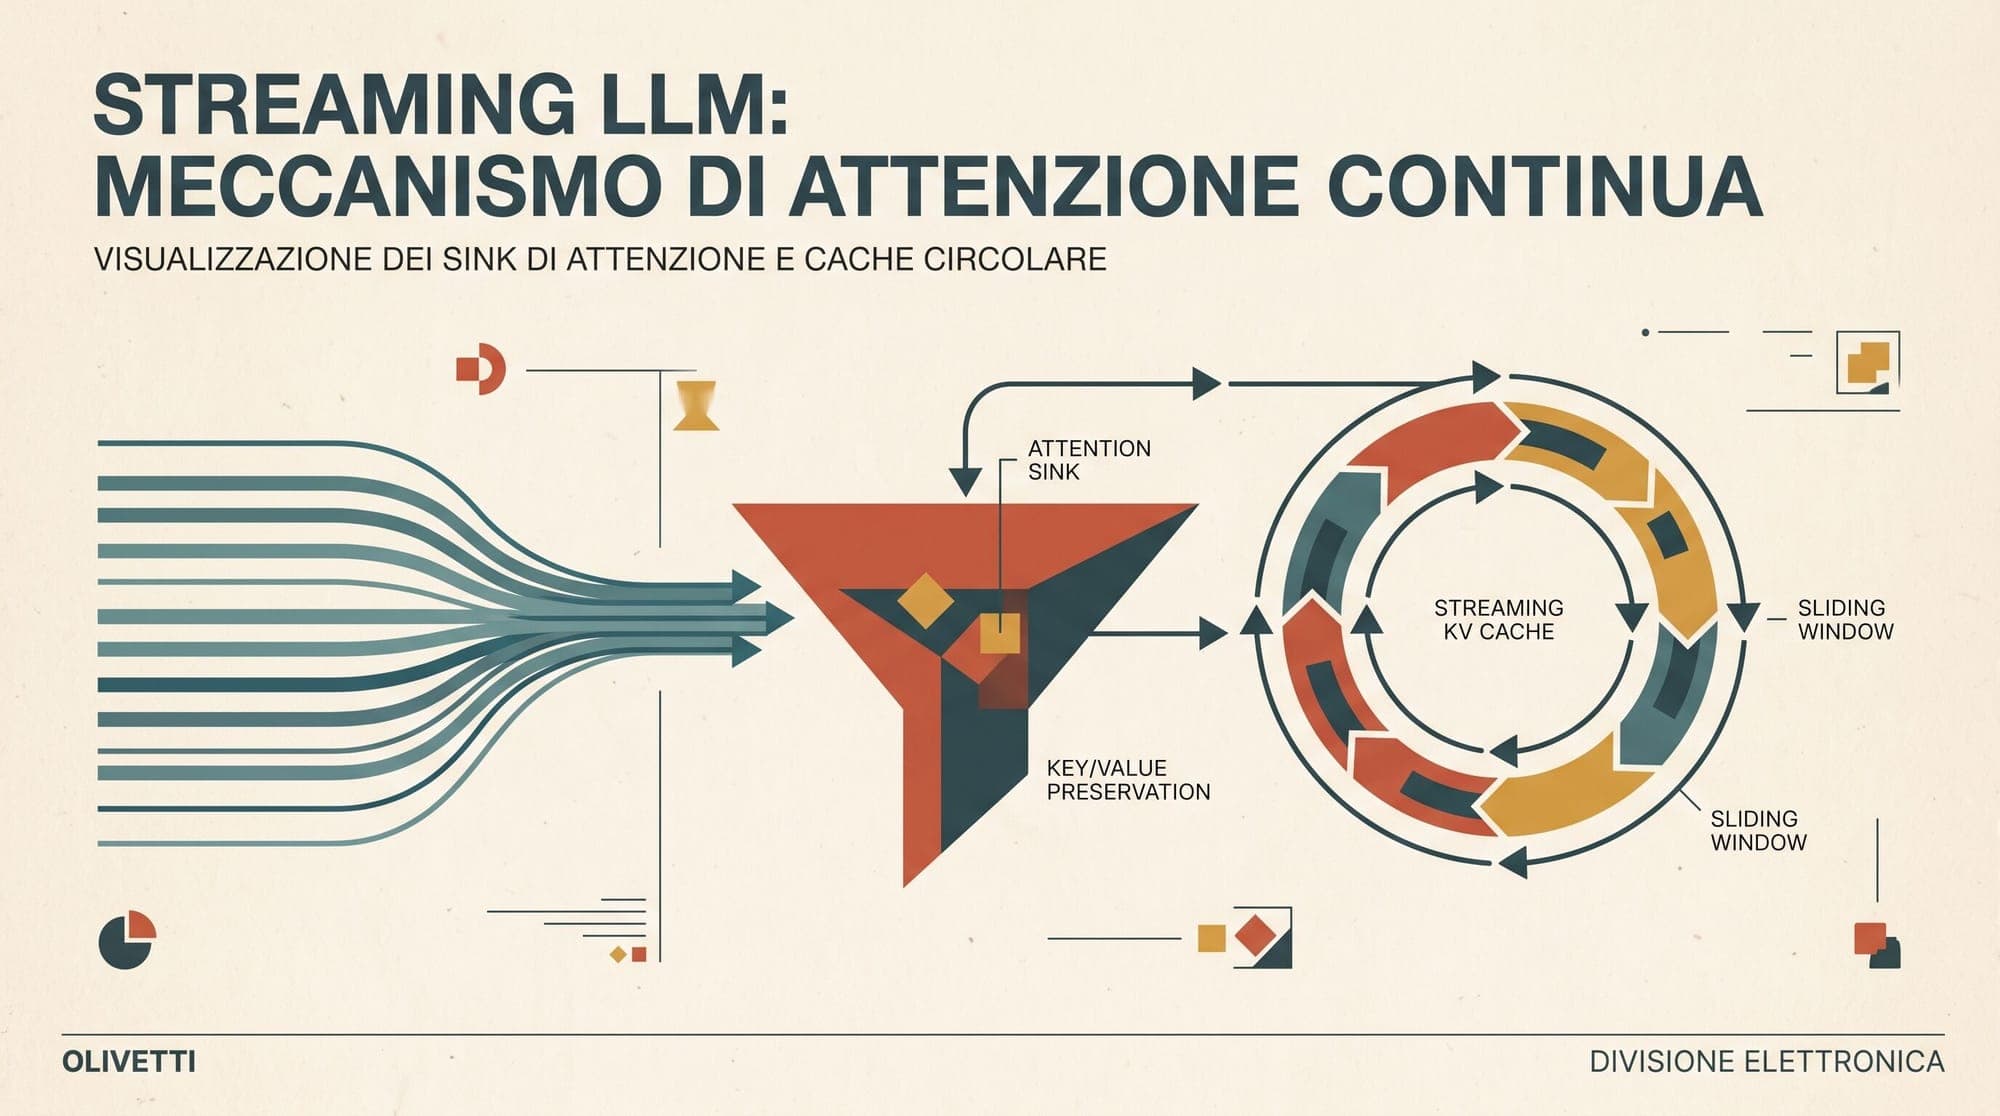
StreamingLLM and Attention Sinks: Mathematical Foundations of Softmax Normalization Artifacts, Initial Token Anchoring, and Infinite-Context Rolling KV-Cache Mechanics In autoregressive Large Language Models (LLMs), long-context deployment is constrained by the quadratic compute complexity of attention and the linear memory growth of the Key-Value (KV) cache. For an LLM processing a sequence of length $L$ with batch size $b$, hidden dimension $d$, and $n_{kv}$ key-value heads across $N_L$ trans
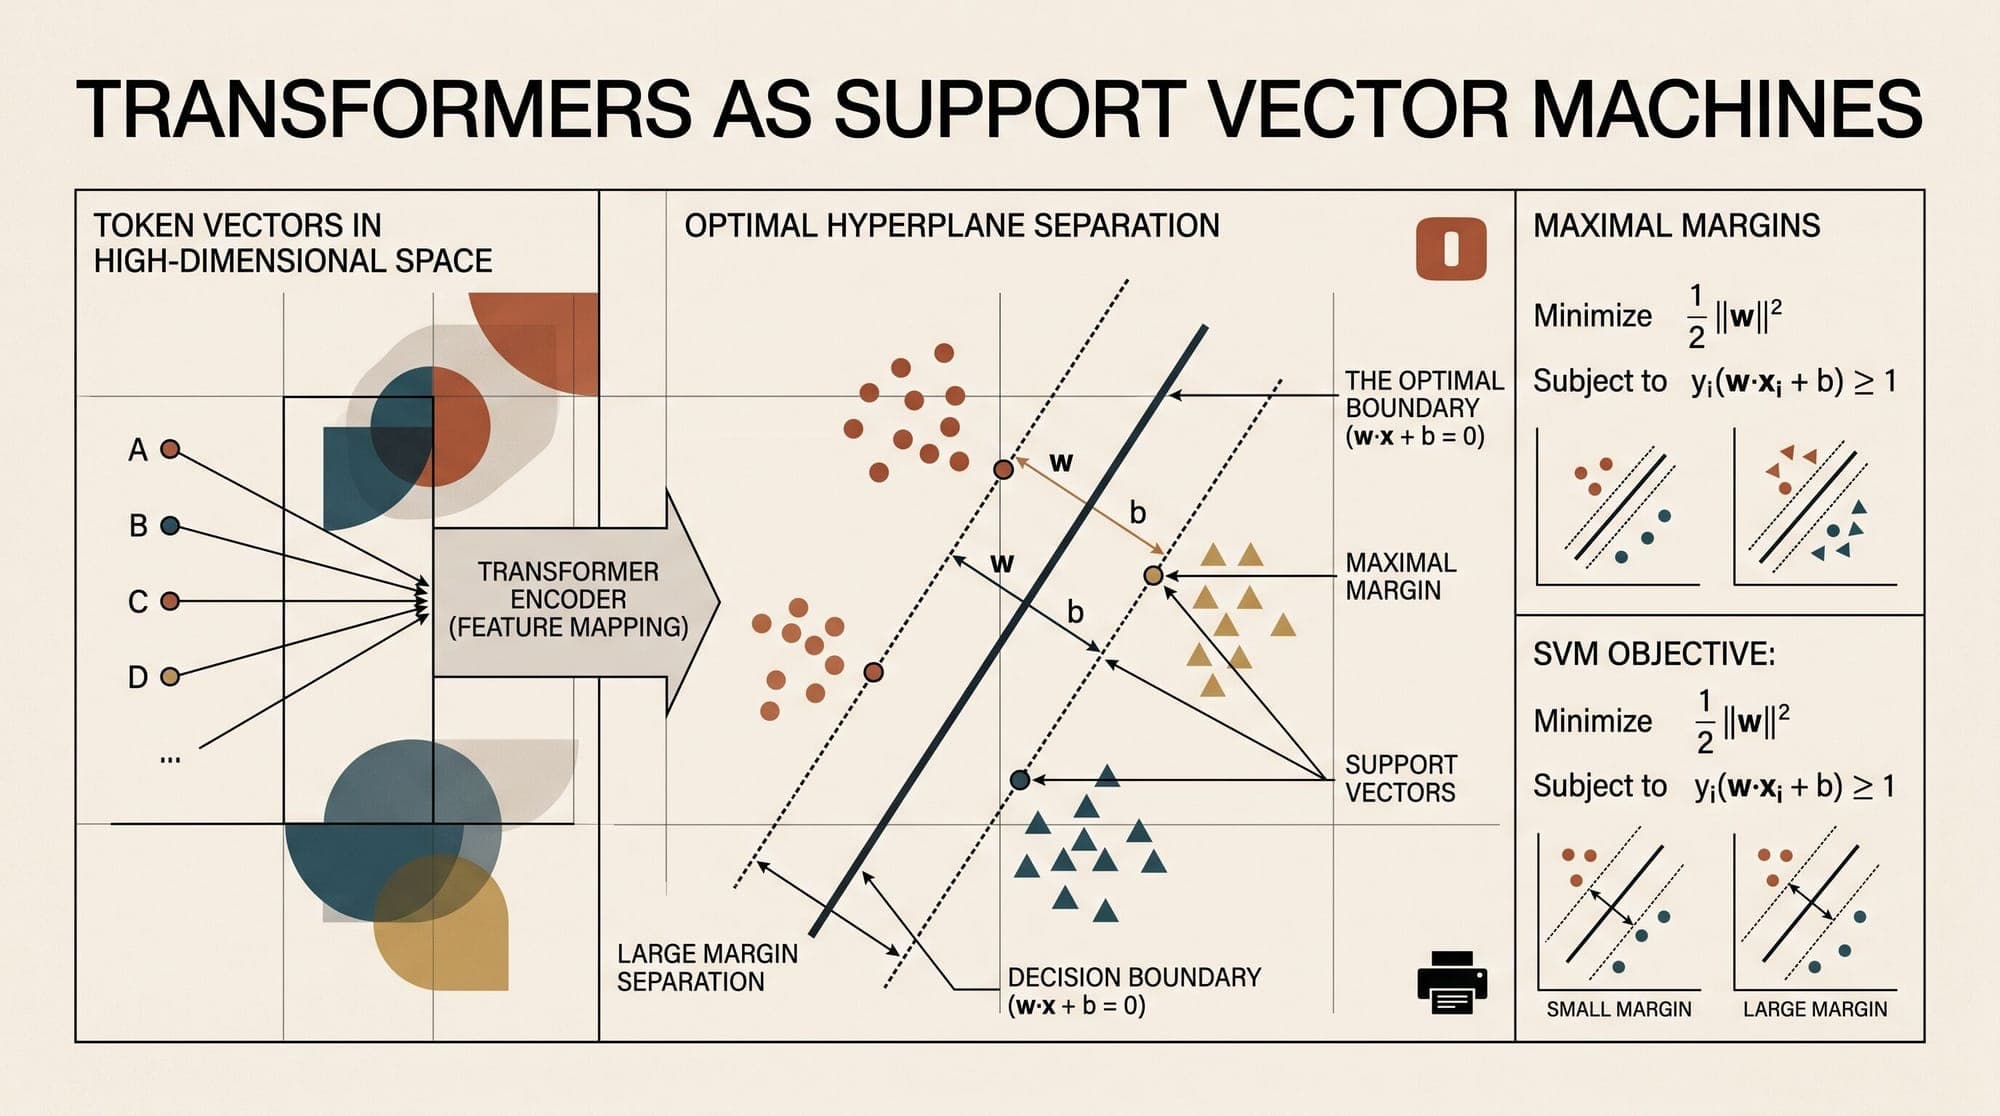
Understanding why overparameterized deep neural networks generalize well despite possessing sufficient capacity to memorize training data remains a fundamental question in theoretical machine learning. In classical linear models trained on separable data under exponential-tailed losses (such as logistic or cross-entropy loss), gradient descent exhibits an implicit bias: parameter iterates diverge in norm while their directions asymptotically converge to the maximum-margin hyperplane, known as th
Large language model inference during autoregressive generation is overwhelmingly memory-bandwidth bound. For batch size 1 decoding, each generated token requires streaming every parameter of a model from High Bandwidth Memory (HBM) into GPU SRAM and Tensor Cores. A 70-billion parameter model in 16-bit precision (FP16 or BF16) requires roughly 140 GB of VRAM, exceeding the capacity of a single 80 GB NVIDIA A100 or H100 GPU and demanding multi-GPU tensor parallelism solely to hold the model weigh