Resources / Tutorials / page 4

Tutorials

116 articles

Articles, page 4

61-80 of 116
  1. Attention with Linear Biases (ALiBi): Mathematical Foundations, Static Positional Biases, and Context Extrapolation in Transformers

    Standard Transformer architectures rely on positional encodings to inject sequence order into permutation-invariant self-attention operations. Early models utilized absolute sinusoidal encodings or learned position embeddings, while subsequent iterations introduced relative positional embeddings and Rotary Position Embedding (RoPE). However, models trained with standard absolute or rotary encodings historically struggled with length extrapolation: evaluating sequences longer than the pre-trainin
    AI
    6 min read
  2. Model Context Protocol (MCP): Architecture, JSON-RPC Primitives, Host-Client-Server Topology, and Standardization in AI Agents

    Before the introduction of standardized integration protocols, connecting Large Language Models (LLMs) to external data stores, business applications, and local developer environments required bespoke glue code. Every agent framework maintained custom integrations for databases, web APIs, and file systems, creating an $M \times N$ integration matrix where $M$ model hosts each implemented unique connectors for $N$ tools. In November 2024, Anthropic published the Model Context Protocol (MCP), an

    AI
    3 min read
  3. KV Cache Eviction and Streaming Attention: Mathematical Foundations, Attention Sink Mechanics, Heavy Hitter Oracles (H2O), and Bounded-Memory Generation

    KV Cache Eviction and Streaming Attention: Mathematical Foundations, Attention Sink Mechanics, Heavy Hitter Oracles (H2O), and Bounded-Memory Generation In autoregressive transformer generation, memory consumption and serving throughput are dominated by the Key-Value (KV) cache. For long-context generation and continuous multi-turn dialogue, the linear growth of the KV cache with sequence length imposes an unsustainable memory footprint and saturates high-bandwidth GPU memory channels. Standar

    AI
    9 min read
  4. Rotary Position Embeddings (RoPE) and Context Window Extension: Mathematical Foundations, Complex Rotations, NTK-Aware Scaling, and YaRN Dynamics

    Autoregressive transformers process input sequences as permutation-invariant collections of token vectors. Without explicit positional encoding, the self-attention mechanism cannot distinguish between different token orderings. While early transformer architectures relied on additive absolute position embeddings (such as learned position tables or fixed sinusoidal encodings) or additive relative position biases, modern frontier large language models have almost universally converged on Rotary Po

    AI
    11 min read
  5. RingAttention and Context Parallelism: Mathematical Foundations, Block-Wise Exact Attention Over Ring Topologies, Overlapped Peer-to-Peer Communication, and Infinite-Context Scaling

    Scaling context windows from thousands to millions of tokens has transformed large language models from localized sequence processors into comprehensive repository analyzers, long-form document synthesizers, and multi-modal world simulators. However, standard self-attention exhibits quadratic computational and memory complexity with respect to sequence length $S$. While IO-aware memory optimizations like FlashAttention eliminate intermediate attention matrix materialization in High Bandwidth Mem

    AI
    13 min read
  6. Anthropic Rolls Out Claude for Teachers to K-12 Schools and Districts with Free Enterprise Tier and FERPA Compliance

    Anthropic has expanded its Claude for Teachers program from individual educator access to a centralized, district-wide Enterprise offering for K-12 public and private schools. Qualifying educational organizations that enroll before June 30, 2027 receive one year of free enterprise access across their instructional and administrative staff. The update introduces centralized administrative controls, domain capture, single sign-on (SSO), role-based access control, and dedicated K-12 terms aligned

    AI
    2 min read
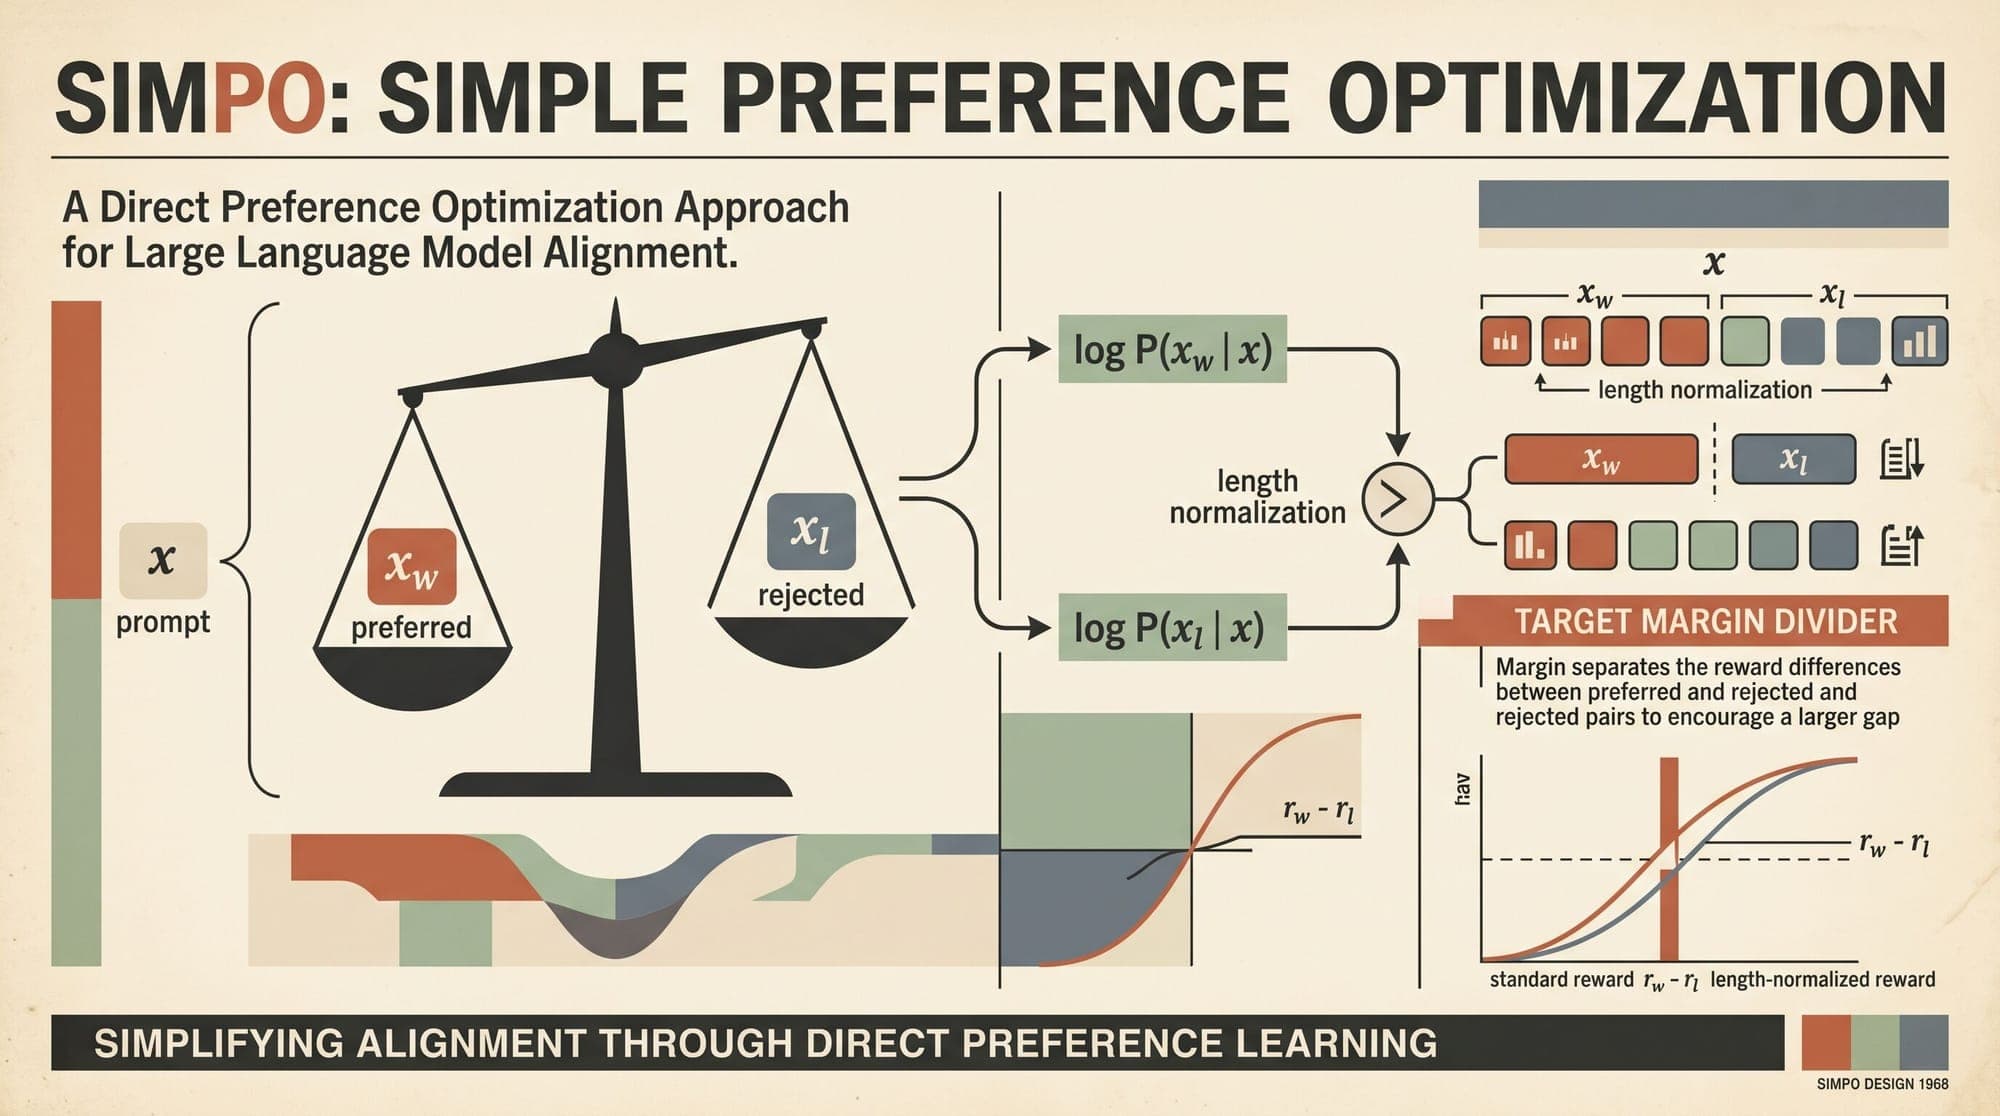
  7. Simple Preference Optimization (SimPO): Mathematical Foundations, Reference-Free Implicit Reward, Length Normalization, and Target Margin Dynamics

    Simple Preference Optimization (SimPO): Mathematical Foundations, Reference-Free Implicit Reward, Length Normalization, and Target Margin Dynamics Post-training preference alignment has become the definitive step in transforming raw pretrained large language models into instruction-following assistants. While Reinforcement Learning from Human Feedback (RLHF) via Proximal Policy Optimization (PPO) established the initial standard, its requirement to maintain actor, critic, reference, and reward

    AI
    11 min read
  8. OpenAI Partners with Thai Government to Launch Accelerator for Healthcare and Education Startups

    OpenAI has partnered with Thailand's Ministry of Higher Education, Science, Research and Innovation (MHESI) to launch an eight-week accelerator program supporting ten Thai startups building AI products in healthcare, wellness, and education. The initiative, announced in Bangkok, represents OpenAI's first public-private partnership focused on startup acceleration with the Thai government. Participating organizations include Thailand's National Innovation Agency (NIA), Mahidol University, and Tec

    OpenAI
    2 min read
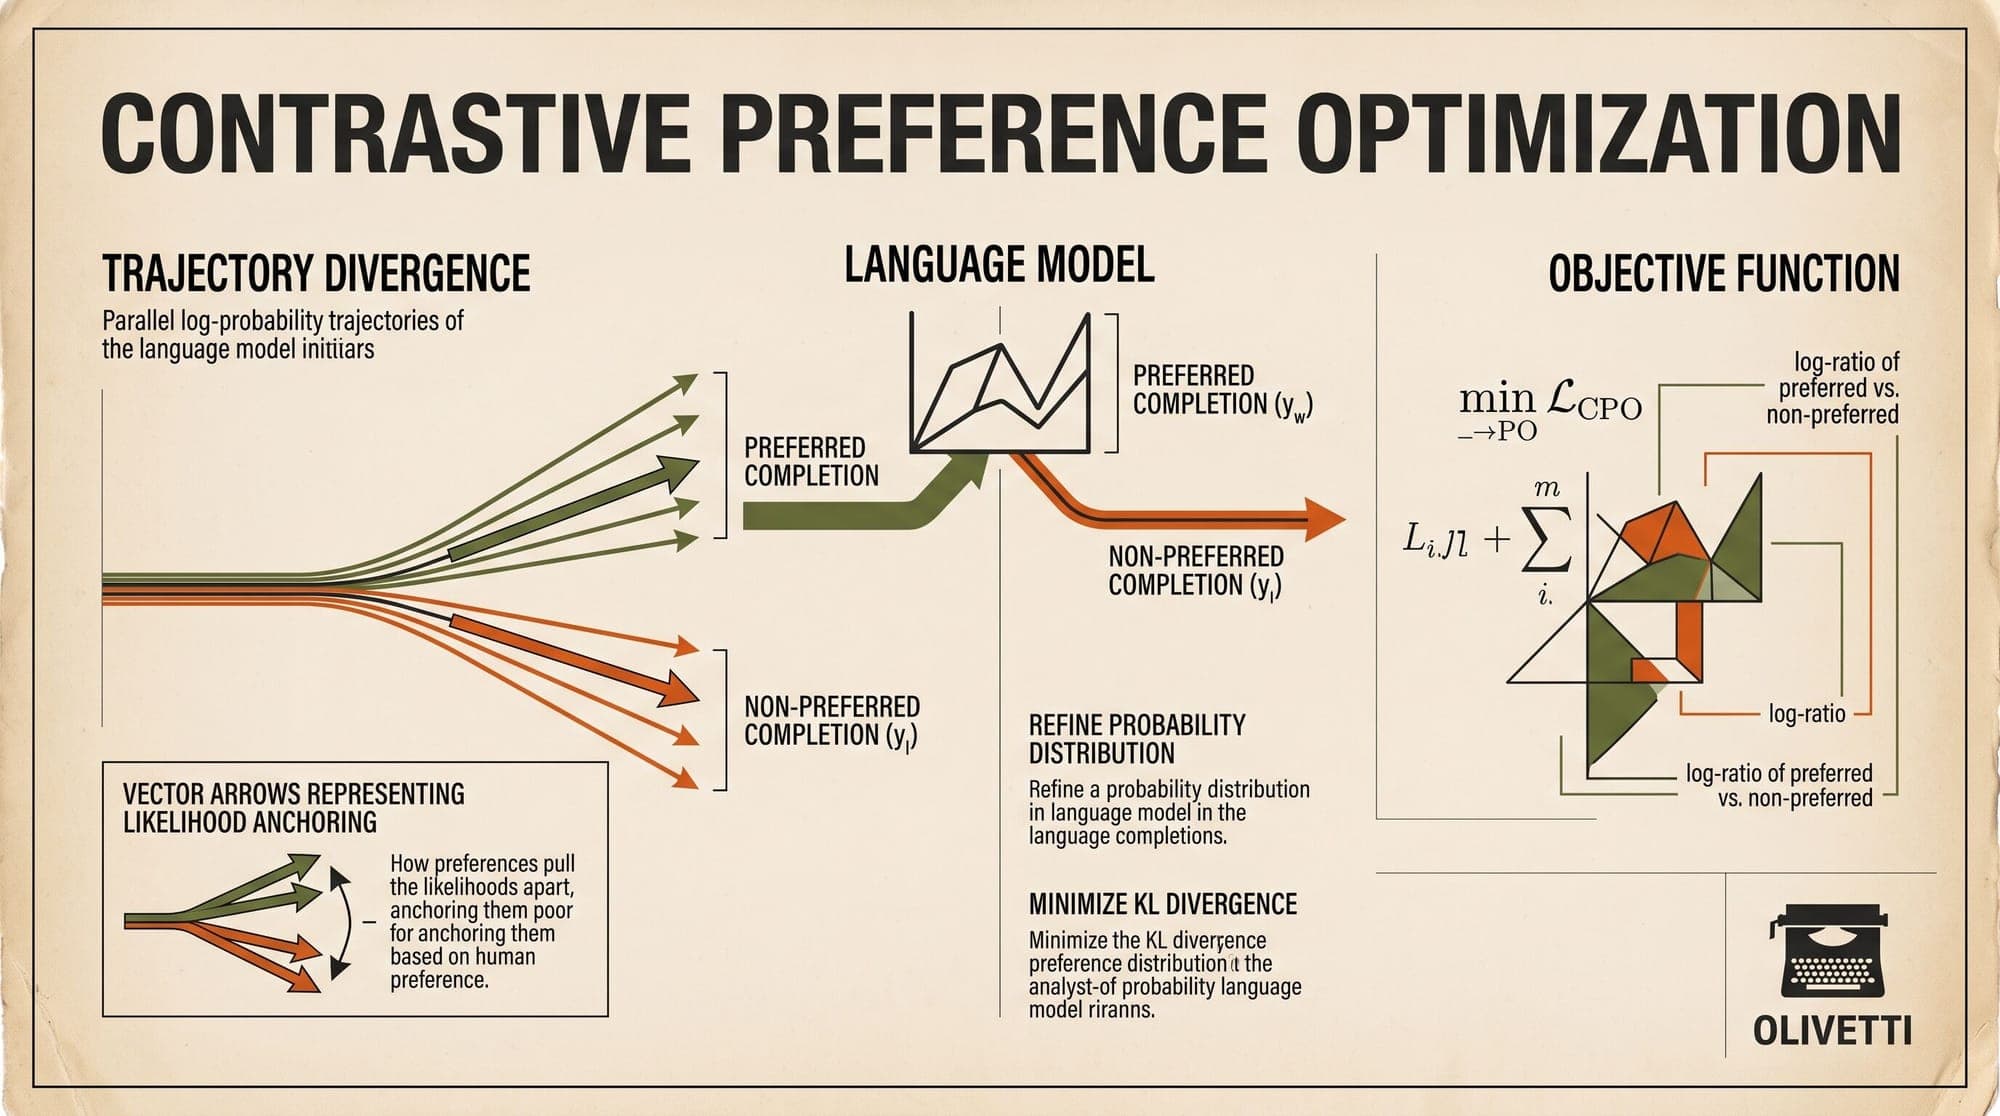
  9. Contrastive Preference Optimization (CPO): Mathematical Foundations, Direct Likelihood Regularization, Out-of-Distribution Error Bounds, and Non-Degenerate Policy Alignment

    Supervised fine-tuning (SFT) and preference alignment represent the standard two-stage training paradigm for post-training large language models. While SFT establishes foundational task adherence by minimizing cross-entropy loss against target references, it suffers from two structural limitations: it cannot surpass the quality ceiling of its training demonstrations, and it lacks an explicit mechanism to penalize near-correct outputs that contain subtle hallucinations or omissions. Direct Prefe

    AI
    11 min read
  10. Chinchilla Scaling Laws: Mathematical Foundations of Compute-Optimal Pre-Training, IsoFLOP Loss Profiles, Parametric Power Laws, and Data-Compute Allocation

    Chinchilla Scaling Laws: Mathematical Foundations of Compute-Optimal Pre-Training, IsoFLOP Loss Profiles, Parametric Power Laws, and Data-Compute Allocation When allocating a fixed computational budget to train an autoregressive Transformer, engineers face a fundamental trade-off: should FLOPs be spent increasing the model parameter count ($N$), or should they be spent streaming a larger volume of training tokens ($D$)? For several years, frontier AI development followed the empirical scaling

    AI
    14 min read
  11. Matryoshka Representation Learning (MRL): Mathematical Foundations, Multi-Scale Loss Optimization, and Adaptive Vector Retrieval

    Matryoshka Representation Learning (MRL) has become the standard architectural foundation for modern dense text embeddings. Introduced by Kusupati et al. at NeurIPS 2022 and subsequently deployed across frontier embedding models like OpenAI text-embedding-3, Nomic Embed, and BAAI BGE-M3, MRL solves a structural inefficiency in vector retrieval: the rigid coupling between embedding dimensionality, memory consumption, and semantic fidelity. Traditional dense encoders project arbitrary text sequen

    AI
    9 min read
  12. Knowledge Distillation in Large Language Models: Mathematical Foundations of Forward vs. Reverse KL Divergence, Sequence-Level Distillation (SeqKD), and On-Policy Mode-Seeking Objectives

    Deploying frontier large language models in latency-critical and compute-constrained environments remains an active challenge in artificial intelligence systems. While parameter scale correlates directly with downstream generalization and emergent reasoning capabilities, the memory footprint and FLOP intensity of dense multi-hundred-billion parameter architectures impose prohibitive operational costs. Post-training compression strategies such as quantization and structural pruning reduce precisi

    AI
    11 min read
  13. Model Merging in Weight Space: Mathematical Foundations of Task Vectors, TIES-Merging, DARE, and Spherical Linear Interpolation

    Training large language models across multiple downstream domains typically requires expensive multi-task supervised fine-tuning (SFT) or sequential continual learning. Both paths present steep practical challenges: multi-task training demands simultaneous access to massive, curated datasets and massive compute budgets, while sequential fine-tuning suffers from catastrophic forgetting. Model merging has emerged as a data-free, compute-efficient alternative. By combining the parameters of multip

    AI
    8 min read
  14. State Space Models (SSMs) and Mamba: Mathematical Foundations of Continuous-Time Discretization, Selective Scan Mechanics, and Structured State Space Duality

    Autoregressive Large Language Models (LLMs) built on the standard Transformer architecture rely on softmax self-attention. While self-attention provides expressive in-context learning and dense token-to-token associative recall, it exhibits fundamental algorithmic scaling limits: prefill compute scales quadratically with sequence length ($O(L^2 d)$), and autoregressive token generation requires maintaining a Key-Value (KV) cache that grows linearly with sequence length ($O(L d)$). At context win

    AI
    12 min read
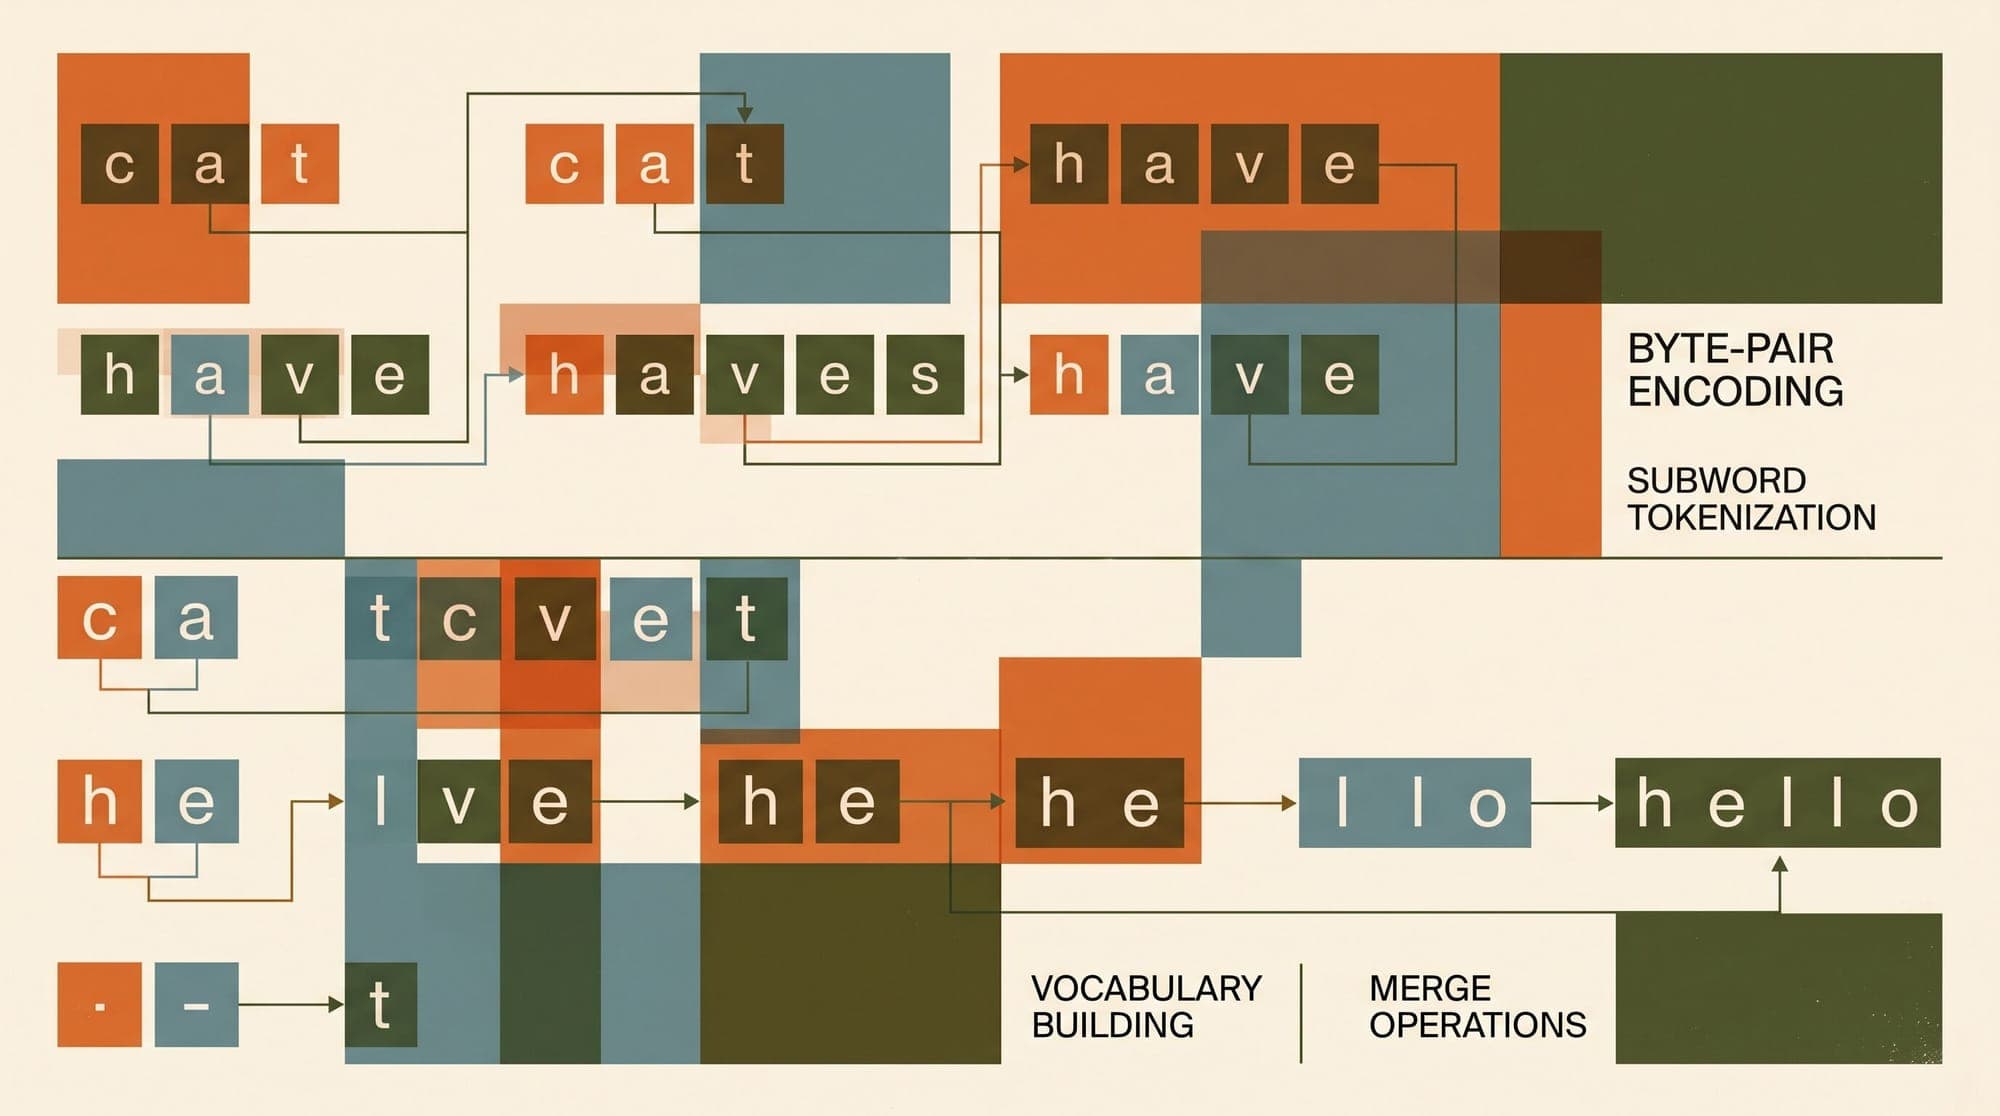
  15. Byte-Pair Encoding (BPE) and Modern Subword Tokenization: Mathematical Foundations, Merge Dynamics, Byte-Level Encodings, and Vocabulary Compression Mechanics

    Tokenization is the discrete boundary interface between raw textual sequences and the continuous vector representations of autoregressive large language models. Before an attention block computes a single inner product or a feed-forward network applies an activation function, an input string must be mapped into an ordered sequence of discrete integer identifiers drawn from a finite vocabulary $V$. The design and mathematical properties of this mapping govern key operational characteristics of l

    AI
    11 min read
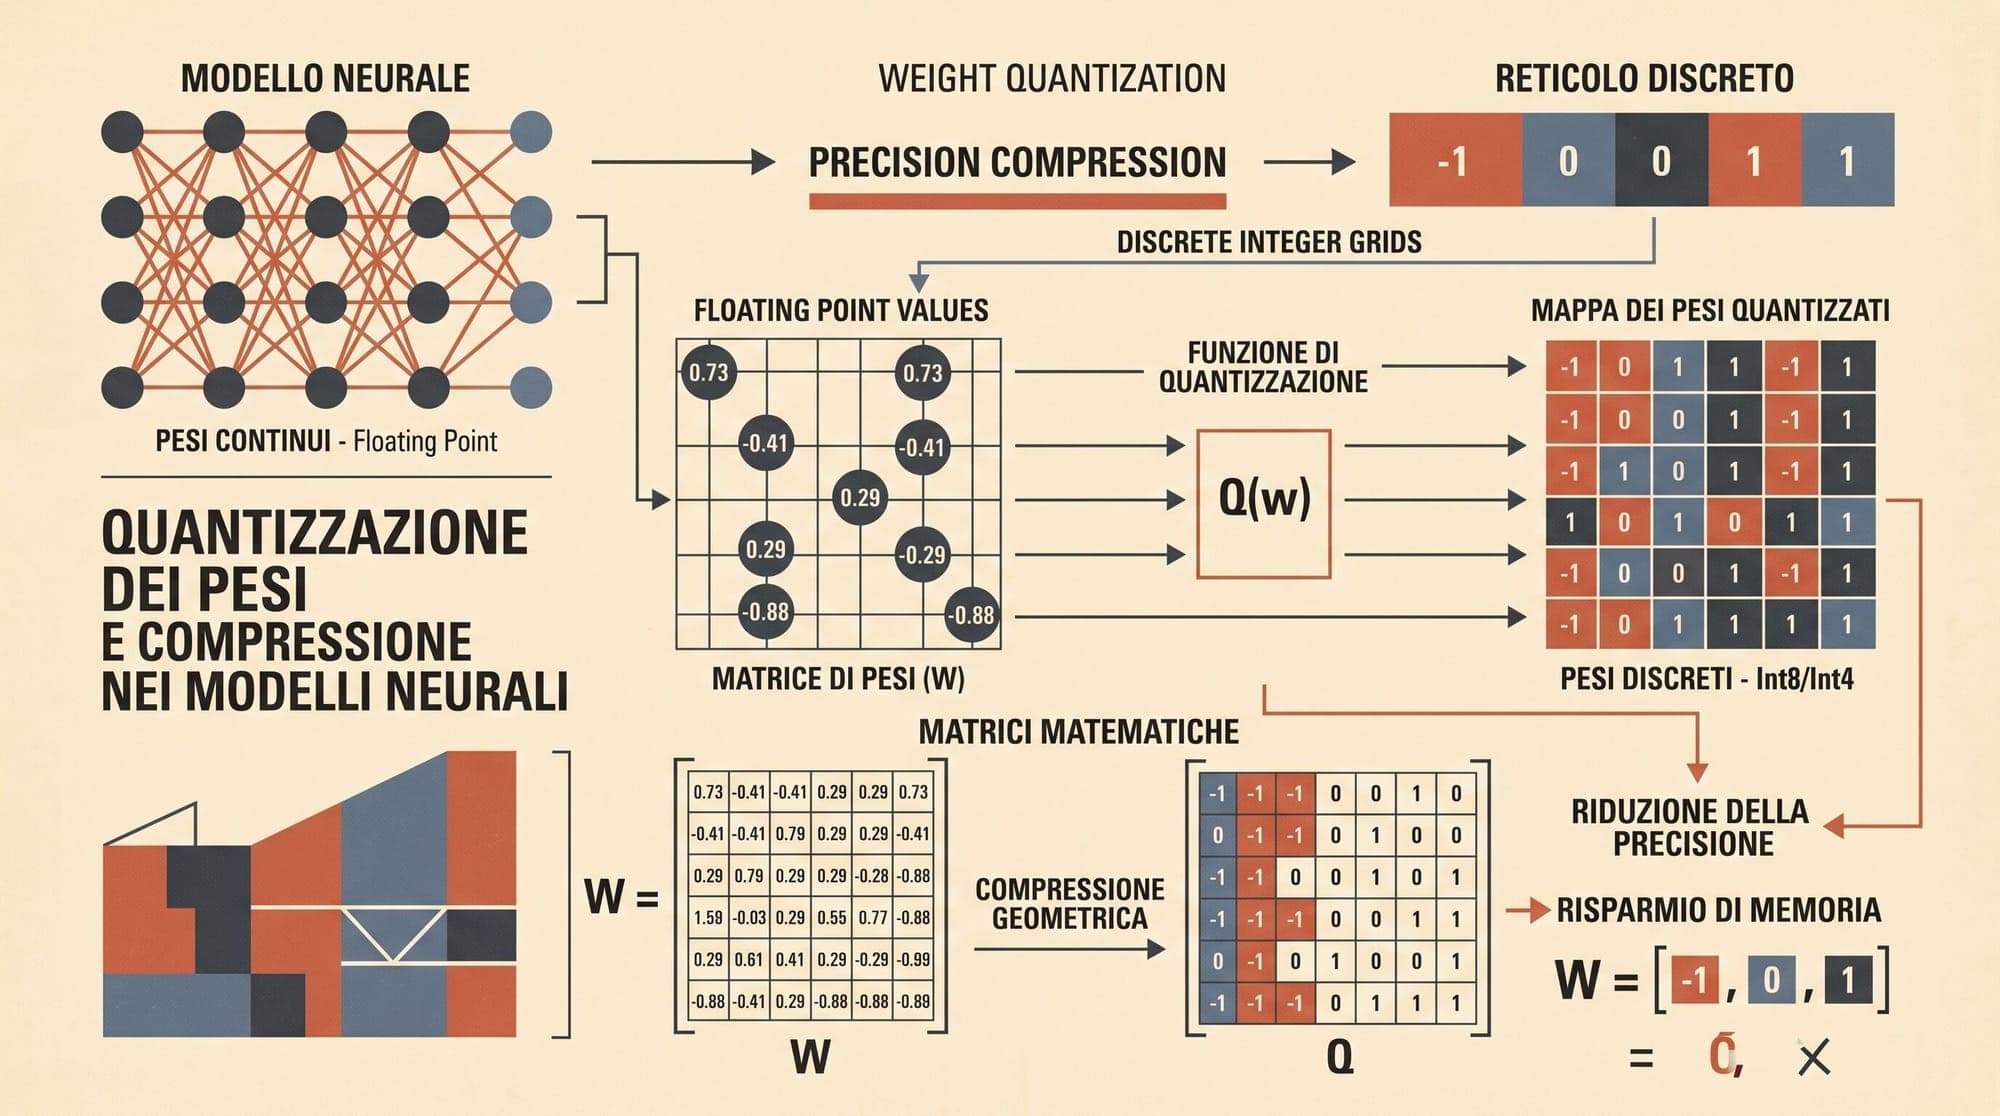
  16. Post-Training Quantization (PTQ): Mathematical Foundations of Optimal Brain Surgeon, GPTQ Hessian Inversion, AWQ Salient Scaling, and SmoothQuant Outlier Migration

    Post-Training Quantization (PTQ): Mathematical Foundations of Optimal Brain Surgeon, GPTQ Hessian Inversion, AWQ Salient Scaling, and SmoothQuant Outlier Migration Serving modern large language models at scale requires addressing severe hardware constraints. In autoregressive generation, decoding is fundamentally bounded by memory bandwidth rather than floating-point computation throughput. Each generated token requires reading every parameter from High Bandwidth Memory (HBM) into SRAM to perfo

    AI
    10 min read
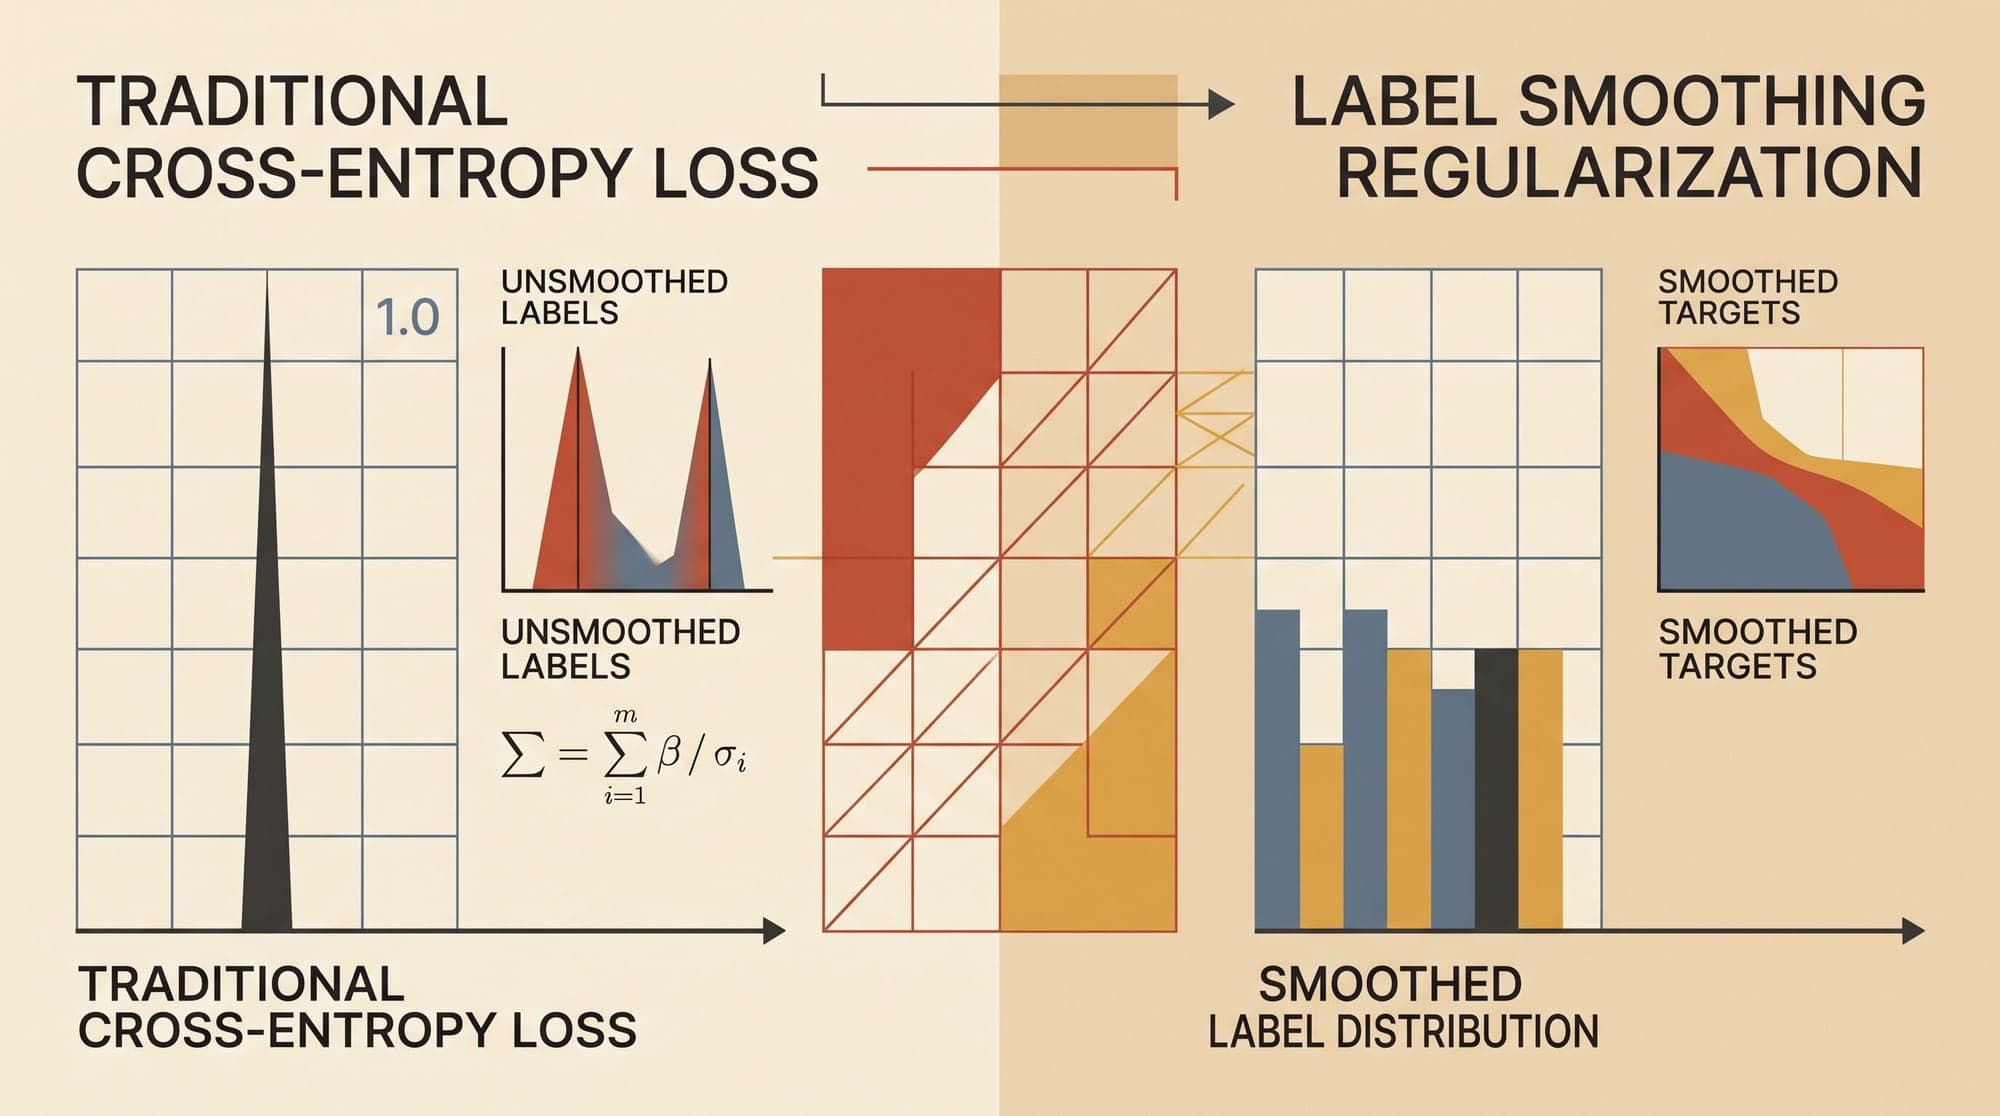
  17. Label Smoothing Regularization: Mathematical Foundations, Maximum Entropy Dynamics, and the Regular Simplex Geometry in LLMs

    In supervised classification and autoregressive language modeling, standard cross-entropy loss trains neural networks against discrete, one-hot target distributions. While intuitive, one-hot supervision creates an inherent optimization pathology: minimizing the cross-entropy objective to zero requires pushing the logit of the target class toward positive infinity while driving all competing non-target logits toward negative infinity. In deep networks, this dynamic inflates parameter norms, cause

    AI
    11 min read
  18. SmoothQuant: Mathematical Foundations, Per-Channel Outlier Migration, and Hardware-Efficient W8A8 Inference in Large Language Models

    SmoothQuant: Mathematical Foundations, Per-Channel Outlier Migration, and Hardware-Efficient W8A8 Inference in Large Language Models Serving large language models (LLMs) in production environments presents two distinct hardware bottlenecks. During the autoregressive generation (decode) phase with small batch sizes, inference is memory-bandwidth bound, as billions of parameters must be streamed from High Bandwidth Memory (HBM) to on-chip SRAM for every generated token. Conversely, during the pro

    Quantization
    12 min read
  19. Kahneman-Tversky Optimization (KTO): Mathematical Foundations, Prospect Theory, and Binary Signal Alignment in Large Language Models

    Post-training alignment of large language models has long relied on pairwise comparison datasets. Methods such as Reinforcement Learning from Human Feedback (RLHF) and Direct Preference Optimization (DPO) assume access to curated pairs $(x, y_w, y_l)$, where a human or automated judge explicitly marks completion $y_w$ as superior to $y_l$ for a given prompt $x$. In production environments, however, collecting paired preferences is logistically complex, expensive, and artificial. Real-world telem

    Explainers
    10 min read
  20. Curriculum Learning in Large Language Models: How Difficulty Pacing, Competence Progression, and Task Scheduling Shape Training Dynamics

    In standard large language model pre-training and fine-tuning pipelines, training batches are almost universally sampled uniformly and independently at random from a static corpus: $$\mathcal{D} = \{z_i = (x_i, y_i)\}_{i=1}^N$$ While this independent and identically distributed (i.i.d.) sampling paradigm aligns with empirical risk minimization (ERM), it ignores the non-convex geometry of deep transformer loss surfaces. Early in training, when network parameters are randomly initialized or unal

    Explainers
    12 min read