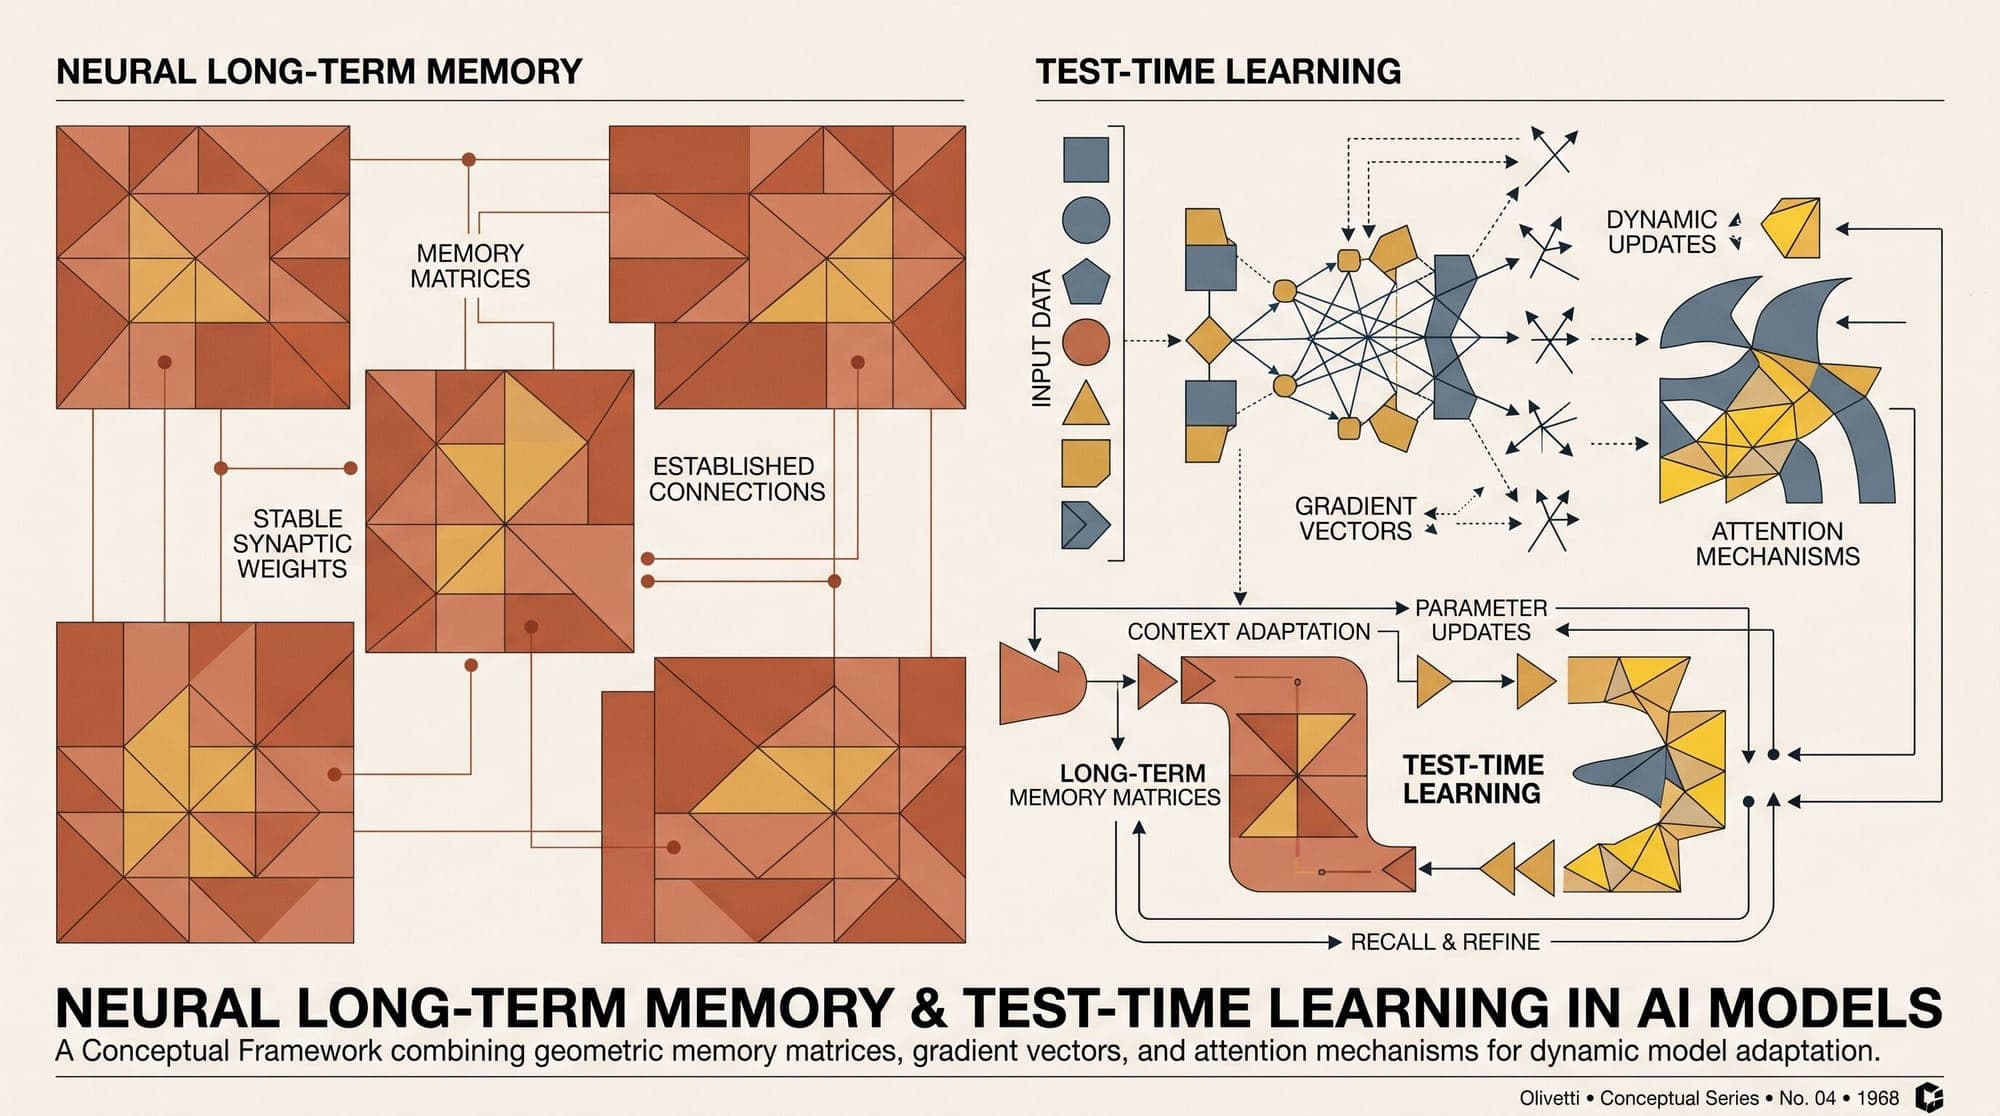
Titans: Learning to Memorize at Test Time — Mathematical Foundations of Neural Long-Term Memory, Surprise-Driven Gradient Updates, Adaptive Forgetting, and Context Scaling
Sequence modeling in large language models has long been caught in a fundamental trade-off between attention mechanisms and recurrent architectures. Softmax attention provides precise associative recall over all tokens in the active context window, but incurs quadratic computational and memory complexity, $O(N^2)$, with respect to sequence length $N$. Conversely, linear recurrent models, such as State Space Models (Mamba, Mamba-2) and linear Transformers (GLA, RetNet, DeltaNet), compress sequenc