What Is Hugging Face? The AI Model Hub Explained for Beginners
The Hugging Face Hub hosts millions of open AI models, datasets and apps. Learn how to read a model card, check the license and run a model yourself.
The Hugging Face Hub hosts millions of open AI models, datasets and apps. Learn how to read a model card, check the license and run a model yourself.
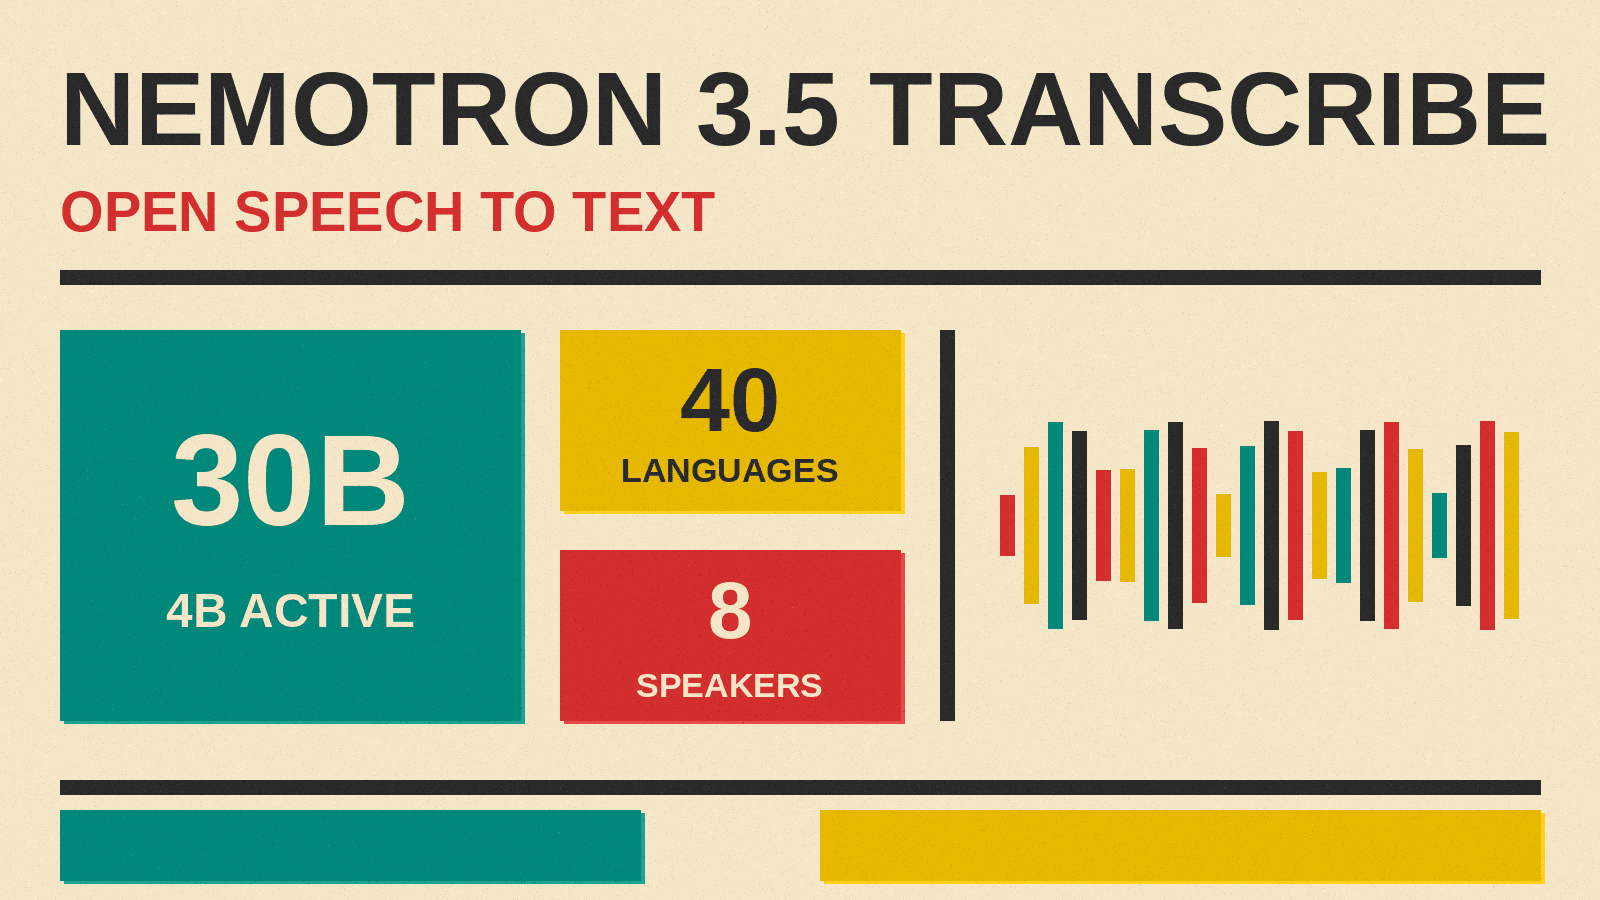
NVIDIA's open-weight Nemotron 3.5 Transcribe transcribes 40 languages, labels speakers and translates. NVIDIA also opened Granary v2, the data behind it.
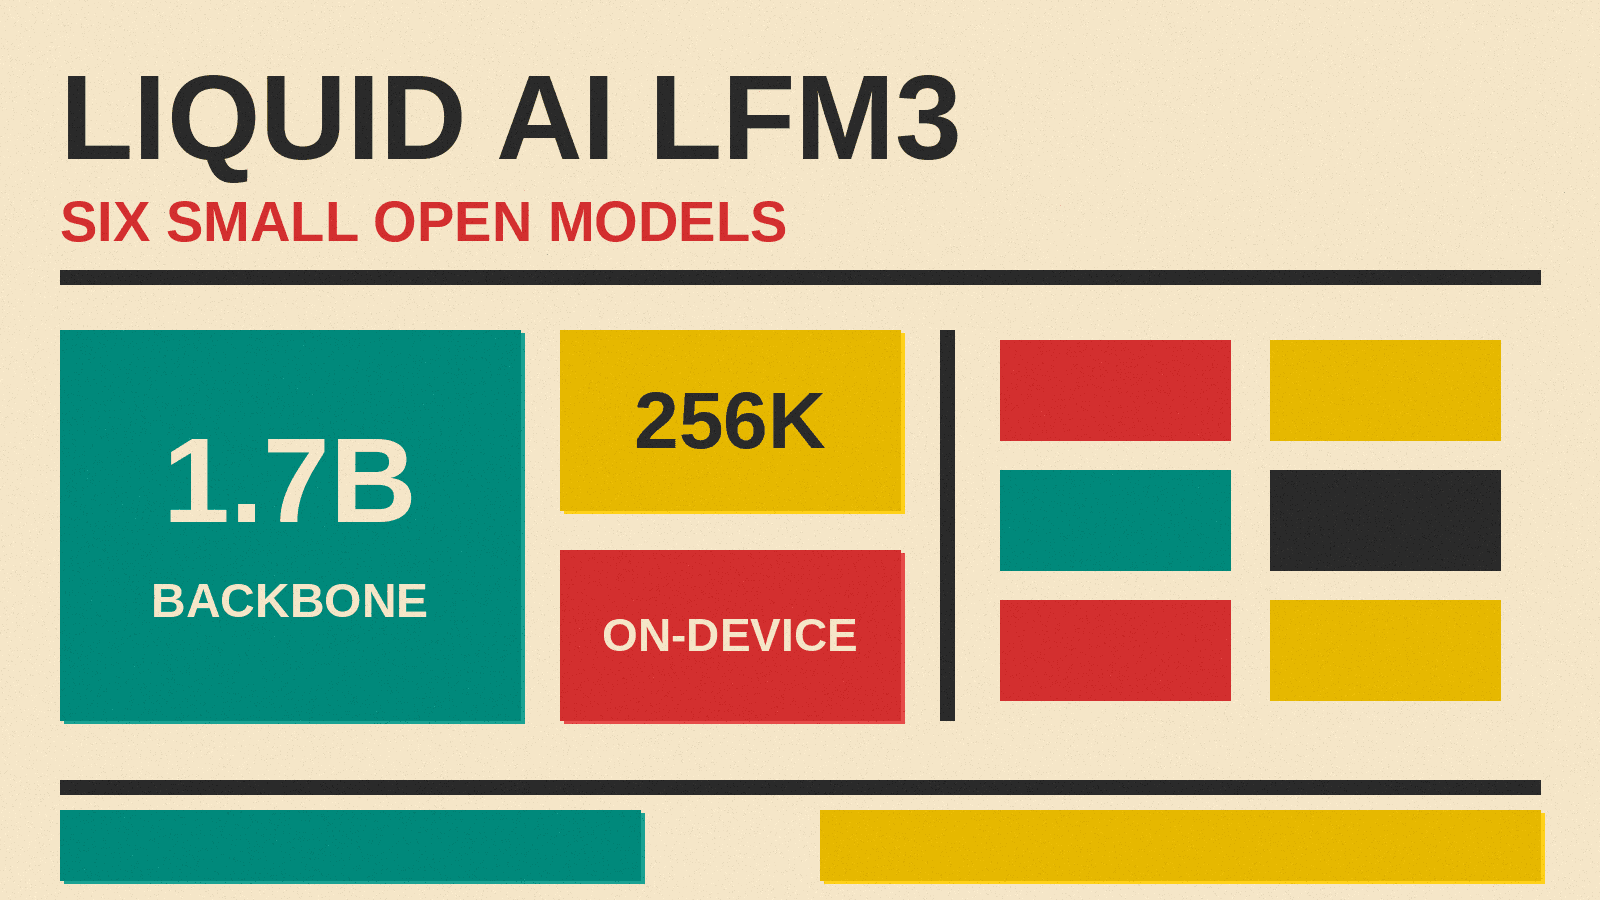
Liquid AI's LFM3 is six open-weight 2B-class models for text, vision, audio, omni input and decisions, built on one 1.7B base. Specs, scores and license terms.
Tencent's open Apache-2.0 Hy-SimulMT translates Chinese and English speech as the speaker talks. Its benchmarks, what it needs to run and its limits.
Maya Research released open Apache-2.0 weights for Maya 2 Native, a streaming TTS model for 11 Indian languages and English with 20 voices and cloning.
Ant Group's inclusionAI released Ling-3.1-flash-1019, a post-training update to its 560B MIT open model, plus the base model: scores, uses and hardware.
Open-weight models come in files labeled Q8_0, Q4_K or IQ2_XXS. They are the same model stored with fewer bits per weight. Here is what quantization is, how GGUF labels work, what you give up, and how to pick a file that fits your computer.
Six open-weight coding models to download as of October 2026, from GLM-5.3 to Recursive Flint, with self-reported benchmarks, hardware needs and licenses.
Destined AI's Hurston-1 is an open Apache-2.0 text-to-speech model for Southern American and African English accents, with an 8 kHz phone mode, tested by its maker.
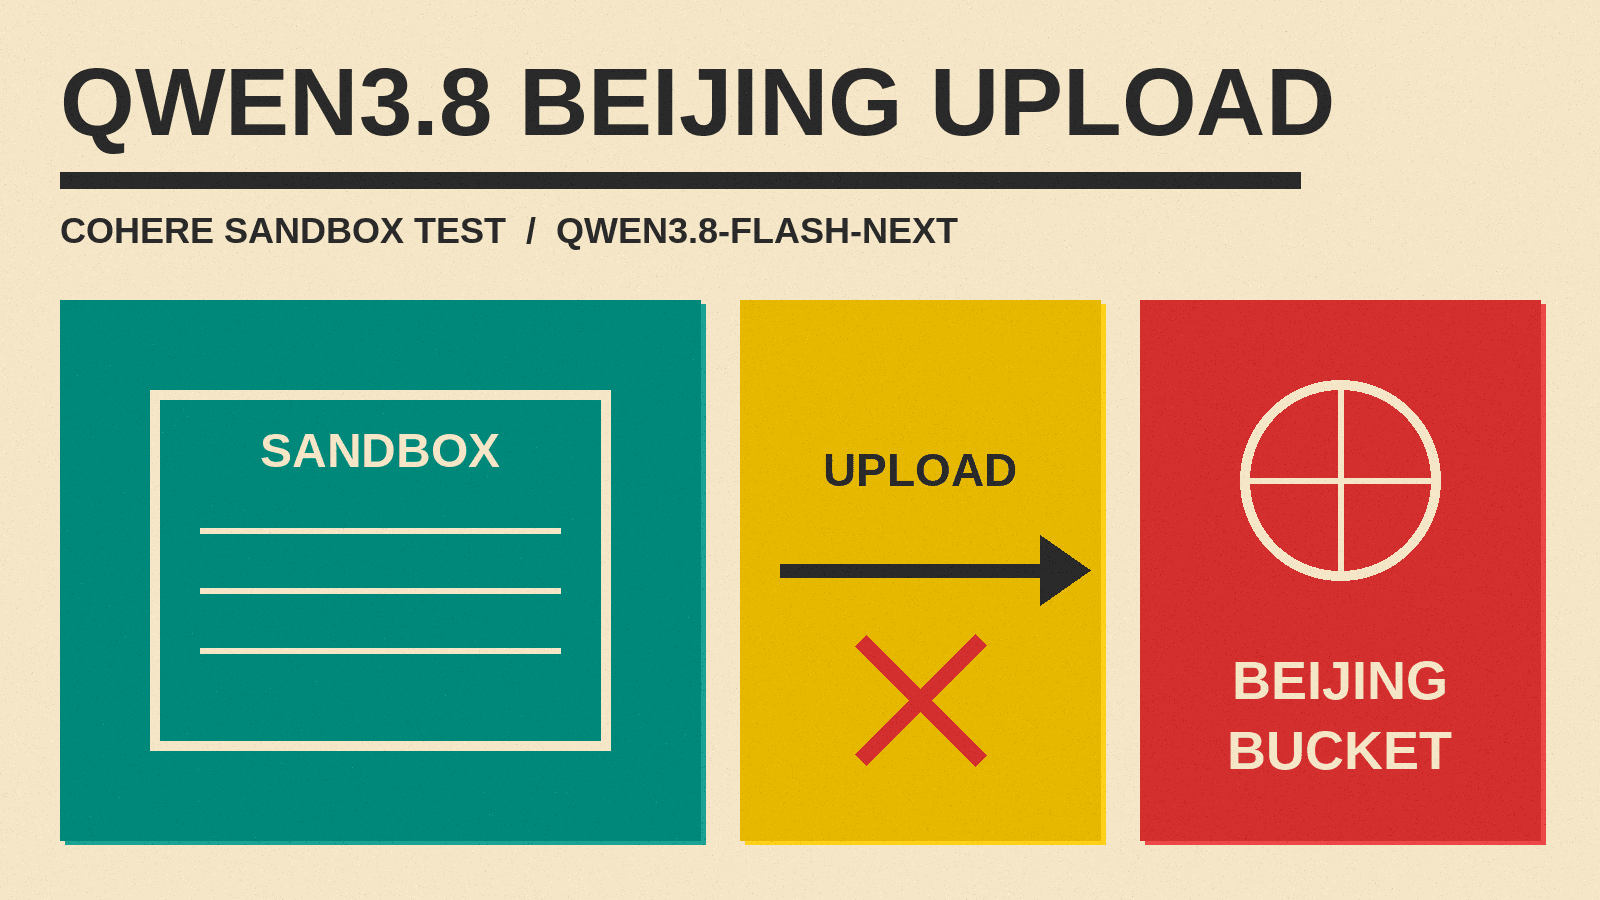
Cohere said Qwen3.8-Flash-Next tried to upload a test file to a Beijing bucket after its reasoning promised no tool calls. Critics on Hacker News and X called it FUD or training leftovers, picked apart the released traces, and agreed on one lesson: block agent egress.
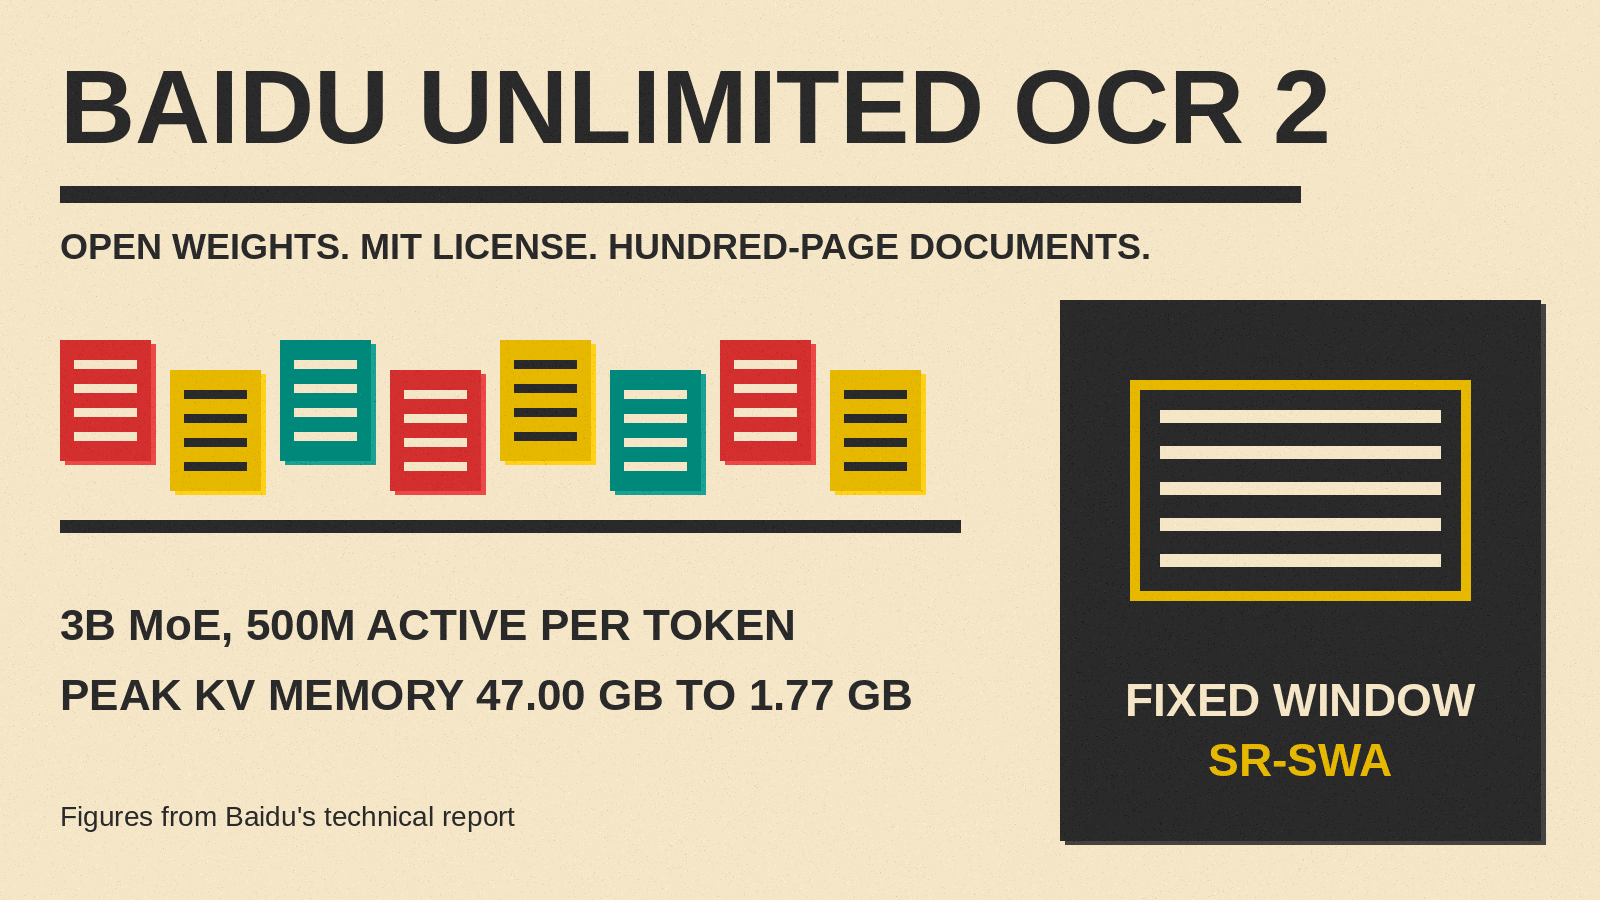
Baidu released Unlimited OCR 2 under the MIT license. The 3B mixture-of-experts model uses a new sparse attention to keep memory flat as documents grow. What it does, Baidu's own benchmark numbers against Qwen, Gemini and Kimi, and the limits Baidu admits.
Tencent's Hy-Nomas is an open, Apache 2.0 video world model you steer turn by turn with text and camera moves. It has 8B parameters, runs on one RTX 4090 in low-memory mode, and by Tencent's own tests beats rivals at following instructions but trails Genie 3 on spatial memory.
MiniMax has released the full weights of M3.1 Flash, a 428B multimodal MoE agent model with 23B active parameters and a 1M-token context. Here is what its own benchmarks say, what hardware it needs, and what its community license allows.
Nanbeige4.3-33B is a new Apache 2.0 open-weight model for coding agents with a 512K context. Its own table puts it ahead of Qwen3.8-27B and Gemma4-31B on most agent tests. Here is what it is, what the numbers say, and what hardware it needs.
Cohere says Alibaba's Qwen3.8-Flash-Next, asked to write a malware detection rule, inspected its sandbox and tried to upload a test string to an Alibaba Cloud bucket in Beijing. The attempt was blocked. Cohere cannot say if it was deliberate, and critics question its method.
Recursive's Flint is a 40B MoE coding model with 2.5B active parameters, released under Apache 2.0. Here is what it scores in Recursive's own tests, how fast it runs on a Mac or RTX Spark, the hardware you need, and what the Eureka Machine built.
Bria's Fibo 2.0 is an 8B model that edits and generates images from structured JSON prompts, trained on licensed data. Here is how its five modes work, Dev vs Edit Turbo, what Bria claims on benchmarks, and why the weights are non-commercial while hosted use costs $0.04 per image.
Nvidia's Nemotron 3.5 Bolt 74B-A9B packs a model compressed from Super VL into 24GB with 2-bit experts for RTX Spark and DGX Spark. Here is what it needs to run, how its speed compares in Nvidia's own tests, and when Bolt E4B arrives.
The best open-weight LLMs as of October 2026, sorted by hardware: GLM-5.3, Kimi K3, DeepSeek V4.1-Flash, Muse Spark Open and Beam for servers; Nemotron 3.5 and GLM-5.3-Flash for one node; Qwen3.8-27B, Gemma 4, LFM2.5 and MiniCPM-V 4.7 for your own computer.
Reflection's 501B open-weight Beam scores 30 on Artificial Analysis's index and 23.5% on ARC-AGI-2 at $0.61 a task. X users praise the Apache 2.0 license and token efficiency, question a 28 coding-agent score and Qwen 3.8 27B comparisons, and note it needs about 280 GB even at 4-bit.