
Reflection AI, a new US lab, put the weights for its first model, Beam 1.0, on Hugging Face on October 16 under Apache 2.0. Three days later people are still testing it. On Monday, October 19, at 10:12 AM PDT, ARC Prize posted Beam's verified ARC-AGI scores, the newest outside test so far. We covered the specs in our news post on Beam. This roundup covers what developers, benchmarkers and skeptics said once they had it.
The short version: people like the license, the token efficiency and how easy it is to try for free. Outside coding-agent scores sit well below Reflection's own model card, several posters say it trails a much smaller Qwen model, and the hardware bill means "open" does not mean "local".
We found no Hacker News thread with real discussion of Beam, so the reactions below come from X.
What Reflection shipped
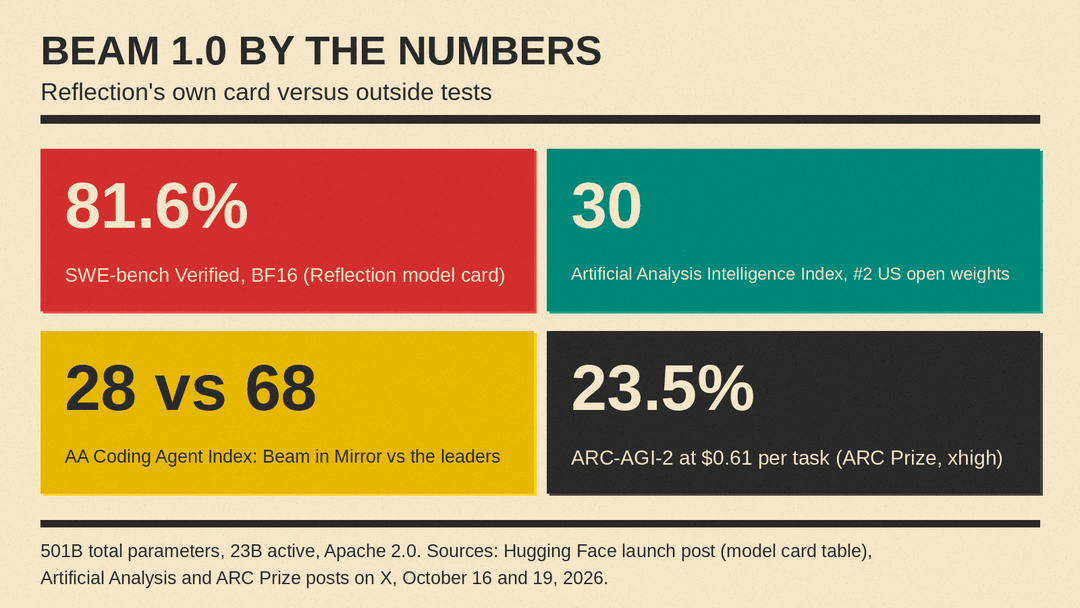
Beam is a sparse Mixture-of-Experts model with 501B total parameters and 23B active per token, according to Reflection's announcement. The Hugging Face launch post lists a 1M-token context window, text input only, BF16, FP8 and NVFP4 checkpoints, five reasoning levels from "low" to "max", and an open source Rust-based harness. Artificial Analysis calls Mirror Reflection's open-source CLI harness. On Reflection's model card numbers, quoted in the Hugging Face post, the BF16 checkpoint scores 81.6% on SWE-bench Verified and 80.1% on Terminal Bench v2.1.
Hardware is the catch. Hugging Face writes that NVFP4 shrinks the weights "from 1 TB to ~280 GB" and tells readers: "Plan for four B200s (720 GB)". Older GPUs such as the H200 need the FP8 checkpoint.
The benchmarks people ran
Artificial Analysis posted its results at 6:31 AM PDT on launch day: "Reflection’s first model, Beam, scores 30 on the Artificial Analysis Intelligence Index, placing it #2 among US open weights models". In the same thread it wrote that Beam, running in Mirror, scores 28 on its Coding Agent Index, "15 points behind the next setup, Claude Code with Qwen3.8 Max (43), and 40 behind the leaders (68)." It also found that Beam stands out on AutomationBench-AA (48.5%) and CritPt (13.1%), and that its weakest results were Terminal-Bench 4.0 at 3.0% and AA-Briefcase at 976 Elo. Note that this Terminal-Bench 4.0 result is a different test version from the v2.1 score on Reflection's card. On cybersecurity, Artificial Analysis said Beam scores 34% on its Cyber Index, "the leading US open weights model that we’ve tested".
Arena wrote on October 17 that "Reflection debuts with Beam 1.0, the #1 US open model on Agent Arena overall."
Today's ARC Prize results put Beam at 23.5% on ARC-AGI-2 at $0.61 per task and 74.0% on ARC-AGI-1 at $0.31 per task. Its best scores came at the "xhigh" reasoning level, but ARC Prize noted that "high" was close on ARC-AGI-2, "20.0% versus 23.5%, at about 43% lower cost." The cost figures use Baseten pricing of $1.30 input and $4.30 output per 1M tokens, and ARC-AGI-3 results are pending.
On speed, @SJRonanMD measured the NVFP4 checkpoint on two DGX Station GB300 machines linked over one 400G link, with the DFlash2 drafter and 8K-token prompts. Their decode speeds were 237.8 tokens per second for 1 user, 587.6 for 4 users and 1,306.8 for 16 users.
Praise: the license, the efficiency and free trials
The Apache 2.0 license got the warmest response. @the_rza_ wrote: "I'd rather run a coding model I'm allowed to fork under Apache 2.0 than build on an API that can change its terms on a Tuesday." @ChakibBouabd said "Apache 2.0 is the bigger deal here, since providers can serve it without license gates." That matters because the other big US open-weight release that week, Meta's Muse Spark Open, ships under Meta's own license.
Token efficiency was the second theme. Artificial Analysis said only 26% of Beam's output goes to final answers, from about 26k output tokens per Intelligence Index task. Several replies treated cost per task as the point. @madmenai wrote: "Open MoEs with thin active params are how agent fleets stop renting every token from one API." @kiedrademi called the "43% cost savings for just a 3.5-point drop on ARC-AGI-2" interesting.
Free access helped people try it. @ElainaNotes flagged that OpenCode made Beam "Free for a limited time". @PerchTerminal posted that Beam is free on its Starter plan until October 23. On Vercel's AI Gateway, @TensorTiffin warned that the "-free slug just stops when the offer ends. Plain reflection/beam quietly rolls over to paid pricing."
@Casper_a10 singled out the harness: "The real gift is Mirror, the harness they trained it in. Weights without the harness is half a model."
Doubts: outside coding scores and a smaller rival
The gap between Reflection's numbers and outside tests drew the most comment. @corbintips wrote on launch day: "Honest take: 81.6% SWE-bench Verified is their own number. Anyone tested it?" @neuralloot pointed to the Coding Agent Index result, "Beam at 28 vs frontier around 68", and said "the agent-coding card still needs an outside harness before we trust it."
The split between the Artificial Analysis results drew questions too. @ItsCuthulhu asked: "48.5% on AutomationBench but only 3.0% on Terminal-Bench is a huge split. What breaks for Beam in the terminal, is it tool use or the longer runs?" @LiuweijiaVip put it more bluntly: "So it clicks buttons but can't read a terminal."
Many replies compared it to Alibaba's much smaller Qwen 3.8 27B, which we cover in our Qwen3.8 explainer. @bleakjustin replied to Artificial Analysis: "It's lower scoring than Qwen 3.8 27b, hot dang." @giffboake wrote: "500B can't even keep up with Qwen 27b. And Qwen 4 probably drops in a week or two." @TroyDoesAI went further and suggested a Qwen model was kept off a chart on purpose: "they didn't want another Q in their chart".
Others saw the scores as a fair measure of where US open models stand. @candnz_lrn wrote "30 vs 56 for muse wonder full. open weights still have a gap to close". @Umargik said "Trailing the leaders by 40 points is the real state of American open weights right now". @arrd_el argued that "the 47% hallucination rate on AA-Omniscience is the more important number". Artificial Analysis's launch thread does report a 47% hallucination rate for Beam on AA-Omniscience.
Complaints: hardware and hands-on misses
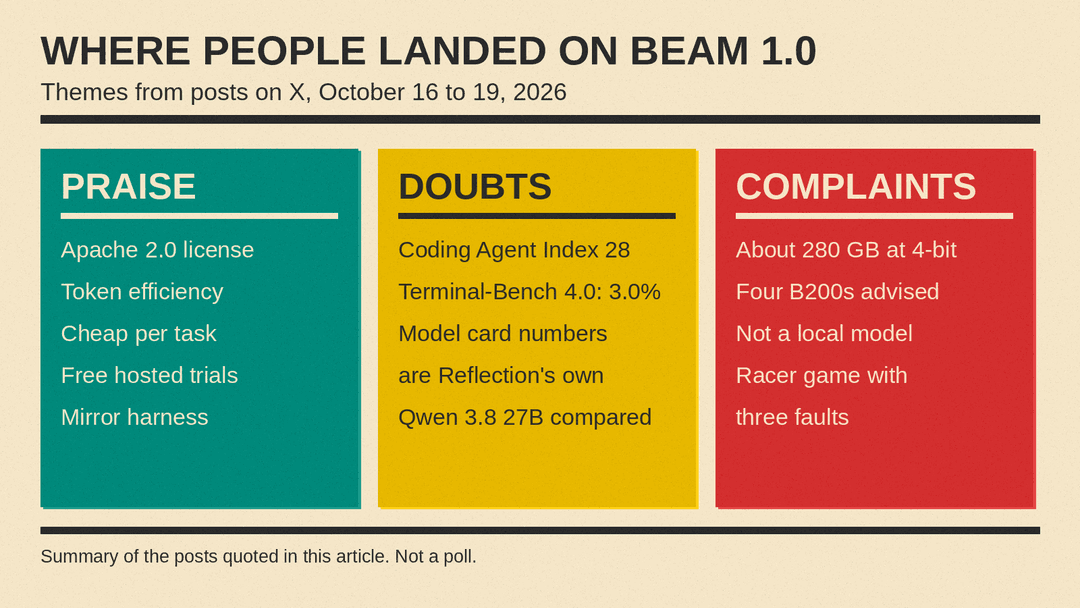
"Open is not local" came up again and again. @ChakibBouabd wrote: "Here's the catch: open is not local. The 4-bit checkpoint is ~280GB, and Hugging Face says plan for four B200s." @Casper_a10 added: "Also BF16 is ~1TB. 'Run it locally' lol, sure, if your local is a rack."
Hands-on reports were mixed. @thecynxio said Beam "built me a Mario Kart-style racer in under four minutes, and its README said everything works. Then I played it." They went on: "Claude, the paid one, tested its own game first. One note fixed Beam's three faults in 66 seconds, for free." @kierishere posted "Beam 1.0:" followed by a shell command, find / -name AGENTS.md 2>/dev/null | head, which searches the whole filesystem for AGENTS.md files, and an unamused emoji. @JamesMalsawm summed up what many replies wanted: "would love to see how it does on real coding tasks, not just the index."
What to take from it
Three days in, Beam's strongest case is the license and the cost per task, not raw ability. Independent tests rank it near the top of US open-weight models, but well behind the closed leaders on coding-agent work, and several posters say a much smaller Qwen model scores higher. The ARC Prize numbers show the "high" reasoning setting gives most of the score for much less money. If you want to try it, the free hosted offers are the cheap way in. Check which model name you pick on Vercel, and do not plan on running it on one consumer GPU. For how earlier open releases held up after launch week, see our roundup on DeepSeek V4.1-Flash-1017.
Sources
- Reflection: Introducing Beam
- Hugging Face: Welcome Beam
- Beam-1.0-501B-A23B on Hugging Face
- Artificial Analysis on X (Intelligence Index)
- Artificial Analysis on X (Coding Agent Index)
- Artificial Analysis on X (per-evaluation results)
- Artificial Analysis on X (output tokens)
- Artificial Analysis on X (Cyber Index)
- Arena on X
- ARC Prize on X (ARC-AGI results)
- ARC Prize on X (pricing used)
- @SJRonanMD on X (DGX Station speeds)
- @the_rza_ on X
- @ChakibBouabd on X (license)
- @ChakibBouabd on X (hardware)
- @Casper_a10 on X
- @madmenai on X
- @kiedrademi on X
- @ElainaNotes on X
- @PerchTerminal on X
- @TensorTiffin on X
- @corbintips on X
- @neuralloot on X
- @ItsCuthulhu on X
- @LiuweijiaVip on X
- @bleakjustin on X
- @giffboake on X
- @TroyDoesAI on X
- @candnz_lrn on X
- @Umargik on X
- @arrd_el on X
- @thecynxio on X
- @kierishere on X
- @JamesMalsawm on X
