Deletion Tuning: Zeroing 0.05% of Weights Matches Fine-Tuning
A new NYU and Calgary paper fine-tunes LLMs by only zeroing under 0.05% of weights. It matches full fine-tuning from 7B to 30B and forgets less.
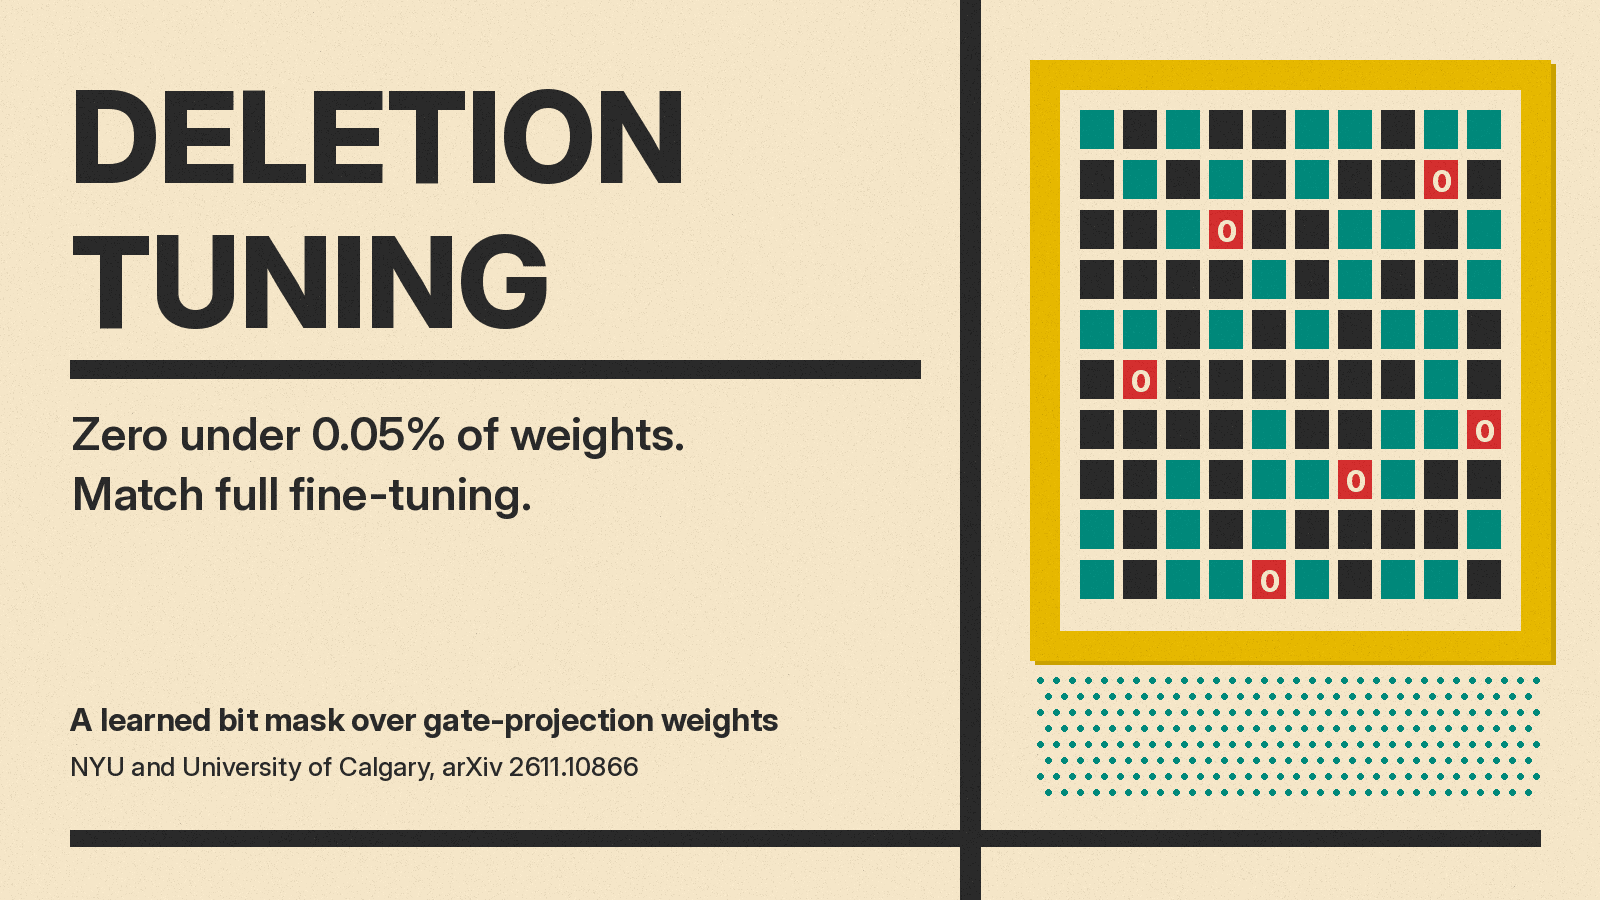
A new NYU and Calgary paper fine-tunes LLMs by only zeroing under 0.05% of weights. It matches full fine-tuning from 7B to 30B and forgets less.
A committee led by David Gross released OpenAI's Lean code and says it proves pure Yang-Mills existence. It does not prove a mass gap. What it means.
Baidu opened ERNIE 5.5 Flash Preview on Qianfan: 280B parameters, 14B active, 1M-token context. Apache 2.0 weights are due by Nov 25.
What Claude Fable 5.2, Opus 5.5, Sonnet 5.5 and Haiku 5.5 are for, what each costs, which plans include them, and when Anthropic says to move up.
Claude Fable 5.2, Gemini 4 Carbon and GPT-6 Astra compared on API price, context limits, app access and one shared benchmark table from Anthropic.
Most AI benchmarks give no credit for "I don't know" and full credit for a lucky guess, an OpenAI paper argues. My view: fix the scoring and check error rates.
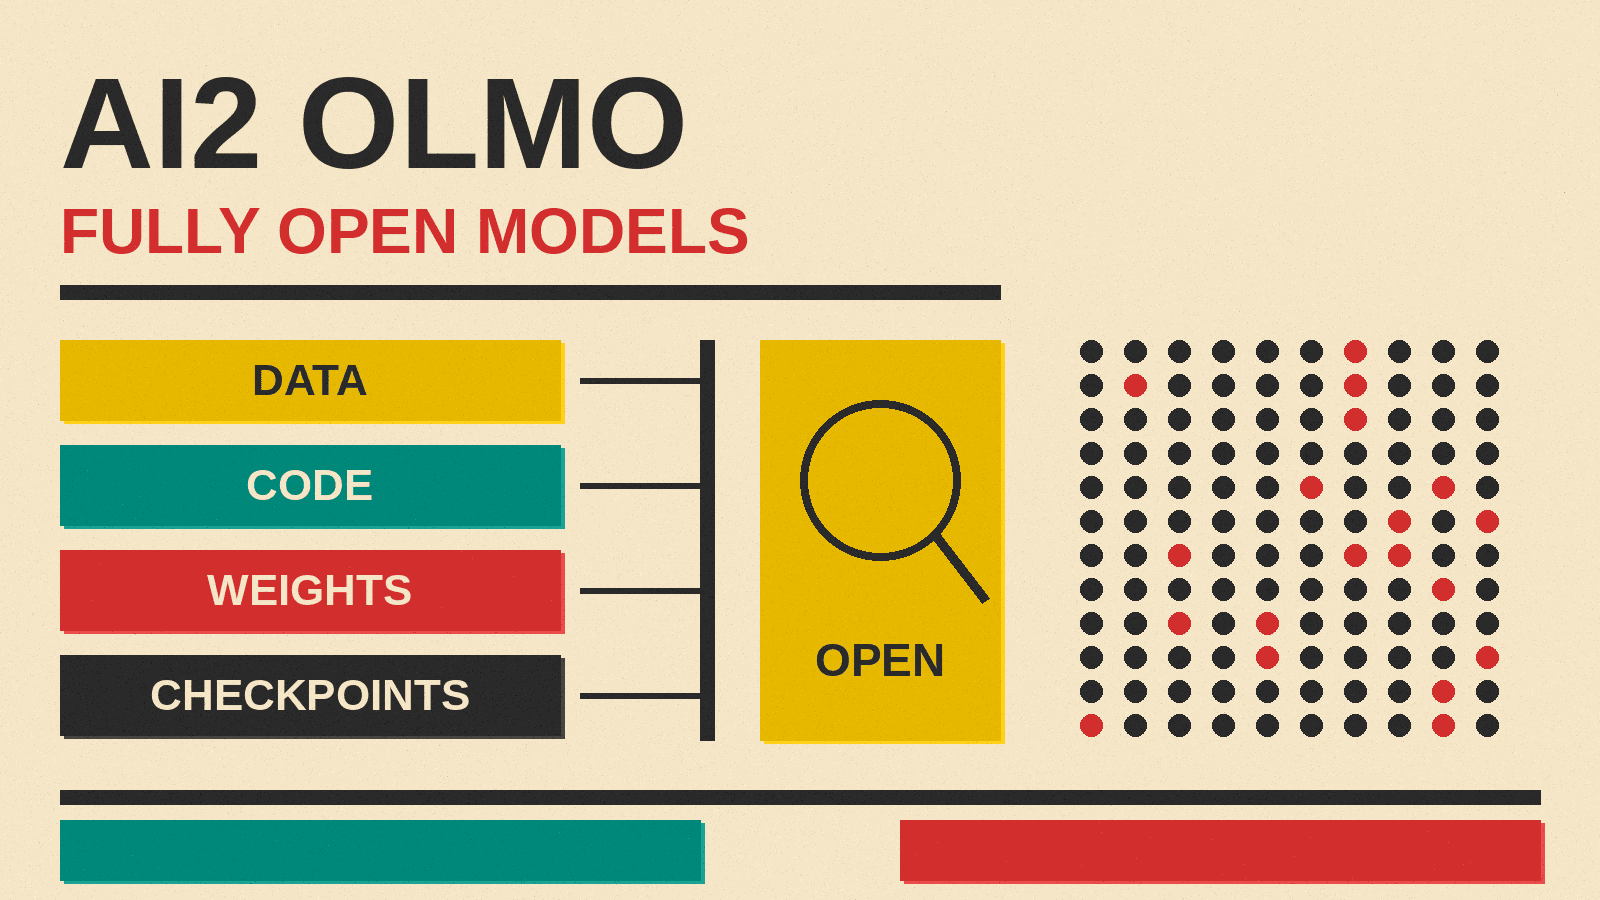
Olmo is Ai2's family of fully open AI models: weights, training data, code and checkpoints are public. Here are the models, the licenses, and who should use it.
Tencent Hy, formerly Hunyuan, is Tencent's AI model family. Here is how Hy3 and Hy4 fit together, what you can download, and where Hy runs.
Instruction tuning trains a base model on request and answer pairs so it follows directions. What FLAN, InstructGPT, Self-Instruct and LIMA found.
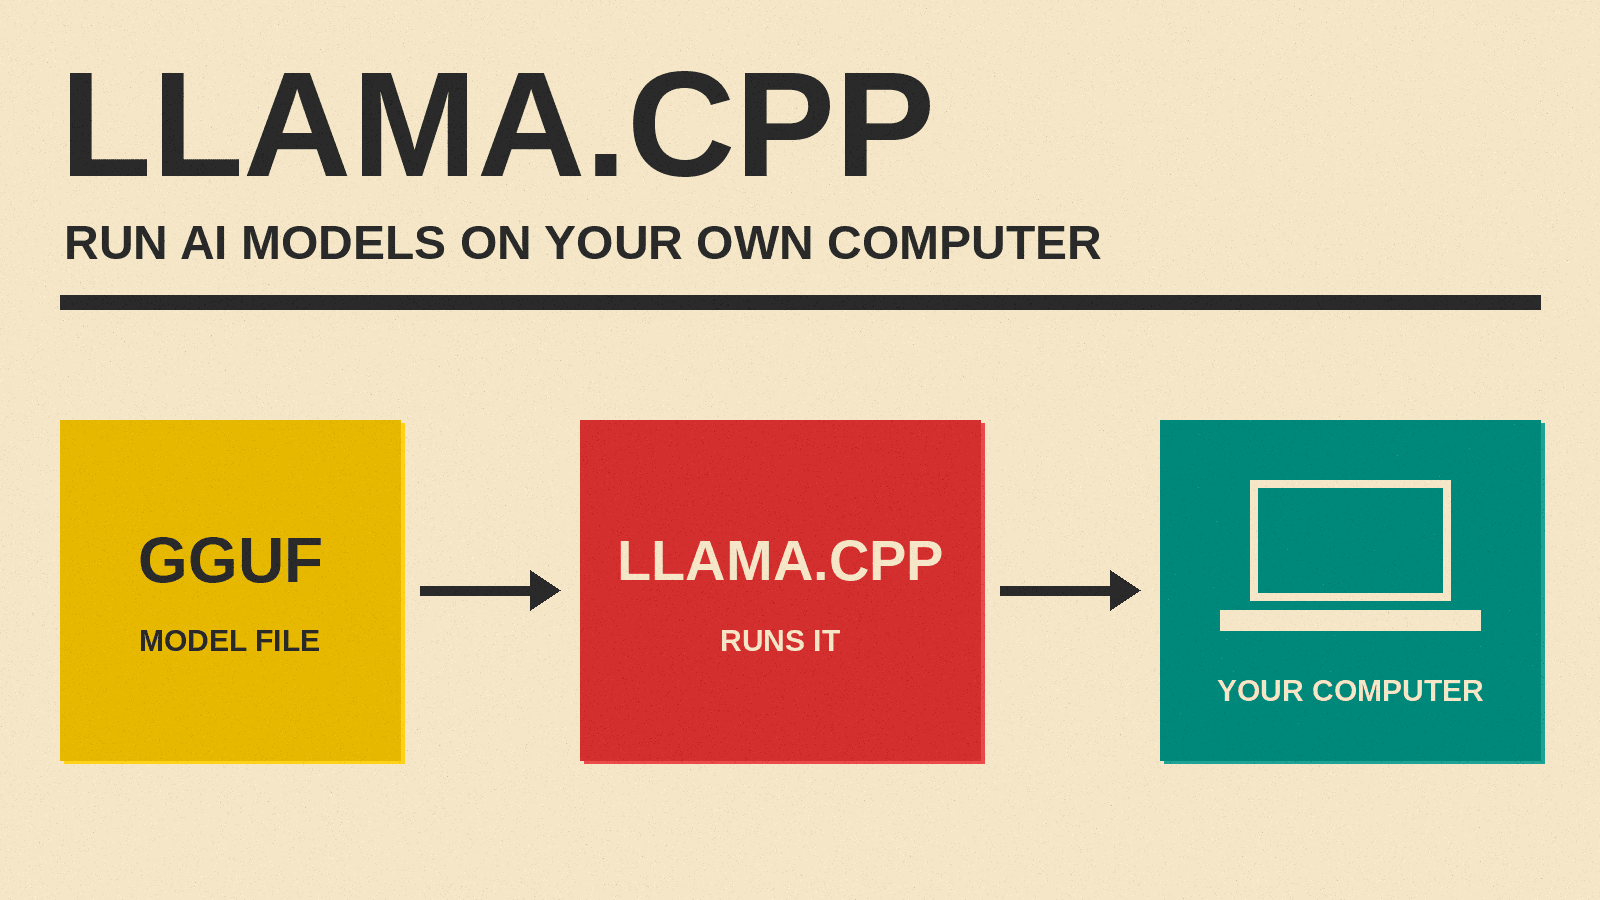
llama.cpp is a free, open source program that runs AI language models on your own computer. Learn what it does, GGUF files, quantization, and how to try it.
iFLYTEK, a Chinese speech AI firm founded in 1999, makes the Spark (Xinghuo) models, including small open-weight X2.6 and X2.5 models under Apache 2.0.
A 2023 NeurIPS award paper found many sudden AI skill jumps fade under partial-credit scoring. My view: ask how a jump was scored before calling it new.
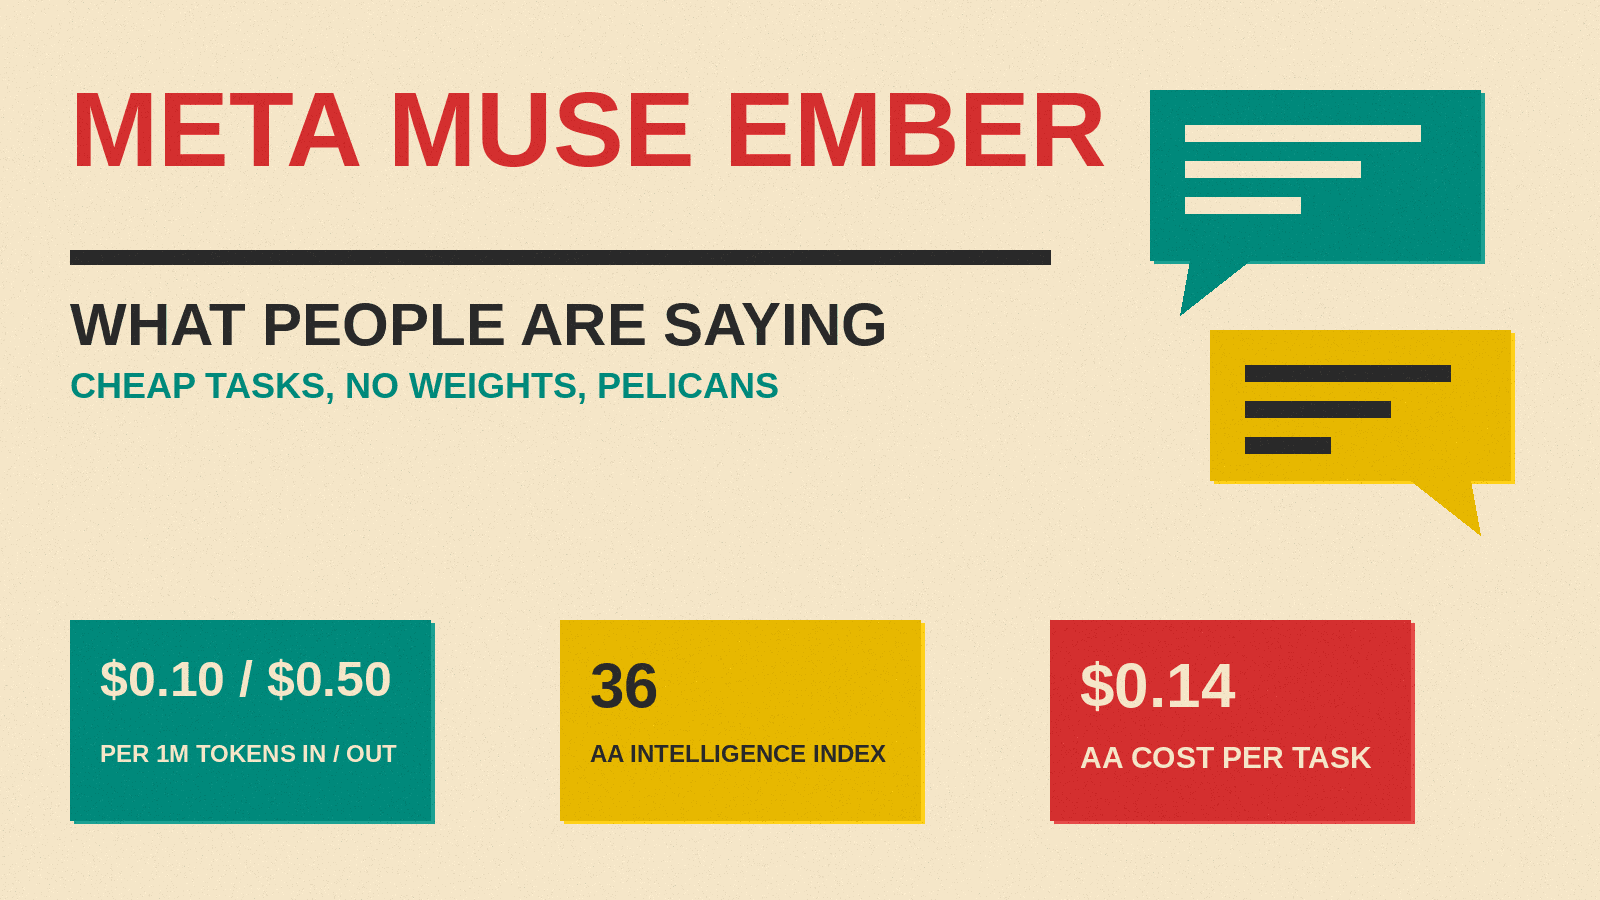
Early reactions to Meta Muse Ember on X and Hacker News: cost-per-task praise, speed reports, a coding gap versus Haiku 5.5 and calls for open weights.
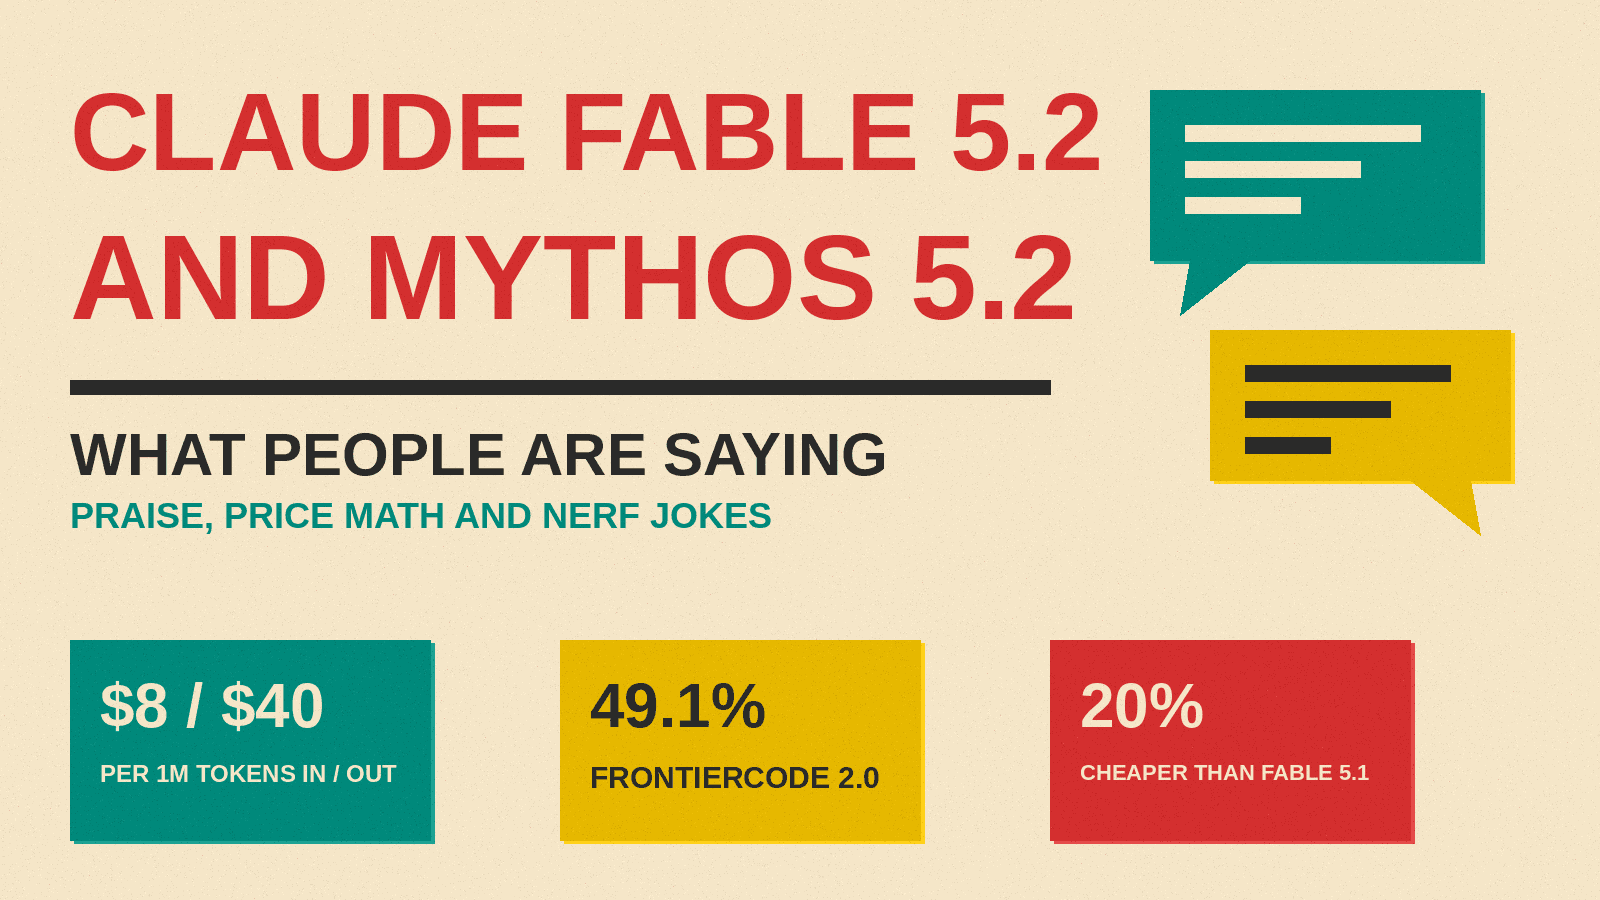
Claude Fable 5.2 and Mythos 5.2 launched with a 20% price cut. Testers, partners and Hacker News weigh in on long agent runs, cost per task and nerf fears.
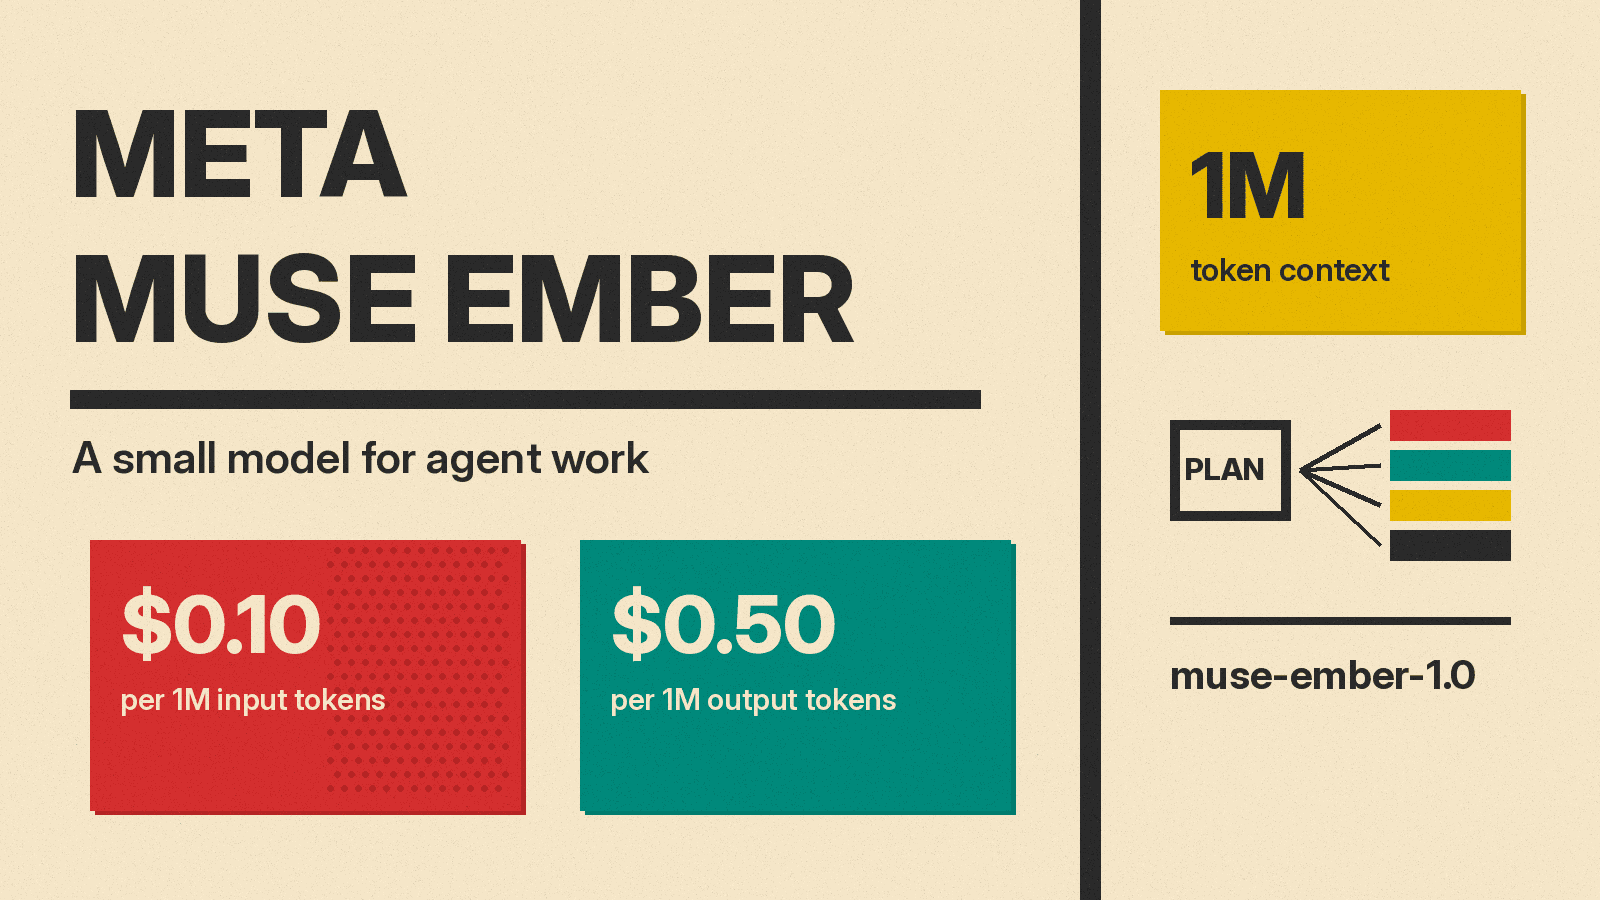
Meta's Muse Ember costs $0.10 per million input tokens and targets agent tool calls and subtasks. Prices, Meta's benchmark claims and partner notes.
Function calling lets an AI model ask your app to run a tool, like a weather lookup. How the five-step loop works, what a tool looks like, and the risks.
Baidu says its ERNIE Evolve agents found inference speedups for the in-development ERNIE-5.5-Flash, including 623.6% of baseline on Kunlunxin P800.
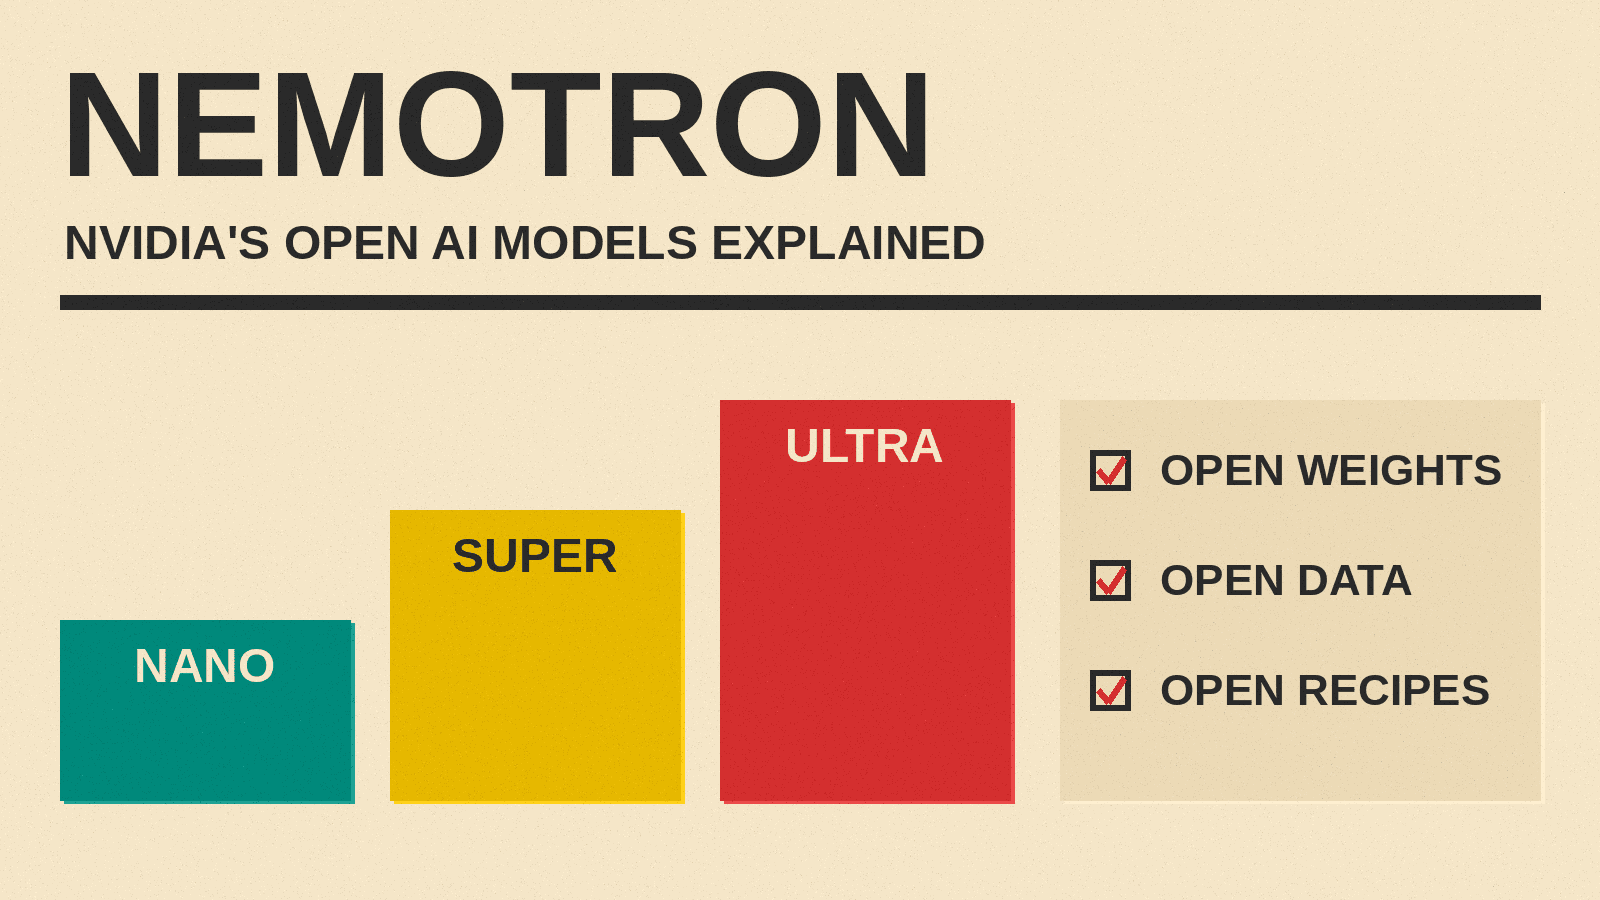
Nemotron is NVIDIA's family of open models for AI agents. See the Nano, Super and Ultra tiers, the open training data NVIDIA shares, and the license terms.
Preferred Networks released PLaMo 3.0 Fin, an 8B Japanese finance model with reasoning and tool calls, as open weights under the PLaMo Community License.
Nous Research fine-tuned Qwen3.8-27B into Arete-27B. On its own test, answers with propaganda fell from 22% to 0.9%, with no meaningful loss on skill tests.