
Anthropic released Claude Fable 5.2 and Claude Mythos 5.2 late Monday morning, November 9, 2026, with a 20% API price cut and a long list of benchmark wins over Claude Opus 5.5. In the first hour, Anthropic staff and launch partners praised its work on long, open-ended projects, independent testers said it is better but not better at everything, and Hacker News split over price, naming and whether Opus 5.5 had been quietly weakened before the launch. These are first-hour reactions, so treat every early test below as provisional.
What did Anthropic release?
Fable and Mythos are the same underlying model. Fable ships with strong cybersecurity and biology safeguards, which lets Anthropic offer it to all users. Mythos is the same model without certain of those safeguards and goes only to organizations approved through Anthropic's Cyber and Life Sciences Verification Programs.
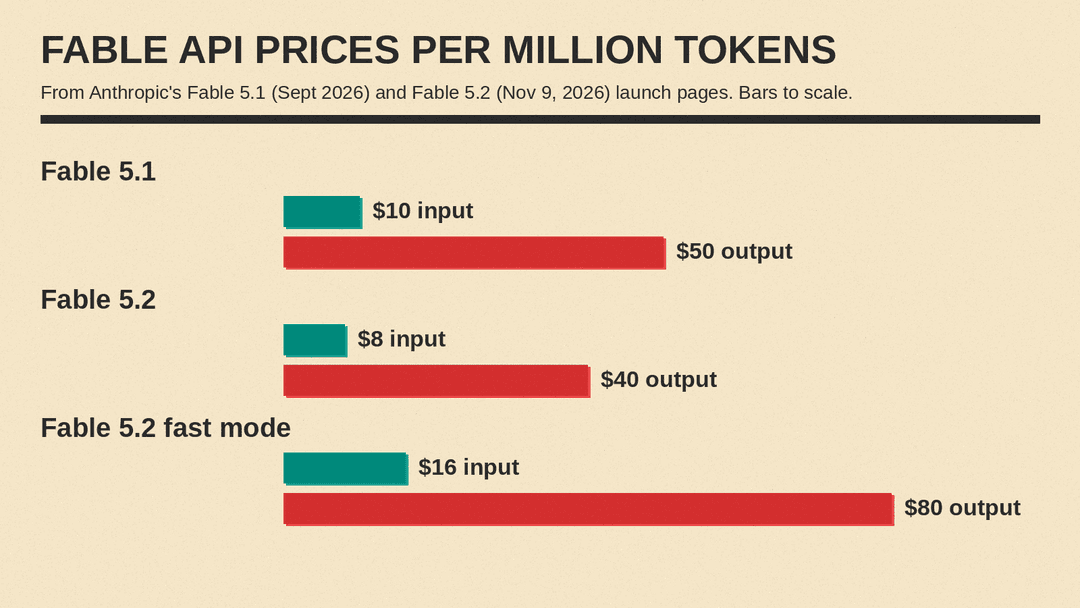
Anthropic says both models generate output up to 30% faster than Fable 5.1 and Mythos 5.1. The API price is $8 per million input tokens and $40 per million output tokens, down from $10 and $50 for Fable 5.1. An optional fast mode, up to 2.5 times faster, costs $16 and $80.
For the full price list, benchmark table, safety results and launch offers, see our news post on Claude Fable 5.2 and Mythos 5.2 price, scores and access.
Anthropic still tells most people to start with Claude Opus 5.5, which it calls "our strongest daily driver", and to move up to Fable or Mythos as the work requires; it says those models are best for the most ambitious, open-ended technical work. Its showcase claims are large: two open problems in black hole physics solved, a team of about 1,000 Fable 5.2 agents formalizing the proof of Fermat's Last Theorem in 30 hours, and a prototype operating system built by over 1,000 subagents over eight days.
The launch was not a total surprise. About three minutes before the Hacker News submission, @kimmonismus posted that the AWS Bedrock price list already showed both models at 20% below their 5.1 prices.
What early testers praised
Wharton professor @emollick (Ethan Mollick), who had early access, wrote: "I think it crosses the line into being a sort of Jagged AGI." In his longer post, Mollick had it turn a small USB keyboard into a game console with six games, plan a business, write a 182-page research paper, and build over 450 3D worlds with teams of agents. Mollick says he takes no money from AI labs.
Anthropic's own people were the warmest. @alexalbert__ (Alex Albert, Anthropic research) wrote: "On big, open-ended work it feels like a major step above Opus 5.5." Albert's advice: "Start on med/high effort, and save xhigh for hardest problems" and "Give it a whole project instead of a next step and let it run for hours." Effort is the setting Anthropic's docs describe as the control for thinking depth, latency and cost. @mikeyk (Mike Krieger, Anthropic Labs) called Fable "a great thought partner on strategy, paired with Opus 5.5 for a lot of my work."
@IndependentEco posted: "Fable 5.2 is faster than Opus 5.5 so far in my testing."
What the benchmarks people posted show
Anthropic's table has Fable 5.2 at 49.1% on FrontierCode 2.0 at xhigh effort, against 45.5% for Opus 5.5, 42.8% for GPT-6 Astra and 32.4% for Fable 5.1. Its Remote Labor Index score of 41.3% (at High effort) is about double Opus 5.5 (21.3%) and GPT-6 Astra (20.8%). One line in the same table cuts the other way: on AutomationBench, Gemini 4 Carbon scores 53.9%, above Fable 5.2's 51.4%.
Launch partners posted their own numbers. These are the companies' own numbers, not independent tests, and each company offers Fable 5.2 in its own product.
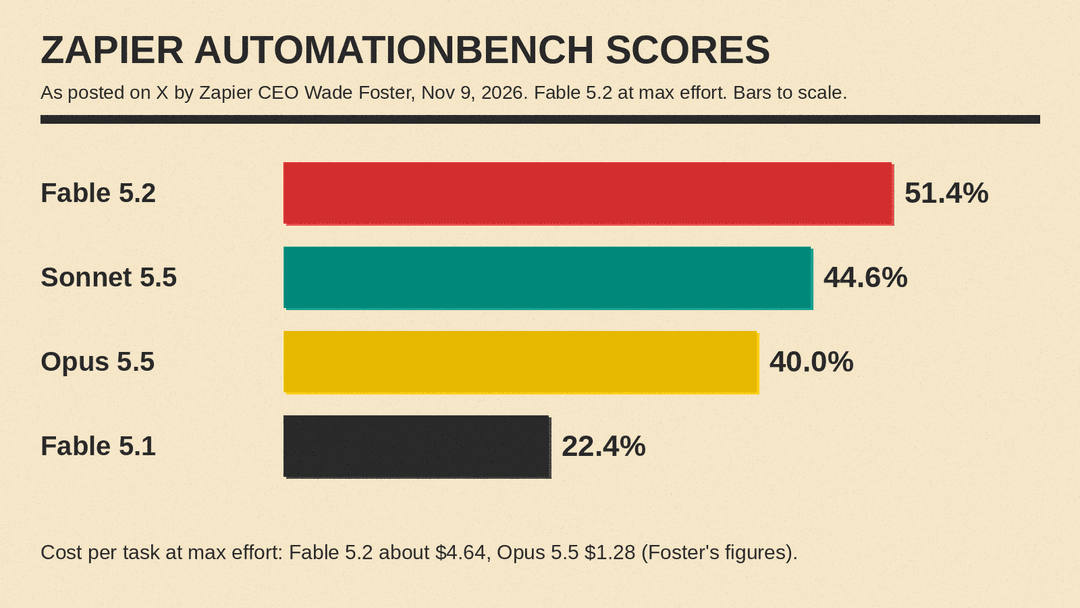
- @wadefoster (Wade Foster, Zapier CEO) posted Zapier's AutomationBench runs: Fable 5.2 at 51.4% at max effort, Sonnet 5.5 at 44.6%, Opus 5.5 at 40.0% and Fable 5.1 at 22.4%. Anthropic's own table lists Opus 5.5 at 42.5% on the same benchmark.
- @cognition, the maker of Devin, wrote: "On FrontierCode 2.0, Fable 5.2 takes the #1 spot at a score of 49.1." It added that at low effort, Fable 5.2 beats Fable 5.1's score "at a third of the cost."
- @tryshortcutai, an AI agent for Excel, reported 91% on its financial modeling benchmarks at high effort, up from 86% for Fable 5.1.
On Hacker News (253 points and 76 comments as of 11:32 AM PT), iamdelirium questioned FrontierCode, saying Gemini is "the only model forced to use Devin CLI while other models get to use their preferred harness." The comment does not cite a source for that. horseloverthin wrote: "Assuming no implicit phacking a 15 point jump on tbench scientific is a big deal." (Anthropic lists Terminal-Bench-Science at 74.6% for Fable 5.2 and 58.7% for Opus 5.5.) bananaflag said of the physics work: "Those theoretical physics papers look like the real thing (i.e. not mathematical physics like the OpenAI Yang-Mills result)."
Is Fable 5.2 worth the cost?
Per token, it is cheaper. Per task, it can cost more, because it works longer.
Foster's Zapier numbers show the trade. Fable 5.2 averaged about 97 tool calls per task against 54 for Fable 5.1. "You do pay for that extra thoroughness," Foster wrote. At max effort a task cost about $4.64 on Fable 5.2 and $1.28 on Opus 5.5. At low effort, Fable 5.2 scored 39.7%, about the same as Opus 5.5 at max effort, for $1.30 per task. Foster's advice: "So figure out which workflows need Fable 5.2, and run the rest on Opus 5.5 ($1.28 per task) or Sonnet 5.5 ($1.00 per task)".
@petergostev (Peter Gostev of Arena) ran dozens of prompts for a video review, including "one that cost $2,618", and concluded: "It's a great model, a LOT of things got better but not every single thing, it does make sense to use Opus still."
On Hacker News, iammrpayments wrote "Too expensive for me". ttul replied: "Really? A $200/mo plan gives you an enormous amount of inference on this model."
What are Fable resets?
Subscribers got a launch promotion. Per Claude's help center, Max, Ultra and premium Team seats get one to three "Fable limit resets" based on how long they have paid (under six months one, six to 12 months two, more than 12 months three), usable until March 8, 2027. Pro and standard Team seats get Fable included for one week, through November 16, for up to 50% of weekly usage, plus one reset.
@bcherny (Boris Cherny, who works on Claude at Anthropic) drew the most likes of the posts in this roundup, 744 with 108 replies as of 11:30 AM PT: "We wanted to do more for the people who’ve been with us the longest. So with Fable 5.2, the longer you’ve been subscribed, the more Fable resets you get."
minimaxir called the reset terms "unusually generous". guybedo read them as resets of the Fable limit, not extra tokens, and johnwards quoted the app: "Resets your Fable limit, and takes this week’s Fable use off your weekly limit." The help page agrees: "A reset doesn’t raise your limits. It restores usage so you can keep working within your existing limits."
The nerf question
"Nerfed" is gamer slang for a quiet downgrade. Late on November 8 (PT), a separate Hacker News thread asked "Is Opus 5.5 nerfed?", which we covered this morning. The launch revived it.
skeledrew wrote: "Damn people were right about 5.5 being nerfed in preparation for a version release. This is not at all a good look." The comment links that thread but gives no evidence that the two are connected. shmoil asked whether Anthropic's comparison came "before you lobotomized Opus 5.5 or after?" minimaxir checked the original Opus 5.5 launch post and found most benchmarks no longer line up because the benchmarks changed, adding: "The Humanity's Last Exam result matches the initial announcement, though."
On X, the jokes started within minutes. @rafalwilinski posted about 16 minutes after Anthropic's launch post on X: "ngl Fable 5.2 feels nerfed compared to 15min ago". @flopsy42: "Fable 5.2 is out, use it well. It will be nerfed in 1 week."
Complaints and doubts
The name confused people. minimaxir noted "leaks" saying it would be called Fable 5.5 and called Fable 5.2 being better than Opus 5.5 "confusing", and ealready_value wrote: "Very interesting that they set the flagship's version number to 5.2, but their penultimate model is 5.5."
@theo (Theo of t3.gg) tried it in the Claude Code desktop app and wrote: "It's improved a lot, but holy SHIT the ux and navigation is horrible." The post continues: "Took me like 2 minutes just to add a project, even though I had the path on my clipboard?" It had 239 likes and 43 replies as of 11:32 AM PT.
Writing style came up again. __natty__ wrote: "I found Claude's writing style terrible compared to GPT or Gemini." aurareturn answered that "Opus 5 and Fable 5 were unbearable in their writing style" but "Opus 5.5 is a massive improvement." Anthropic says testers found 5.2 communicates more clearly than past Fable models.
Mollick also listed the limits. The agents in his 3D-worlds project wrote themselves a rule book that grew to "204 sections and 87,500 words" and slowed the work down. His main caveat: "Knowing when your own work is not good enough is a large part of what makes someone an expert, and it is the part Fable does least reliably."
What to watch next
Watch three things: independent benchmark runs that are not from launch partners, cost per task in real agent workflows (in Zapier's runs, a max-effort task cost about 3.6 times as much as on Opus 5.5), and whether the "nerfed" complaints follow Fable 5.2 the way they followed Opus 5.5. Mythos 5.2 reactions will be slower, since only vetted organizations can use it.
Sources
- Anthropic: Introducing Claude Fable 5.2 and Claude Mythos 5.2
- Anthropic: Claude Fable and Mythos 5.1 (pricing)
- Claude help center: Fable 5.2 launch offers
- Ethan Mollick: Fable 5.2 and Jagged AGI
- Peter Gostev video review
- X posts: @emollick, @alexalbert__, @mikeyk, @bcherny, @wadefoster, @cognition, @tryshortcutai, @petergostev, @theo, @kimmonismus, @IndependentEco, @rafalwilinski, @flopsy42
- Hacker News: Claude Fable 5.2 and Mythos 5.2
- Hacker News: Is Opus 5.5 nerfed?
- Hacker News comments: iamdelirium, horseloverthin, bananaflag, iammrpayments, ttul, guybedo, johnwards, skeledrew, shmoil, minimaxir on benchmarks, minimaxir on naming, ealready_value, __natty__, aurareturn
- llms.blog: Is Claude Opus 5.5 nerfed? What people are saying
- llms.blog: Claude Fable 5.2 and Mythos 5.2: Price, Scores, Access
