Ant Ling-3.2-flash: 560B Multimodal Model, Free for 2 Weeks
Ant Group launched Ling-3.2-flash on Nov 5, 2026: 560B total, 25B active, 1M context, image and video input, free for two weeks, no open weights yet.
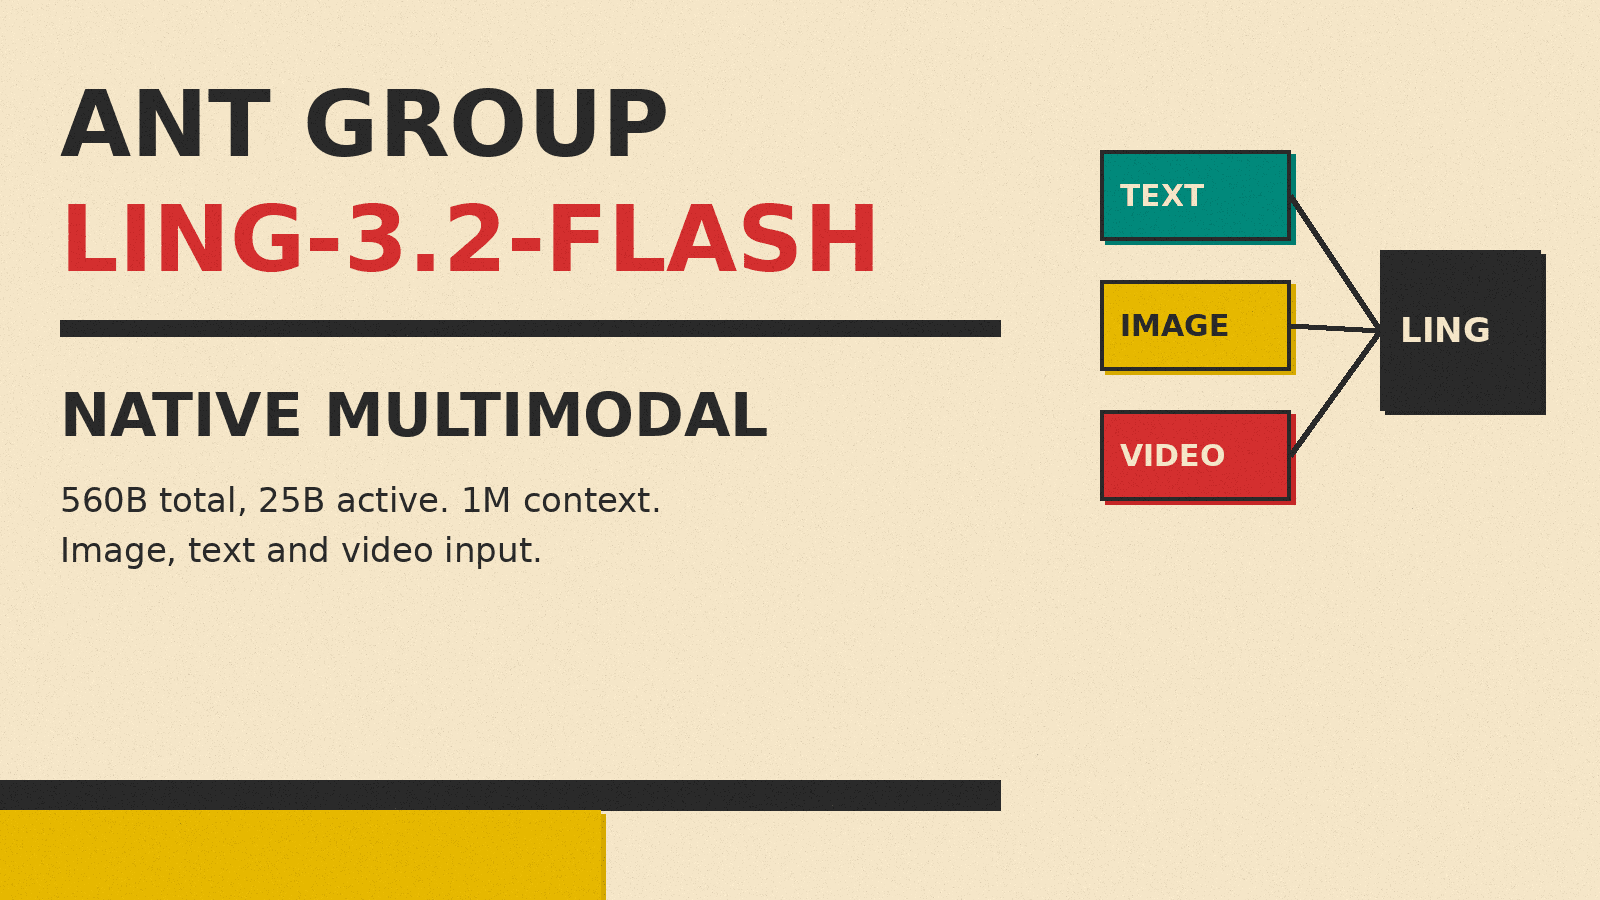
Ant Group launched Ling-3.2-flash on Nov 5, 2026: 560B total, 25B active, 1M context, image and video input, free for two weeks, no open weights yet.
A 2023 paper found AI judges can match human raters, and also that they flip verdicts when answer order changes and can be fooled by length. My view: treat an AI judge as a rater with habits, and check them.
Anthropic's post separates workflows from agents and advises finding the simplest solution possible. My view: make a fixed workflow the default for any task whose steps you can write down in advance.
What temperature, top-p and top-k do when an AI model picks each word, how OpenAI, Anthropic, Google and Ollama handle them, and what to change instead.
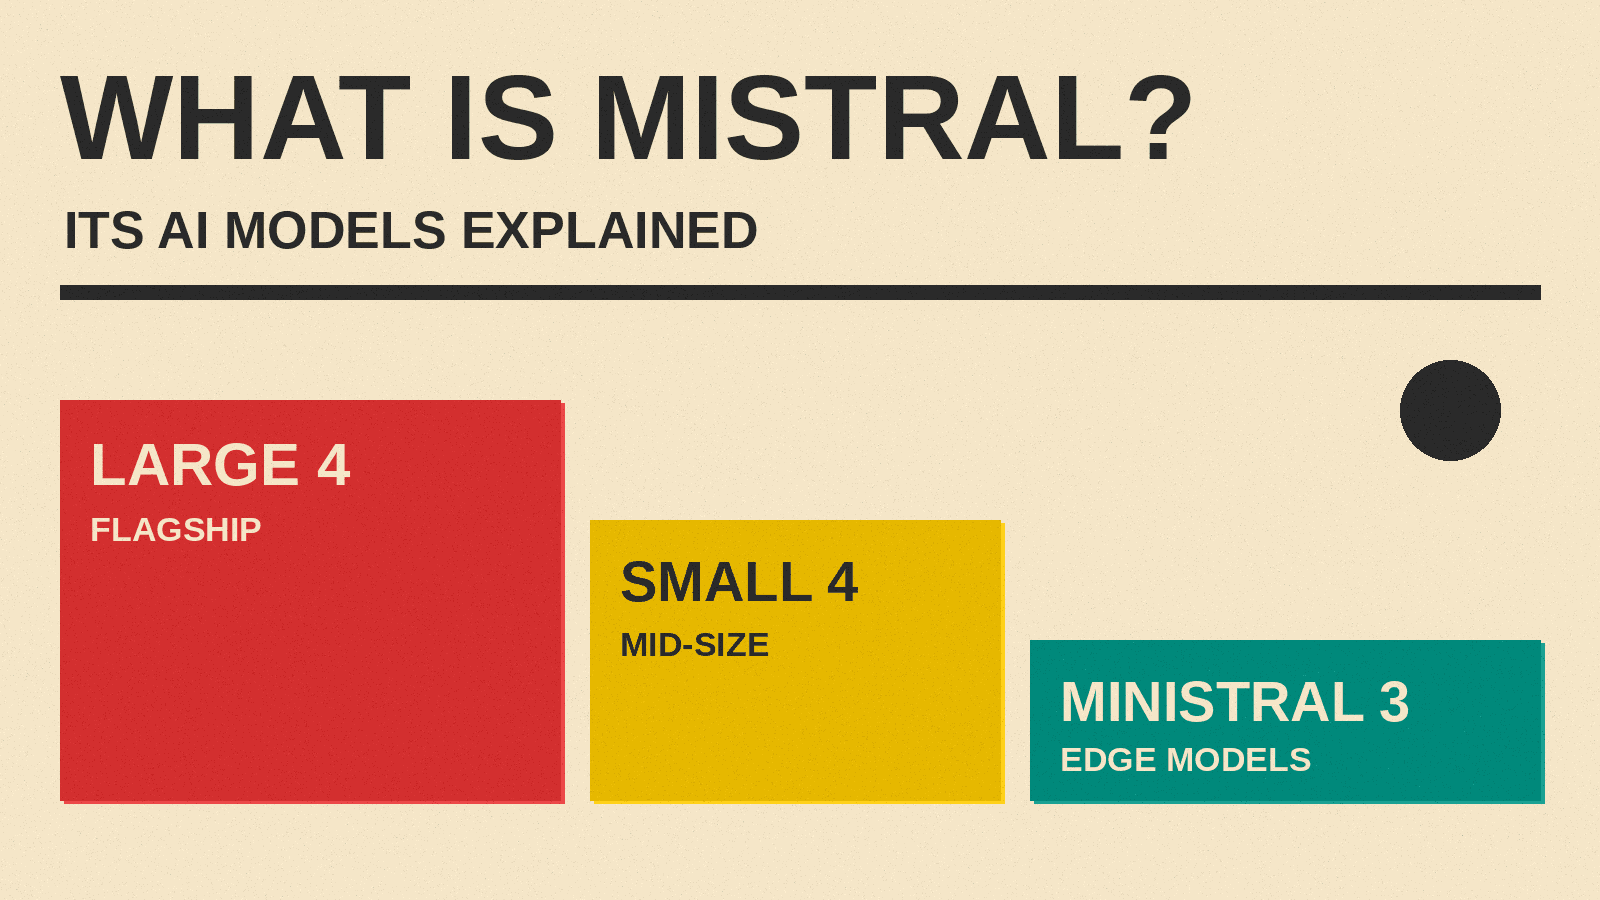
Mistral is a European AI lab that releases open-weight models. See the Large 4, Small 4 and Ministral 3 lineup, what each license allows, and how to try them.
A paper argues small models suit many agent steps. My view: test a small model on your agent's most repeated step and keep the big one for the rest.
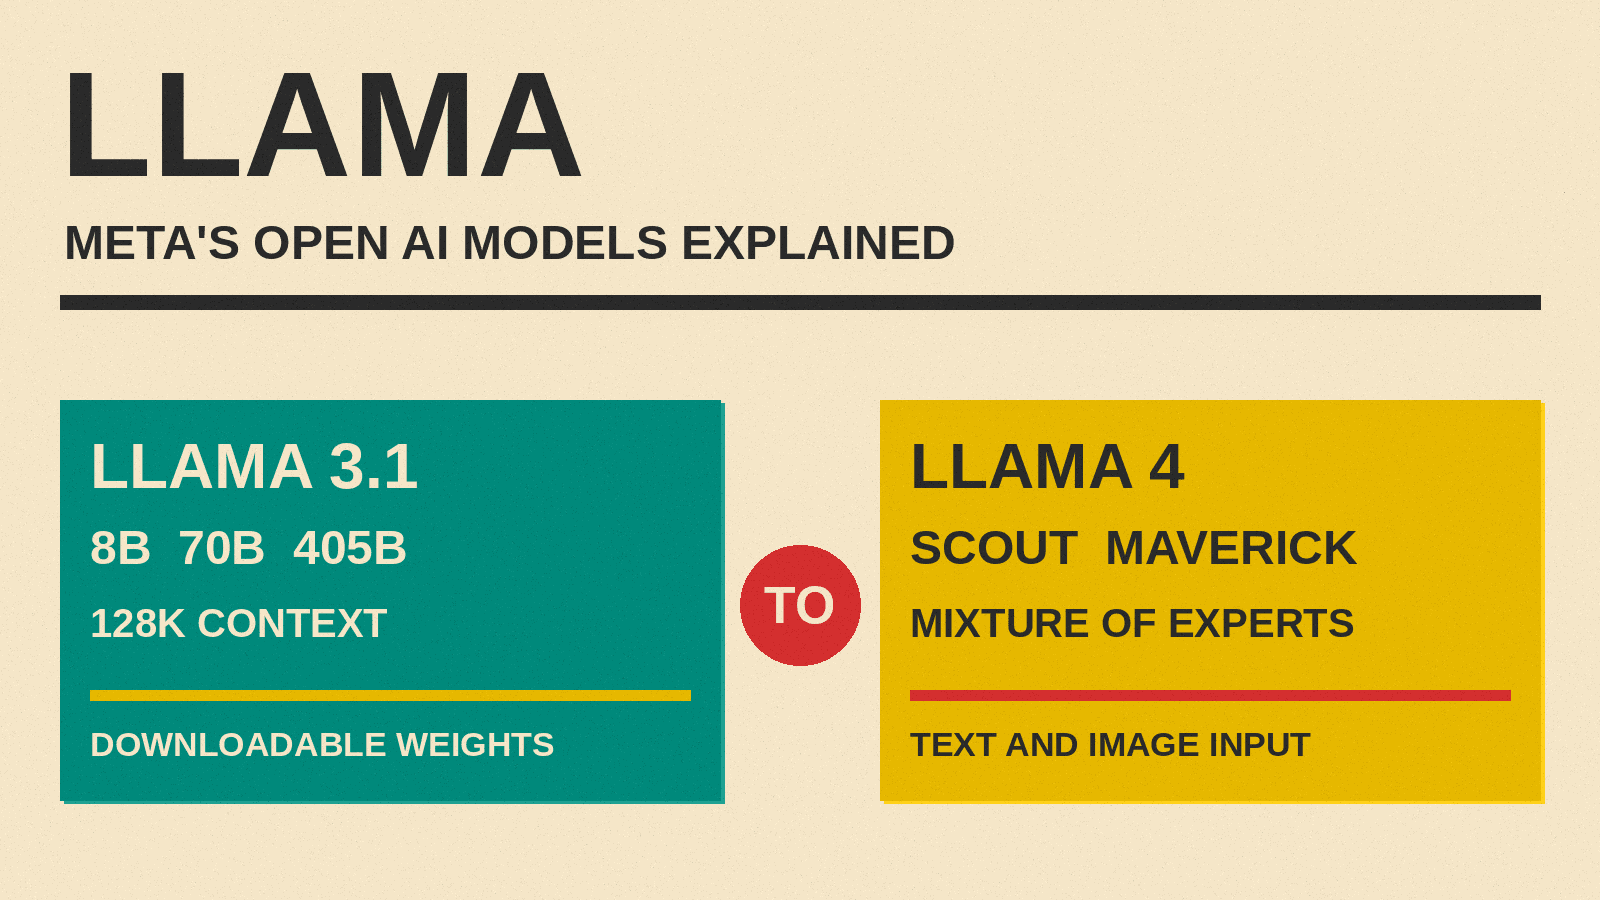
Llama is Meta's family of AI models with downloadable weights. See how Llama 3.1 and Llama 4 differ, what the license requires, and where Muse fits in now.
What a large language model is, how it is trained, how it writes an answer one token at a time, where it goes wrong, and how it differs from a chatbot or agent.
Ollama or LM Studio? A plain comparison for beginners: install, interface, models, local API, license and price, hardware and privacy, from official sources.
A context window sets how much text a model can take in. Three studies suggest that is not the same as using it well. My view: test your own task and send less.
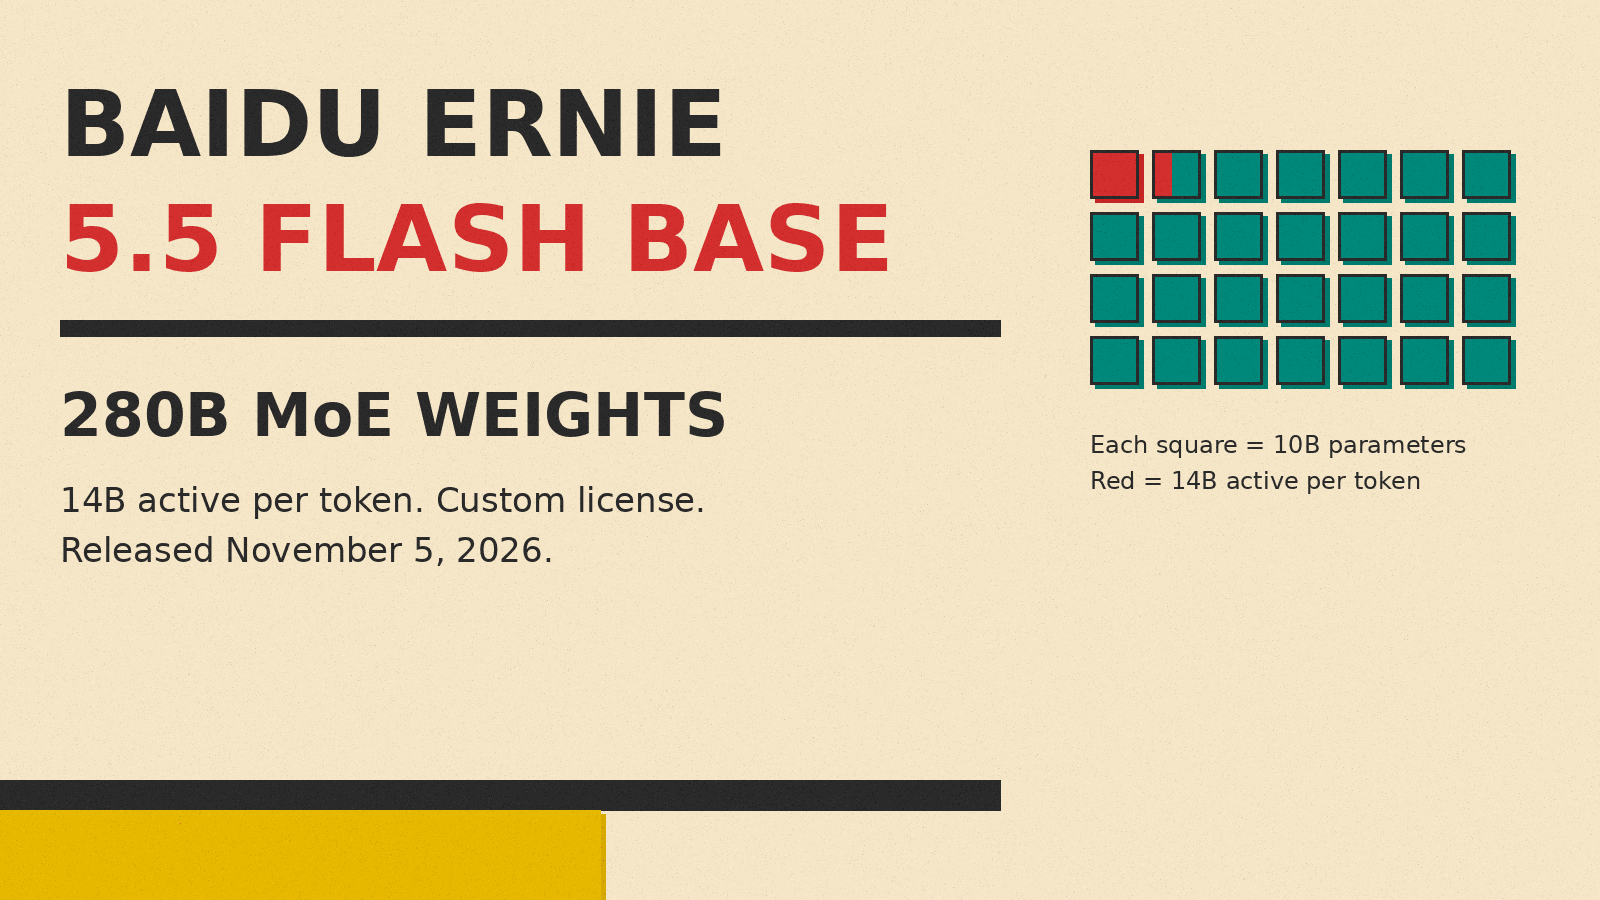
Baidu released ERNIE-5.5-Flash-Base on Nov 5, 2026: a 280B MoE with 14B active per token, 1M context and a custom license that excludes the EU and UK.
SuperCLUE's November 2026 leaderboard puts Kimi K3.1 Pro first among ranked Chinese models at 61.46. See the five test areas, the scores and the caveats.
Meituan released LongCat-2.5, a 1.6T-parameter model it says was trained entirely on Chinese accelerators. Its price, benchmark claims and open questions.
DPO tunes a chat model from human preferences with no reward model and no RL loop. How it works and what the Stanford paper measured.
Who makes MiniMax, what its text, video, speech and music models do, where Hailuo AI, Talkie and MiniMax Code fit, how to try them, and privacy basics.
Kimi K3.1 Pro, DeepSeek V4.1 Flash and MiniMax M3.1 Flash compared on one Artificial Analysis index, price per token, cost per task, speed and license terms.
Tencent released Hy4 on November 4, 2026 with image input and computer use, the Preview's price, and open weights promised in the coming days.
Training AI on AI-made text can degrade models, a Nature paper found. Keeping real data in the mix avoids collapse. The real risk is losing data provenance.
Reasoning models write hidden tokens before they answer. How that thinking works, how to control it, what it costs, and the limits of shown reasoning.
Parameters times bytes per parameter, plus about 20 percent. How to estimate the RAM or VRAM an open model needs, with worked examples from 3B to 70B.