Subscribe
Topic / page 12

LLM

Articles, page 12

221-240
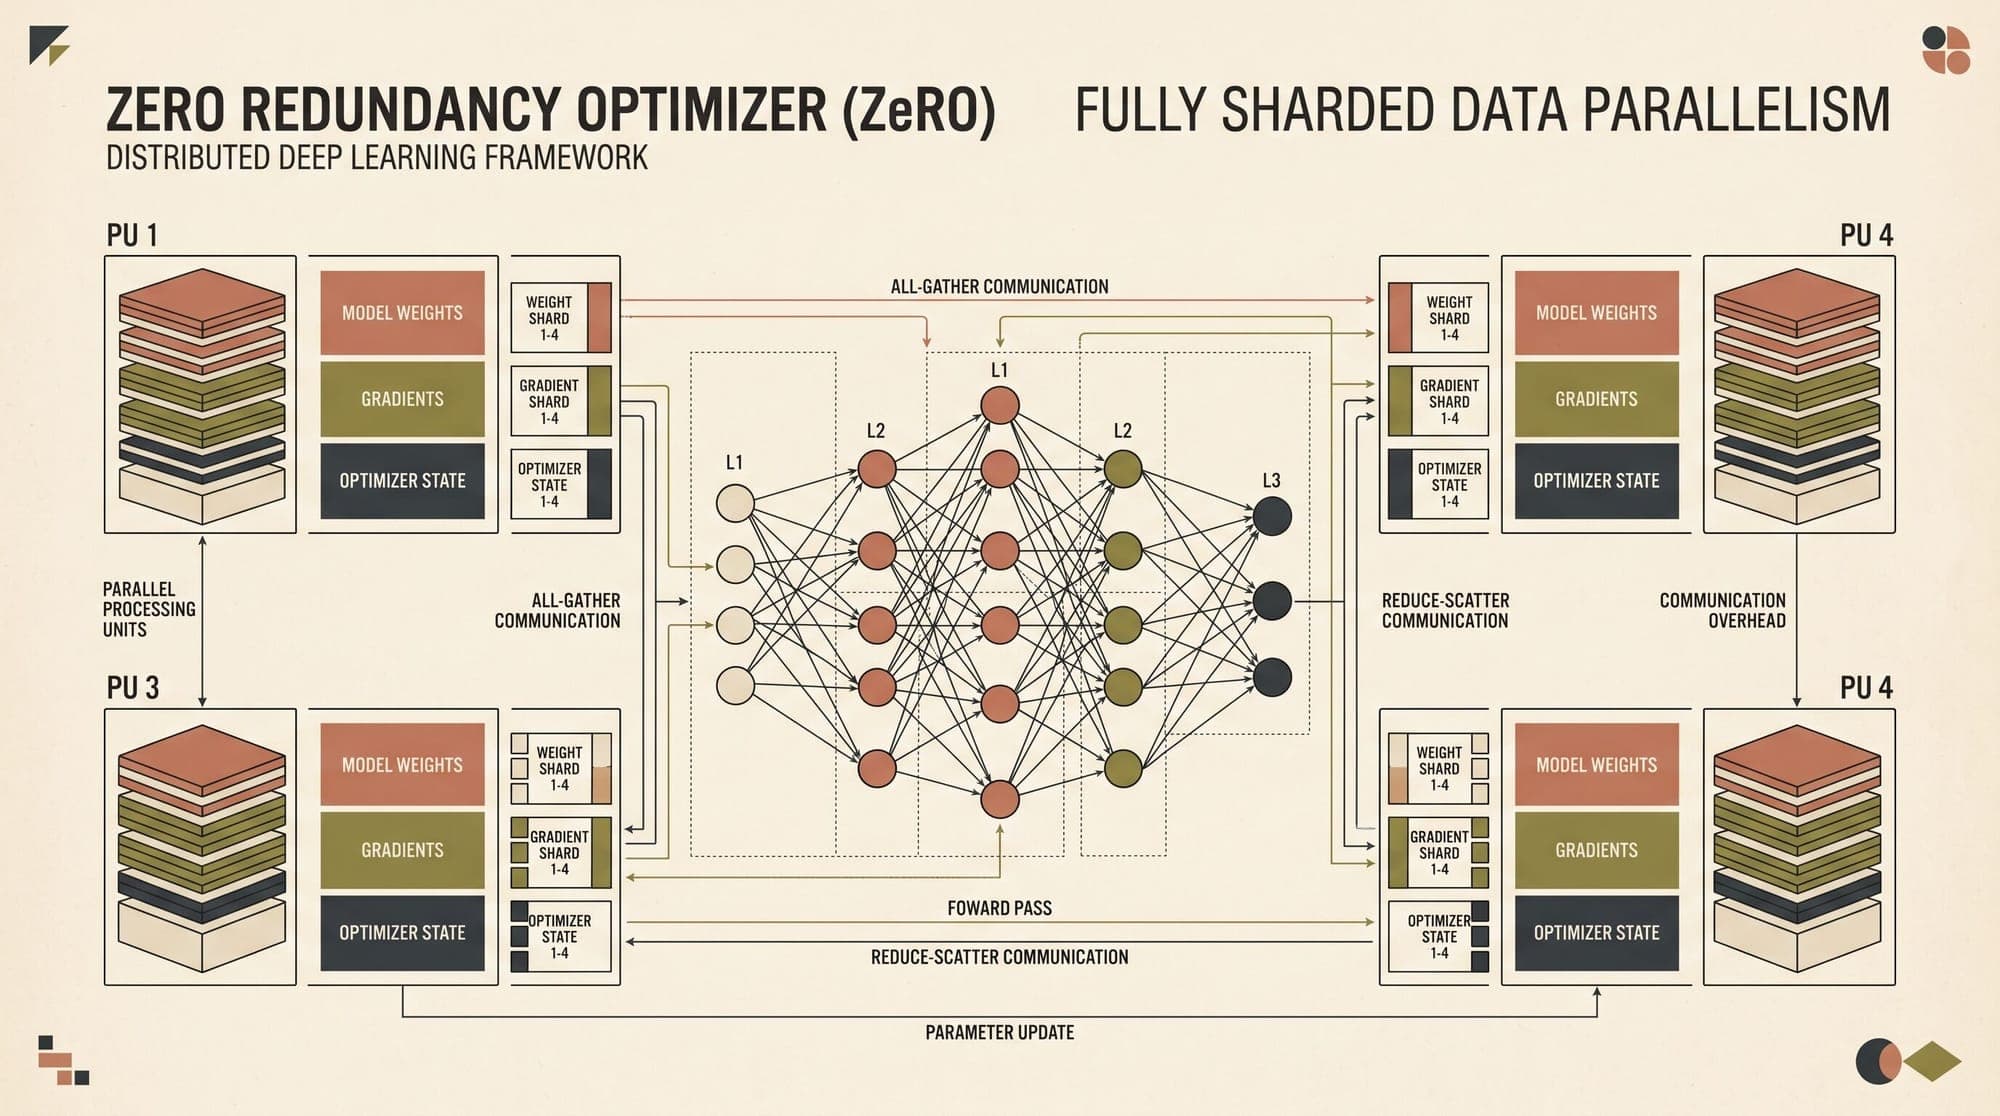
  1. Zero Redundancy Optimizer (ZeRO) and Fully Sharded Data Parallelism (FSDP): Mathematical Foundations of Memory Partitioning, Communication Complexity, and Overlapped Execution

    Training modern frontier large language models requires orchestrating compute across thousands of accelerators. As parameter counts scaled from billions to hundreds of billions, the memory capacity of single accelerators (such as 80 GB on an NVIDIA H100 or 96 GB on an H200) became a primary scaling bottleneck. Traditional distributed training paradigms relied on standard Data Parallelism (DDP), where every GPU maintains a complete replica of the model weights, gradients, and optimizer states, sy
    AI
    12 min read
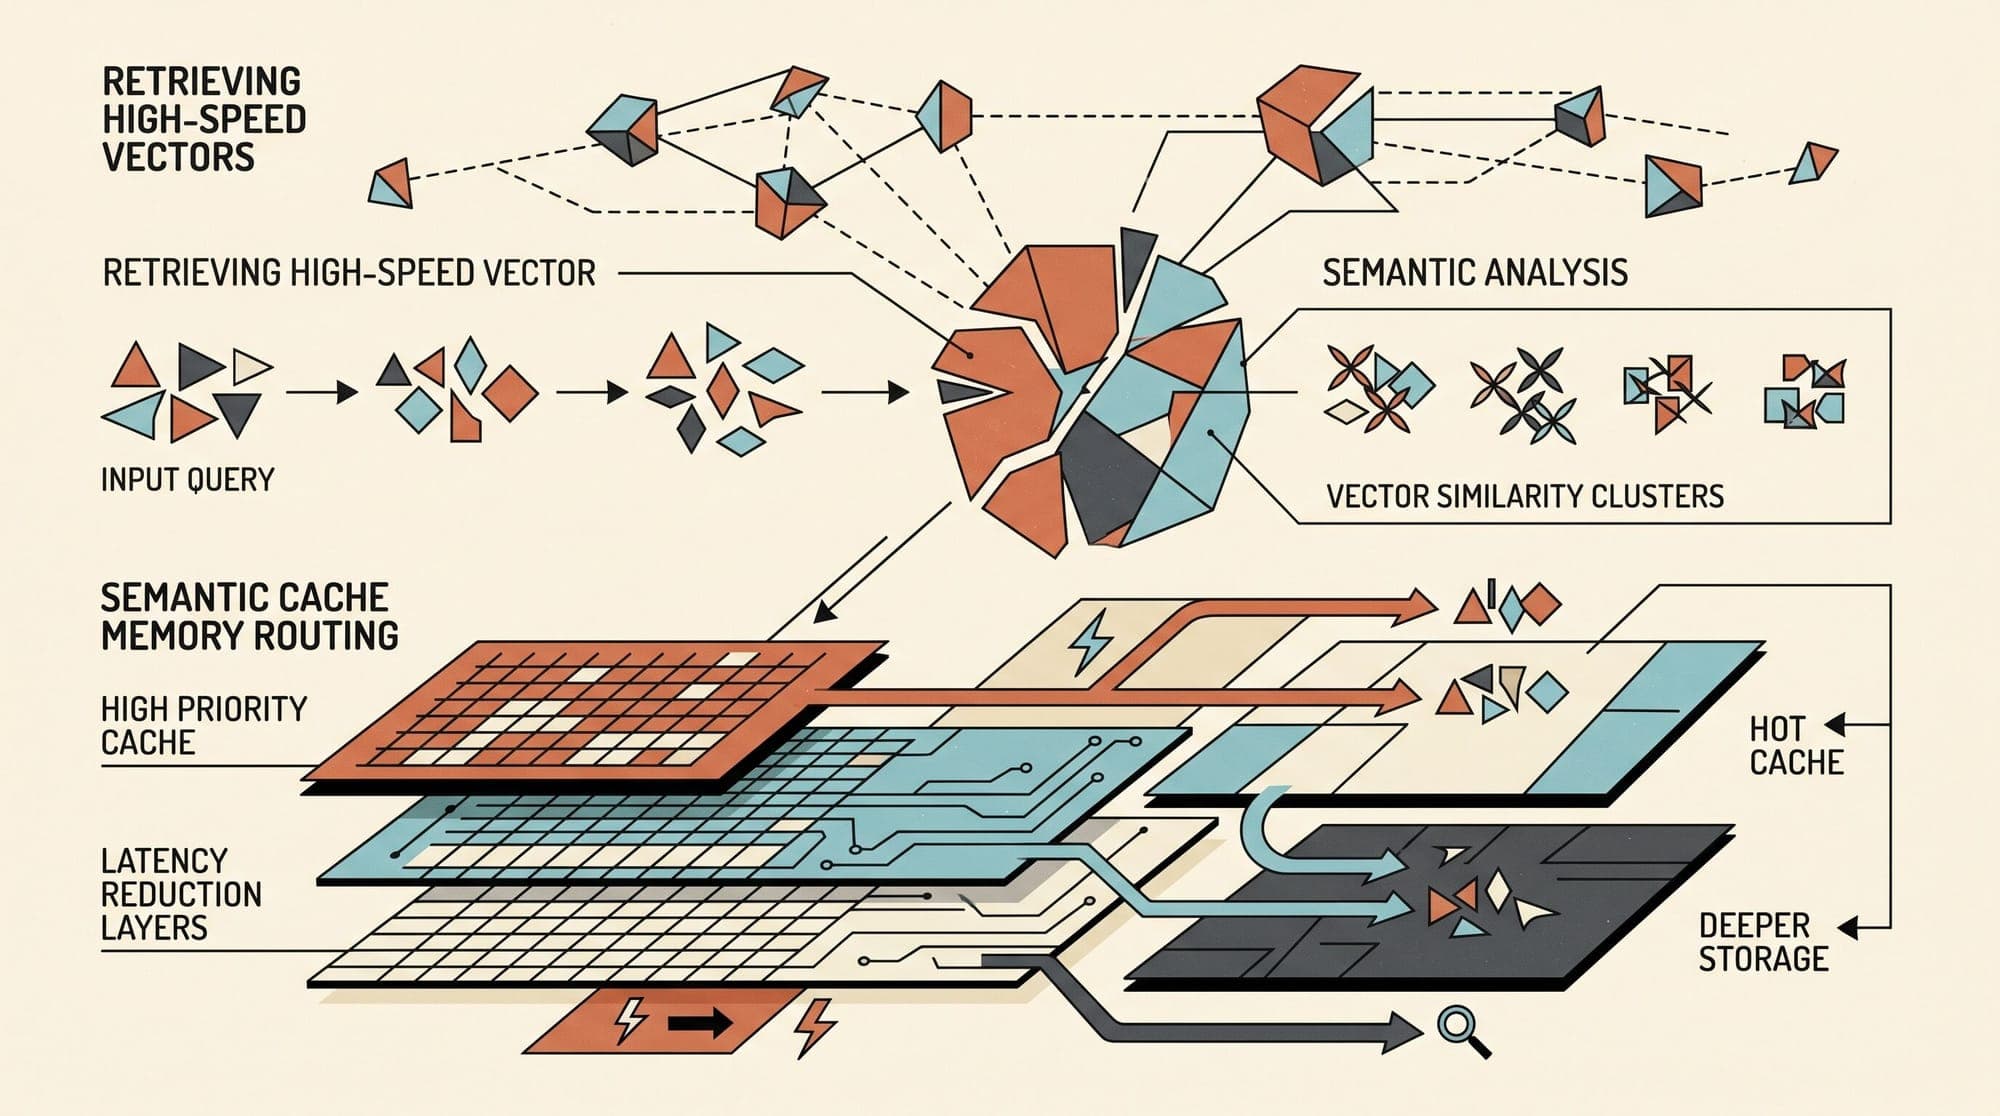
  2. Semantic Caching Engines in Production LLM Systems: Comparing GPTCache, RedisVL, Portkey, and Cloudflare AI Gateway

    Semantic Caching Engines in Production LLM Systems: Comparing GPTCache, RedisVL, Portkey, and Cloudflare AI Gateway Standard exact-match caching strategies fail in large language model applications. Because natural language is inherently variable, users asking the exact same question will use different phrasing, punctuation, sentence structures, or synonyms. Exact string hashing (such as MD5 or SHA-256 caching over raw prompt strings) rarely yields hit rates above 3% to 5% in production convers

    AI
    10 min read
  3. RMSNorm and SwiGLU: Mathematical Foundations of Scaling-Invariant Normalization, Gated Activations, and FFN Architectures in Modern LLMs

    The architectural baseline of modern autoregressive large language models has converged on a distinct set of mathematical primitives. While early Transformer architectures relied on standard Layer Normalization, Post-LN residual routing, and two-layer Multi-Layer Perceptrons with ReLU or GELU activations, state-of-the-art open-weights models such as LLaMA, Mistral, Gemma, Qwen, and DeepSeek utilize a different combination: Root Mean Square Layer Normalization (RMSNorm), Pre-LN residual connectio

    AI
    10 min read
  4. Chunking Strategies in Production RAG: Comparing Fixed-Size, Semantic Chunking, Late Chunking, and Contextual Retrieval

    In production Retrieval-Augmented Generation (RAG) pipelines, the chunking strategy determines the theoretical ceiling of retrieval quality. Splitting documents into discrete text spans transforms continuous discourse into isolated segments. When chunks are indexed in isolation, critical context disappears: pronoun antecedents lose their referents, domain-specific acronyms lose their definitions, and propositions spanning arbitrary token boundaries become fragmented. Selecting an appropriate ch

    AI
    9 min read
  5. Matryoshka Representation Learning (MRL): Mathematical Foundations, Multi-Scale Loss Optimization, and Adaptive Vector Retrieval

    Matryoshka Representation Learning (MRL) has become the standard architectural foundation for modern dense text embeddings. Introduced by Kusupati et al. at NeurIPS 2022 and subsequently deployed across frontier embedding models like OpenAI text-embedding-3, Nomic Embed, and BAAI BGE-M3, MRL solves a structural inefficiency in vector retrieval: the rigid coupling between embedding dimensionality, memory consumption, and semantic fidelity. Traditional dense encoders project arbitrary text sequen

    AI
    9 min read
  6. Synthetic Data Generation and Data Curation Pipelines in Production: Comparing Distilabel, NVIDIA NeMo Curator, Data-Juicer, and InstructLab

    As frontier language models exhaust human-authored web text, pretraining and post-training performance increasingly depends on automated data curation and synthetic data synthesis. Unfiltered public corpora introduce duplicate content, synthetic artifacts, low-reasoning text, and licensing liabilities. Modern foundation models, including Meta's Llama 3.1, NVIDIA's Nemotron-4 340B, Alibaba's Qwen 2.5, and IBM's Granite, are trained on datasets where synthetic generation and rigorous multi-stage f

    Data Curation
    9 min read
  7. Tensor Parallelism and Pipeline Parallelism: Mathematical Foundations of Megatron-LM 1D Slicing, Sequence Parallelism, and 1F1B Scheduling

    Scaling modern large language models beyond tens of billions of parameters quickly exhausts the physical memory and compute throughput of individual graphics processing units. A 70-billion-parameter model stored in 16-bit floating-point (FP16 or BF16) requires 140 GB of VRAM solely for model weights. During full-precision training with the Adam optimizer, parameter states, gradients, and optimizer momentum terms demand approximately 16 to 18 bytes per parameter (amounting to 1.12 TB to 1.26 TB f

    AI
    10 min read
  8. Durable Execution Engines for AI Agents in Production: Comparing Temporal, Inngest, Hatchet, and Restate

    Durable Execution Engines for AI Agents in Production: Comparing Temporal, Inngest, Hatchet, and Restate Architecture, State Persistence, Event Replay, and Latency Overheads Building production AI agents requires solving a fundamental systems failure: language model reasoning loops are inherently long-running, non-deterministic, and prone to transient failures. When an autonomous agent executes a 20-step chain involving web scraping, document parsing, API queries, code generation, and human app

    AI
    9 min read
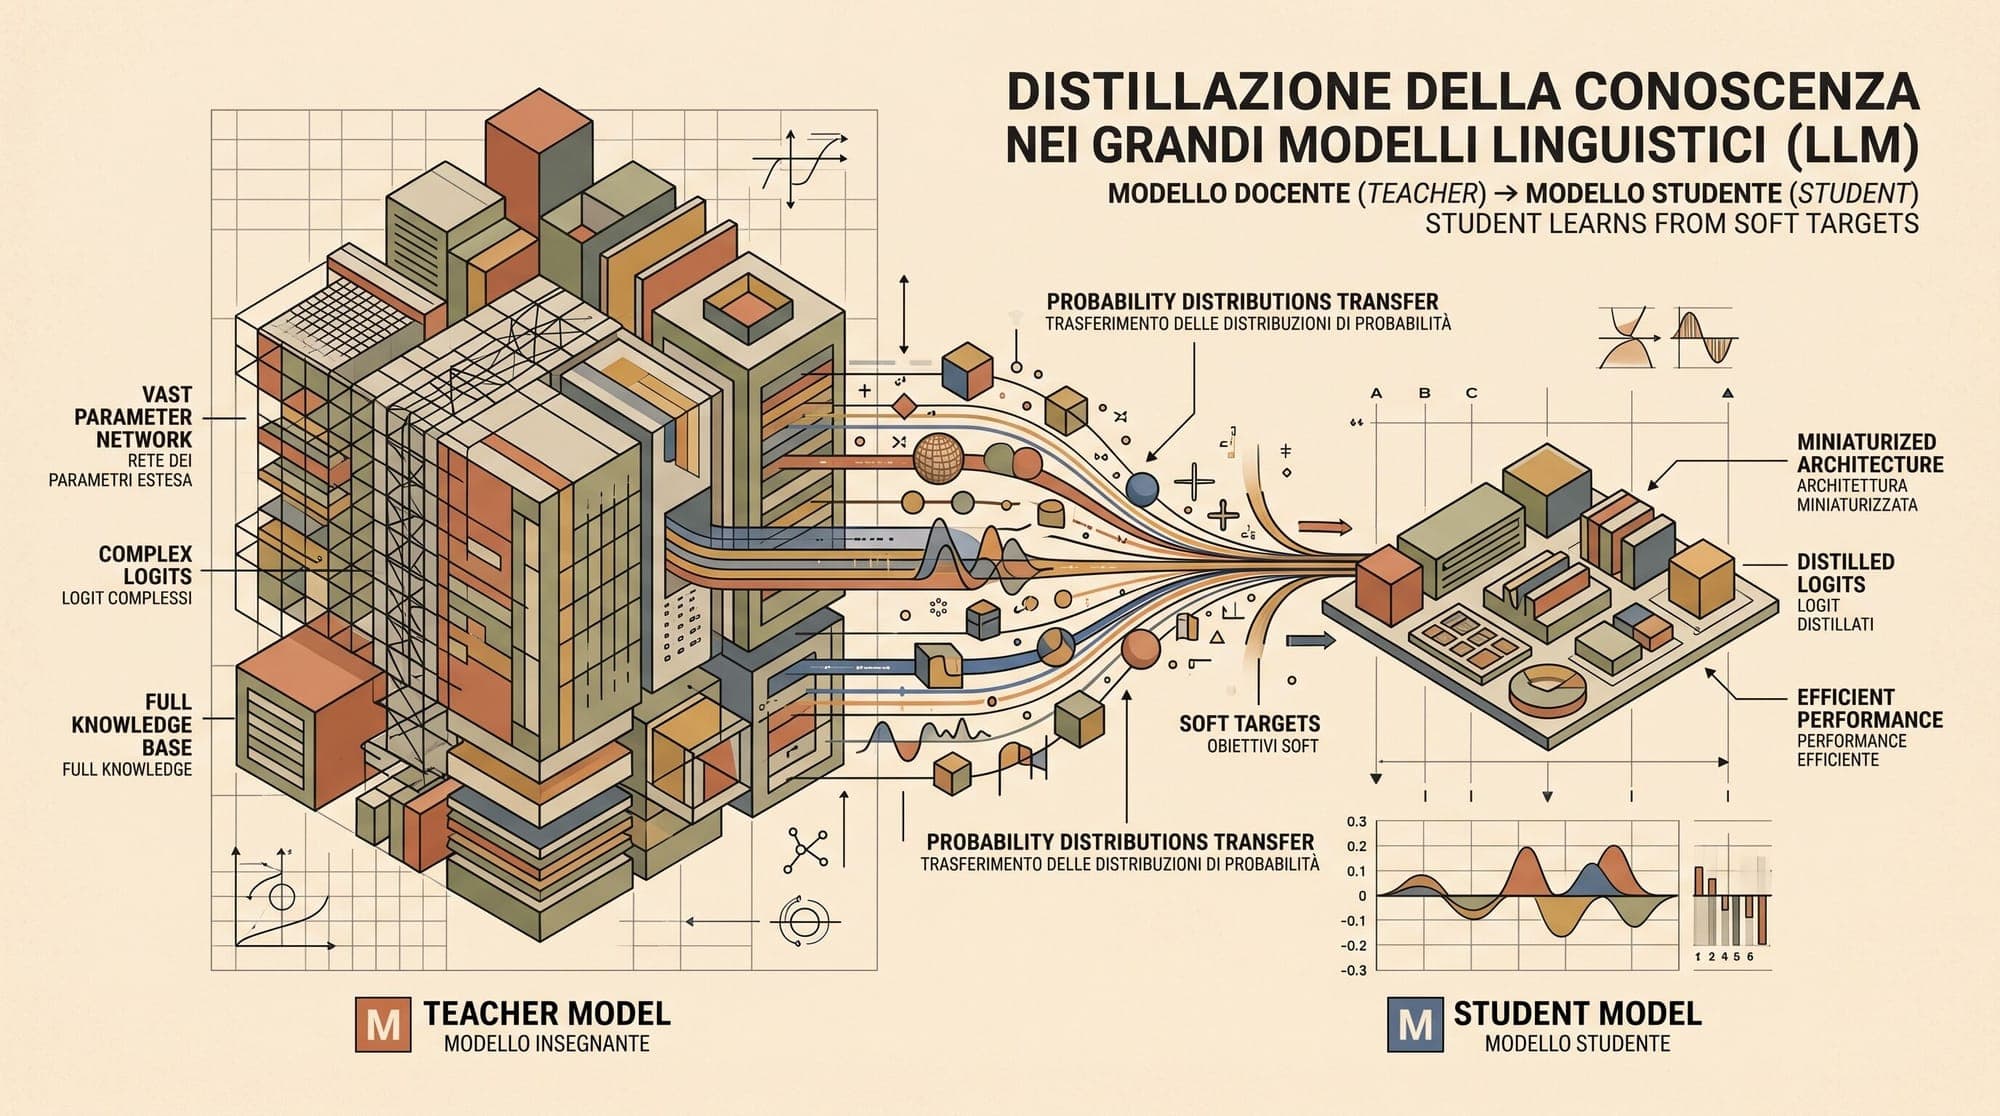
  9. Knowledge Distillation in Large Language Models: Mathematical Foundations of Forward vs. Reverse KL Divergence, Sequence-Level Distillation (SeqKD), and On-Policy Mode-Seeking Objectives

    Deploying frontier large language models in latency-critical and compute-constrained environments remains an active challenge in artificial intelligence systems. While parameter scale correlates directly with downstream generalization and emergent reasoning capabilities, the memory footprint and FLOP intensity of dense multi-hundred-billion parameter architectures impose prohibitive operational costs. Post-training compression strategies such as quantization and structural pruning reduce precisi

    AI
    11 min read
  10. LLM Red Teaming and Automated Adversarial Testing in Production: Comparing Garak, Microsoft PyRIT, Promptfoo Red Team, and HarmBench

    Manual penetration testing and bespoke adversarial prompt engineering cannot scale to modern production LLM systems. As language models transition from isolated completion endpoints to stateful autonomous agents with tool-calling capabilities, file system access, and external retrieval pipelines, their attack surface expands combinatorially. Static test suites and manual prompt probing fail to catch subtle multi-turn jailbreaks, prompt injections, and indirect data poisoning vulnerabilities befo

    AI
    10 min read
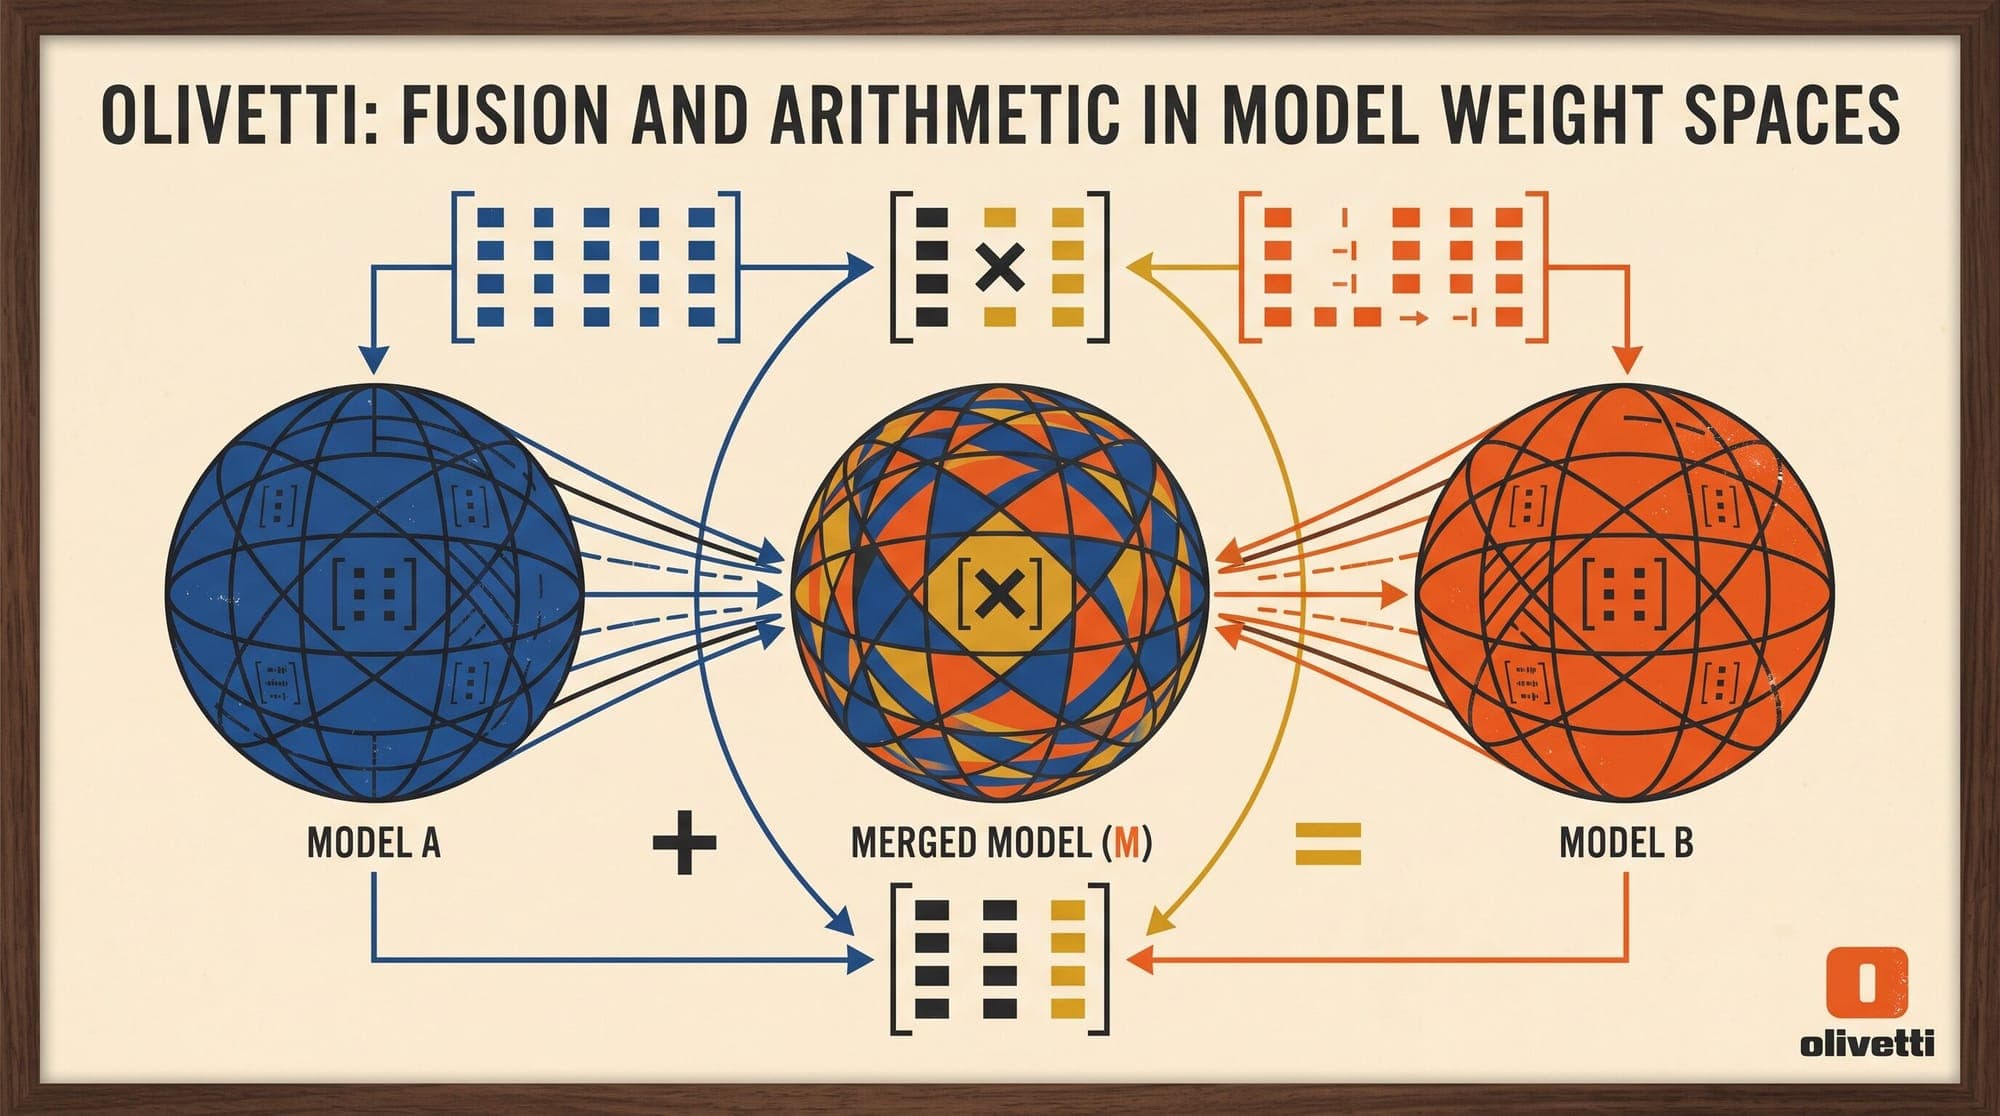
  11. Model Merging in Weight Space: Mathematical Foundations of Task Vectors, TIES-Merging, DARE, and Spherical Linear Interpolation

    Training large language models across multiple downstream domains typically requires expensive multi-task supervised fine-tuning (SFT) or sequential continual learning. Both paths present steep practical challenges: multi-task training demands simultaneous access to massive, curated datasets and massive compute budgets, while sequential fine-tuning suffers from catastrophic forgetting. Model merging has emerged as a data-free, compute-efficient alternative. By combining the parameters of multip

    AI
    8 min read
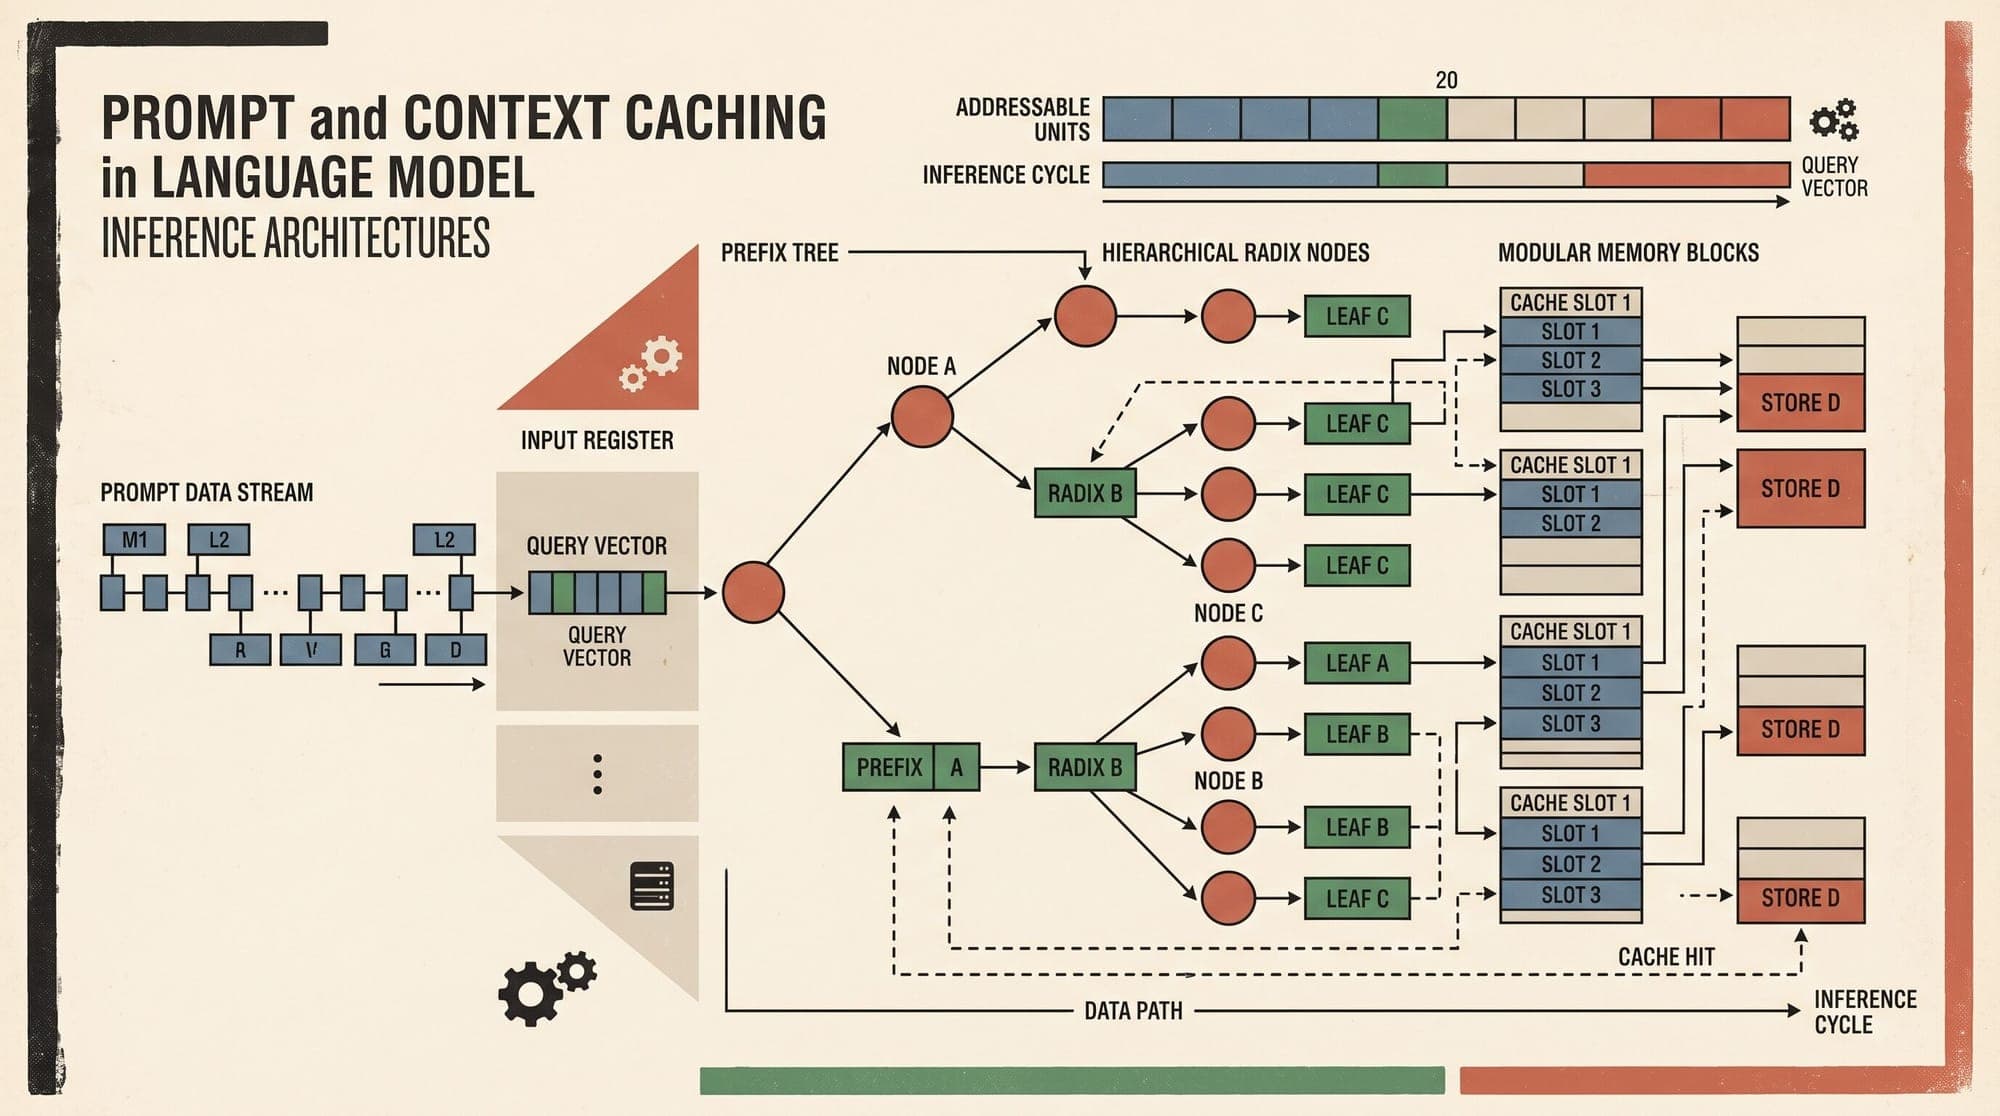
  12. Prompt and Context Caching in Production: Comparing Anthropic, OpenAI, DeepSeek, Google Gemini, and RadixAttention KV Reuse

    Modern LLM serving workloads spend a disproportionate share of computational budget and time-to-first-token (TTFT) latency on prompt prefill. In agentic loops, retrieval-augmented generation (RAG), and multi-turn chat applications, repeated prompts often share 80% to 95% of their token sequences across requests. Without caching, inference engines recompute key-value (KV) attention tensors across every input token on every turn, driving quadratic compute overhead and memory bandwidth saturation.

    AI
    5 min read
  13. Anthropic Hires Google TPU Architect Amir Salek for In-House Silicon Push

    Anthropic has hired Amir Salek, the engineer who established Google's custom silicon program and led the development of its first seven Tensor Processing Unit (TPU) generations, to expand the AI lab's in-house semiconductor engineering initiatives. Salek joins Anthropic's compute team and reports to James Bradbury, Bloomberg reported (via The Economic Times). Anthropic has indicated that it wants to build an in-house silicon business and has begun hiring and listing jobs for the effort. Backg

    AI
    2 min read
  14. Google Releases Gemini Omni 1.1 Flash with Scene Extension and Keyframe Control

    Google DeepMind has released Gemini Omni 1.1 Flash, updating its multimodal generative video model with programmatic editing controls, extended scene generation, and lower-cost drafting tiers. The model is accessible via the Gemini API in Google AI Studio and the Gemini Enterprise Agent Platform. Update, November 9, 2026: Google has since released Gemini Omni 1.2 Flash, with 15-second clips and lower prices. See our post on Gemini Omni 1.2 Flash. The update addresses primary friction points in

    AI
    3 min read
  15. AI Agent Sandboxes and Safe Code Execution Runtimes in Production: Comparing E2B, Modal, Daytona, and Docker/gVisor Architecture, Isolation Boundaries, Startup Latency, and Serving Economics

    Autonomous AI agents, evaluation harnesses, and code generation pipelines increasingly execute untrusted code generated directly by Large Language Models. When an agent runs dynamic Python scripts, executes terminal shell commands, installs arbitrary packages via package managers, or browses the web, it introduces severe security and operational risks. These risks include host privilege escalation, kernel exploitation, container breakout vulnerabilities such as CVE-2024-21626, credential theft v

    AI
    8 min read
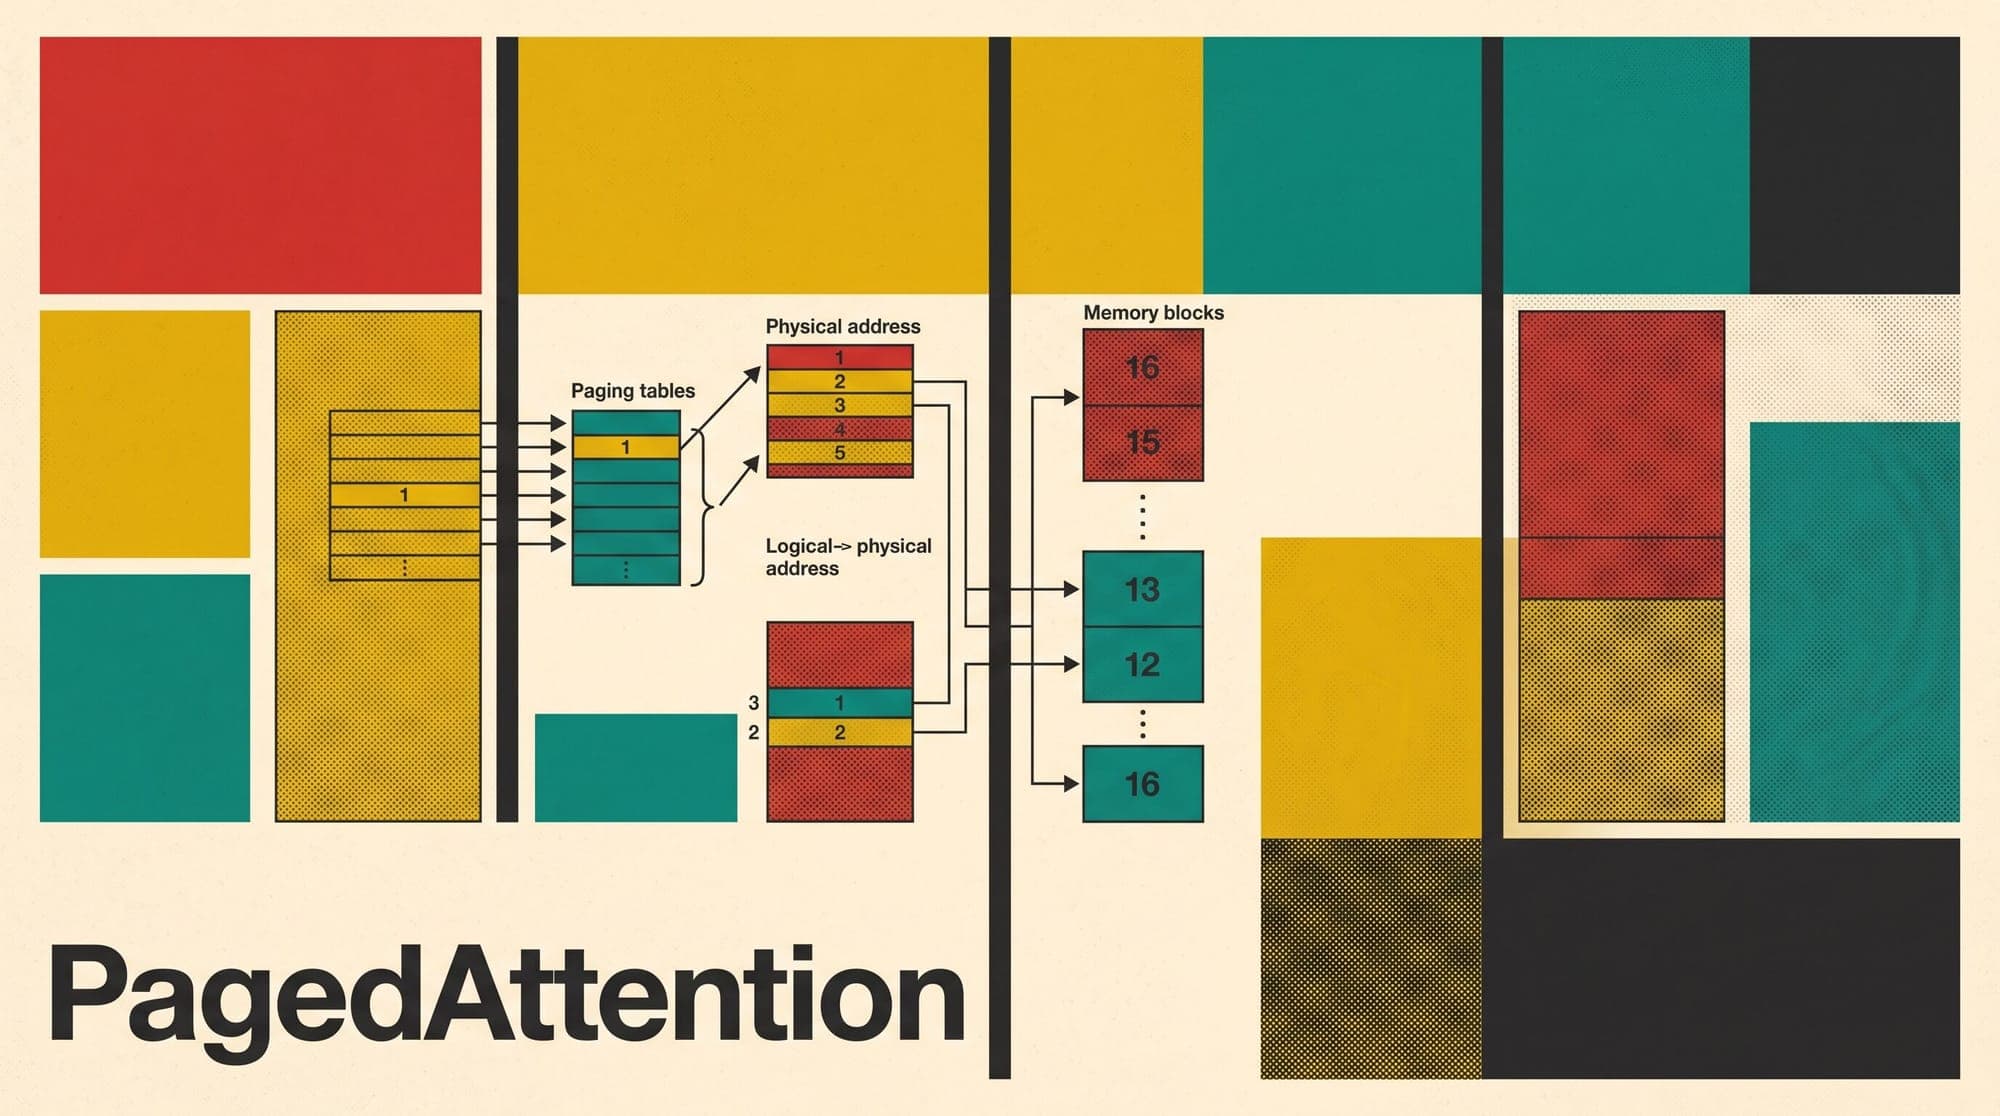
  16. PagedAttention and Virtual Memory Management: Mathematical Foundations of Non-Contiguous KV-Cache Allocation, Dynamic Block Translation, and Copy-on-Write Forking Mechanics

    In autoregressive transformer serving, the generation phase is fundamentally constrained by GPU memory capacity and memory bandwidth rather than raw compute throughput. While the initial prefill phase processes the prompt in parallel with high arithmetic intensity, the subsequent token-by-token decoding phase computes attention for only a single new token per sequence at each step. At each decoding step, the model must read all historical Key (K) and Value (V) activation tensors from GPU High Ba

    AI
    13 min read
  17. Agentic Web Scraping and Headless Browser Automation in Production: Comparing Crawl4AI, Browser-Use, Stagehand, and ScrapeGraphAI

    Agentic Web Scraping and Headless Browser Automation in Production: Comparing Crawl4AI, Browser-Use, Stagehand, and ScrapeGraphAI Web scraping has undergone a fundamental architectural transition. For decades, automated data extraction relied on deterministic parsers such as Beautiful Soup, Scrapy, and raw headless browser drivers like Playwright or Puppeteer. These tools depended on hand-crafted CSS selectors, XPath expressions, and rigid execution trees. While computationally lightweight, sel

    AI
    10 min read
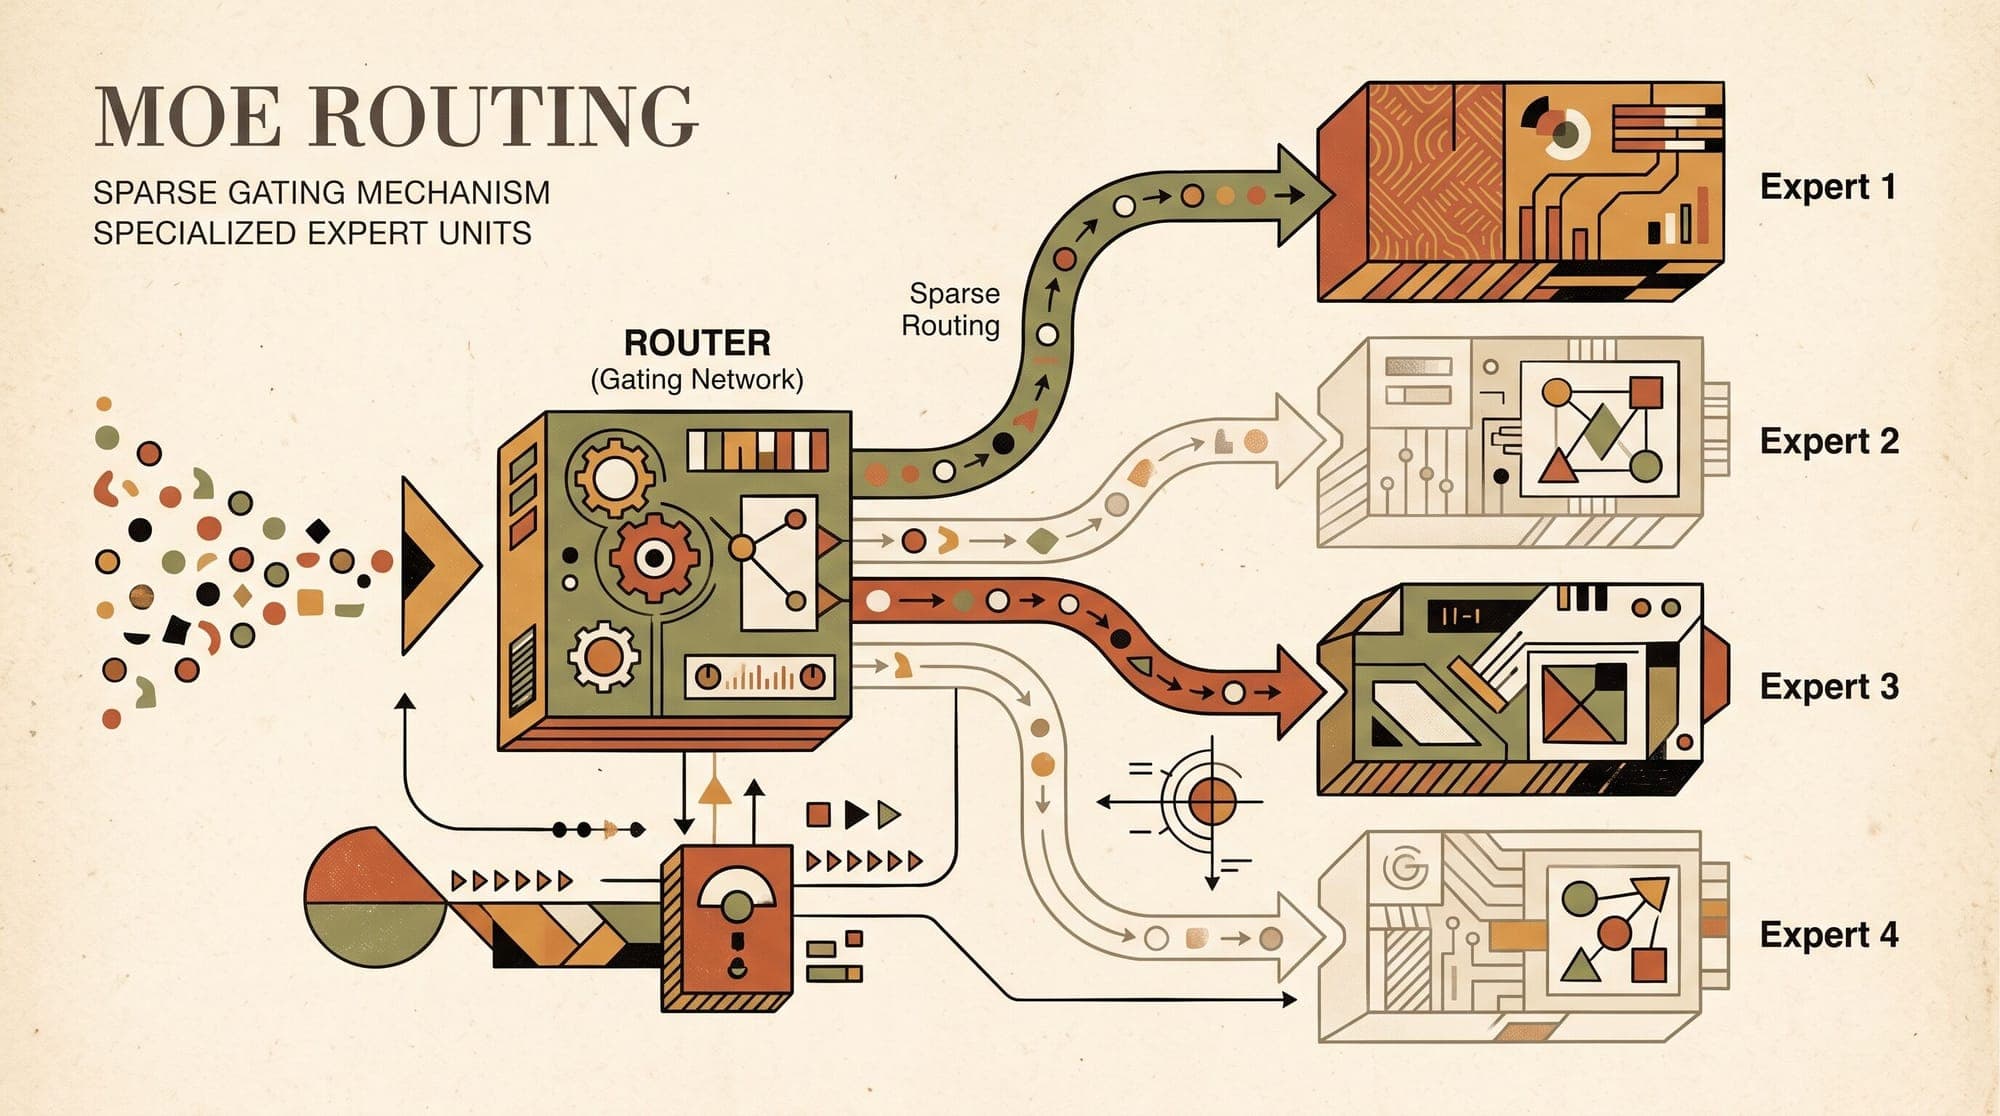
  18. Mixture-of-Experts (MoE) Routing and Load Balancing: Mathematical Foundations of Noisy Top-k Gating, Expert Capacity, Auxiliary Balancing Losses, and Loss-Free Load Balancing

    Mixture-of-Experts (MoE) Routing and Load Balancing: Mathematical Foundations of Noisy Top-k Gating, Expert Capacity, Auxiliary Balancing Losses, and Loss-Free Load Balancing Scaling dense transformer models incurs computational costs that grow proportionally with parameter count. In dense architectures, every token in a sequence activates all feed-forward network (FFN) parameters across every layer. Sparse Mixture-of-Experts (MoE) architectures decouple parameter count from per-token compute b

    AI
    15 min read
  19. Document Parsing Engines in Production RAG: Comparing Docling, Marker, MinerU, and Unstructured Architecture, Layout Analysis, Table Extraction, and Serving Economics

    Retrieval-Augmented Generation (RAG) systems frequently fail not in their embedding models or vector databases, but at the initial document ingestion layer. When enterprise documents (including financial 10-K filings, clinical trial reports, technical manuals, and multi-column academic papers) are parsed using legacy text scrapers such as basic pypdf or pdfminer, structural semantics are lost. Multi-column reading orders interleave across paragraphs, header and footer noise pollutes vector indic

    AI
    9 min read
  20. Autonomous Coding Agent Harnesses in Production: Comparing OpenHands, SWE-agent, Aider, and Cline

    The transition from inline code completion to autonomous software engineering harnesses marks a structural shift in how frontier models interact with codebases. Where early coding assistants operated within narrow token completion windows, modern agentic harnesses construct closed action-observation loops. These systems inspect repository structures, invoke compiler toolchains, execute unit test suites, parse stdout diagnostics, and iteratively correct syntax and logic errors until a pull reques

    AI
    5 min read