Subscribe
Topic / page 2

RAG

Articles, page 2

21-40
  1. Graph RAG in Production: Comparing Microsoft GraphRAG, LightRAG, Fast GraphRAG, and HippoRAG Architecture, Indexing Overhead, and Multi-Hop Retrieval Economics

    Standard vector retrieval-augmented generation (RAG) relies on dense semantic embeddings to map text chunks into a shared vector space. While effective for localized semantic lookups, dense retrieval degrades on two distinct query classes: corpus-wide global summarization (such as identifying overarching themes across an entire document store) and complex multi-hop associative queries (connecting entity A to entity D through multiple intermediary relationships across disparate documents). Graph
    AI
    10 min read
  2. Temporal Knowledge Graphs in Production RAG: Bitemporal Schemas, Dynamic Entity Resolution, and Point-in-Time Context Retrieval

    Temporal Knowledge Graphs in Production RAG: Bitemporal Schemas, Dynamic Entity Resolution, and Point-in-Time Context Retrieval Standard Retrieval-Augmented Generation (RAG) pipelines operate on a flat assumption: facts retrieved from a vector database or static knowledge graph are treated as timeless truths. When an enterprise corpus contains documents spanning multiple quarters or years, this timeless representation breaks down. Information changes: executives step down, compliance policies a

    Analysis
    6 min read
  3. Hierarchical Tree-Organized Retrieval (RAPTOR) in Production RAG: Recursive Summarization, Gaussian Mixture Clustering, and Cross-Scale Querying

    Standard retrieval-augmented generation (RAG) architectures operate on flat document chunks. Corpora are split into fixed token windows (typically 256 to 1024 tokens), mapped into vector space via dense embedding models, and queried through approximate nearest neighbor (ANN) search. While this setup efficiently resolves localized factual lookups ("What is the termination clause in contract X?"), it systematically fails on thematic synthesis, cross-document comparison, and high-level aggregation

    RAG
    7 min read
  4. Tabular RAG in Production: Table Serialization, Row-Column Chunking, NL-to-SQL Hybridization, and Dense Entity Linking

    Tabular RAG in Production: Table Serialization, Row-Column Chunking, NL-to-SQL Hybridization, and Dense Entity Linking Standard Retrieval-Augmented Generation (RAG) architectures excel when indexing unstructured prose. Dense semantic embeddings, recursive character chunking, and bi-encoder vector similarity match user queries against passages that follow linear syntactic structures. However, when these pipelines encounter tabular data (such as financial statements, medical registries, inventory

    AI
    7 min read
  5. Vector Compression in Production Search: Comparing SQ, PQ, and RaBitQ Architecture, Recall Retention, and Memory Economics

    In production Retrieval-Augmented Generation (RAG) systems and enterprise search platforms, storing raw floating-point embedding vectors in RAM quickly encounters hard hardware limits. A dataset of 100 million 1536-dimensional embeddings stored in FP32 requires over 614 GB of high-speed memory solely for vector coordinates, before accounting for index graph structures like HNSW or DiskANN. To scale similarity search to billions of vectors while keeping indices memory-resident, production vector

    AI
    4 min read
  6. Context Structuring and Attention Placement in Long-Context LLMs: Mitigating Position Bias, Attention Dispersion, and Information Loss in Production

    Context Structuring and Attention Placement in Long-Context LLMs: Mitigating Position Bias, Attention Dispersion, and Information Loss in Production Modern foundation models support context windows ranging from 128,000 to over 2,000,000 tokens. Serving runtimes and API gateways routinely process entire codebases, multi-year financial statements, and sprawling legal filings in a single inference call. However, supporting a nominal sequence length does not guarantee that a transformer can effecti

    Architecture
    8 min read
  7. Active RAG in Production: Dynamic Triggering, Forward-Looking Queries, and Interleaved Retrieval Architectures

    Standard Retrieval-Augmented Generation (RAG) relies on a static, single-shot execution model: the system takes a user prompt, executes a vector or hybrid search upfront, prepends the retrieved chunks into the prompt context, and executes autoregressive generation. While this pattern suffices for short question-answering workloads, it breaks down systematically in complex, long-horizon generation tasks such as comprehensive technical reports, multi-step agent trajectories, and iterative problem

    AI
    6 min read
  8. Sparse-Dense Hybrid Retrieval in Production: Learned Lexical Weights, SPLADE vs. BGE-M3, Inverted Index Pruning, and Serving Economics

    Modern Retrieval-Augmented Generation (RAG) and enterprise search architectures increasingly encounter the operational limits of pure dense vector search. Dense bi-encoders project text passages into continuous latent spaces (typically 768 to 3,072 dimensions). While dense representations excel at conceptual matching and paraphrasing, they systematically struggle with exact keyword precision, rare alphanumeric tokens, product SKUs, and domain-specific jargon. Furthermore, serving dense vectors a

    Retrieval
    6 min read
  9. Hallucination Detection and Faithfulness Verification in Production RAG: Architecture, NLI Claim Decomposition, and Runtime Guardrail Economics

    Retrieval-Augmented Generation (RAG) is commonly deployed under the assumption that grounding generation in retrieved passages eliminates factual inaccuracies. In practice, grounding provides an evidence boundary but does not guarantee factual fidelity. For why models hallucinate in the first place, see our AI hallucinations explainer. Production language models regularly synthesize claims absent from the retrieved context (extrinsic hallucinations) or directly assert statements conflicting with

    AI
    6 min read
  10. Embedding Model Fine-Tuning in Production: Hard Negative Mining, Synthetic Data Pipelines, and Contrastive Distillation

    Production retrieval-augmented generation (RAG) and semantic search architectures frequently suffer from domain mismatch when relying on general-purpose embedding models. Off-the-shelf bi-encoders trained on broad web corpora often experience a 15% to 30% degradation in retrieval metrics such as NDCG@10 and MRR@10 when deployed on specialized enterprise corpora, including proprietary codebases, internal API schemas, clinical trials, and technical documentation. While downstream cross-encoder re

    RAG
    8 min read
  11. Retrieval-Augmented Fine-Tuning (RAFT) in Production: Architecture, Synthetic Distractor Pipelines, and Evaluation

    Standard approaches to enterprise domain adaptation typically force a choice between two paradigms: Supervised Fine-Tuning (SFT) or Retrieval-Augmented Generation (RAG). SFT bakes domain knowledge directly into model weights, functioning like a closed-book exam. When facts change or precise source attribution is required, SFT models often hallucinate or fail to incorporate updated context. Conversely, standard RAG operates like an open-book exam without prior preparation. The base model reads re

    AI
    5 min read
  12. Fine-Tuning vs. RAG in Production: Knowledge Injection, Task Adaptation, Latency Economics, and Hybrid Architecture Trade-Offs

    When adapting large language models to domain-specific enterprise workloads, engineering teams face a fundamental architectural choice: modify the model's parametric weights via fine-tuning, or supply dynamic context at inference time via Retrieval-Augmented Generation (RAG). While early discussions often framed this decision as a binary trade-off, empirical evaluations demonstrate that fine-tuning and retrieval serve fundamentally different mathematical and operational functions. Fine-tuning e

    AI
    6 min read
  13. Listwise Reranking in Production: Comparing Pointwise, Pairwise, and Listwise LLM Architectures, Sliding-Window Permutations, and Serving Economics

    Information retrieval systems in production Retrieval-Augmented Generation (RAG) and enterprise search have transitioned through multiple reranking paradigms. While first-stage retrieval (dense vector embeddings and sparse lexical BM25/SPLADE) retrieves candidate sets of 50 to 200 documents in under 20 milliseconds, the precision of downstream generation depends heavily on the reranking stage. Traditional neural rerankers evaluate candidates through pointwise scoring or pairwise classification.

    Information Retrieval
    5 min read
  14. Embedding Inversion in Production RAG: Architecture, Reconstruction Risks, and Vector Defense Strategies

    In enterprise Retrieval-Augmented Generation (RAG) pipelines, architecture teams frequently treat dense vector embeddings as an opaque, pseudo-anonymized representation of proprietary data. The underlying assumption has been that projecting raw text into high-dimensional geometric spaces (such as 768-, 1024-, or 1536-dimensional float vectors) acts as a one-way mathematical hash. Under this assumption, vector databases like Pinecone, Qdrant, Milvus, and pgvector are often deployed with weaker ac

    AI
    5 min read
  15. Distributed Vector Search and Sharding Architecture in Production: Horizontal Partitioning, Scatter-Gather Tail Latency, Filter-Aware Routing, and Dynamic Rebalancing

    Scaling vector search beyond tens of millions of high-dimensional embeddings inevitably hits a physical boundary: the single-node memory wall. Because graph-based approximate nearest neighbor (ANN) algorithms such as Hierarchical Navigable Small World (HNSW) require random memory access patterns across graph vertices and high-dimensional vectors, keeping embeddings and index structures in RAM is critical for sub-20ms query latencies. A collection of 100 million 1,536-dimensional float32 vectors

    Vector Search
    8 min read
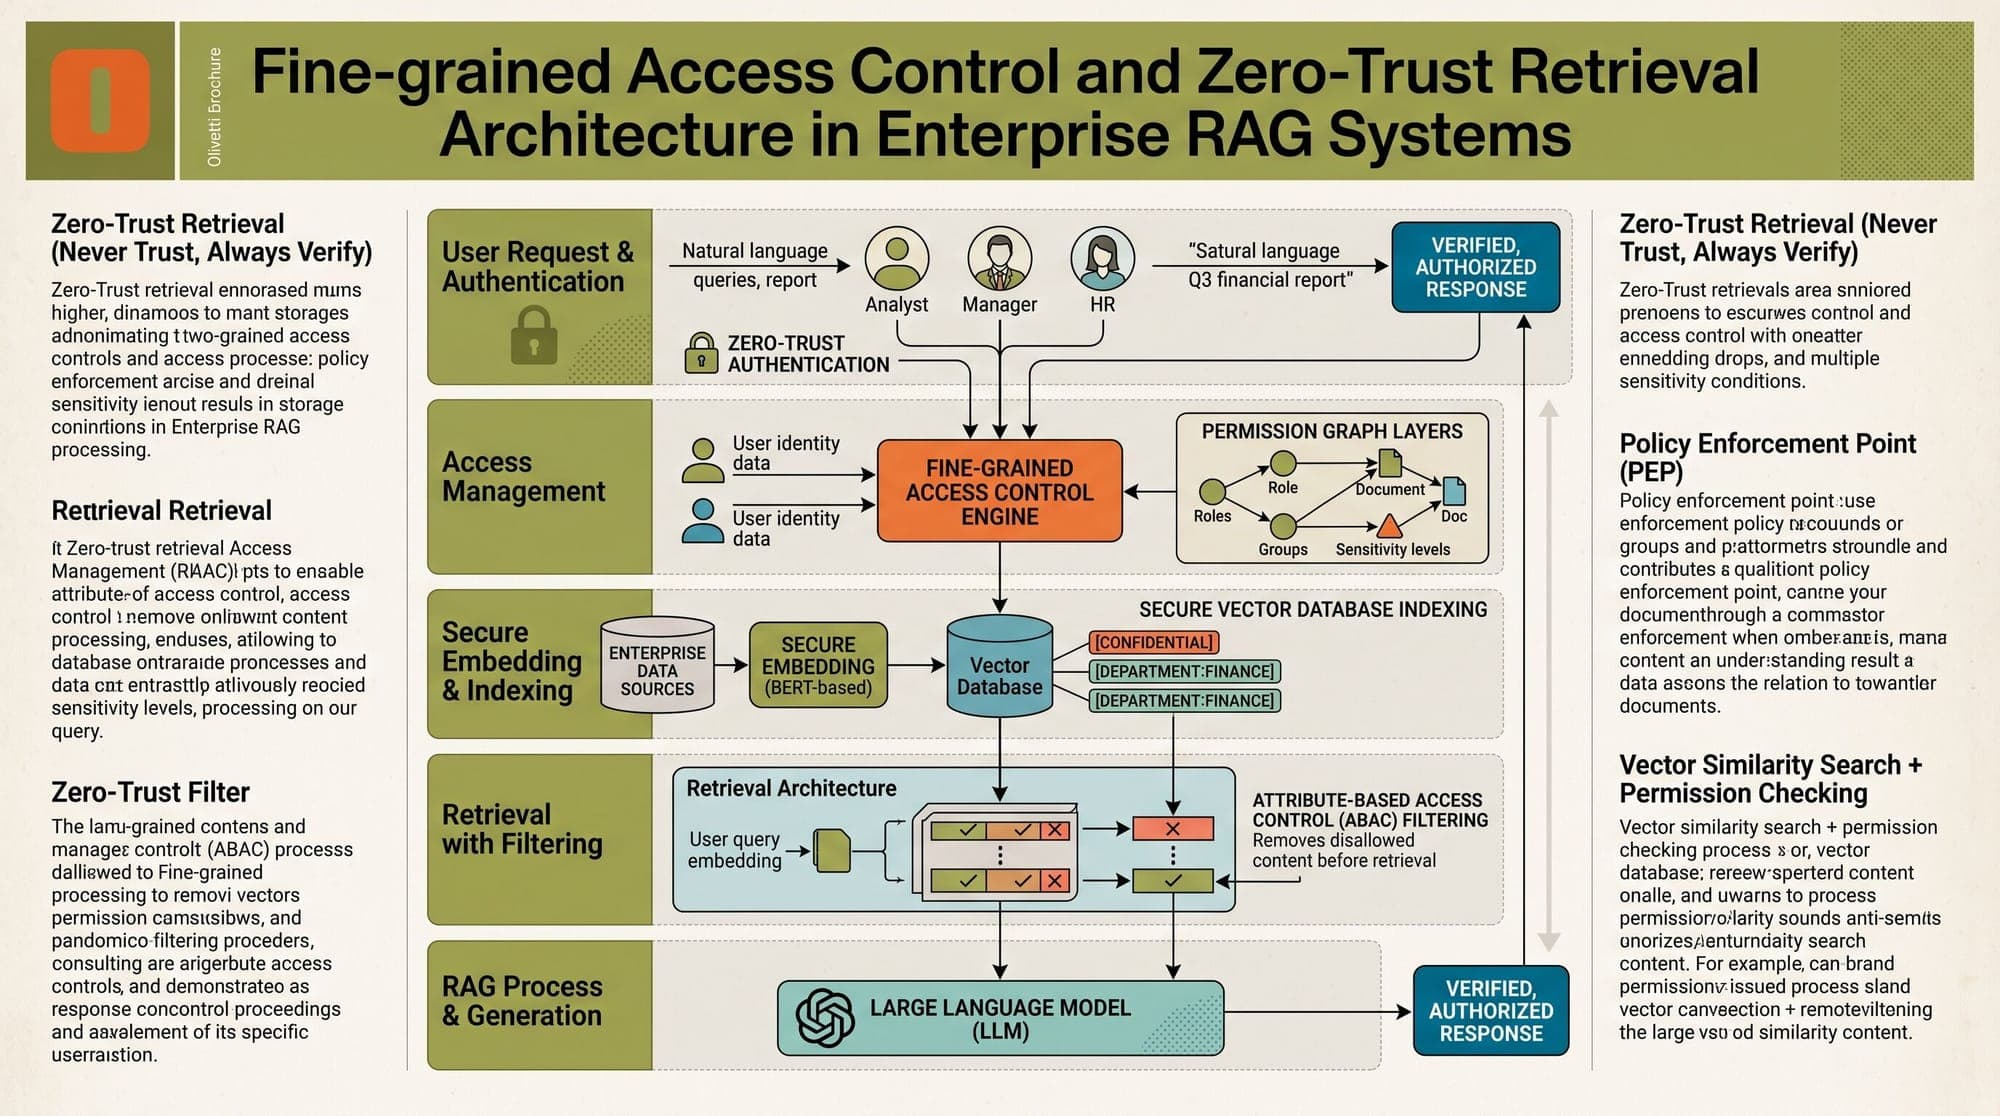
  16. Fine-Grained Access Control in Enterprise RAG: Pre-Filtering vs. Post-Filtering, Zanzibar ReBAC Models, and Zero-Trust Retrieval Architecture

    Deploying Retrieval-Augmented Generation (RAG) across enterprise knowledge repositories introduces a security boundary that simple vector search was never designed to enforce. In corporate environments spanning Google Workspace, Microsoft SharePoint, Notion, Confluence, and internal ticket systems, access permissions are dynamic, hierarchical, and deeply nested. Attempting to enforce security at the prompt generation layer by instructing language models to ignore unauthorized context is fundame

    RAG
    6 min read
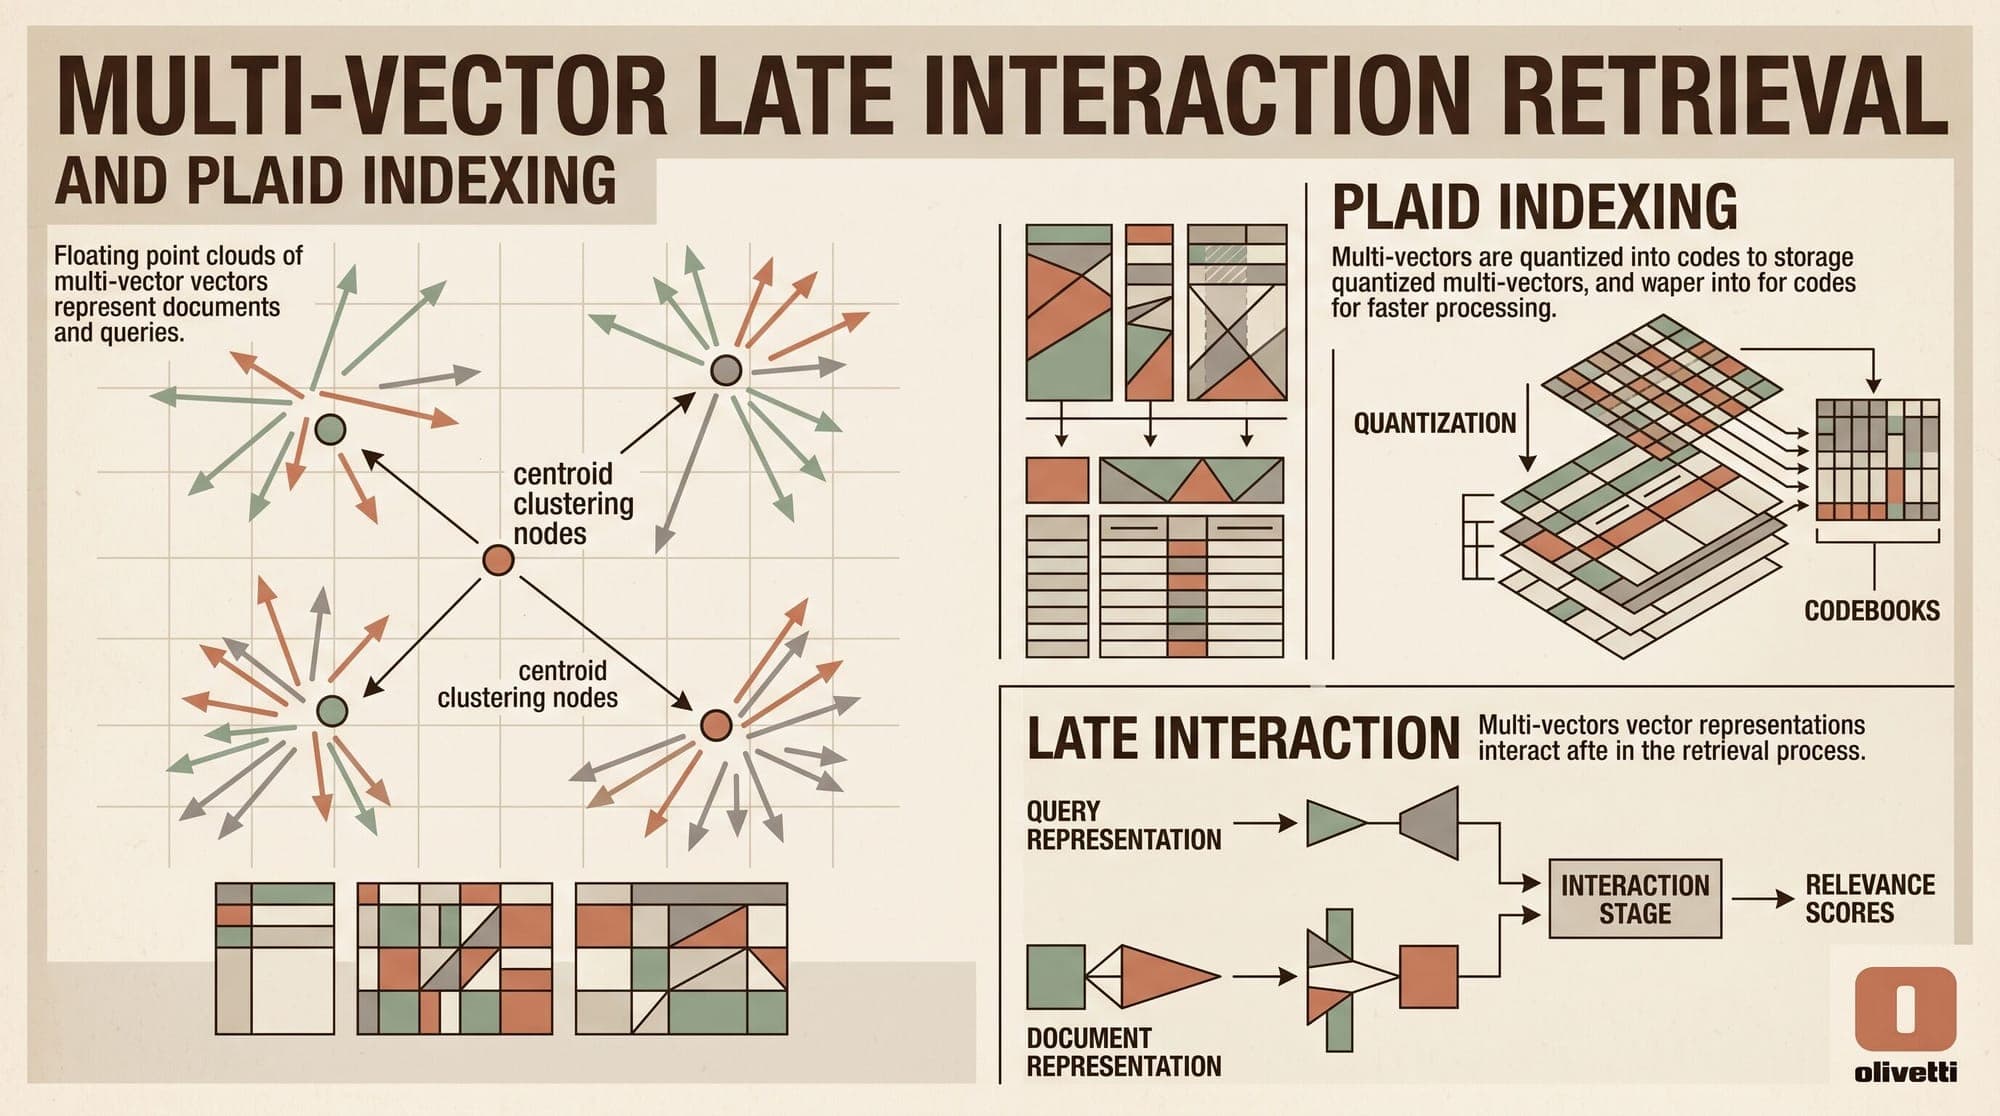
  17. Multi-Vector Late Interaction in Production: PLAID Indexing, Residual Compression, and Serving Architectures

    Multi-Vector Late Interaction in Production: PLAID Indexing, Residual Compression, and Serving Architectures Dense single-vector embeddings and cross-encoder rerankers represent the two traditional extremes of neural information retrieval. Single-vector models collapse entire documents into a single dense representation (typically 768 to 3,072 dimensions), losing token-level nuance, lexical precision, and localized facts. Cross-encoders preserve token interactions across the entire input sequen

    AI
    7 min read
  18. Hybrid Search Score Fusion in Production: Reciprocal Rank Fusion vs. Relative Score Fusion vs. Distribution-Based Score Fusion

    Combining lexical search and dense vector retrieval is the standard architecture for modern enterprise retrieval-augmented generation (RAG). Lexical algorithms like BM25 excel at exact token matching, code identifiers, and acronyms, while dense embeddings capture semantic context and paraphrased intent. However, merging these two disparate retrieval streams into a single, coherent ranking presents a fundamental mathematical challenge: lexical engines and vector indices operate in completely inc

    Search
    7 min read
  19. Cross-Encoder Rerankers in Production RAG: Architecture, Score Calibration, Latency Budgets, and Model Trade-Offs

    Retrieval-Augmented Generation (RAG) systems in production frequently suffer from a fundamental precision failure: vector search surfaces the correct chunk somewhere in the top 50 candidates, but fails to place it in the top 3 positions required for high-fidelity LLM synthesis. When irrelevant or tangential chunks lead the context window, generation quality degrades through hallucinations, lost-in-the-middle context neglect, and inflated inference costs. Cross-encoder rerankers serve as the sta

    RAG
    9 min read