Subscribe
Topic / page 8

LLM

Articles, page 8

141-160
  1. How AI Agents Pay: ACP, UCP, AP2, and x402 Explained

    AI agents now check out and pay on behalf of users. This explainer breaks agent payments into checkout, authorization, and settlement, and shows how ACP, UCP, AP2 mandates, card network tokens, and x402 each solve one part.
    Agents
    9 min read
  2. NVIDIA Publishes an Open Midtraining Recipe for Agentic Coding Models

    An NVIDIA preprint documents a full midtraining blend for coding agents on Nemotron 3.5. After identical SFT, it lifts SWE-bench Multilingual from 55.8 to 62.8 and DeepSWE from 11.7 to 15.7, with ablations on traces, tool-response masking, replay, and learning rate.

    LLM
    7 min read
  3. Test-Time Training (TTT): Mathematical Foundations, Expressive Hidden States, and Linear Complexity in Sequence Models

    Test-Time Training (TTT): Mathematical Foundations, Expressive Hidden States, and Linear Complexity in Sequence Models Sequence modeling has long been characterized by a sharp trade-off between computational efficiency and expressive memory. Transformers provide high expressive capacity by retaining all historical tokens in an uncompressed Key-Value (KV) cache. This structure enables them to scale to long contexts and continuously reduce perplexity as more tokens are conditioned on. However, th

    Education
    8 min read
  4. NVIDIA Releases Nemotron 3.5 Super VL with 120B Parameters and 1M Context Window

    NVIDIA has released Nemotron 3.5 Super VL, an open-weights vision-language model designed for complex agentic workflows. The model features a 120-billion-parameter mixture-of-experts (MoE) architecture that activates 12 billion parameters per token, paired with a context window supporting up to 1 million tokens. NVIDIA announced it alongside Nemotron 3.5 Bolt, a 2-bit model for local agents on RTX Spark PCs. The release is available on Hugging Face in full-precision BF16 reference weights and q

    Nvidia
    2 min read
  5. Intel Unveils Data Center GPU D-Series with 480GB LPDDR5X Memory for AI Inference

    Intel has introduced the Intel GPU D-series, a data center accelerator engineered specifically for large language model inference workloads. Unveiled at the Open Compute Project (OCP) Global Summit, the accelerator (previously codenamed Crescent Island) integrates up to 480GB of LPDDR5X memory, prioritizing raw memory capacity and power efficiency over ultra-high-bandwidth memory tiers. By equipping a single PCIe accelerator with 480GB of memory, Intel surpasses the onboard capacity of Nvidia's

    Hardware
    2 min read
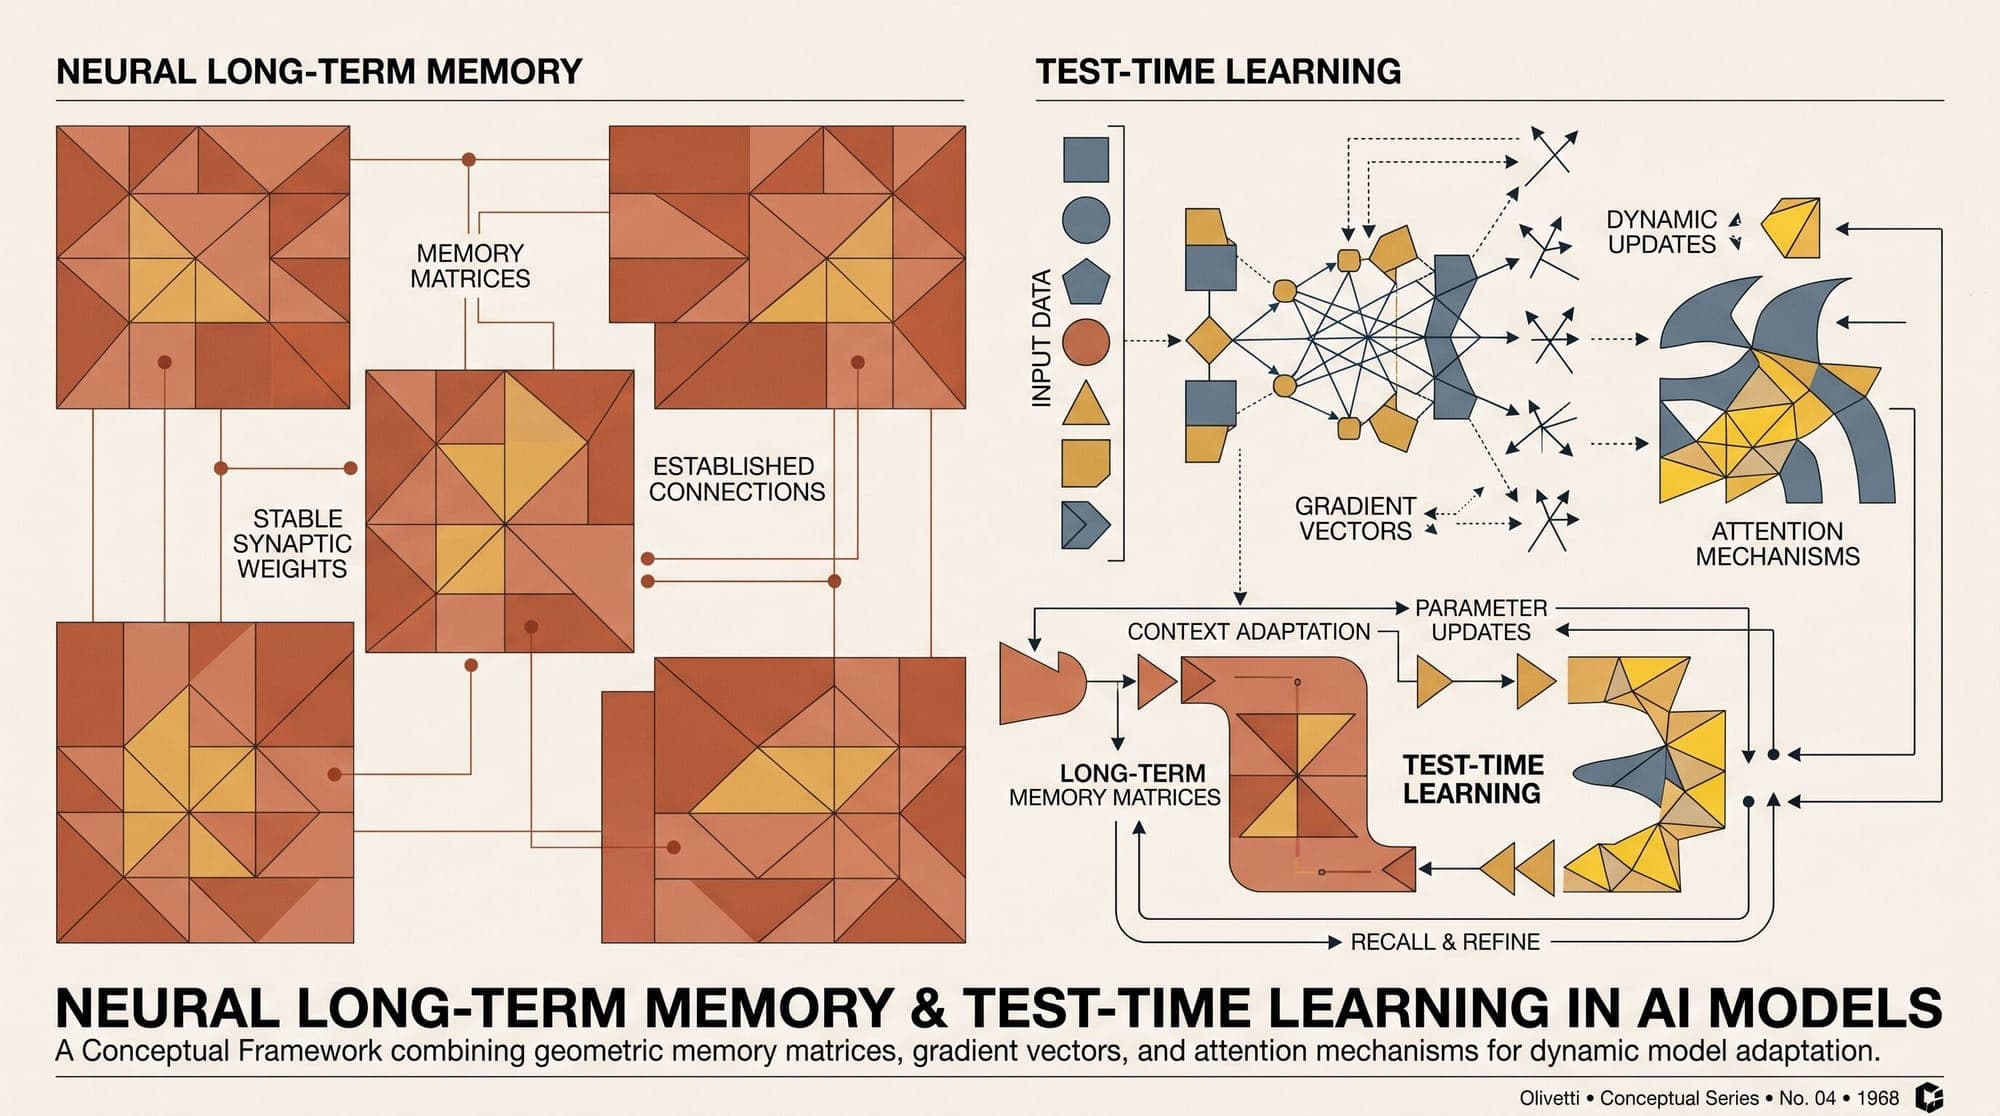
  6. Titans: Learning to Memorize at Test Time — Mathematical Foundations of Neural Long-Term Memory, Surprise-Driven Gradient Updates, Adaptive Forgetting, and Context Scaling

    Sequence modeling in large language models has long been caught in a fundamental trade-off between attention mechanisms and recurrent architectures. Softmax attention provides precise associative recall over all tokens in the active context window, but incurs quadratic computational and memory complexity, $O(N^2)$, with respect to sequence length $N$. Conversely, linear recurrent models, such as State Space Models (Mamba, Mamba-2) and linear Transformers (GLA, RetNet, DeltaNet), compress sequenc

    AI
    8 min read
  7. Open-Source Video Diffusion Models in Production: Comparing HunyuanVideo, CogVideoX, Mochi 1, and LTX-Video

    Generating temporally coherent, high-resolution video from natural language prompts has transitioned from UNet-based frame interpolation pipelines to scalable Diffusion Transformers (DiT) operating over compressed spatiotemporal latent spaces. The release of open-weight video foundation models has established production-viable alternatives to proprietary commercial APIs. However, engineering teams deploying video generation pipelines face stark trade-offs across transformer parameter scaling, 3D

    AI
    7 min read
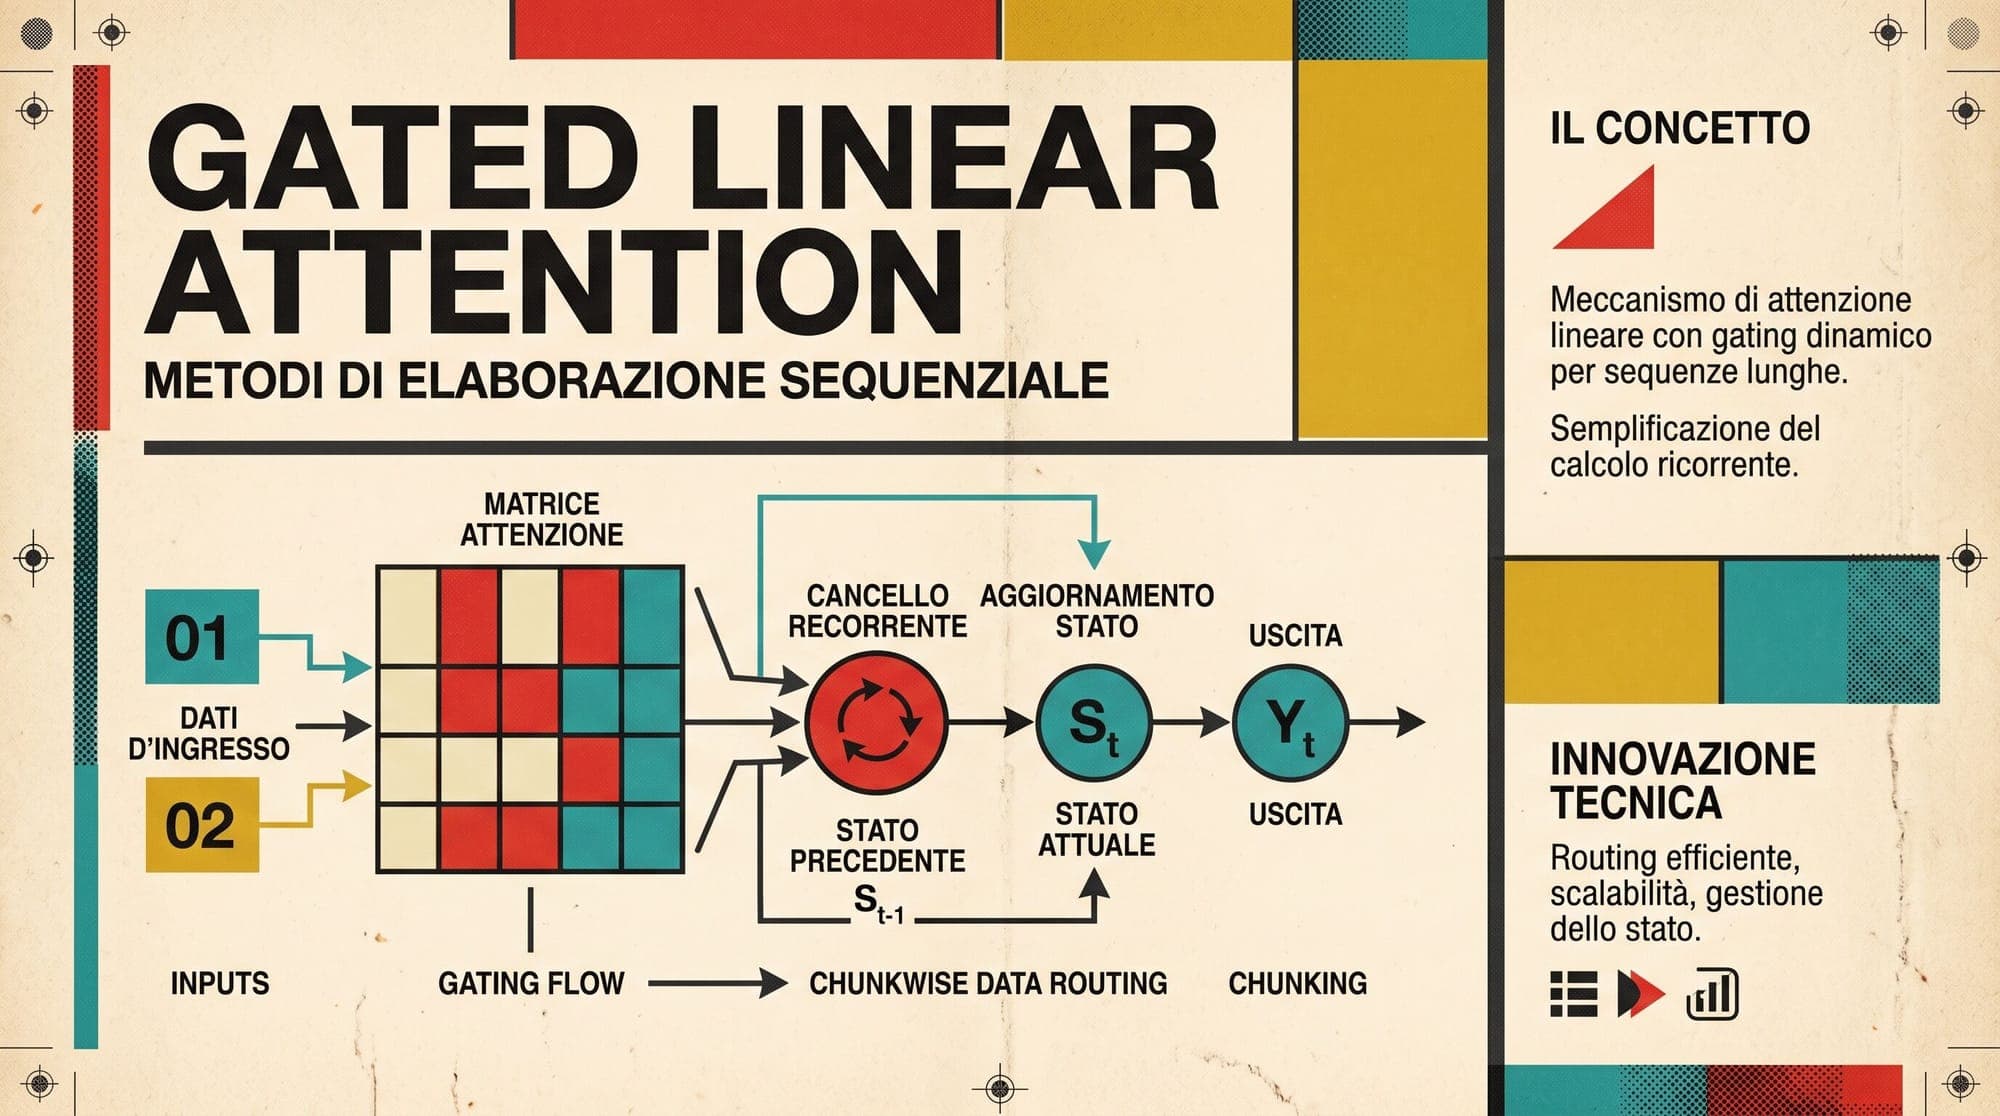
  8. Gated Linear Attention (GLA): Mathematical Foundations, Data-Dependent Gating, Chunkwise Parallel Forms, and Sub-Quadratic Sequence Modeling

    Standard Transformer architectures rely on softmax self-attention, which exhibits quadratic time and memory complexity $O(N^2)$ with respect to sequence length $N$. While FlashAttention and its successors optimize memory access patterns to execute exact softmax attention efficiently within GPU SRAM, the fundamental quadratic compute barrier remains. Moreover, autoregressive generation requires maintaining a Key-Value (KV) cache that grows linearly with sequence length, creating a memory capacity

    AI
    9 min read
  9. Open-Source Text-to-Image Diffusion Models in Production: Comparing FLUX.1, Stable Diffusion 3.5, PixArt-Sigma, and Sana

    Production deployments of text-to-image generative systems have undergone a structural transition over the past two years. The classical convolutional U-Net architectures that powered Stable Diffusion 1.5 and Stable Diffusion XL have largely been superseded by transformer-based backbones. Modern open-weight models rely on Diffusion Transformers (DiT), Multimodal Diffusion Transformers (MMDiT), Linear DiTs, and Flow Matching formulations. Choosing an open-source text-to-image foundation model fo

    AI
    8 min read
  10. Self-Taught Reasoner (STaR) and Quiet-STaR: Mathematical Foundations, Rationalization Dynamics, and Bootstrapped Reasoning in Large Language Models

    Self-Taught Reasoner (STaR) and Quiet-STaR: Mathematical Foundations, Rationalization Dynamics, and Bootstrapped Reasoning in Large Language Models Chain-of-thought prompting enables autoregressive transformers to solve multi-step arithmetic, symbolic logic, and commonsense reasoning tasks by emitting intermediate tokens before generating a final answer. However, scaling chain-of-thought capabilities faces a fundamental data bottleneck: supervised datasets of high-quality, human-annotated reaso

    AI
    9 min read
  11. Prompt Injection Detection and Jailbreak Defense Frameworks in Production: Comparing Rebuff, Vigil, LLM Guard, and Meta Prompt Guard

    Prompt injection remains one of the primary operational vulnerabilities facing production Large Language Model (LLM) deployments. As systems expand from isolated chat interfaces into autonomous agents with access to databases, web browsing, APIs, and file systems, the blast radius of an unmitigated injection attack shifts from offensive output generation to unauthorized tool invocation and systemic data exfiltration. Standard input sanitization methods developed for traditional software enginee

    Security
    6 min read
  12. Chinese Mathematicians Prove 3D Ghys Conjecture Using Shanghai AI Lab's Shusheng-S2 and Lean Verification

    A research team led by mathematicians from Great Bay University and the Shanghai Artificial Intelligence Laboratory has published a complete proof of the three-dimensional Ghys conjecture, resolving a 31-year-old open problem in dynamical systems. The proof relied on Shanghai AI Lab's Shusheng-S2 multimodal scientific foundation model to explore deduction pathways, followed by formal computer verification in the Lean proof assistant conducted by researchers at Peking University. The achievement

    AI
    3 min read
  13. Open-Source Function-Calling Models in Production: Comparing Gorilla OpenFunctions-v2, Hermes 3, Functionary, and xLAM

    Deploying autonomous AI agents and automated API workflows requires reliable structured output generation and tool invocation. While general-purpose language models can be prompted to output JSON tool invocations, specialized function-calling fine-tunes provide higher schema compliance, lower parameter hallucination rates, and support for parallel tool invocation. Four open-source model families have emerged as prominent architectures for local and private function calling: Gorilla OpenFunction

    AI
    4 min read
  14. Google Releases Harness² for Recursive Agent Harnessing Without Model Retraining

    Google Cloud AI Research has open-sourced Harness², a framework designed to automate the recursive self-improvement of AI agent scaffolding without modifying underlying model weights. Released under the Apache-2.0 license, the repository provides tools to optimize prompts, tools, memory, skills, and orchestration across open-world tasks where no ground-truth answer keys or verifiers exist. Decoupling Agent Scaffolding from Model Weights An autonomous agent's performance depends heavily on its

    AI
    3 min read
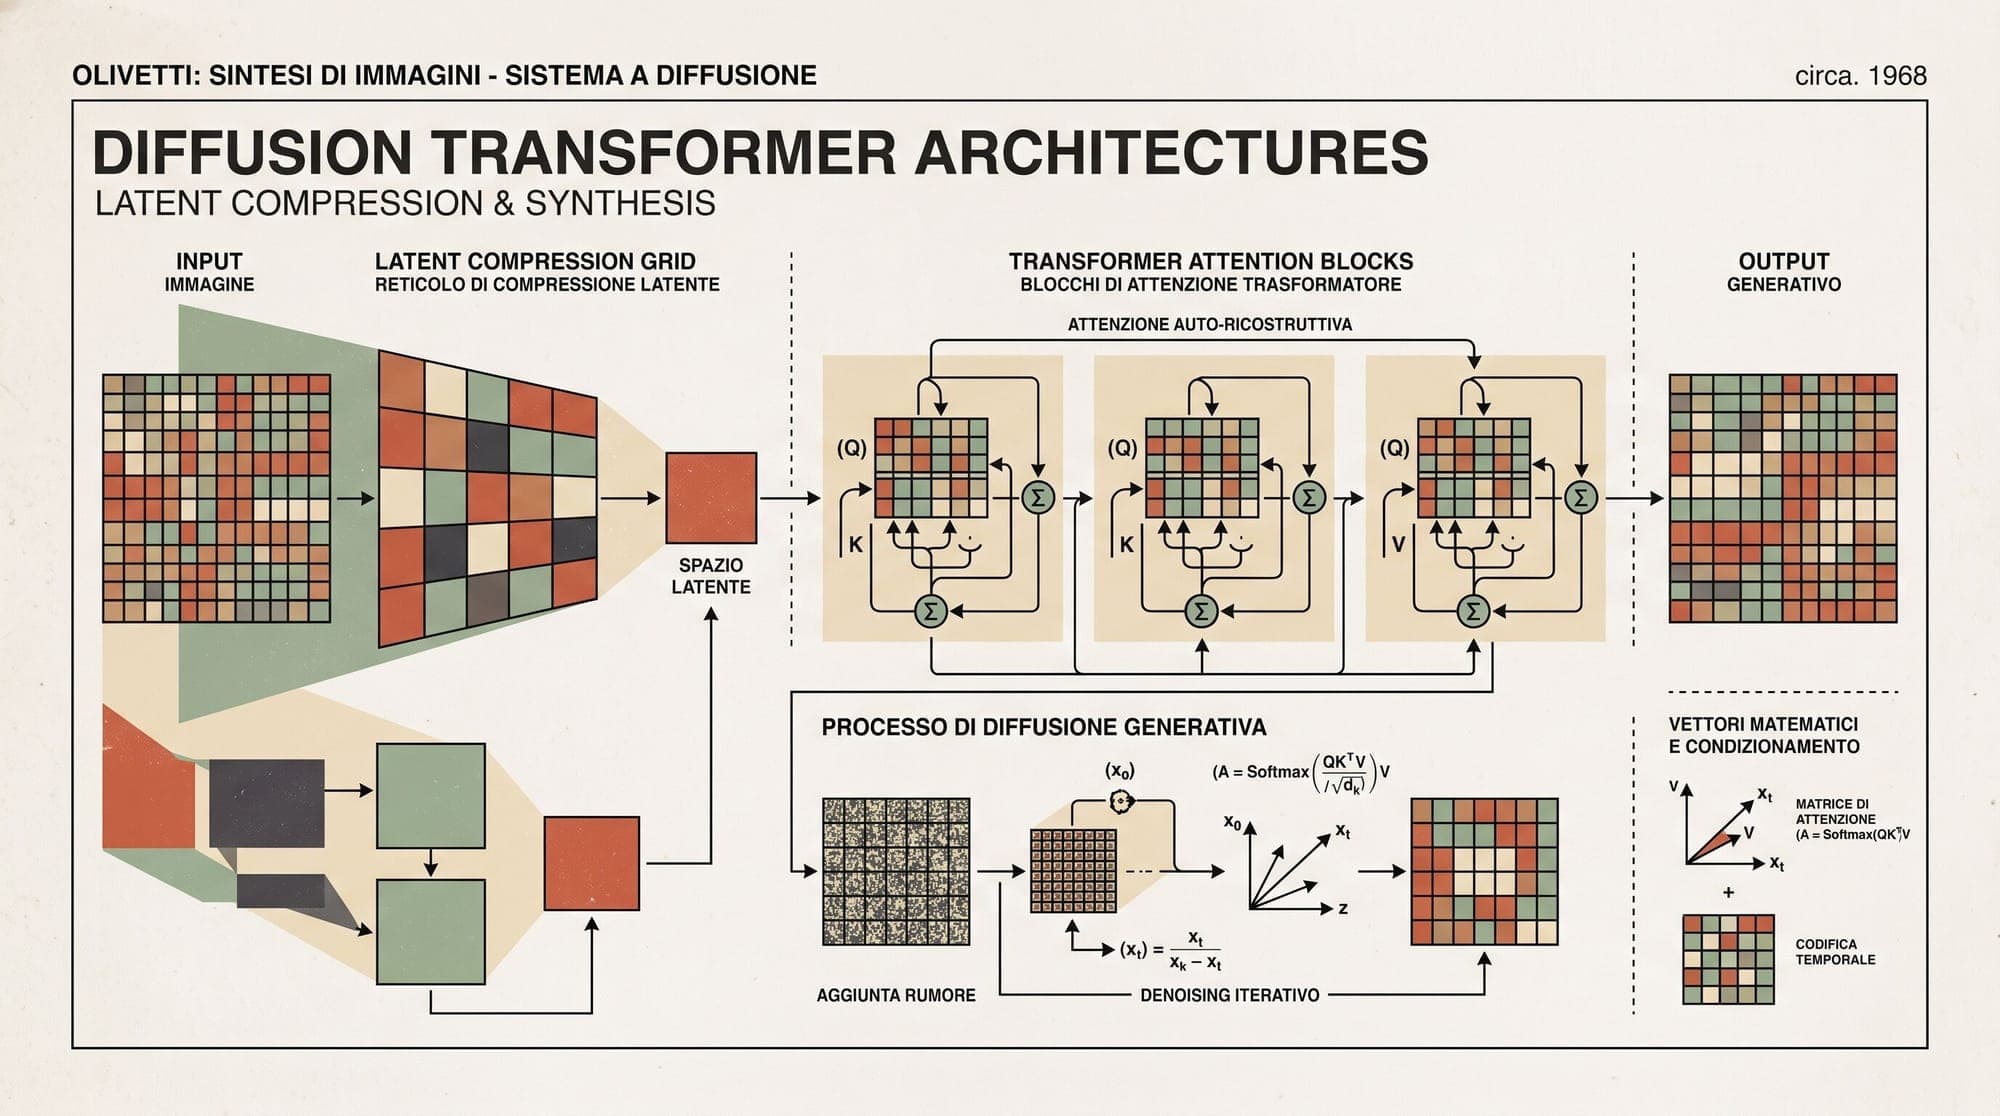
  15. Diffusion Transformers (DiT): Mathematical Foundations, Patchification, Adaptive LayerNorm (adaLN-Zero), and Latent Diffusion Scaling

    Diffusion Transformers (DiT), introduced by William Peebles and Saining Xie in their 2023 paper Scalable Diffusion Models with Transformers, established a structural departure in generative visual modeling. For years, diffusion pipelines relied almost exclusively on convolutional U-Net backbones derived from Denoising Diffusion Probabilistic Models (DDPM) and Latent Diffusion Models (LDM). DiT replaced these multi-scale convolutional networks with standard isotropic Transformer architectures ope

    AI
    5 min read
  16. Open-Source Safety and Moderation Classifiers in Production: Comparing Llama Guard 3, ShieldGemma, WildGuard, and Prompt-Guard

    Production large language model (LLM) applications require structured defenses against adversarial jailbreaks, prompt injections, and policy-violating content. While guardrail orchestration frameworks handle workflow logic, the actual enforcement decisions rely on specialized safety classifier models. Open-source safety classifiers have diverged into distinct architectural paradigms, ranging from lightweight bidirectional encoders to full autoregressive decoders and multi-task refusal evaluator

    AI
    5 min read