Who Is Colette Kress, Nvidia's Interim CEO?
After Jensen Huang resigned, Nvidia's board named CFO Colette Kress interim CEO, an 8-K says. Here is her finance record and what the filing says.
News on Nvidia's AI chips, models, deals and finances. Recent stories cover the Nemotron 3.5 Super VL model, Samsung making NVHBM base dies on TSMC 3nm, GPU financing deals, and Nvidia's agreement to acquire Hugging Face.
After Jensen Huang resigned, Nvidia's board named CFO Colette Kress interim CEO, an 8-K says. Here is her finance record and what the filing says.
What people are saying about Jensen Huang's resignation as Nvidia CEO, with links to each post. Nvidia has not given a reason.
Nvidia's board says Jensen Huang has resigned as CEO, effective immediately. CFO Colette Kress is interim CEO and Harvey Jones is the first board chair.
NVIDIA gave OpenShell, its open source runtime that sandboxes AI agents and enforces what they can touch, to the CNCF as a Sandbox project at KubeCon.
Update, Nov. 12, 2026: Nvidia says Jensen Huang resigned as CEO, effective immediately. CFO Colette Kress is interim CEO. The Nov. 11 reports are below.
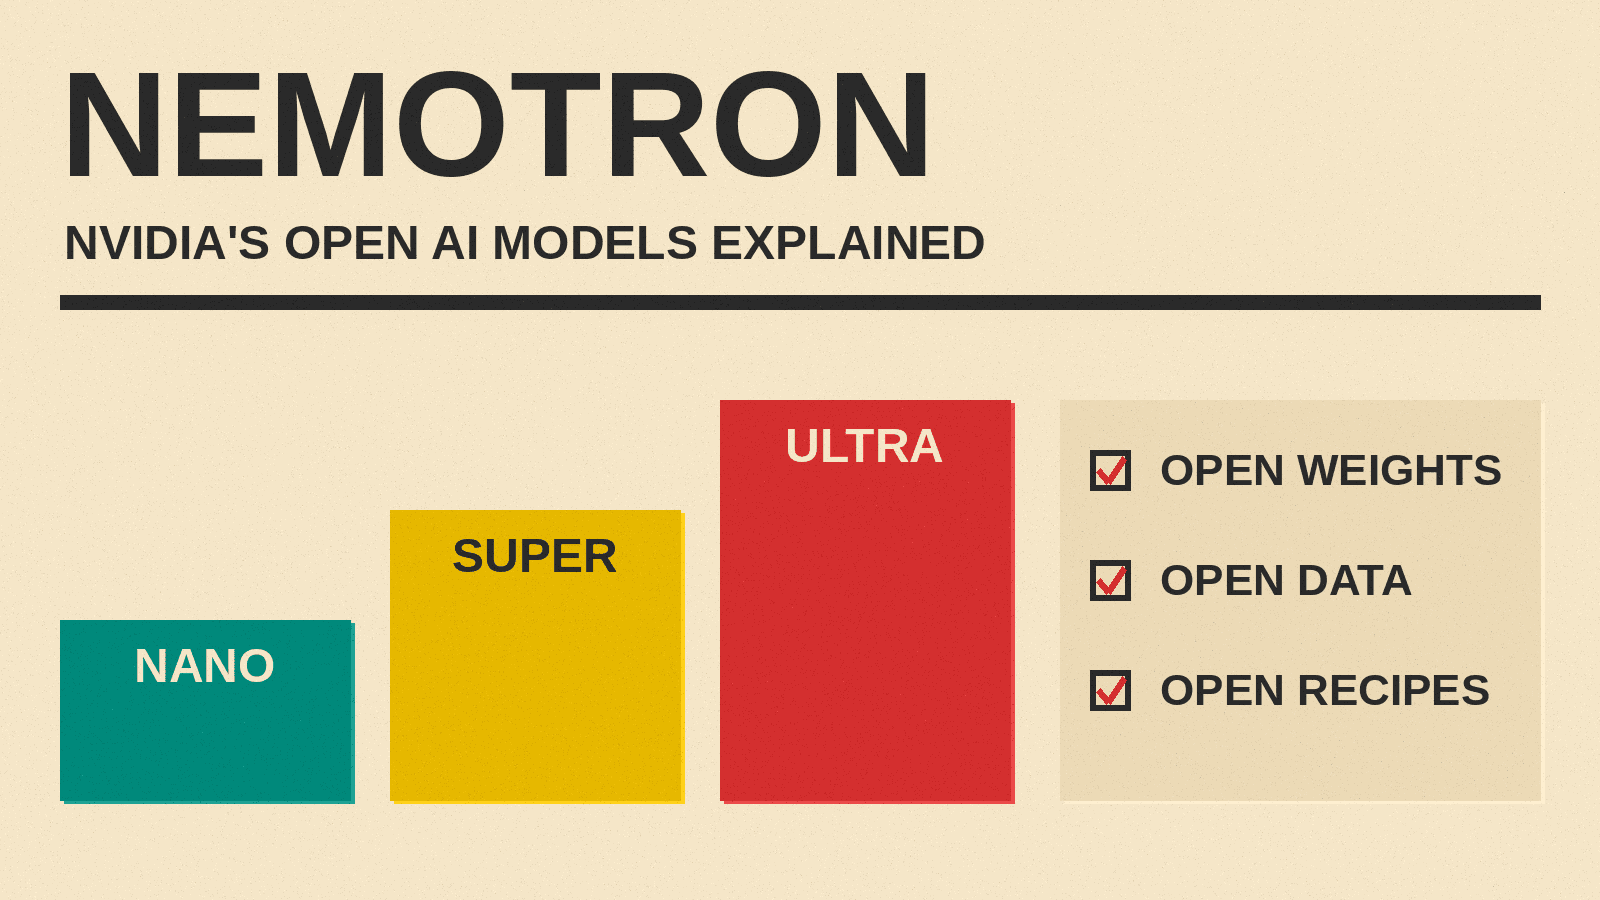
Nemotron is NVIDIA's family of open models for AI agents. See the Nano, Super and Ultra tiers, the open training data NVIDIA shares, and the license terms.
Nvidia shares fell Monday after its board opened a probe into reports that CEO Jensen Huang was a foreign-intelligence target. No charges have been announced.
Nvidia GPUs will run prefill and Rebellions' R200 NPUs will run decode in SK Telecom racks linked by NVLink Fusion. R200 systems are expected in 2028.
Nvidia's board opened a probe into reports that CEO Jensen Huang was a foreign-intelligence target. Huang admitted an affair and says he will cooperate.
Nvidia's Nemotron 3.5 Bolt 74B-A9B packs a model compressed from Super VL into 24GB with 2-bit experts for RTX Spark and DGX Spark. Here is what it needs to run, how its speed compares in Nvidia's own tests, and when Bolt E4B arrives.
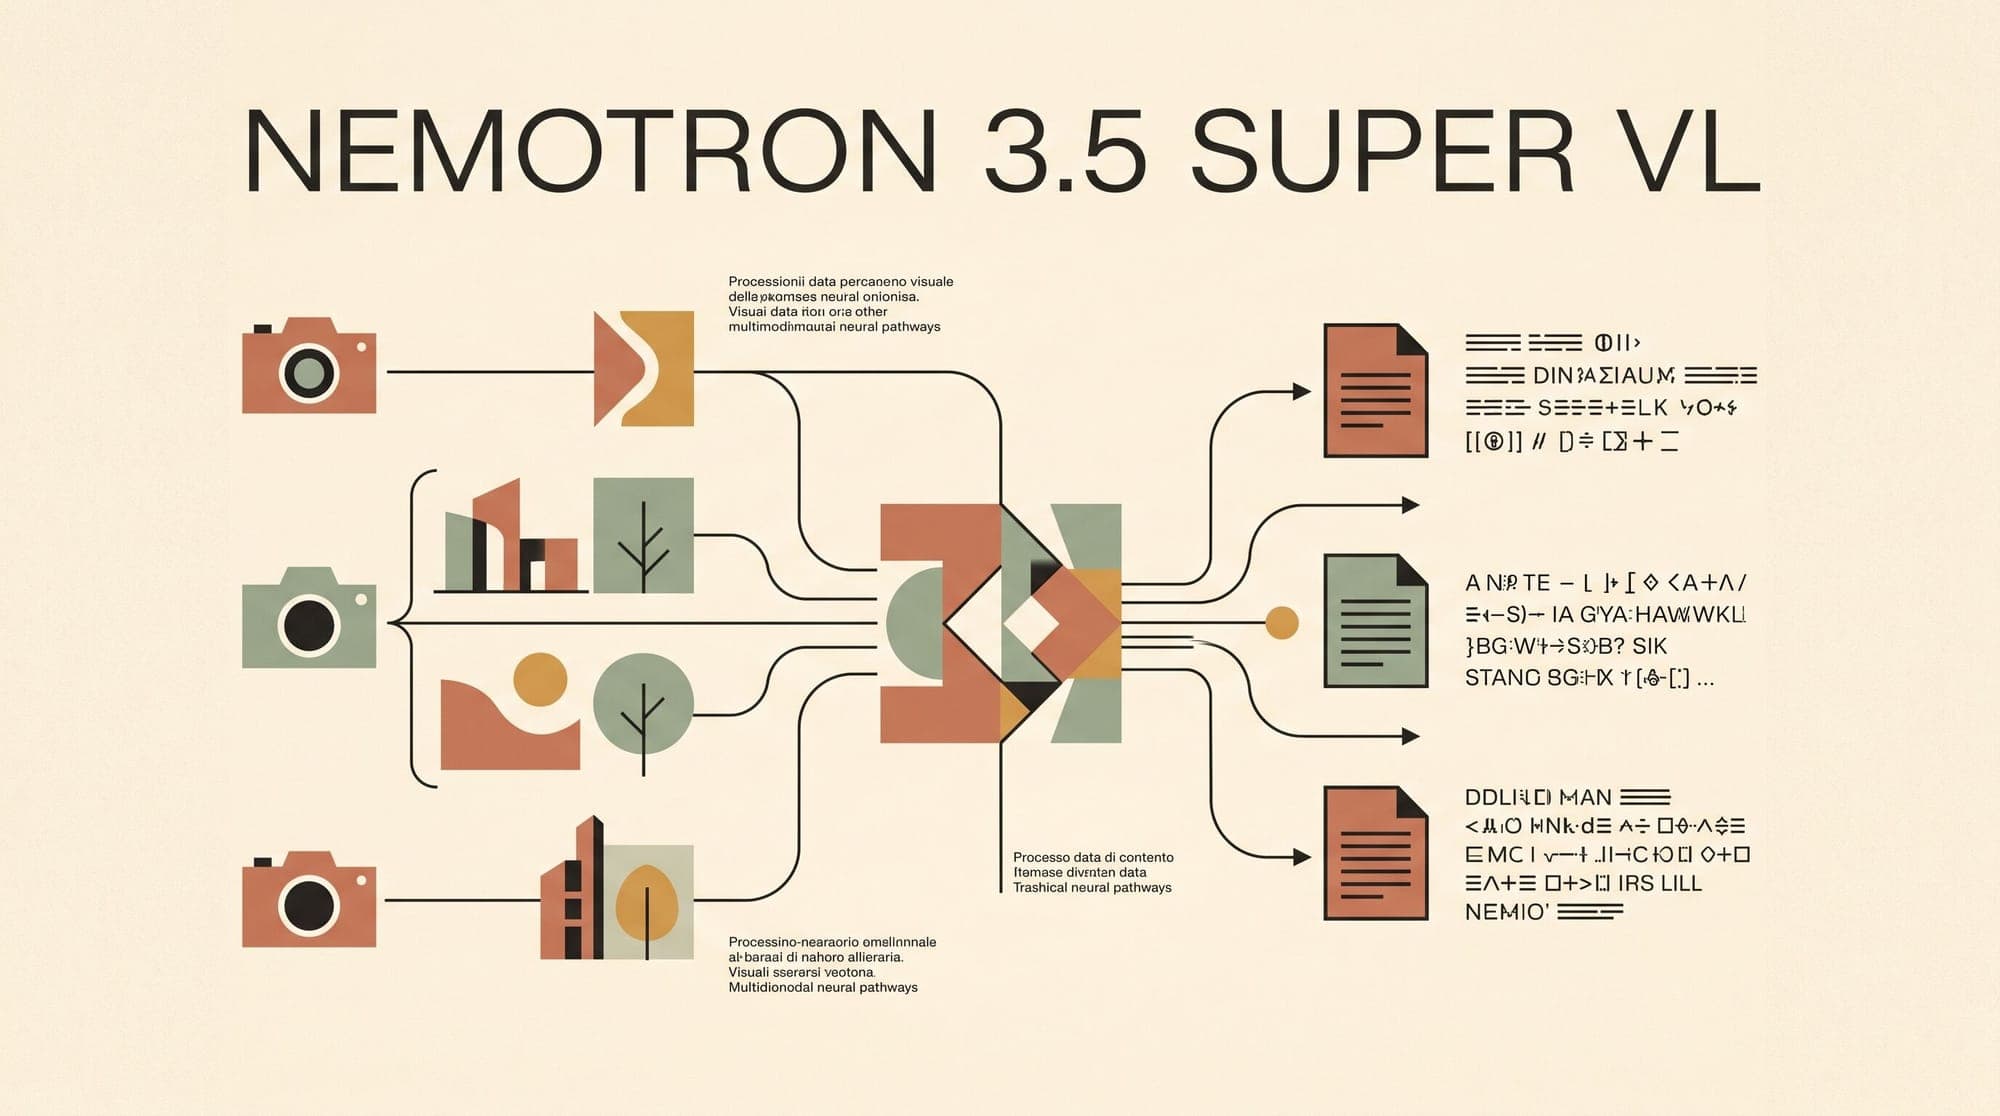
NVIDIA has released Nemotron 3.5 Super VL, an open-weights vision-language model designed for complex agentic workflows. The model features a 120-billion-parameter mixture-of-experts (MoE) architecture that activates 12 billion parameters per token, paired with a context window supporting up to 1 million tokens. NVIDIA announced it alongside Nemotron 3.5 Bolt, a 2-bit model for local agents on RTX Spark PCs. The release is available on Hugging Face in full-precision BF16 reference weights and q
Microsoft pulled out of Nscale's planned Loughton, Essex data center, which was to hold 23,040 Nvidia GPUs. The Guardian cites power supply concerns.
Blue Owl-led funds back a $2.4B, 9.0% fixed-rate GPU loan for IREN's Mackenzie campus. How it works, and why it costs more than IREN's Microsoft loan.
AI cloud infrastructure provider Lambda has secured $1 billion in private, short-dated debt to purchase Nvidia GPU clusters that will be leased directly to Microsoft. The transaction, arranged by JPMorgan Chase, highlights an accelerating shift across the AI infrastructure sector toward structured debt and asset-backed financing to fund capital-intensive data center hardware. The short-dated maturity structure indicates that Lambda plans to amortize the debt rapidly using contracted lease reven
Nvidia has paused select partnership deals under its newly introduced AI cloud financing initiative, according to reporting by The Wall Street Journal. The program, unveiled in July 2026, was designed to provide credit support and hardware access to emerging cloud computing providers in exchange for a percentage of future recurring revenues. While Nvidia stated that the broader program remains operational, several individual agreements have been put on hold as the company reassesses customer te
Nvidia has significantly expanded its forward supply chain obligations, reporting total component and manufacturing capacity commitments of $279 billion in its fiscal second-quarter disclosures. The figure marks a 134 percent sequential increase from $119 billion reported in the preceding quarter and $95.2 billion at the close of fiscal 2026. The multi-year commitments reflect efforts to secure critical semiconductor fabrication, advanced packaging, and high-bandwidth memory (HBM) capacity nece
Zhipu's GLM-5.3-Flash Runs Fully on Domestic Chinese Chips, Challenges NVIDIA Dominance Zhipu AI's GLM-5.3-Flash model, initially released as the mysterious "Niu Lai" (Ox Alpha) model, has been confirmed to run entirely on domestically produced Chinese accelerator chips, marking a significant milestone in China's AI self-sufficiency efforts. The 320B parameter mixture-of-experts model activates only 18B parameters and achieves performance comparable to Claude Opus 4.8 while operating at 1/40th
Nvidia has agreed to acquire Hugging Face for $12.9 billion, according to reporting from The Information. Parallel reports from Business Insider, Bloomberg, and Reuters confirm that the companies engaged in advanced acquisition negotiations valuing the open-source artificial intelligence hub between $12.9 billion and $13 billion. The transaction marks the largest software and developer platform acquisition in Nvidia's history, placing the primary distribution nexus for open-weight foundation mo
Amazon Web Services (AWS) and NVIDIA have announced a major expansion of their cloud infrastructure partnership, committing to deploy two million additional high-end NVIDIA GPUs across AWS global data centers in 2027 and 2028. The deployment expands on AWS's previous commitment from GTC 2026 to add one million GPUs starting in 2026, bringing total forward allocations across the multi-year cycle to three million units. The upcoming capacity will comprise NVIDIA Blackwell Ultra, Rubin, and Rubin
Indian AI infrastructure platform AM Intelligence (AMI) has placed a binding purchase order for 9,000 Nvidia Vera Rubin computing systems. The procurement represents one of the earliest hyperscale commitments for Nvidia's next-generation Rubin architecture across Asia and anchors an $8 billion capital expenditure initiative to build 1 gigawatt (GW) of dedicated AI computing capacity. The first phase of the deployment will take place at AMI's upcoming data center facility in Hyderabad, India. Th