Subscribe
Topic / page 4

Engineering

Articles, page 4

61-75
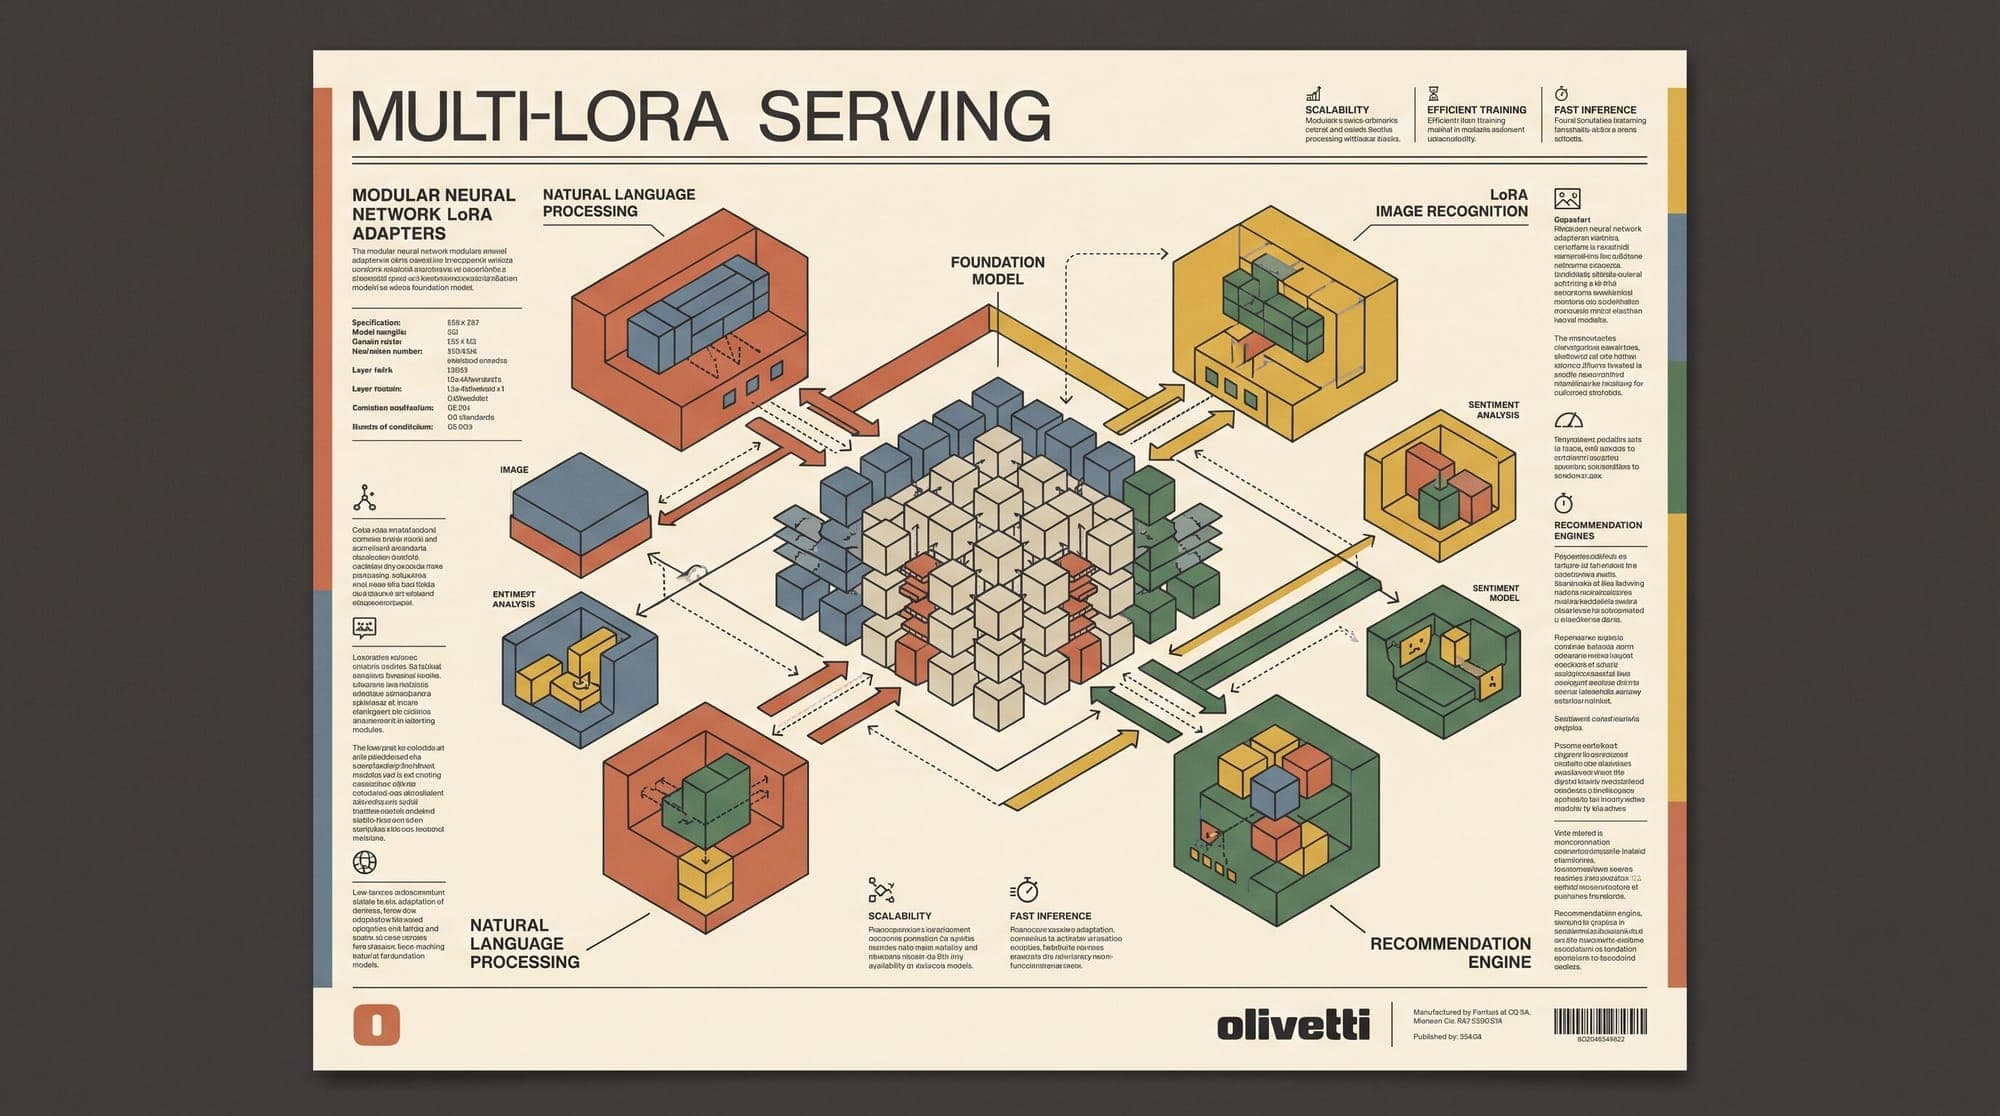
  1. Multi-LoRA Serving in Production: Architecture, Dynamic Adapter Swapping, and GPU Memory Management

    Deploying hundreds or thousands of fine-tuned language models across enterprise workflows presents a fundamental infrastructure dilemma. While parameter-efficient fine-tuning (PEFT) methods like Low-Rank Adaptation (LoRA) reduce training compute by freezing base model weights and training compact low-rank matrices, naive deployment strategies fail at scale. Merging adapter weights directly into the base model creates a distinct 7B to 70B parameter checkpoint for every specialized task, requiring
    AI
    8 min read
  2. Small Language Models in Production: Task Specialization, Serving Economics, and the Frontier Offloading Pattern

    The default architecture for first-generation enterprise AI agents routed every prompt, tool selection, and intermediate evaluation step to a single frontier large language model. While this monolithic approach simplified initial orchestration, it introduced severe latency bottlenecks and unsustainable inference unit economics in high-throughput production environments. In production agentic loops, between 40% and 70% of model invocations are narrow, highly structured operations: classifying in

    AI
    6 min read
  3. Semantic Routers in Production: Architecture, Embedding Classification vs. LLM Triage, and Cascade Topologies

    Routing user requests to specialized tools, APIs, or tiered foundation models is central to production AI architectures. However, relying on large language models (LLMs) or native JSON tool-calling mechanisms to perform initial intent classification introduces significant latency and cost overheads. A single LLM-based classification pass typically adds between 200 milliseconds and 1.5 seconds of time-to-first-token (TTFT) latency, alongside linear token billing for routine triage queries. To el

    AI
    5 min read
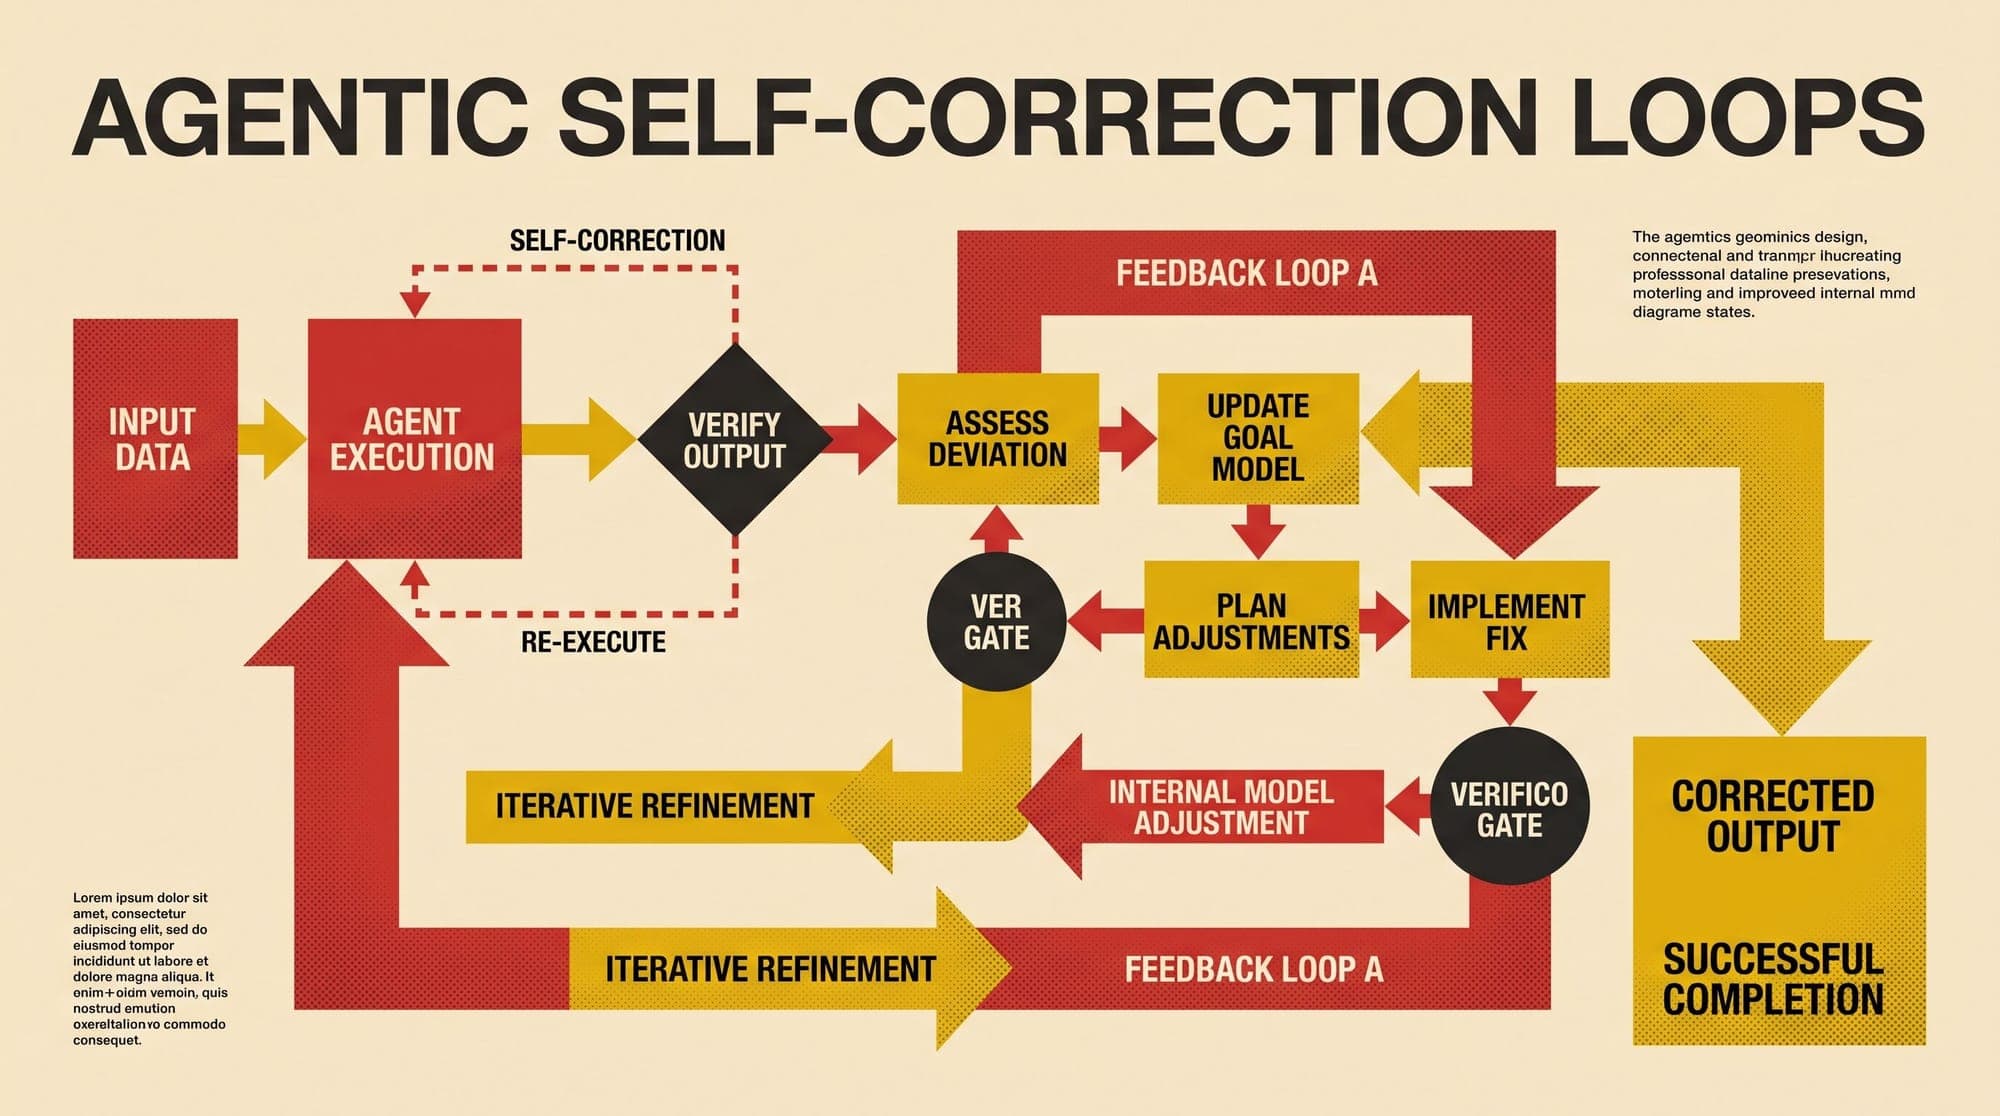
  4. Self-Correction and Reflection Loops in Production AI Agents: Architecture, Verification Oracles, and the Over-Correction Trap

    Autonomous AI agents frequently fail on initial generation when solving multi-step reasoning, code generation, and complex API orchestration tasks. To address initial execution failures, system architects widely deploy self-correction and reflection loops. However, the mechanism through which reflection operates determines whether a system converges on a valid solution or degrades into hallucinations and infinite loops. Recent research demonstrates a sharp division in reflection paradigms: whil

    AI
    6 min read
  5. LLM Streaming in Production: Server-Sent Events vs. WebSockets, Incomplete JSON Parsing, and Backpressure Architecture

    Token streaming is the primary user experience mechanism in generative AI applications. By piping generated tokens to the client as they leave the transformer layers rather than awaiting full sequence completion, systems dramatically reduce perceived latency from tens of seconds to sub-second time to first token (TTFT). However, moving from batch request-response models to long-lived streaming pipelines introduces brittle failure modes across the networking stack. In production, engineering tea

    AI
    7 min read
  6. Type-Safe LLM Interfaces in Production: Comparing BAML, Instructor, and PydanticAI

    Converting non-deterministic natural language into deterministic, typed data structures is a fundamental requirement of production AI engineering. While early implementations relied on string manipulation, regular expressions, or basic json.loads calls, modern production systems require strict type guarantees, schema validation, and predictable failure modes. Today, engineering teams face three distinct architectural paradigms for enforcing type safety across large language model (LLM) interfac

    AI
    7 min read
  7. Cloud Browser Infrastructure for AI Agents: Architecture, Anti-Bot Bypassing, Session State, and Fleet Scaling

    Autonomous AI agents require interactive web environments to navigate single-page applications, authenticate across complex portals, fill multi-step forms, and extract dynamic client-rendered data. However, running headless browsers at scale introduces severe operational bottlenecks. Ephemeral container instances (such as Docker containers or AWS Lambda functions) frequently suffer from cold starts, memory leaks, fingerprint leakage, and instant IP blacklisting by bot-detection networks. To sol

    AI
    6 min read
  8. Pipeline Parallelism in Large Language Models: How GPipe, 1F1B Scheduling, and Interleaving Tame Memory and Bubbles

    Training frontier large language models with tens or hundreds of billions of parameters exceeds the physical memory capacity of any individual GPU. While intra-node sharding strategies such as Tensor Parallelism partition individual matrix multiplications across accelerators over high-speed NVLink interconnects, scaling across multi-node clusters encounters strict hardware boundaries. Tensor Parallelism requires multiple collective All-Reduce communications per transformer layer. Across standar

    AI
    6 min read
  9. Document Parsing and Visual Retrieval for Production RAG: Architecture, Benchmarks, and Serving Trade-Offs for Docling, Marker, MinerU, and ColPali

    Document Parsing and Visual Retrieval for Production RAG: Architecture, Benchmarks, and Serving Trade-Offs for Docling, Marker, MinerU, and ColPali The retrieval quality of a Retrieval-Augmented Generation (RAG) system is strictly bounded by the fidelity of its document ingestion pipeline. In enterprise environments, the vast majority of domain knowledge remains locked in unstructured Portable Document Format (PDF) files, scanned reports, technical manuals, and multi-column research papers. Na

    RAG
    8 min read
  10. AI Guardrails in Production: Multi-Stage Filtering, Classification Models, and the Latency Tax

    AI Guardrails in Production: Multi-Stage Filtering, Classification Models, and the Latency Tax Production deployments of large language models cannot rely solely on system prompt instructions to maintain safety, prevent prompt injection, or restrict domain scope. System prompt alignment is inherently susceptible to adversarial bypasses, context dilution, and non-deterministic instruction following. To enforce strict security, compliance, and topic boundaries, engineering teams increasingly depl

    AI
    4 min read
  11. Multi-Head Latent Attention: How Low-Rank KV Compression Scales LLM Serving

    Autoregressive transformer inference faces a fundamental hardware constraint during text generation: memory bandwidth saturation. While prefill (processing prompt tokens) is compute-bound and saturates GPU tensor cores, token-by-token generation is memory-bandwidth bound. To generate each subsequent token, the inference engine must load all prior Key and Value vectors from High Bandwidth Memory (HBM) into SRAM. As sequence lengths reach 32k, 64k, or 128k tokens and batch sizes scale, the Key-Va

    AI
    6 min read
  12. LLM Gateways in Production: Multi-Provider Failover, Rate Limiting, and Spend Governance

    LLM Gateways in Production: Multi-Provider Failover, Rate Limiting, and Spend Governance As generative AI workloads transition from experimental prototypes to mission-critical infrastructure, direct client-to-provider API calls introduce substantial operational risk. Relying on hardcoded SDK connections to a single model provider exposes production services to unexpected rate limits, regional outages, silent breaking changes, and uncontrolled token costs. To solve these reliability and governa

    AI
    5 min read
  13. Multi-Agent Orchestration in Production: State Machines, Swarms, and Error Cascades

    Moving large language model applications from isolated prompts to multi-agent architectures introduces distinct systemic complexities. While single-agent systems face localized points of failure, multi-agent topologies exhibit emergent dynamics such as cascading hallucinations, coordination deadlocks, and severe context bloat. Designing multi-agent systems for production environments requires selecting explicit orchestration paradigms, bounding error propagation, and enforcing durable state per

    AI
    5 min read
  14. LLM Model Routing and Cascades: Architecture, Economics, and Quality Trade-Offs

    In modern enterprise AI systems, uniform model dispatch, sending all incoming user traffic to a single frontier large language model, is one of the most common architectural inefficiencies. Frontier models like GPT-4o and Claude 3.5 Sonnet provide industry-leading reasoning and code generation capabilities, but their inference costs range between $2.50 and $15.00 per million tokens. Conversely, smaller open-weights or distilled models, such as Llama 3.1 8B or GPT-4o-mini, execute at a fraction o

    AI
    6 min read
  15. Prompt Caching in Production: Architecture, Economics, and Invalidation Pitfalls

    As multi-turn AI agents, code generation assistants, and retrieval-augmented generation (RAG) pipelines expand in production, prompt sizes routinely exceed tens of thousands of tokens per request. In these architectures, the vast majority of tokens across consecutive API calls are static: system prompts, OpenAPI tool specifications, reference documents, and accumulated conversation history. Without optimization, inference engines must re-evaluate the full attention matrix for every token on eac

    AI
    5 min read