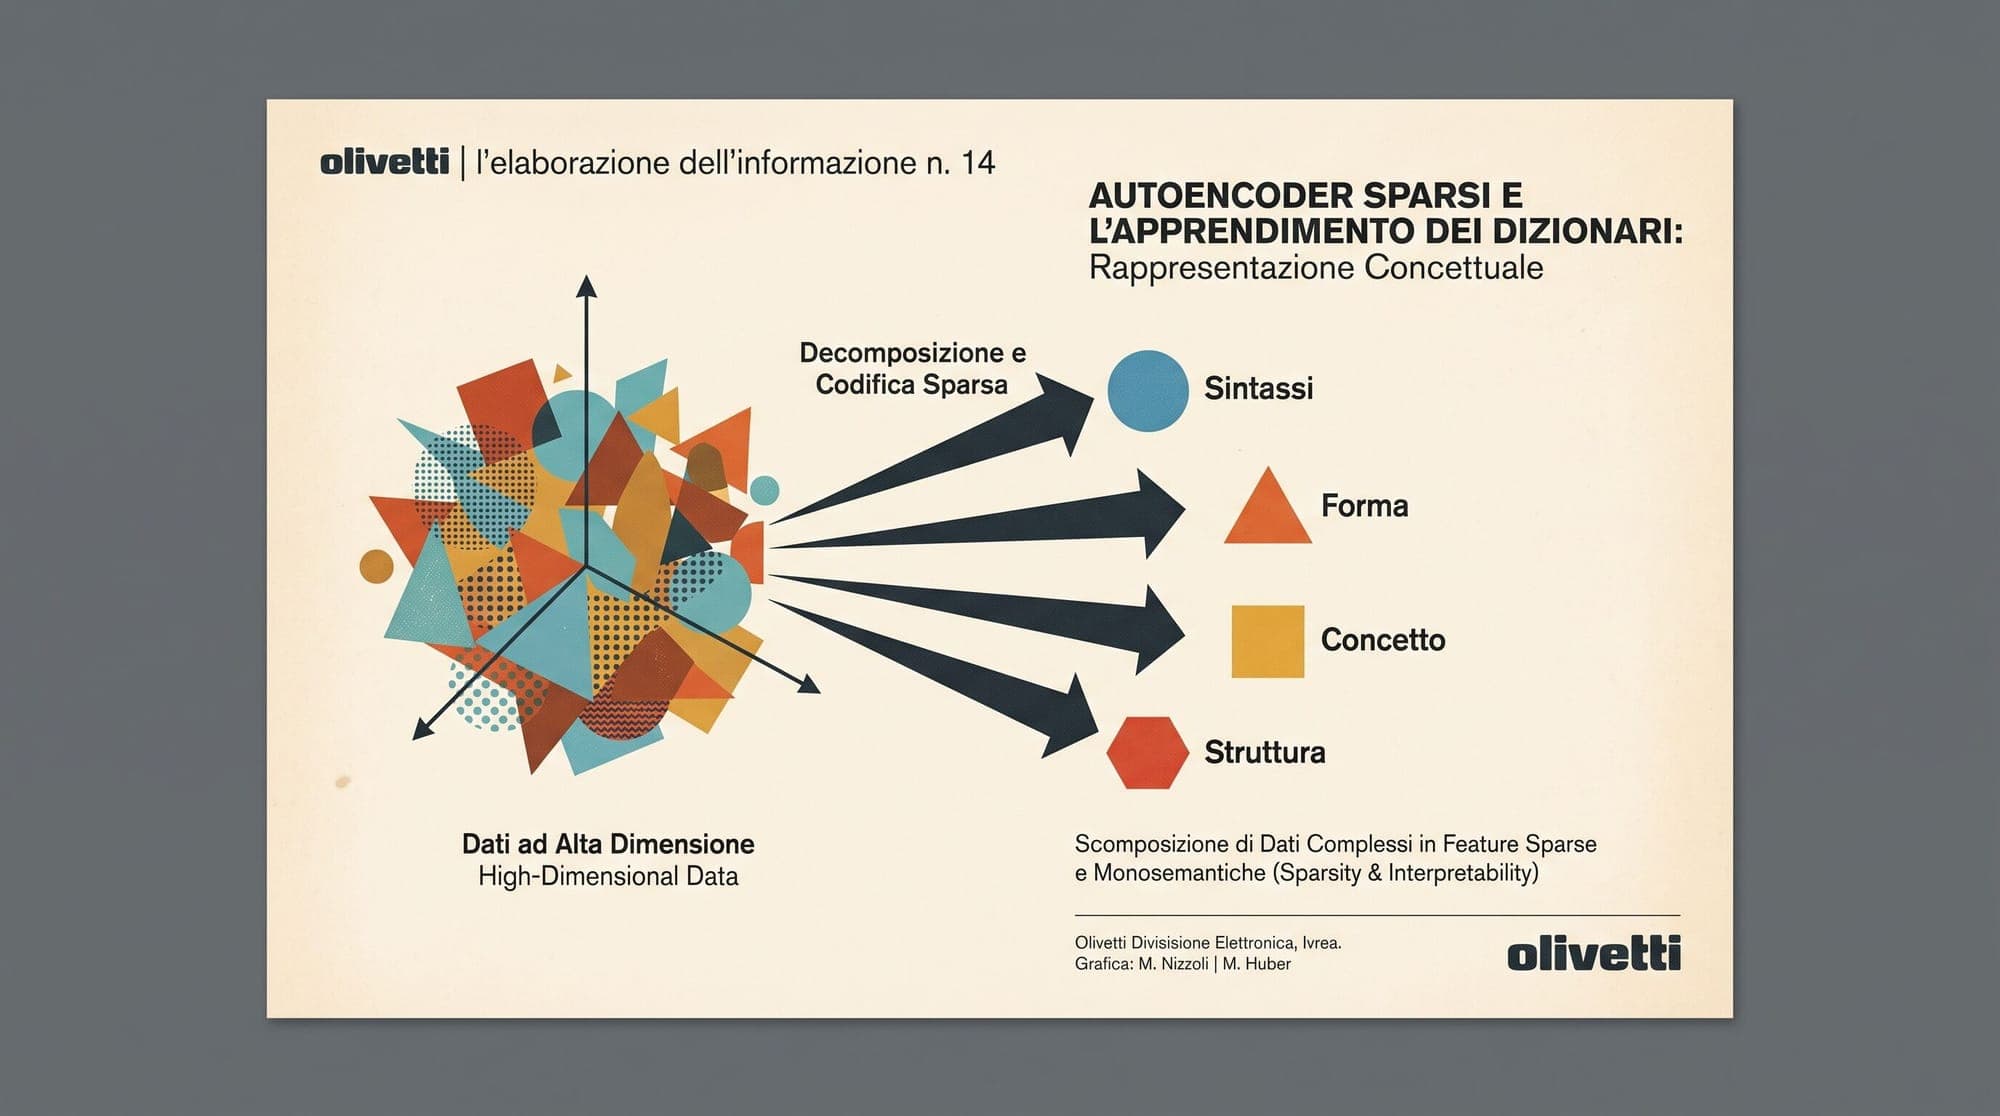
Sparse Autoencoders (SAEs) and Mechanistic Interpretability: Mathematical Foundations, Dictionary Learning, Top-K Sparsity, Feature Steering, and Monosemanticity
Modern autoregressive large language models represent a vast catalog of world concepts, syntactic rules, and abstract reasoning heuristics. However, inspecting the raw weight matrices and internal activation states of transformer networks reveals an obstinate barrier to mechanistic interpretability: individual neurons are notoriously polysemantic, firing across disjoint and unrelated semantic domains. This entanglement is explained by the superposition hypothesis (Elhage et al., 2022): neural n