Research / page 5

Research

470 articles

Articles, page 5

81-100 of 470
  1. Real-Time Voice AI Agent Frameworks in Production: Comparing LiveKit Agents, Pipecat, OpenAI Realtime API, and Ultravox

    Deploying conversational voice agents in production requires solving a fundamental physics and networking problem: human conversational turn-taking occurs within an average gap of 200 to 300 milliseconds. When an artificial conversational agent exceeds 600 to 800 milliseconds of round-trip latency, users perceive the interaction as sluggish, talk over the assistant, or experience severe turn collisions. Historically, conversational voice systems relied on sequential request-response architectur
    AI
    10 min read
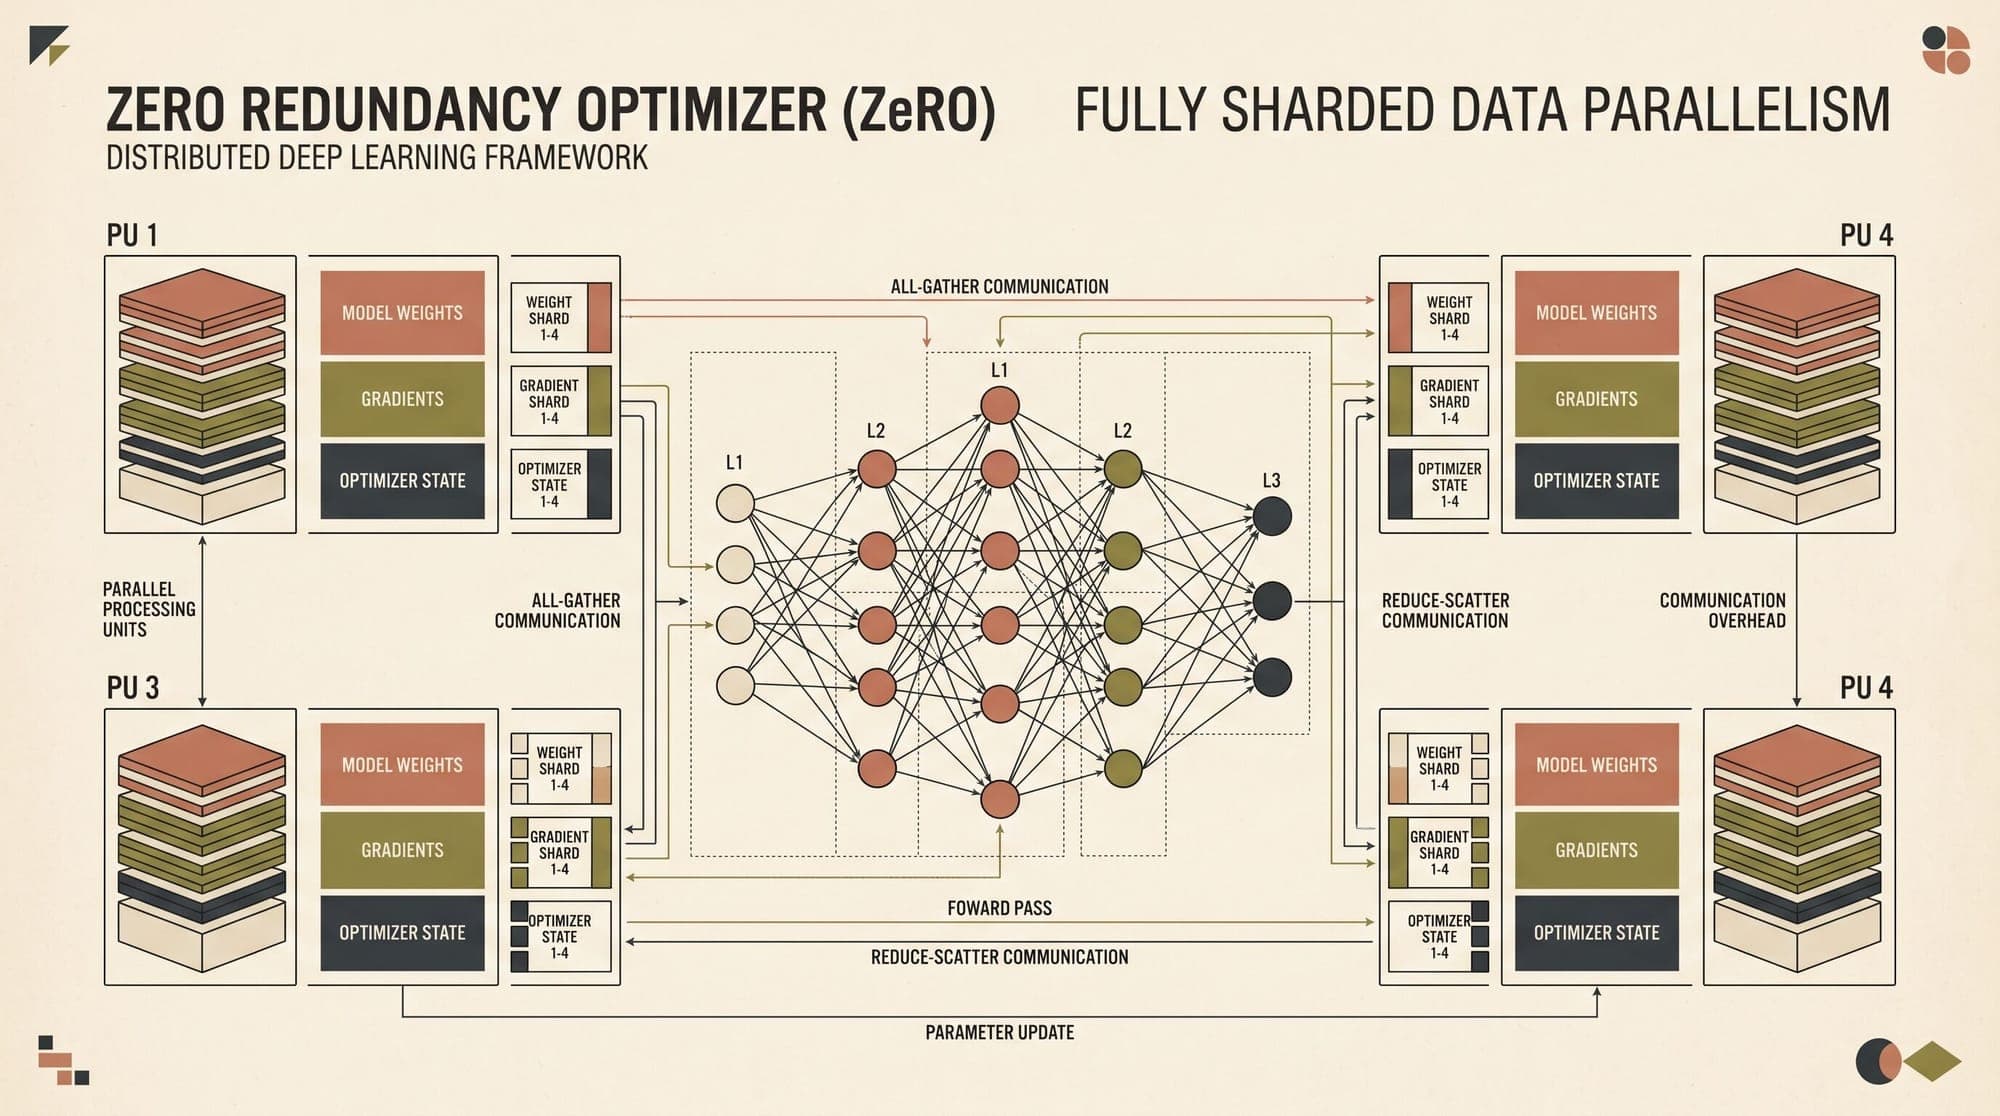
  2. Zero Redundancy Optimizer (ZeRO) and Fully Sharded Data Parallelism (FSDP): Mathematical Foundations of Memory Partitioning, Communication Complexity, and Overlapped Execution

    Training modern frontier large language models requires orchestrating compute across thousands of accelerators. As parameter counts scaled from billions to hundreds of billions, the memory capacity of single accelerators (such as 80 GB on an NVIDIA H100 or 96 GB on an H200) became a primary scaling bottleneck. Traditional distributed training paradigms relied on standard Data Parallelism (DDP), where every GPU maintains a complete replica of the model weights, gradients, and optimizer states, sy

    AI
    12 min read
  3. Semantic Caching Engines in Production LLM Systems: Comparing GPTCache, RedisVL, Portkey, and Cloudflare AI Gateway

    Semantic Caching Engines in Production LLM Systems: Comparing GPTCache, RedisVL, Portkey, and Cloudflare AI Gateway Standard exact-match caching strategies fail in large language model applications. Because natural language is inherently variable, users asking the exact same question will use different phrasing, punctuation, sentence structures, or synonyms. Exact string hashing (such as MD5 or SHA-256 caching over raw prompt strings) rarely yields hit rates above 3% to 5% in production convers

    AI
    10 min read
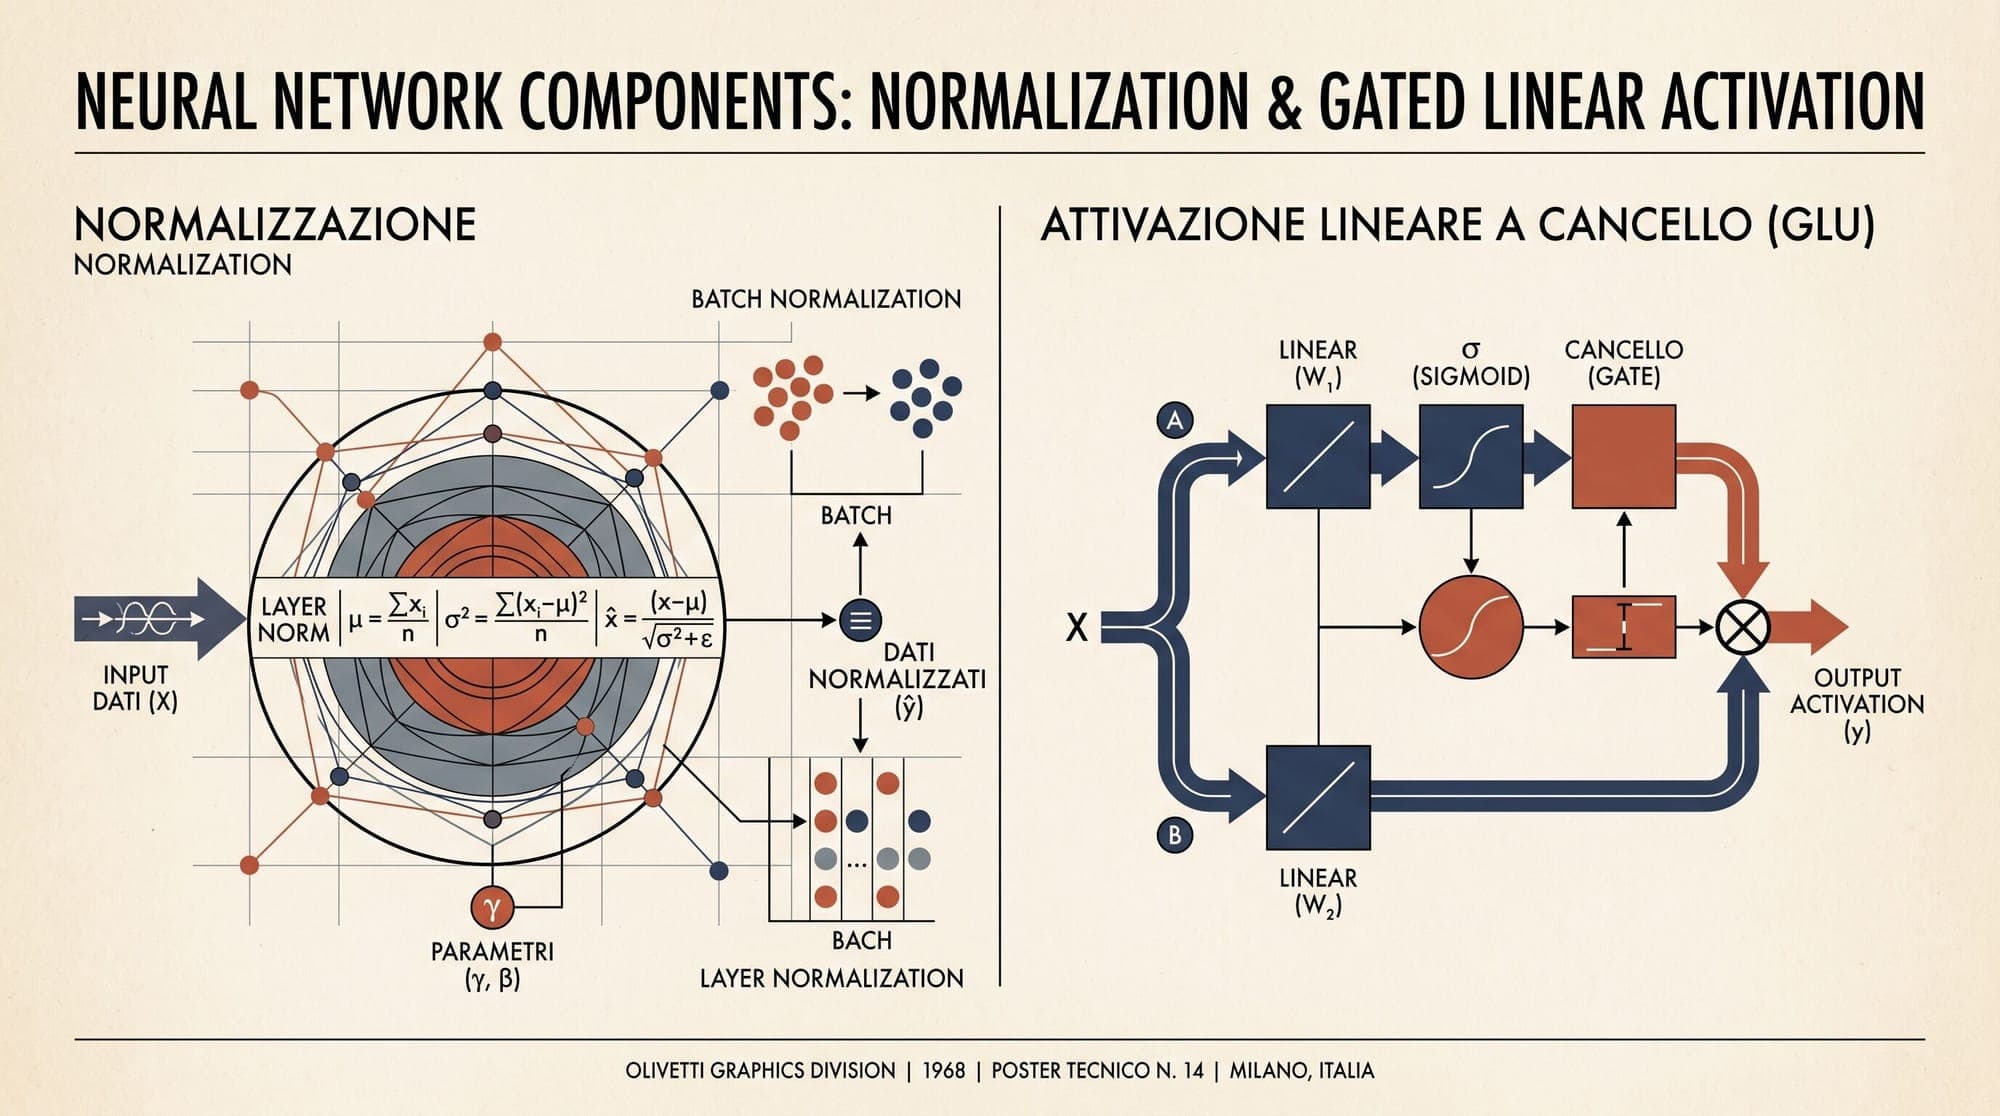
  4. RMSNorm and SwiGLU: Mathematical Foundations of Scaling-Invariant Normalization, Gated Activations, and FFN Architectures in Modern LLMs

    The architectural baseline of modern autoregressive large language models has converged on a distinct set of mathematical primitives. While early Transformer architectures relied on standard Layer Normalization, Post-LN residual routing, and two-layer Multi-Layer Perceptrons with ReLU or GELU activations, state-of-the-art open-weights models such as LLaMA, Mistral, Gemma, Qwen, and DeepSeek utilize a different combination: Root Mean Square Layer Normalization (RMSNorm), Pre-LN residual connectio

    AI
    10 min read
  5. Chunking Strategies in Production RAG: Comparing Fixed-Size, Semantic Chunking, Late Chunking, and Contextual Retrieval

    In production Retrieval-Augmented Generation (RAG) pipelines, the chunking strategy determines the theoretical ceiling of retrieval quality. Splitting documents into discrete text spans transforms continuous discourse into isolated segments. When chunks are indexed in isolation, critical context disappears: pronoun antecedents lose their referents, domain-specific acronyms lose their definitions, and propositions spanning arbitrary token boundaries become fragmented. Selecting an appropriate ch

    AI
    9 min read
  6. Matryoshka Representation Learning (MRL): Mathematical Foundations, Multi-Scale Loss Optimization, and Adaptive Vector Retrieval

    Matryoshka Representation Learning (MRL) has become the standard architectural foundation for modern dense text embeddings. Introduced by Kusupati et al. at NeurIPS 2022 and subsequently deployed across frontier embedding models like OpenAI text-embedding-3, Nomic Embed, and BAAI BGE-M3, MRL solves a structural inefficiency in vector retrieval: the rigid coupling between embedding dimensionality, memory consumption, and semantic fidelity. Traditional dense encoders project arbitrary text sequen

    AI
    9 min read
  7. Synthetic Data Generation and Data Curation Pipelines in Production: Comparing Distilabel, NVIDIA NeMo Curator, Data-Juicer, and InstructLab

    As frontier language models exhaust human-authored web text, pretraining and post-training performance increasingly depends on automated data curation and synthetic data synthesis. Unfiltered public corpora introduce duplicate content, synthetic artifacts, low-reasoning text, and licensing liabilities. Modern foundation models, including Meta's Llama 3.1, NVIDIA's Nemotron-4 340B, Alibaba's Qwen 2.5, and IBM's Granite, are trained on datasets where synthetic generation and rigorous multi-stage f

    Data Curation
    9 min read
  8. Tensor Parallelism and Pipeline Parallelism: Mathematical Foundations of Megatron-LM 1D Slicing, Sequence Parallelism, and 1F1B Scheduling

    Scaling modern large language models beyond tens of billions of parameters quickly exhausts the physical memory and compute throughput of individual graphics processing units. A 70-billion-parameter model stored in 16-bit floating-point (FP16 or BF16) requires 140 GB of VRAM solely for model weights. During full-precision training with the Adam optimizer, parameter states, gradients, and optimizer momentum terms demand approximately 16 to 18 bytes per parameter (amounting to 1.12 TB to 1.26 TB f

    AI
    10 min read
  9. Barret Zoph Joins Google as VP of Research to Lead Gemini Post-Training and Reinforcement Learning

    Barret Zoph, former post-training lead at OpenAI and co-founder of Thinking Machines Lab, has joined Google as Vice President of Research. Google confirmed the appointment, stating that Zoph will direct reinforcement learning (RL) and post-training initiatives across the Gemini model family. Background and Industry Trajectory Zoph previously spent several years at Google Brain, where he co-authored foundational papers on Neural Architecture Search (NAS) and scaling mixture-of-experts (MoE) ar

    Google
    1 min read
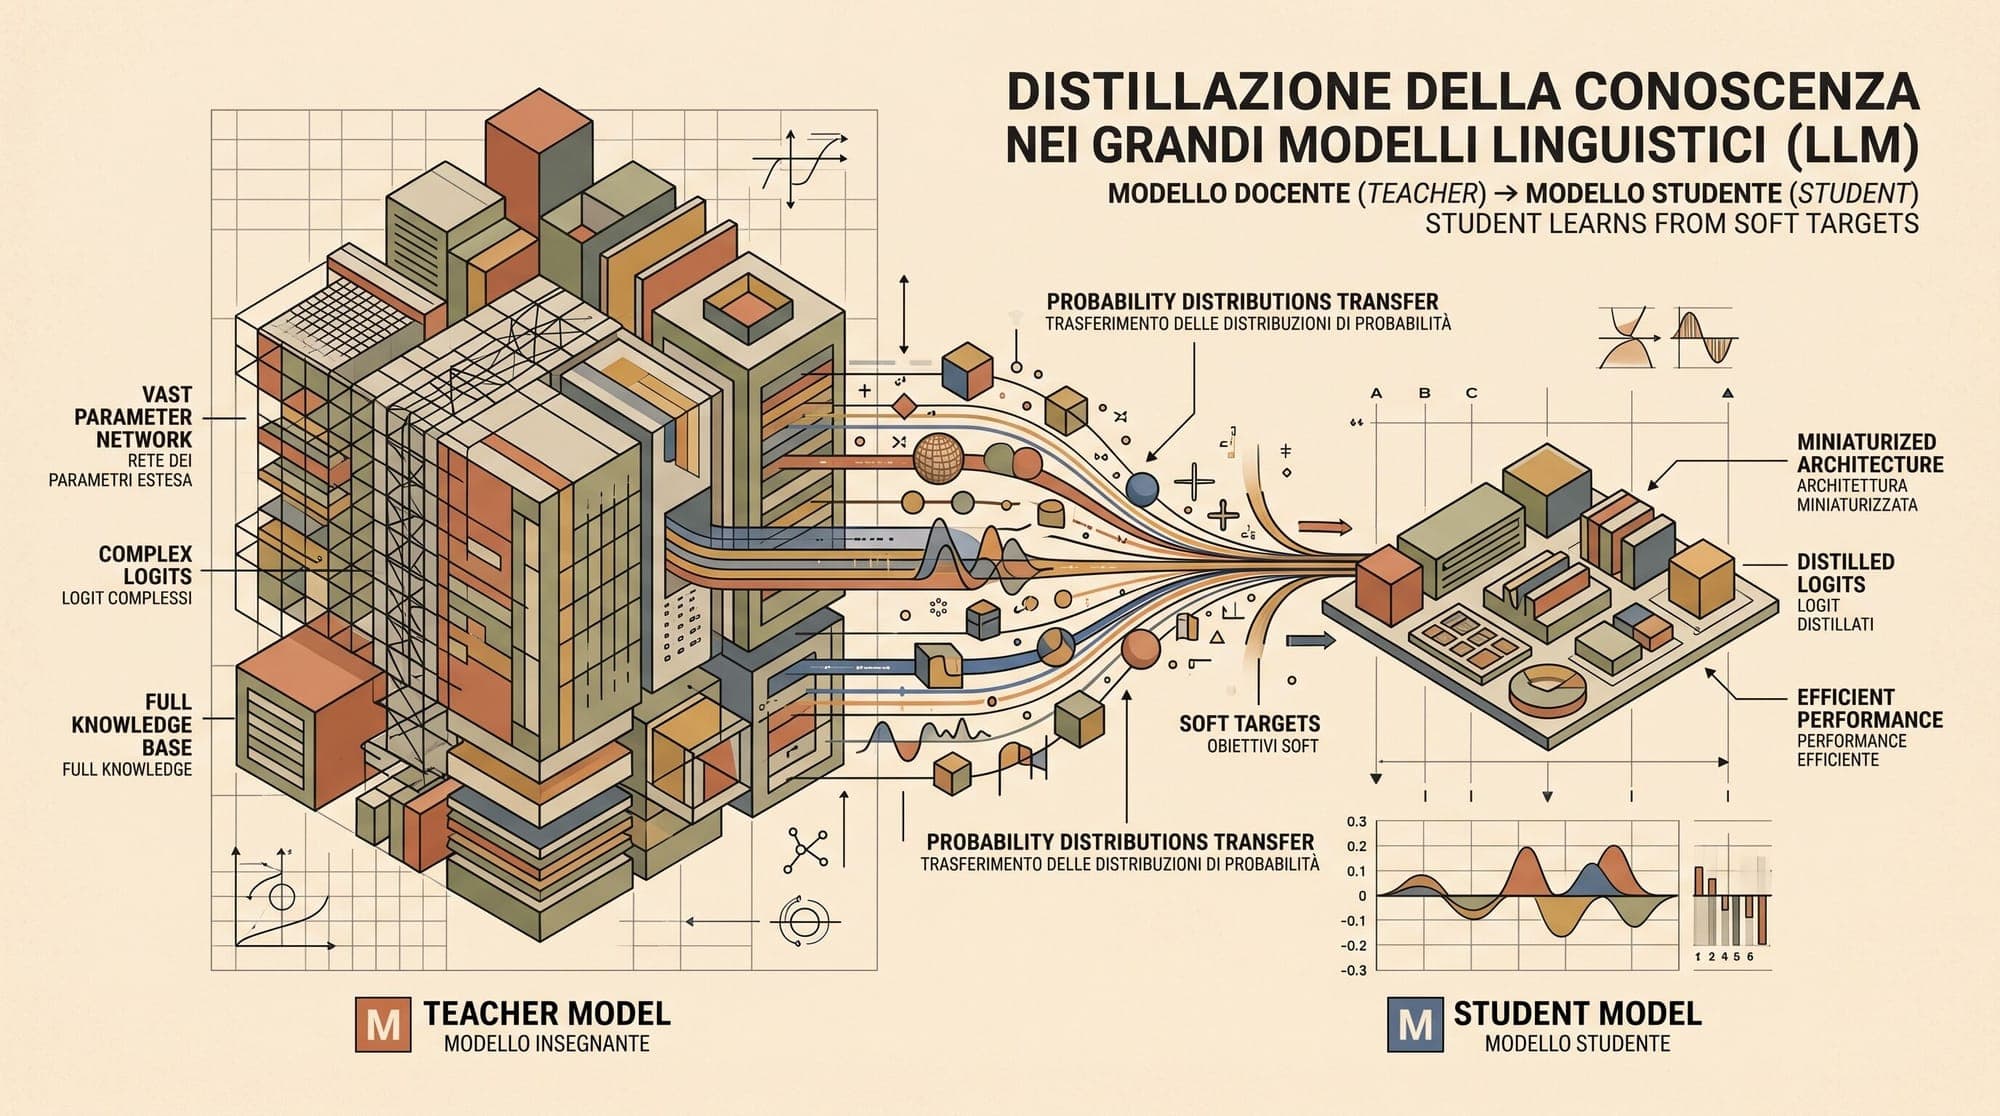
  10. Knowledge Distillation in Large Language Models: Mathematical Foundations of Forward vs. Reverse KL Divergence, Sequence-Level Distillation (SeqKD), and On-Policy Mode-Seeking Objectives

    Deploying frontier large language models in latency-critical and compute-constrained environments remains an active challenge in artificial intelligence systems. While parameter scale correlates directly with downstream generalization and emergent reasoning capabilities, the memory footprint and FLOP intensity of dense multi-hundred-billion parameter architectures impose prohibitive operational costs. Post-training compression strategies such as quantization and structural pruning reduce precisi

    AI
    11 min read
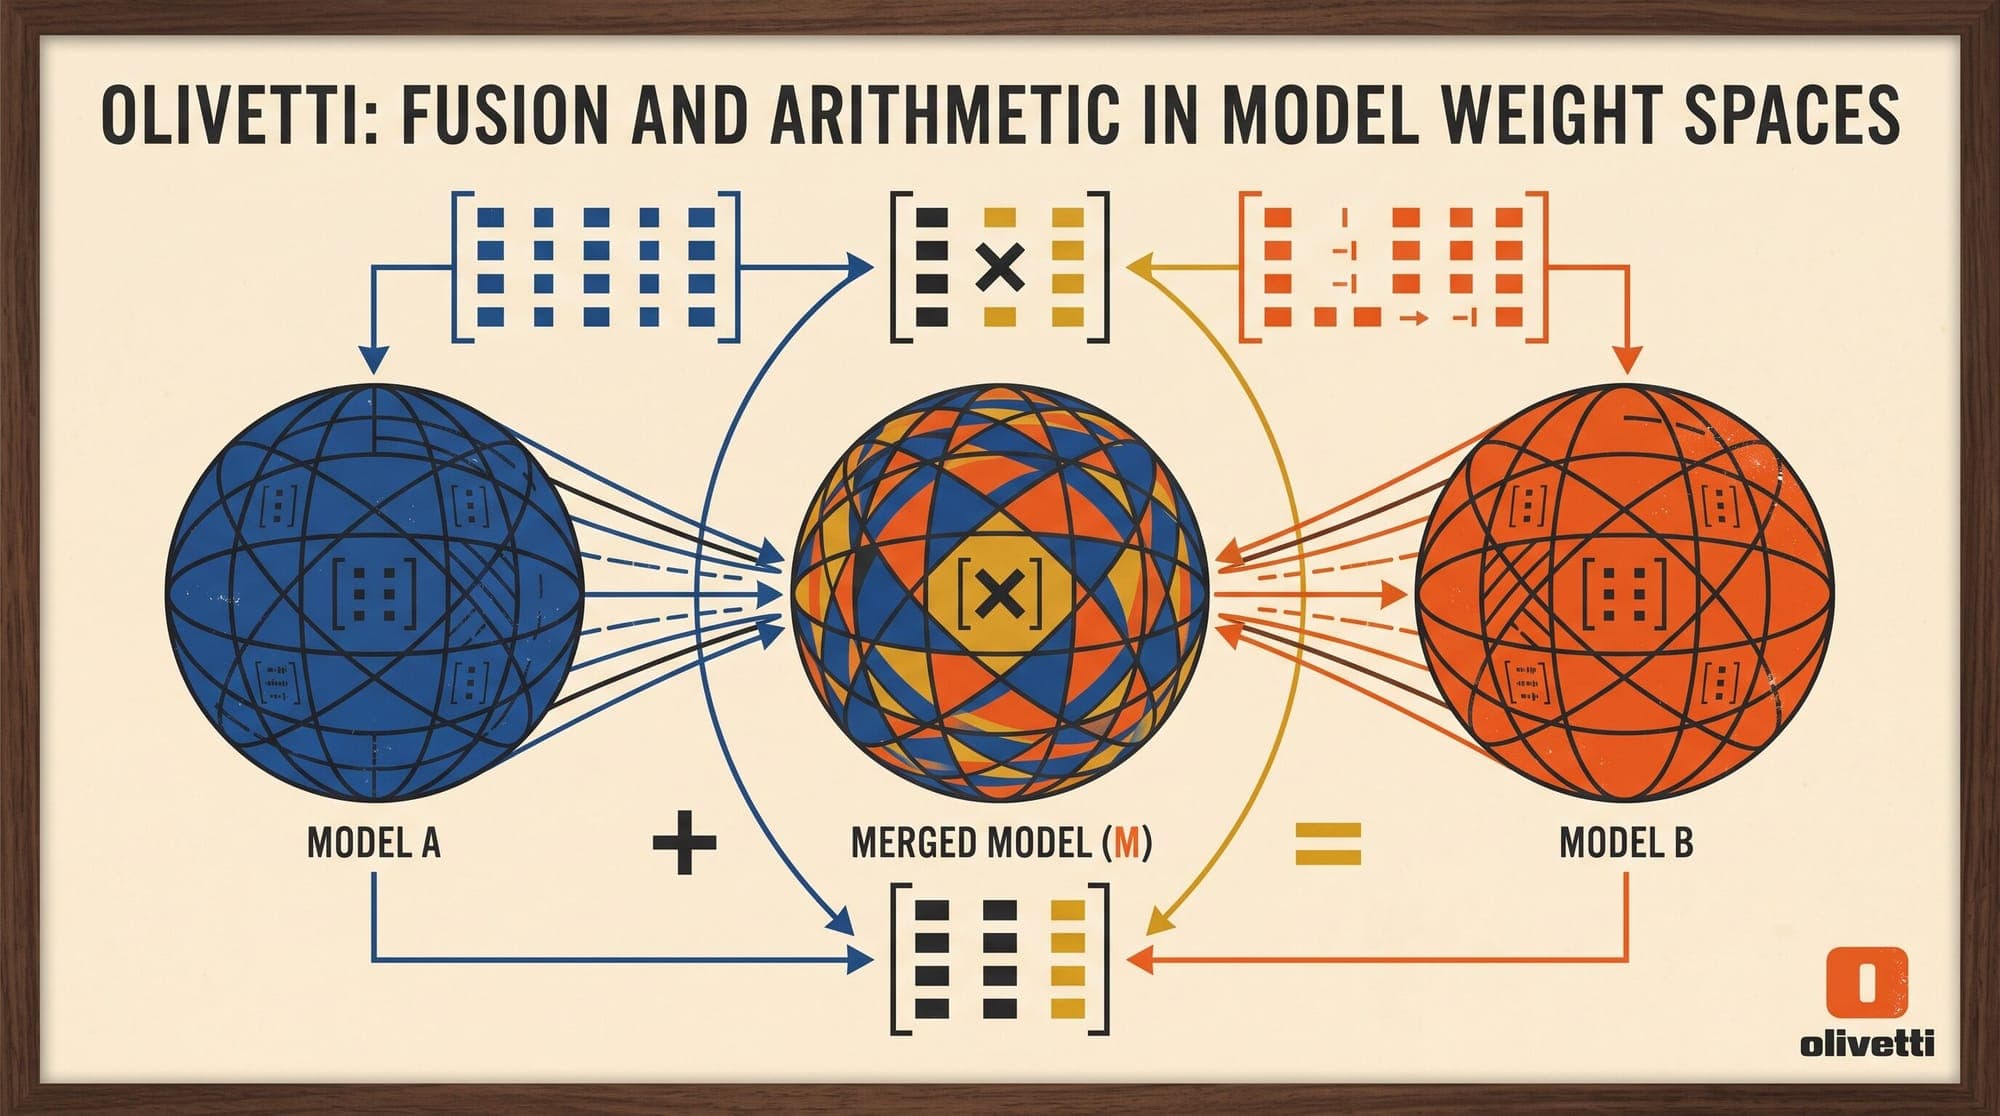
  11. Model Merging in Weight Space: Mathematical Foundations of Task Vectors, TIES-Merging, DARE, and Spherical Linear Interpolation

    Training large language models across multiple downstream domains typically requires expensive multi-task supervised fine-tuning (SFT) or sequential continual learning. Both paths present steep practical challenges: multi-task training demands simultaneous access to massive, curated datasets and massive compute budgets, while sequential fine-tuning suffers from catastrophic forgetting. Model merging has emerged as a data-free, compute-efficient alternative. By combining the parameters of multip

    AI
    8 min read
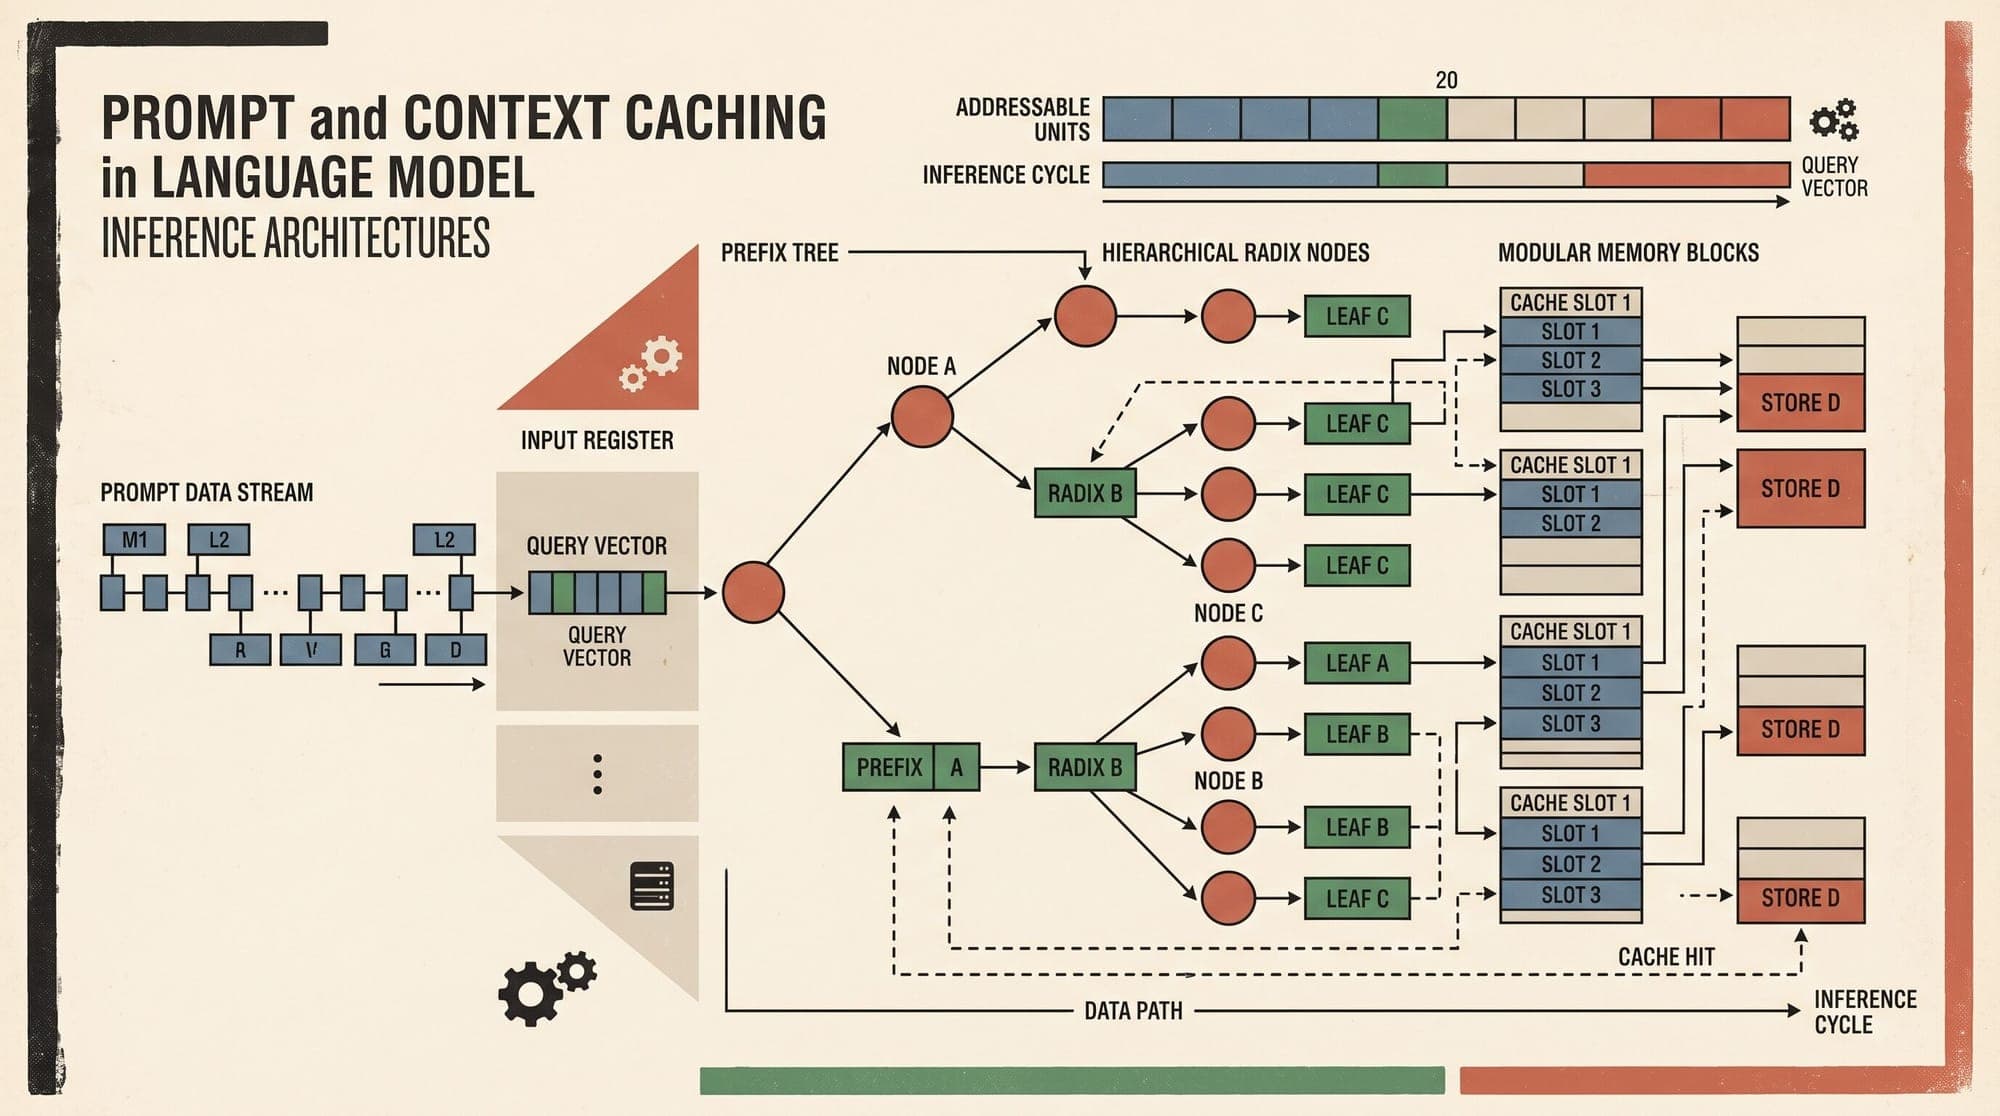
  12. Prompt and Context Caching in Production: Comparing Anthropic, OpenAI, DeepSeek, Google Gemini, and RadixAttention KV Reuse

    Modern LLM serving workloads spend a disproportionate share of computational budget and time-to-first-token (TTFT) latency on prompt prefill. In agentic loops, retrieval-augmented generation (RAG), and multi-turn chat applications, repeated prompts often share 80% to 95% of their token sequences across requests. Without caching, inference engines recompute key-value (KV) attention tensors across every input token on every turn, driving quadratic compute overhead and memory bandwidth saturation.

    AI
    5 min read
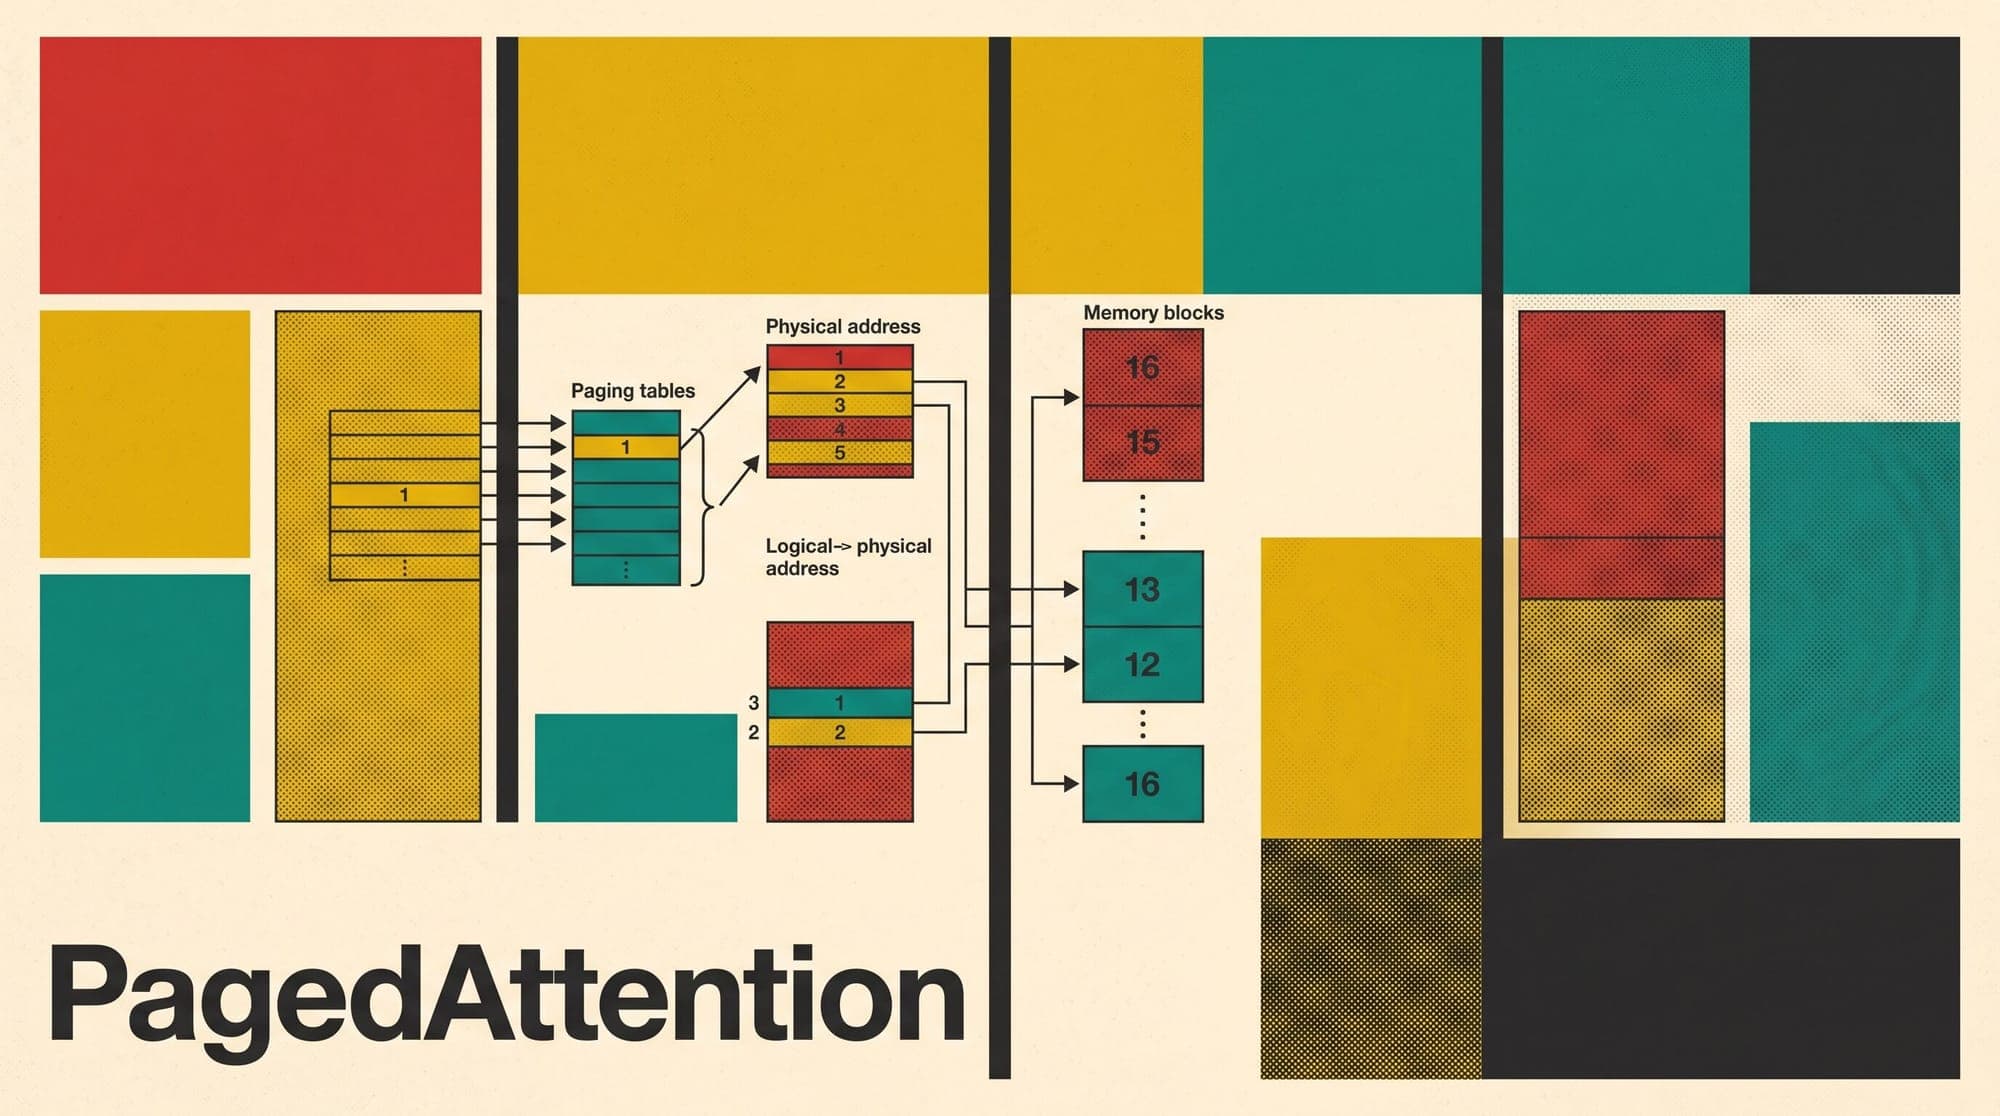
  13. PagedAttention and Virtual Memory Management: Mathematical Foundations of Non-Contiguous KV-Cache Allocation, Dynamic Block Translation, and Copy-on-Write Forking Mechanics

    In autoregressive transformer serving, the generation phase is fundamentally constrained by GPU memory capacity and memory bandwidth rather than raw compute throughput. While the initial prefill phase processes the prompt in parallel with high arithmetic intensity, the subsequent token-by-token decoding phase computes attention for only a single new token per sequence at each step. At each decoding step, the model must read all historical Key (K) and Value (V) activation tensors from GPU High Ba

    AI
    13 min read
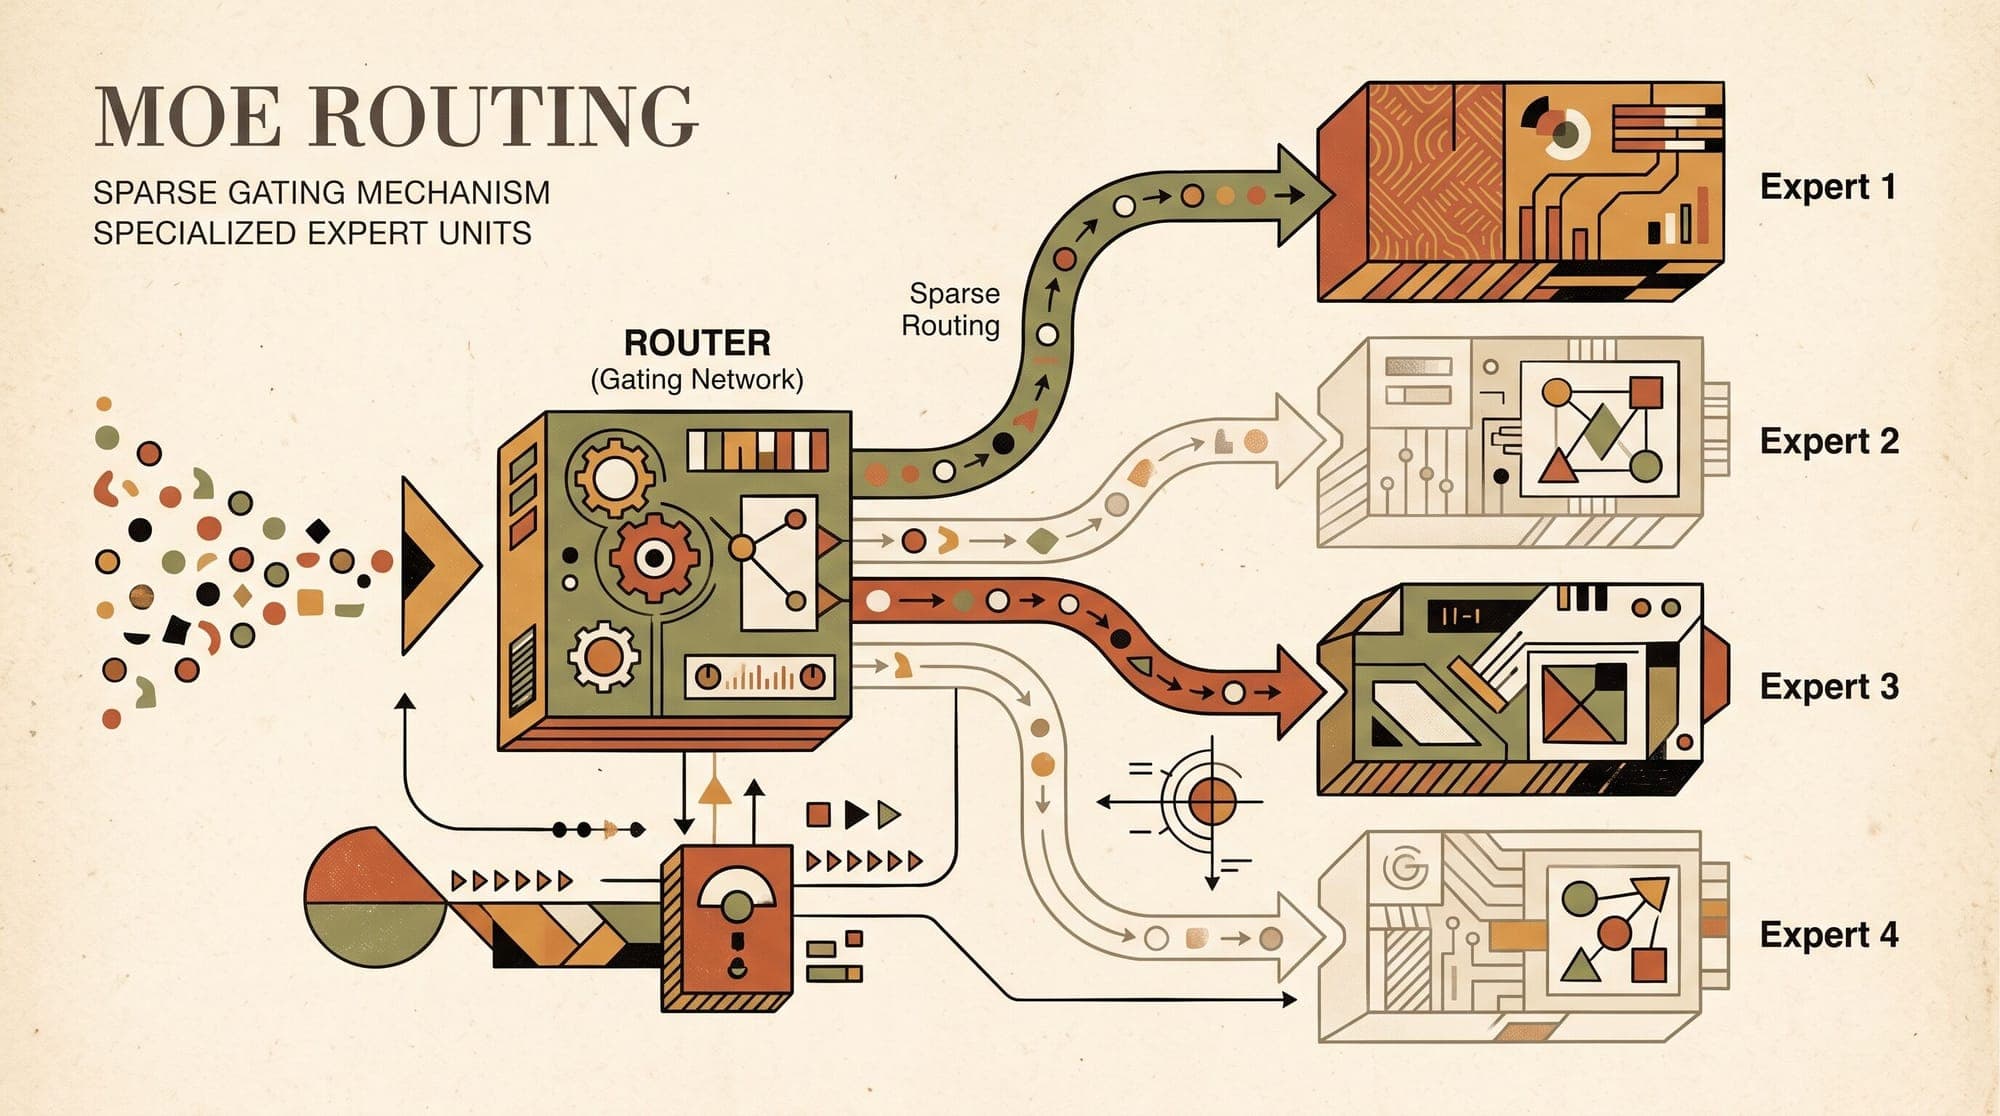
  14. Mixture-of-Experts (MoE) Routing and Load Balancing: Mathematical Foundations of Noisy Top-k Gating, Expert Capacity, Auxiliary Balancing Losses, and Loss-Free Load Balancing

    Mixture-of-Experts (MoE) Routing and Load Balancing: Mathematical Foundations of Noisy Top-k Gating, Expert Capacity, Auxiliary Balancing Losses, and Loss-Free Load Balancing Scaling dense transformer models incurs computational costs that grow proportionally with parameter count. In dense architectures, every token in a sequence activates all feed-forward network (FFN) parameters across every layer. Sparse Mixture-of-Experts (MoE) architectures decouple parameter count from per-token compute b

    AI
    15 min read
  15. Document Parsing Engines in Production RAG: Comparing Docling, Marker, MinerU, and Unstructured Architecture, Layout Analysis, Table Extraction, and Serving Economics

    Retrieval-Augmented Generation (RAG) systems frequently fail not in their embedding models or vector databases, but at the initial document ingestion layer. When enterprise documents (including financial 10-K filings, clinical trial reports, technical manuals, and multi-column academic papers) are parsed using legacy text scrapers such as basic pypdf or pdfminer, structural semantics are lost. Multi-column reading orders interleave across paragraphs, header and footer noise pollutes vector indic

    AI
    9 min read
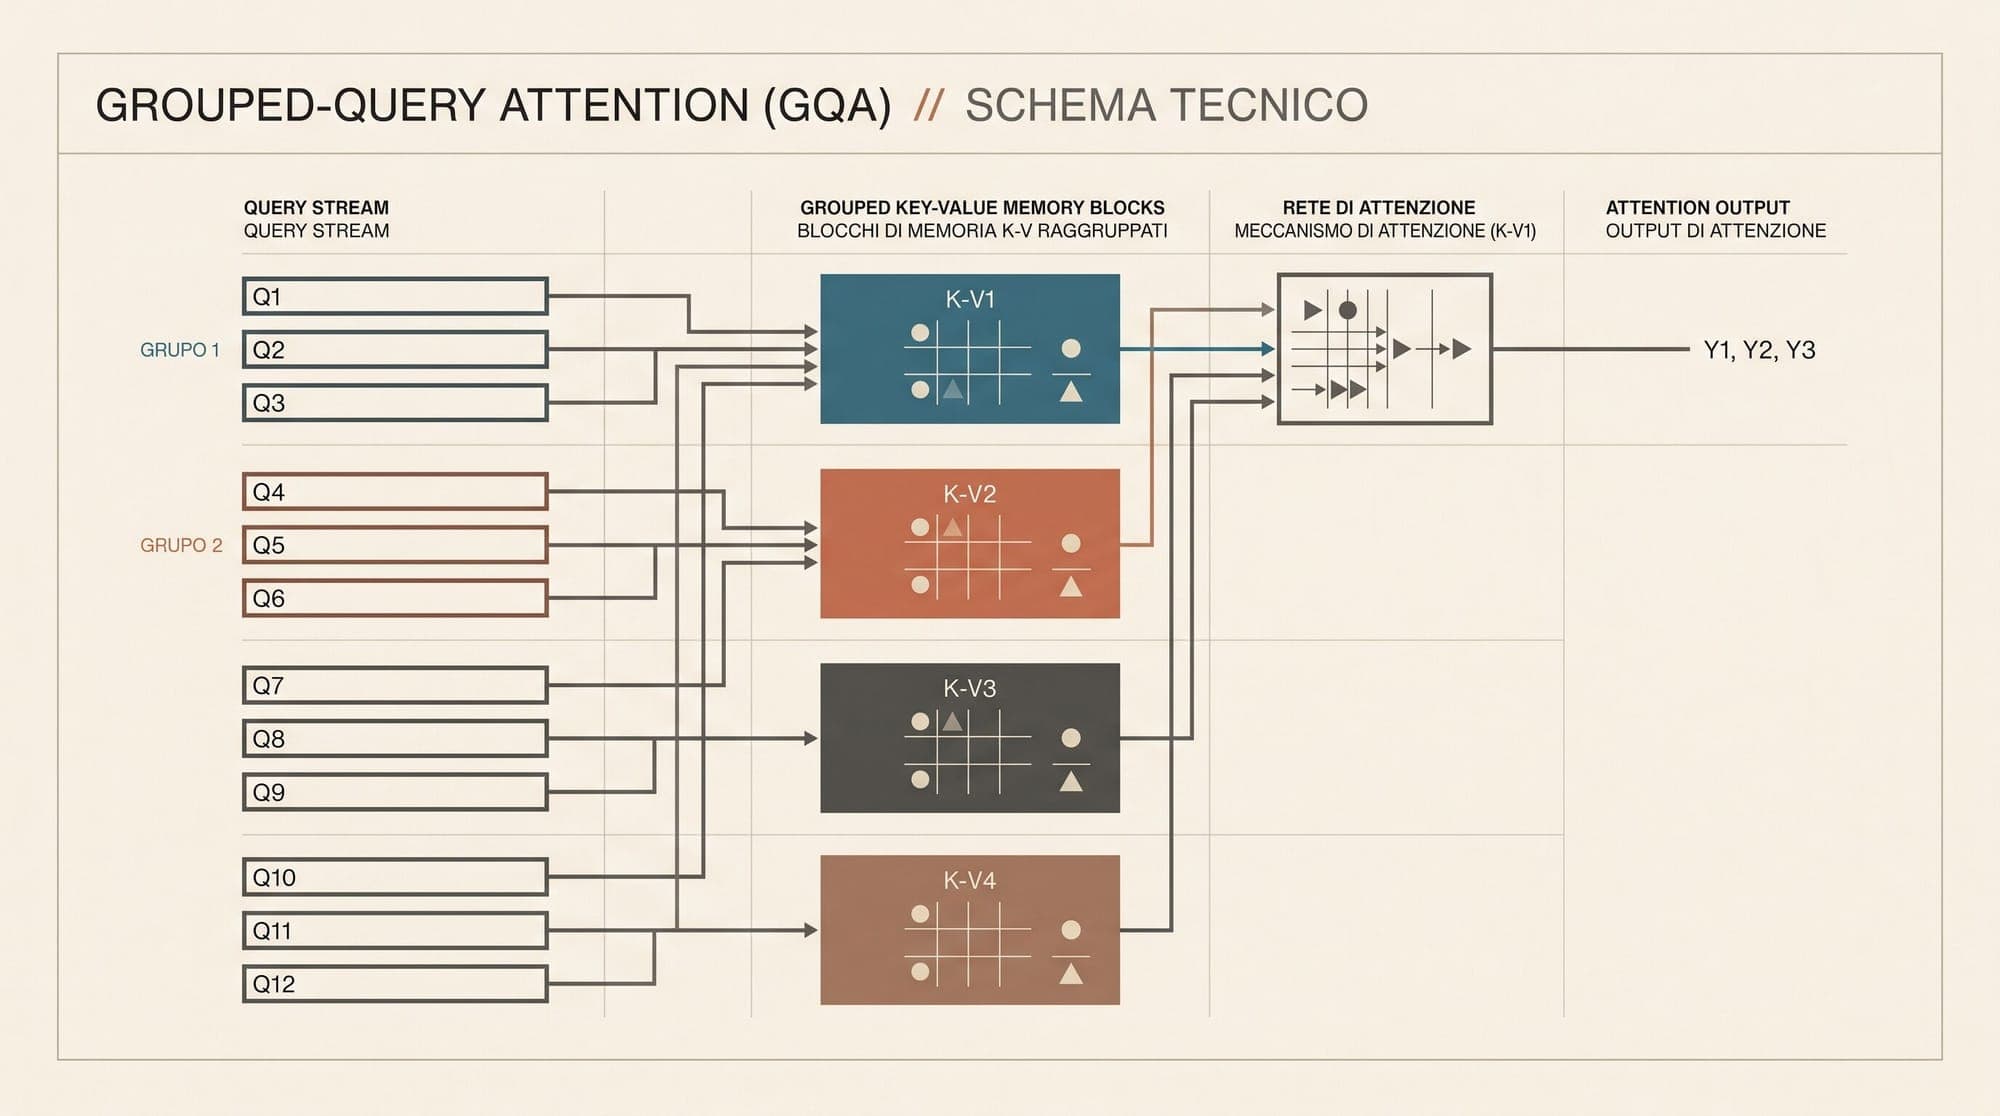
  16. Grouped-Query Attention (GQA) and Multi-Query Attention (MQA): Mathematical Foundations, Arithmetic Intensity, and KV-Cache Scaling Mechanics

    Grouped-Query Attention (GQA) and Multi-Query Attention (MQA): Mathematical Foundations, Arithmetic Intensity, and KV-Cache Scaling Mechanics Autoregressive large language model inference is governed by a fundamental hardware asymmetry. During the initial prompt processing phase (prefill), computation is compute-bound because matrix multiplications process entire sequences in parallel. During sequential token generation (decoding), execution becomes strictly memory-bandwidth bound. For each gen

    AI
    12 min read
  17. LLM Fine-Tuning and Post-Training Frameworks in Production: Comparing Unsloth, Axolotl, Torchtune, and LLaMA-Factory

    Post-training has transitioned from a specialized research task into a standard production engineering discipline. As open-weight base models such as Llama 3.1, Qwen 2.5, and DeepSeek-V3 establish competitive baselines, the primary engineering challenge has shifted toward domain adaptation, instruction alignment, and reasoning distillation. However, selecting a post-training framework requires balancing competing architectural trade-offs: low-level kernel fusion, distributed multi-node scaling,

    AI
    6 min read
  18. State Space Models (SSMs) and Mamba: Mathematical Foundations of Continuous-Time Discretization, Selective Scan Mechanics, and Structured State Space Duality

    Autoregressive Large Language Models (LLMs) built on the standard Transformer architecture rely on softmax self-attention. While self-attention provides expressive in-context learning and dense token-to-token associative recall, it exhibits fundamental algorithmic scaling limits: prefill compute scales quadratically with sequence length ($O(L^2 d)$), and autoregressive token generation requires maintaining a Key-Value (KV) cache that grows linearly with sequence length ($O(L d)$). At context win

    AI
    12 min read
  19. Anthropic Opens 250,000 Claude Conversations to External Researchers Across Stanford, Oxford, and METR

    Anthropic's Societal Impacts team has released initial results from a research pilot that opened aggregate, real-world Claude conversation data to outside academic teams. The initiative partnered with researchers from Stanford University's Social and Language Technologies (SALT) Lab, the University of Oxford's Human Information Processing Lab, and the model evaluation non-profit METR. Each group conducted independent studies across a sample of approximately 250,000 conversations recorded on Clau

    AI
    2 min read
  20. Low-Rank Adaptation (LoRA) and QLoRA: Mathematical Foundations, Intrinsic Rank Parameterization, NF4 Quantization, and Double Quantization Mechanics

    Low-Rank Adaptation (LoRA) and QLoRA: Mathematical Foundations, Intrinsic Rank Parameterization, NF4 Quantization, and Double Quantization Mechanics Parameter-efficient fine-tuning (PEFT) has become the standard operational methodology for adapting large language models to domain-specific tasks, downstream instruction following, and structured tool use. Full-parameter fine-tuning of frontier architectures requires updating and tracking optimizer states for tens or hundreds of billions of parame

    AI
    11 min read