Representation Fine-Tuning (ReFT): Mathematical Foundations, Low-Rank Linear Subspaces, Intervention Operations, and Parameter-Efficient Representation Editing in Large Language Models
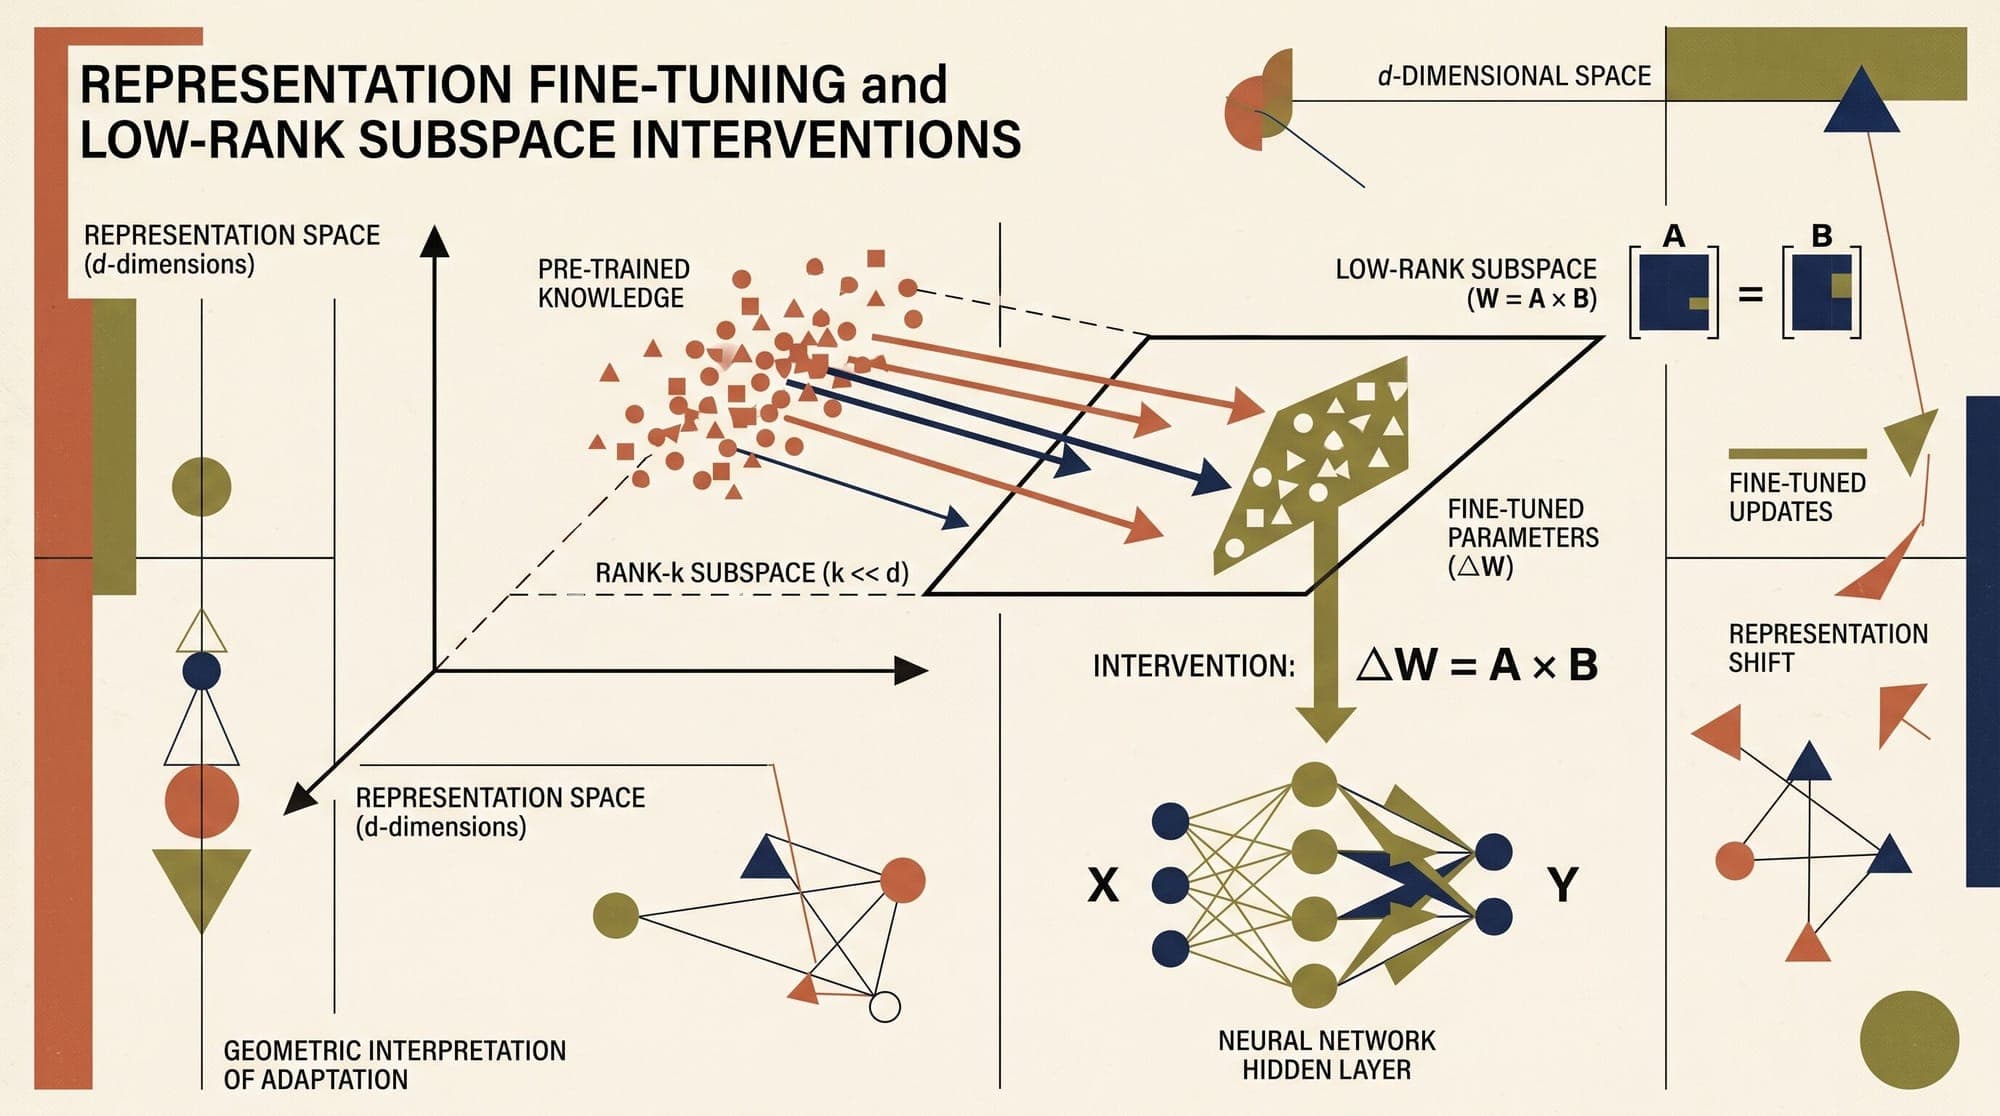
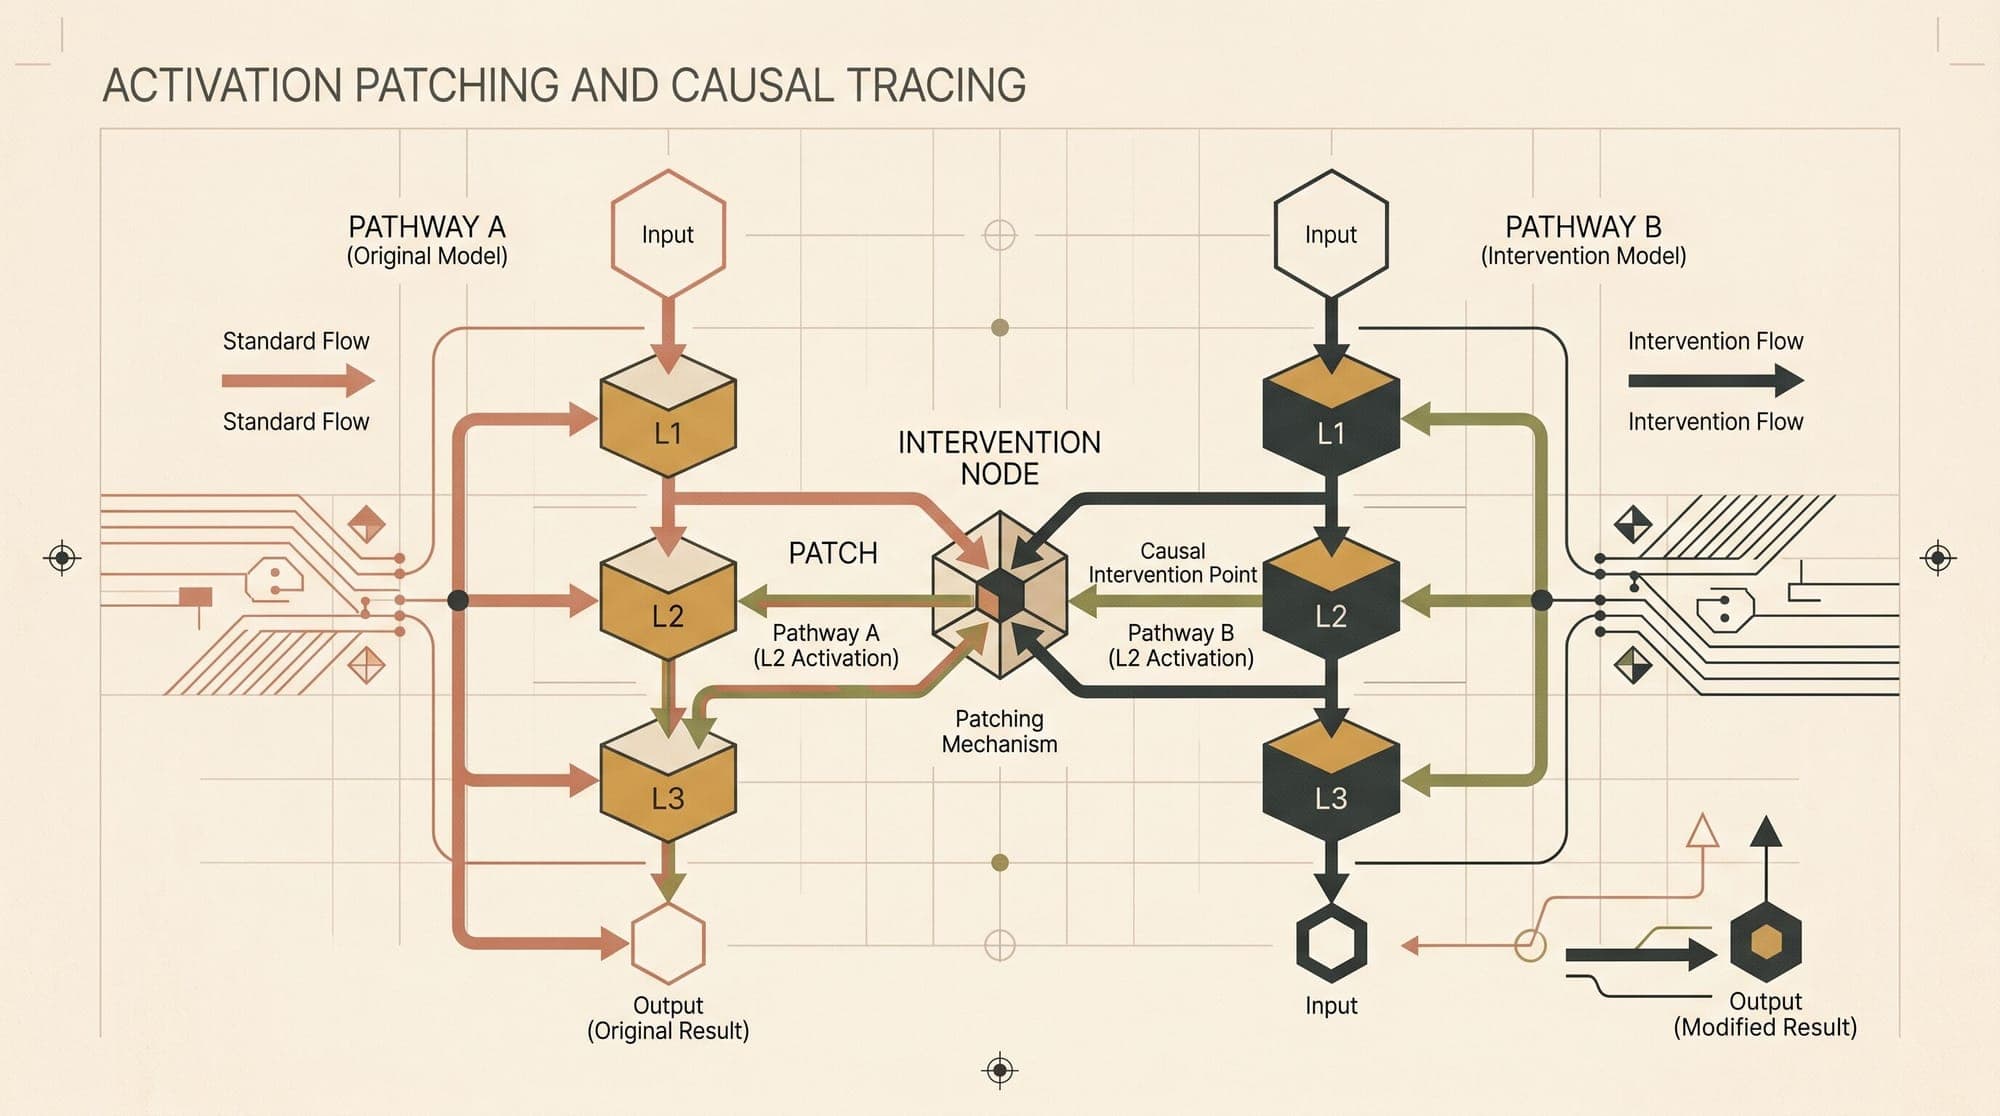
Representation Fine-Tuning (ReFT) introduces a parameter-efficient adaptation paradigm that operates directly on the hidden representations of frozen language models rather than updating or augmenting model weight matrices. Developed by researchers at Stanford University (Wu et al., 2024), ReFT leverages insights from mechanistic interpretability and causal abstraction to steer model behavior through learned low-rank subspace interventions. By editing internal activations at targeted sequence po