Data Annotation and Preference Labeling Frameworks in Production: Comparing Argilla, Label Studio, Prodigy, and Cleanlab
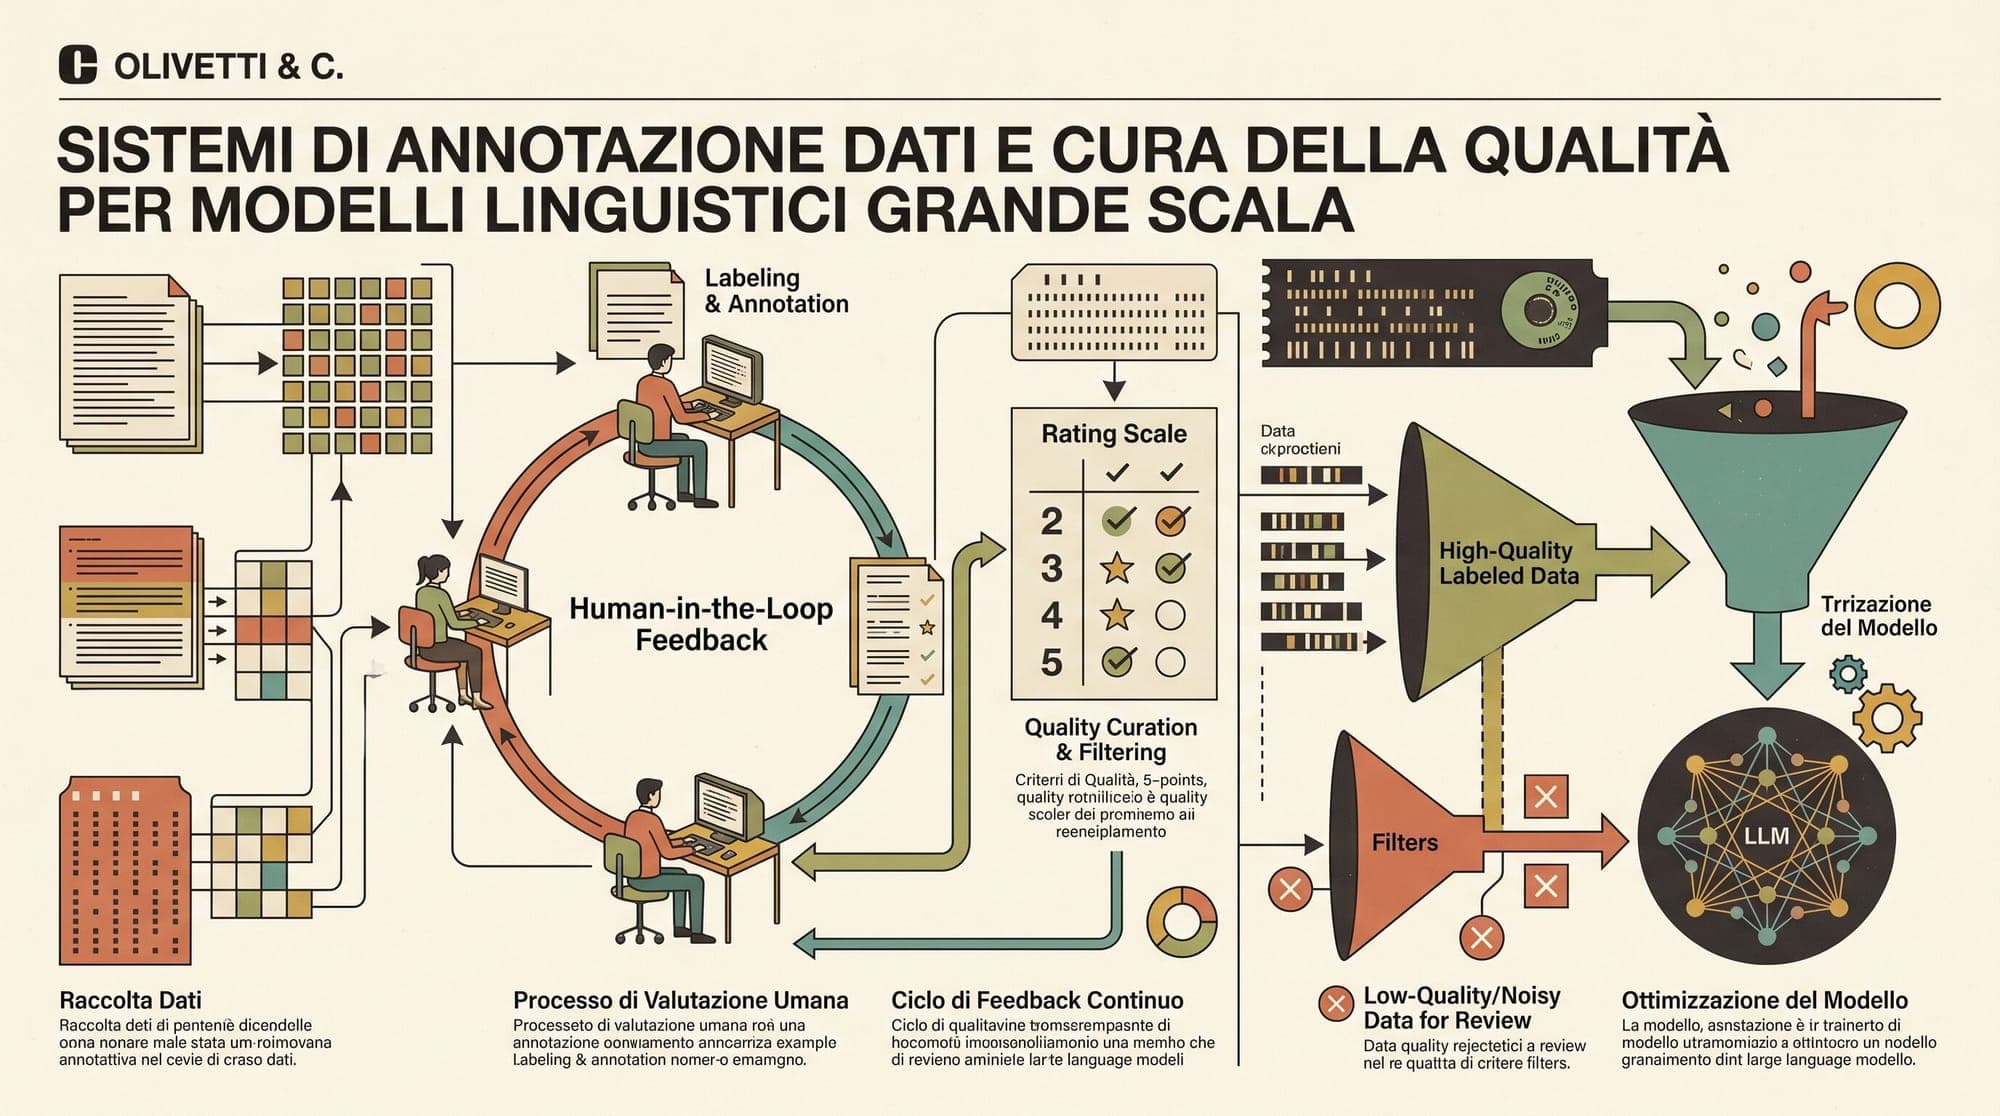
Modern frontier and open-weight large language models rely heavily on curated data pipelines across Supervised Fine-Tuning (SFT), Reinforcement Learning from Human Feedback (RLHF), and Direct Preference Optimization (DPO). While pre-training ingests trillions of uncurated tokens from the public web, post-training alignment requires high-precision preference rankings, instruction demonstrations, and safety boundary evaluations. Empirical research demonstrates that a few thousand meticulously cura