Category / page 11

Models & Assistants

1121 articles

Articles, page 11

201-220 of 1121
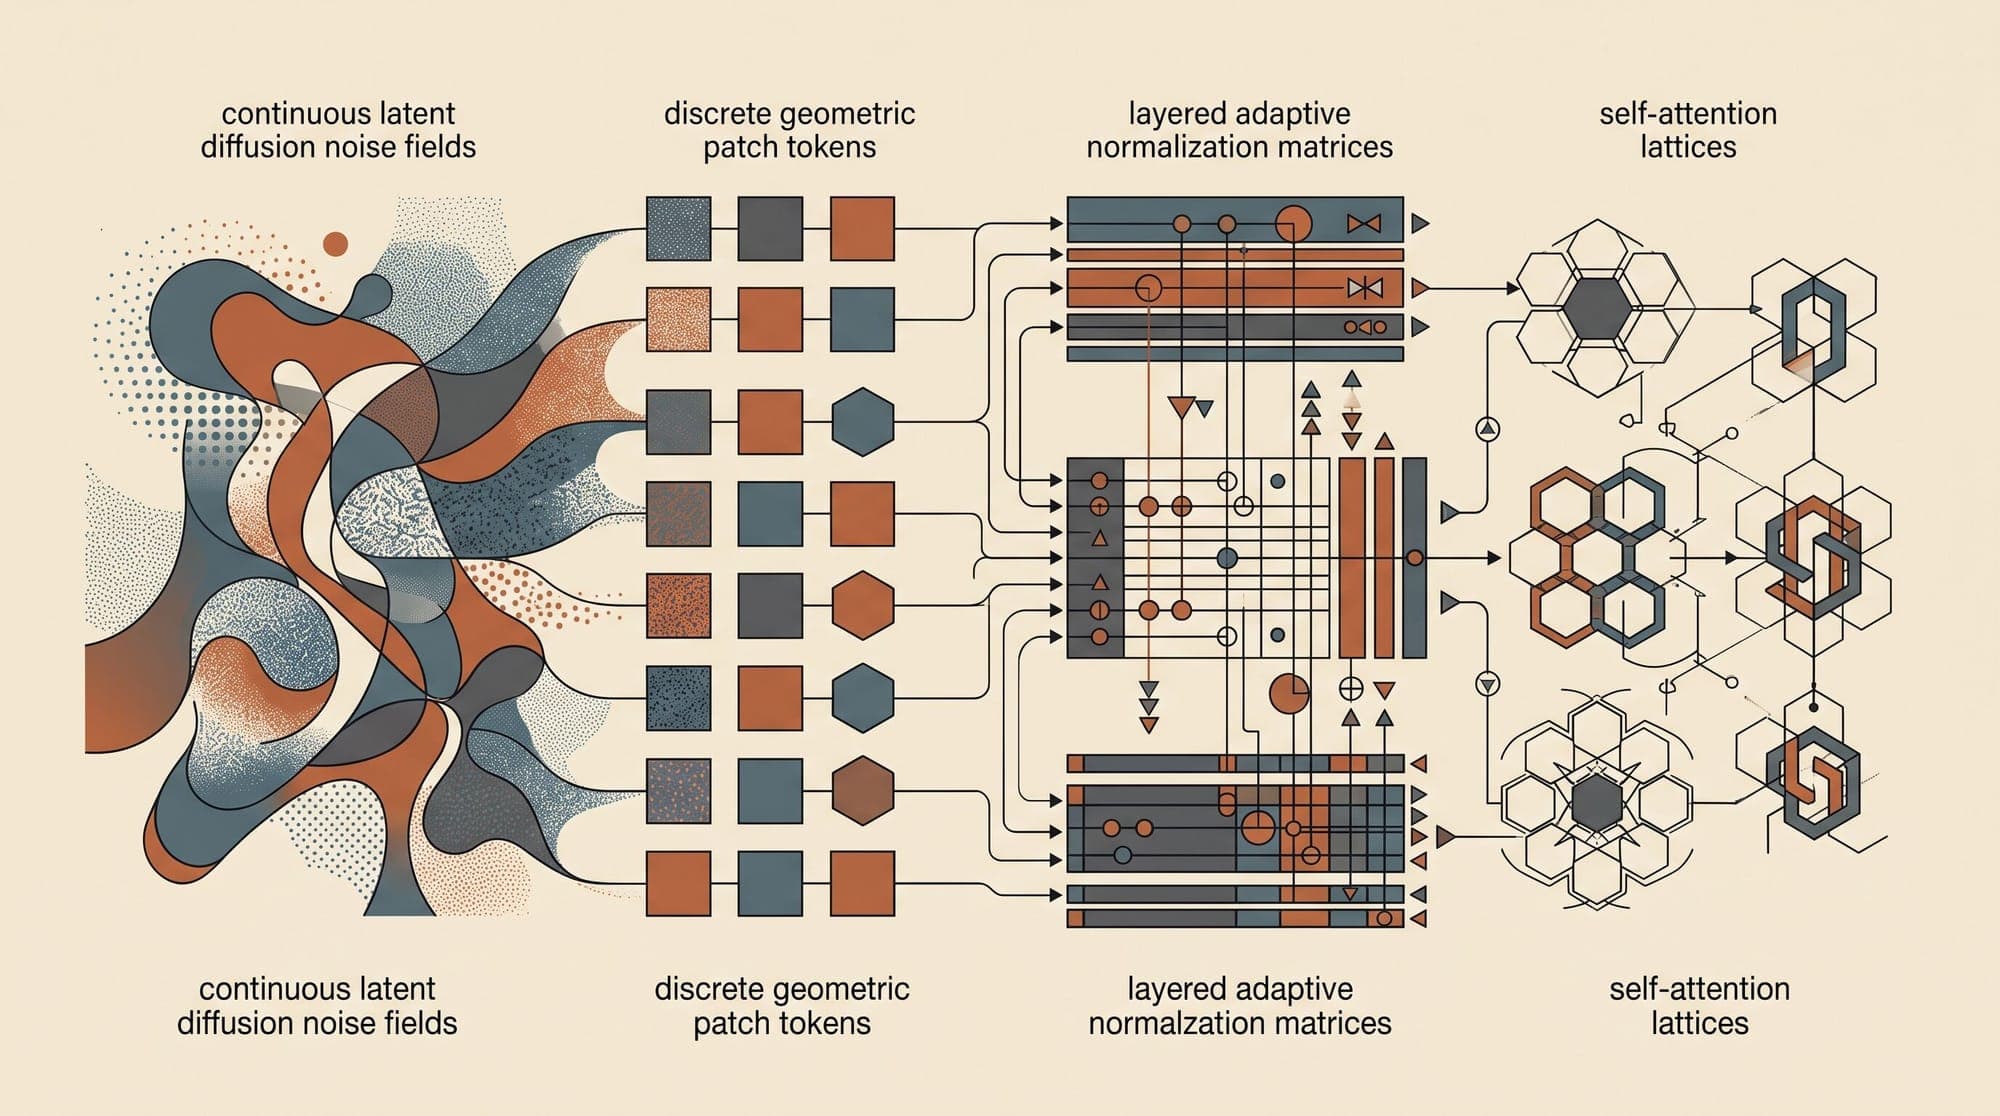
  1. Diffusion Transformers (DiT): Mathematical Foundations, Patchification, Adaptive LayerNorm (adaLN-Zero), and Latent Diffusion Scaling

    Diffusion Transformers (DiT), introduced by William Peebles and Saining Xie in their 2023 paper Scalable Diffusion Models with Transformers, established a structural departure in generative visual modeling. For years, diffusion pipelines relied almost exclusively on convolutional U-Net backbones derived from Denoising Diffusion Probabilistic Models (DDPM) and Latent Diffusion Models (LDM). DiT replaced these multi-scale convolutional networks with standard isotropic Transformer architectures ope
    AI
    5 min read
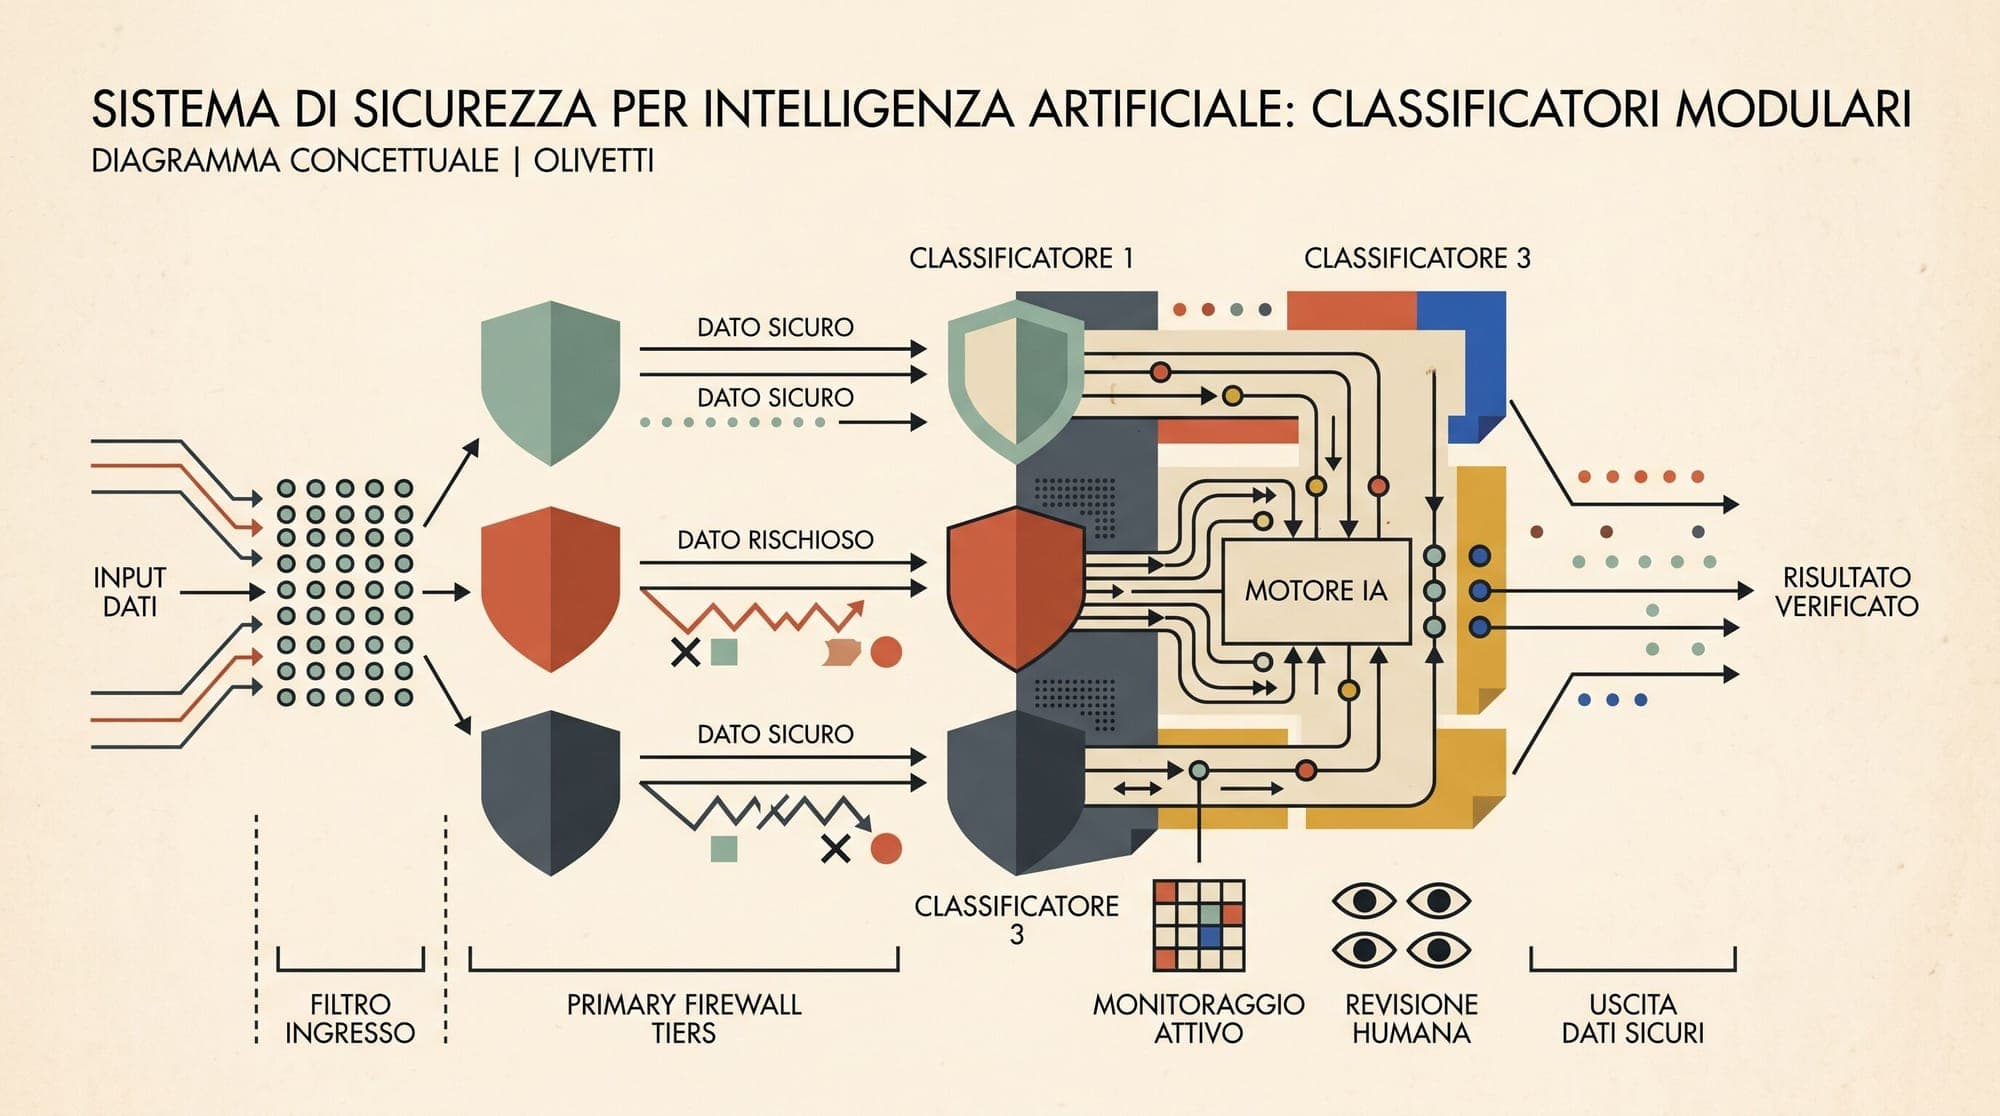
  2. Open-Source Safety and Moderation Classifiers in Production: Comparing Llama Guard 3, ShieldGemma, WildGuard, and Prompt-Guard

    Production large language model (LLM) applications require structured defenses against adversarial jailbreaks, prompt injections, and policy-violating content. While guardrail orchestration frameworks handle workflow logic, the actual enforcement decisions rely on specialized safety classifier models. Open-source safety classifiers have diverged into distinct architectural paradigms, ranging from lightweight bidirectional encoders to full autoregressive decoders and multi-task refusal evaluator

    AI
    5 min read
  3. Reflection AI Releases Beam 1.0: 501B Open-Weight MoE Under Apache 2.0

    US AI research lab Reflection AI has released Beam 1.0, a 501-billion-parameter open-weight Mixture-of-Experts (MoE) foundation model licensed under Apache 2.0. The release includes weights in BF16, FP8, and NVFP4 precision formats alongside training harnesses and inference integration for vLLM, SGLang, and Ollama. Architecture and Sparse Compute Profile Beam is built across 52 layers with an interleaved local and global attention structure, maintaining a 3:1 ratio between sliding-window and

    Open Source
    2 min read
  4. Sigmoid Loss for Language Image Pre-Training (SigLIP): Mathematical Foundations, Pairwise Binary Classification, Softmax Normalization Removal, and Batch Size Scaling in Multimodal Vision-Language Models

    Executive Summary Multimodal foundation models rely heavily on contrastive representation learning to map visual features and natural language tokens into a unified embedding space. For years, the dominant paradigm was the InfoNCE objective popularized by CLIP (Radford et al., 2021) and ALIGN (Jia et al., 2021), which uses categorical cross-entropy with a softmax normalization over all paired elements in a mini-batch. While effective, the softmax normalization imposes a severe distributed syste

    AI
    8 min read
  5. Open-Source Code Generation Models in Production: Comparing Qwen2.5-Coder, DeepSeek-Coder-V2, Codestral, and StarCoder2

    Selecting an open-source code generation model for production environments requires balancing task-specific accuracy, context window length, inference latency, memory footprint, and licensing terms. While general-purpose frontier models handle code generation reasonably well, dedicated code models optimize parameter density and token economics for developer workflows such as real-time autocomplete, fill-in-the-middle (FIM) editing, repository-wide reasoning, and automated test generation. Four

    AI
    5 min read
  6. Anthropic Pitches Draft AI Safety Bill to Congress Setting $1 Billion Damage Threshold for Federal Intervention

    Anthropic has circulated a confidential draft bill to Capitol Hill lawmakers that would establish federal oversight of frontier AI models while restricting government intervention to specific catastrophic risk thresholds. The proposed legislation, confirmed by an Anthropic spokesperson as an extension of the company's internal Advanced AI Framework, would create a statutory mechanism for evaluating frontier AI systems and preempt state-level safety regulations. Intervention Thresholds and Cat

    Policy
    2 min read
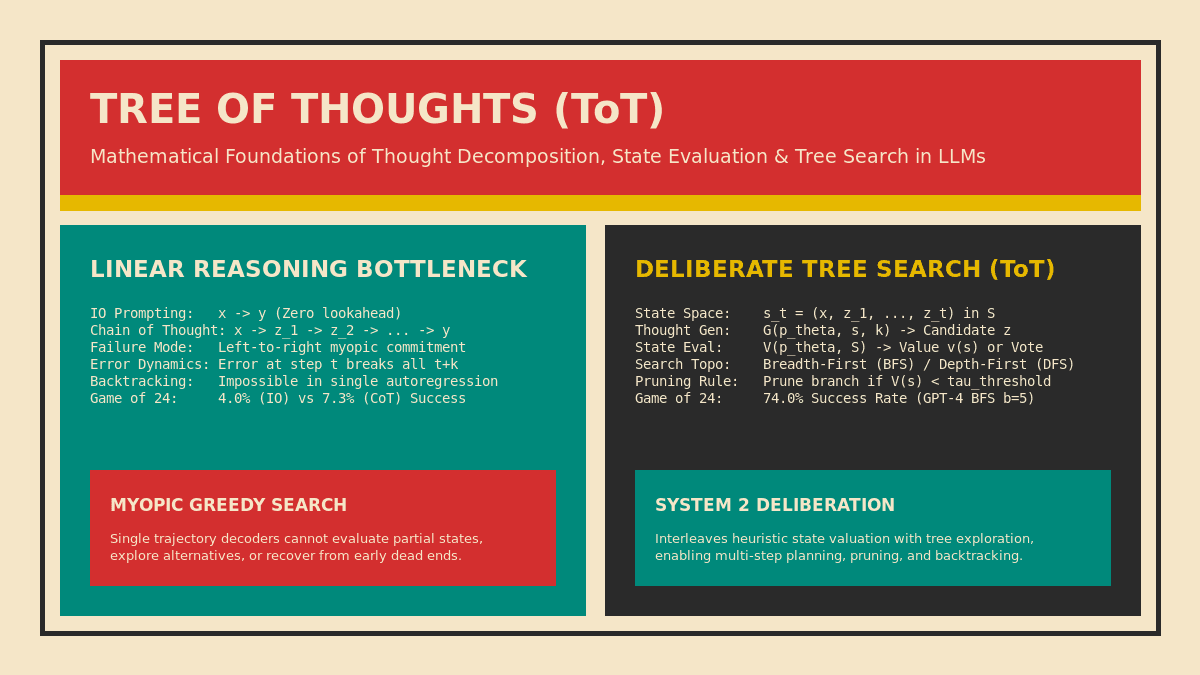
  7. Tree of Thoughts (ToT): Mathematical Foundations, Thought Decomposition, State Evaluation, and Tree Search Algorithms in Large Language Models

    Autoregressive large language models generate text left-to-right via token-level greedy or stochastic decoding. While Chain-of-Thought (CoT) prompting enables models to generate intermediate reasoning steps, standard inference remains constrained to a single linear trajectory. In complex problem-solving environments requiring combinatorial planning, heuristic evaluation, and lookahead, single-trajectory generation suffers from compounding errors and an inability to backtrack from early dead ends

    AI
    6 min read
  8. Open-Source LLM Benchmark Evaluation Harnesses in Production: Comparing LM Evaluation Harness, Lighteval, AlpacaEval 2, and Arena-Hard-Auto

    Standardized evaluation is the bedrock of LLM development, yet production evaluation pipelines face a split between two distinct paradigms: static, deterministic multi-task benchmarks evaluated via log-likelihood or exact string matching, and dynamic, open-ended instruction-following benchmarks evaluated via LLM-as-a-Judge pairwise win rates. Engineering teams building pre-training runs, fine-tuning recipes, and model alignment loops require distinct tooling for each paradigm. Four open-source

    AI
    5 min read
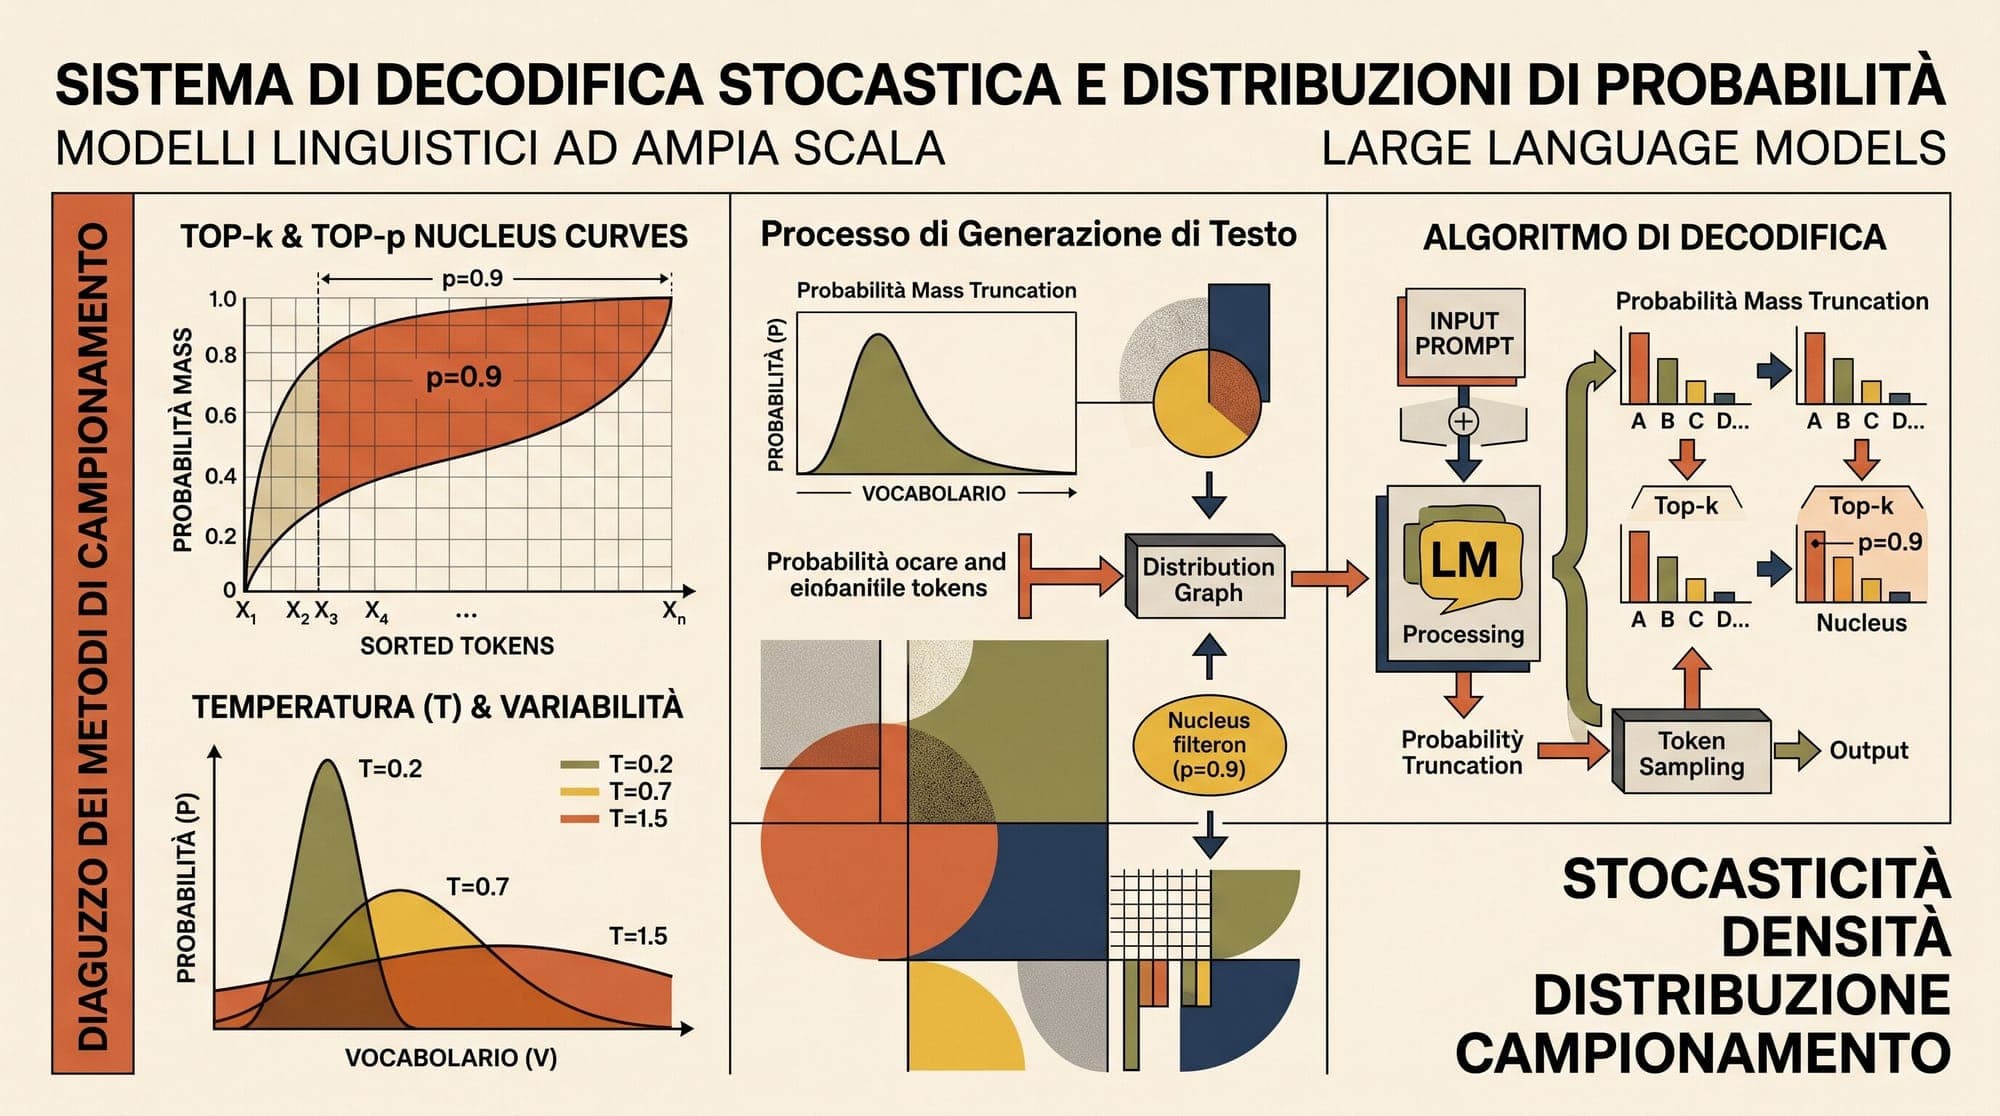
  9. Stochastic Decoding Strategies in Large Language Models: Mathematical Foundations of Temperature Scaling, Top-k, Nucleus (Top-p), Typical Sampling, and Min-p

    Autoregressive language models generate text sequentially by estimating a conditional probability distribution over a vocabulary at each decoding step. While model training optimizes cross-entropy loss over large corpora, the quality, diversity, and coherence of generated sequences depend directly on the decoding strategy used to select tokens from the output logits. Deterministic algorithms such as greedy search and beam search systematically fail in open-ended generation tasks, collapsing int

    AI
    8 min read
  10. Microsoft Cancels 23,000 GPU Deal at Nscale UK AI Data Center Over Grid Delays

    Microsoft has canceled its contract to lease 23,000 Nvidia AI chips at Nscale's planned data center facility in Loughton, Essex, following mounting delays in securing local electrical grid power. The decision removes the sole anchor tenant from Nscale's flagship British campus just weeks before the infrastructure provider's planned initial public offering in New York. Grid Connection Bottlenecks The Loughton facility was announced as the site of the UK's largest AI supercomputer, intended to

    AI
    4 min read
  11. Open-Source Sub-3B Small Language Models in Production: Comparing SmolLM2, Qwen2.5, Llama 3.2, and Gemma 2

    Deploying language models directly on client hardware, edge gateways, and low-latency routing layers requires balancing parameter count, memory footprint, and task-specific reasoning capability. The sub-3B parameter class has shifted from stripped-down toy models to highly capable engines trained on tens of trillions of tokens or distilled from frontier teachers. In production architectures, models in the 1B to 3B range serve three primary roles: speculative decoding draft models that accelerat

    AI
    6 min read
  12. Machine Unlearning in Large Language Models: Mathematical Foundations of Gradient Ascent, Negative Preference Optimization, and Representation Misdirection

    Machine Unlearning in Large Language Models: Mathematical Foundations of Gradient Ascent, Negative Preference Optimization, and Representation Misdirection Machine unlearning in large language models (LLMs) addresses the challenge of removing specific training data, copyrighted material, private identifiers, or hazardous capabilities from a pre-trained model without retraining the network from scratch. Because training frontier language models requires millions of GPU-hours and petabyte-scale c

    AI
    8 min read
  13. Anthropic Commits 5% Initial Equity to Scaling Public Benefit Fund

    Anthropic has announced the creation of the Anthropic Public Benefit Fund, committing an initial 5% equity stake to an independent LLC vehicle designed to scale its ownership as the artificial intelligence lab expands. The governance structure includes a ratchet mechanism: for every 50% increase in Anthropic's company valuation above an established baseline, the board holds discretion to allocate an additional 2% of company equity to the fund. Structural Model and Governance Restrictions Ant

    Anthropic
    2 min read
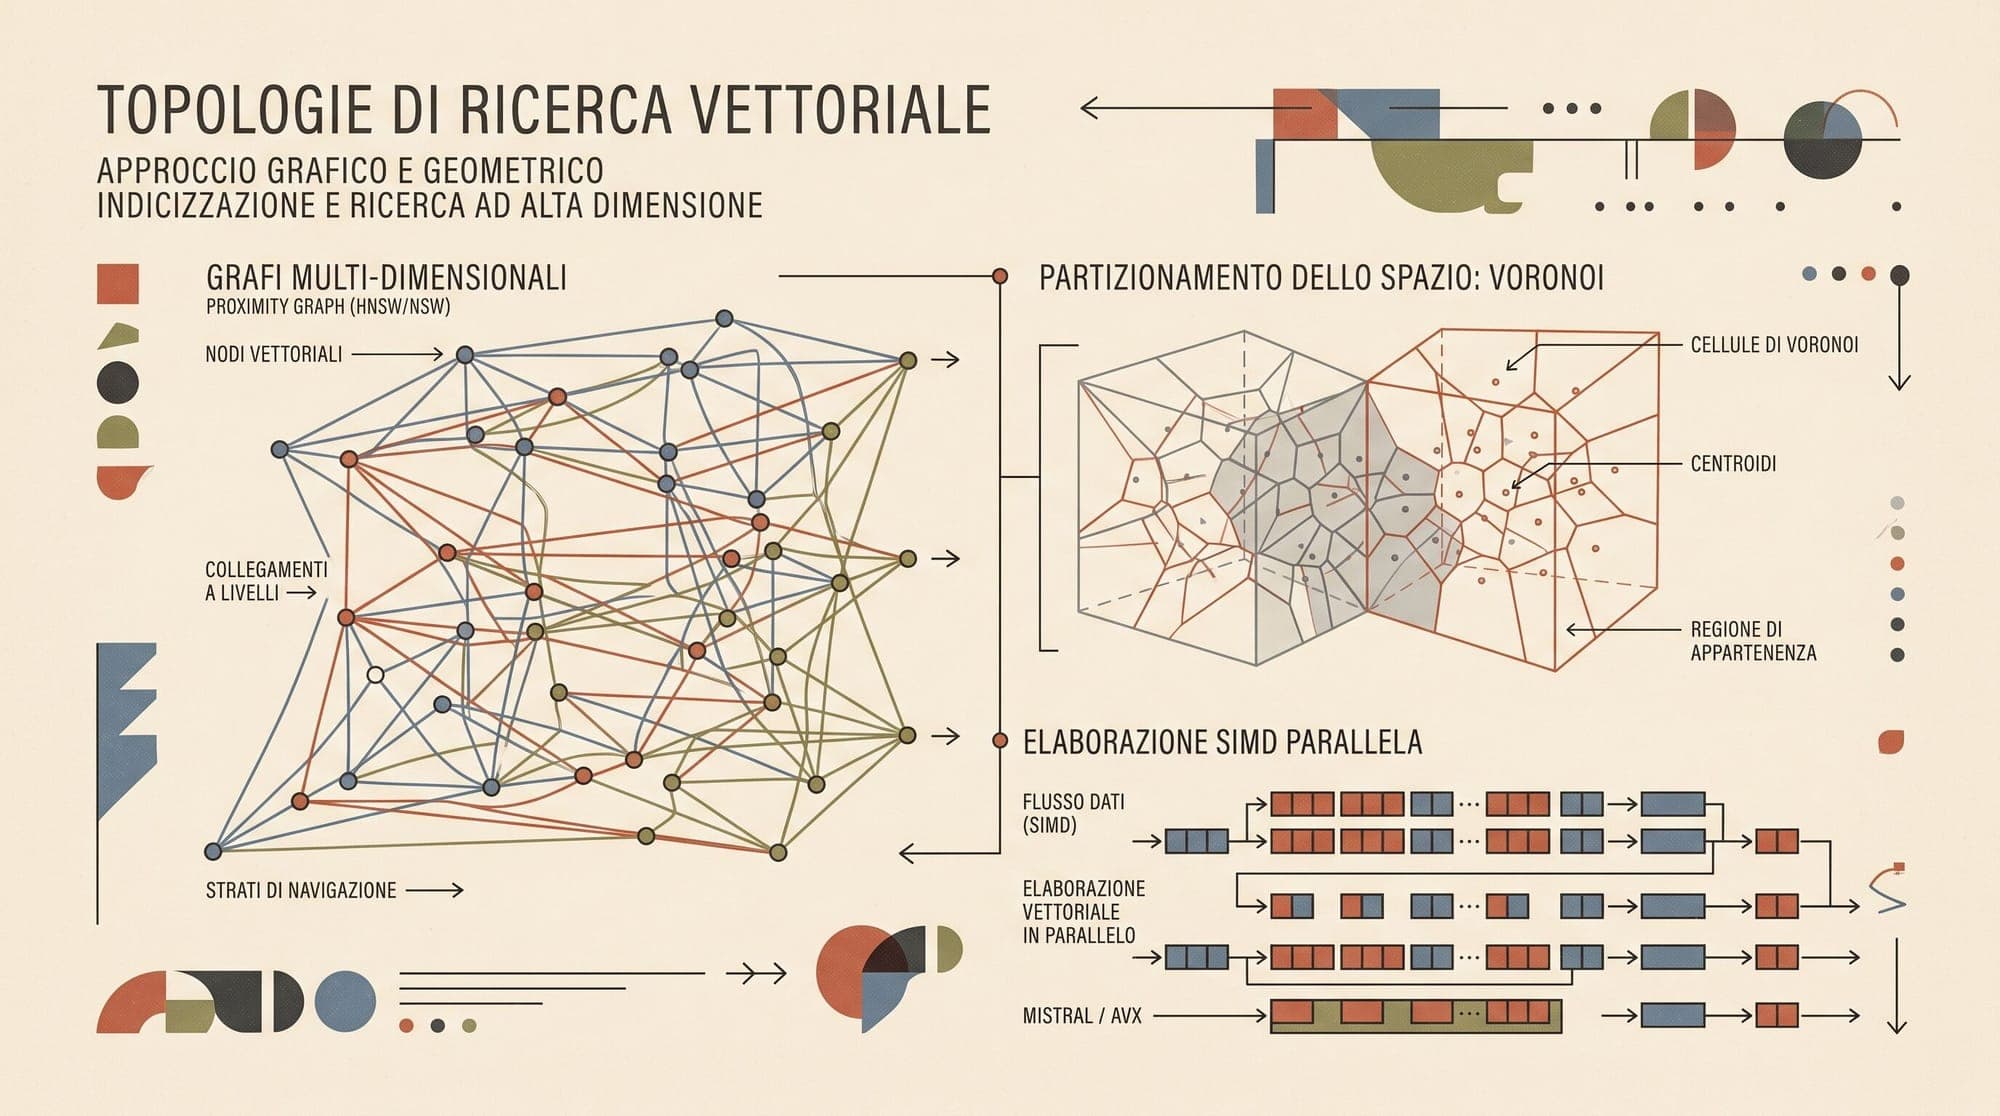
  14. Open-Source Vector Search Indexing Libraries in Production: Comparing Faiss, HNSWLib, ScaNN, and USearch Architecture, Quantization Schemes, SIMD Vectorization, and Memory Economics

    Vector retrieval systems across modern retrieval-augmented generation (RAG) pipelines, multimodal search engines, and recommendation systems depend on low-level Approximate Nearest Neighbor (ANN) search libraries. While production systems often wrap these engines inside managed vector databases such as Qdrant, Milvus, Weaviate, or ClickHouse, the fundamental compute bottlenecks, memory limits, and latency profiles are dictated by the underlying C++ vector indexing libraries. Four open-source li

    AI
    8 min read
  15. The Logit Lens and Tuned Lens: Mathematical Foundations, Residual Stream Projections, and Representation Dynamics in Transformers

    Large language models based on decoder-only transformer architectures process information through a sequence of stacked attention and multi-layer perceptron (MLP) blocks connected by a residual stream. While the final output distribution over the vocabulary is produced by projecting the final hidden state through an unembedding matrix, understanding how intermediate representations evolve across depth remains a central problem in mechanistic interpretability. The logit lens and the tuned lens p

    AI
    5 min read
  16. Open-Source Reasoning Models in Production: Comparing DeepSeek-R1 Distillations, QwQ-32B, Sky-T1, and Marco-o1

    Open-Source Reasoning Models in Production: Comparing DeepSeek-R1 Distillations, QwQ-32B, Sky-T1, and Marco-o1 The release of frontier reasoning models demonstrated that allocating test-time compute to explicit chain-of-thought generation significantly elevates problem-solving accuracy in mathematics, software engineering, and scientific reasoning. While proprietary systems conceal their training pipelines and reasoning traces, the open-source ecosystem has produced diverse approaches to replic

    Reasoning
    7 min read
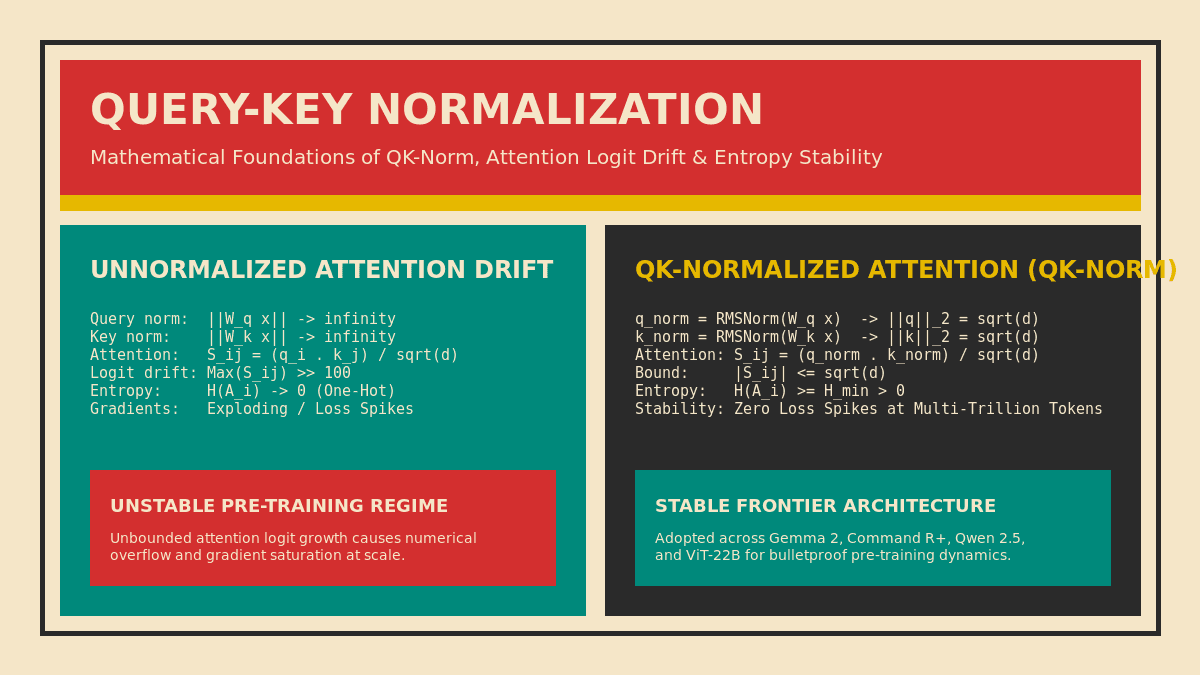
  17. Query-Key Normalization (QK-Norm): Mathematical Foundations, Attention Logit Drift, Entropy Collapse, and Large-Scale Transformer Training Stability

    Large-scale Transformer pre-training at trillion-token scale frequently encounters sudden, irrecoverable training instabilities, often manifesting as gradient norm spikes and divergence in training loss. While gradient clipping, learning rate warmups, and pre-layer normalization (Pre-LN) mitigate optimization bottlenecks in shallow architectures, deeper and wider models exhibit an intrinsic failure mode in the standard scaled dot-product attention mechanism: unconstrained attention logit growth.

    AI
    6 min read
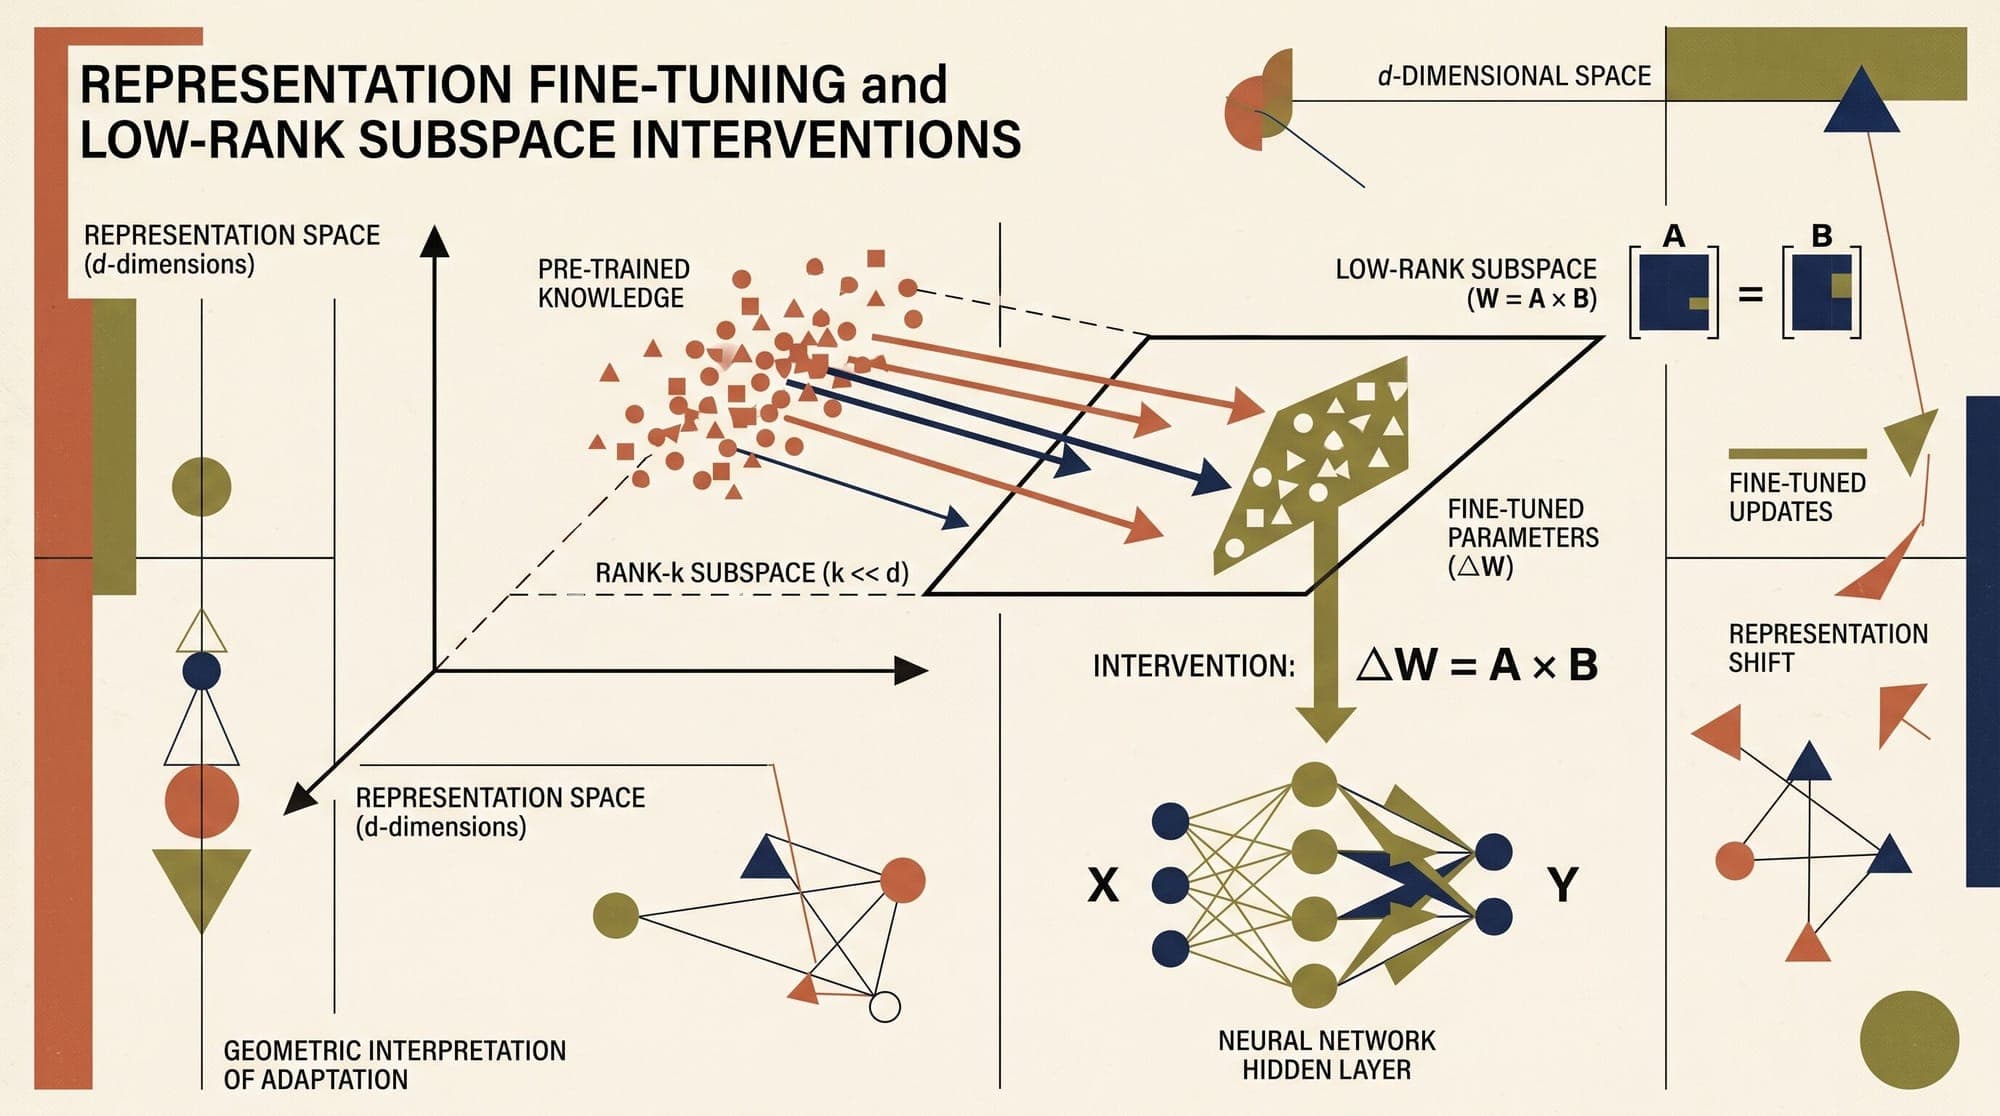
  18. Representation Fine-Tuning (ReFT): Mathematical Foundations, Low-Rank Linear Subspaces, Intervention Operations, and Parameter-Efficient Representation Editing in Large Language Models

    Representation Fine-Tuning (ReFT) introduces a parameter-efficient adaptation paradigm that operates directly on the hidden representations of frozen language models rather than updating or augmenting model weight matrices. Developed by researchers at Stanford University (Wu et al., 2024), ReFT leverages insights from mechanistic interpretability and causal abstraction to steer model behavior through learned low-rank subspace interventions. By editing internal activations at targeted sequence po

    AI
    6 min read
  19. Self-Hosted AI Code Completion Engines in Production: Comparing Tabby, Continue, Refact.ai, and Twinny Architecture, Fill-in-the-Middle Pipelines, AST Context Retrieval, and Serving Latency

    Deploying AI-assisted code completion within air-gapped environments, regulated enterprises, and privacy-conscious engineering teams requires decoupling developer tooling from third-party cloud APIs. While agentic coding systems focus on multi-turn planning and repository-wide refactoring with relaxed latency budgets, inline code completion operates under strict real-time constraints. Developers expect ghost-text suggestions to appear within 100 to 200 milliseconds of pausing keystrokes. Delive

    AI
    7 min read
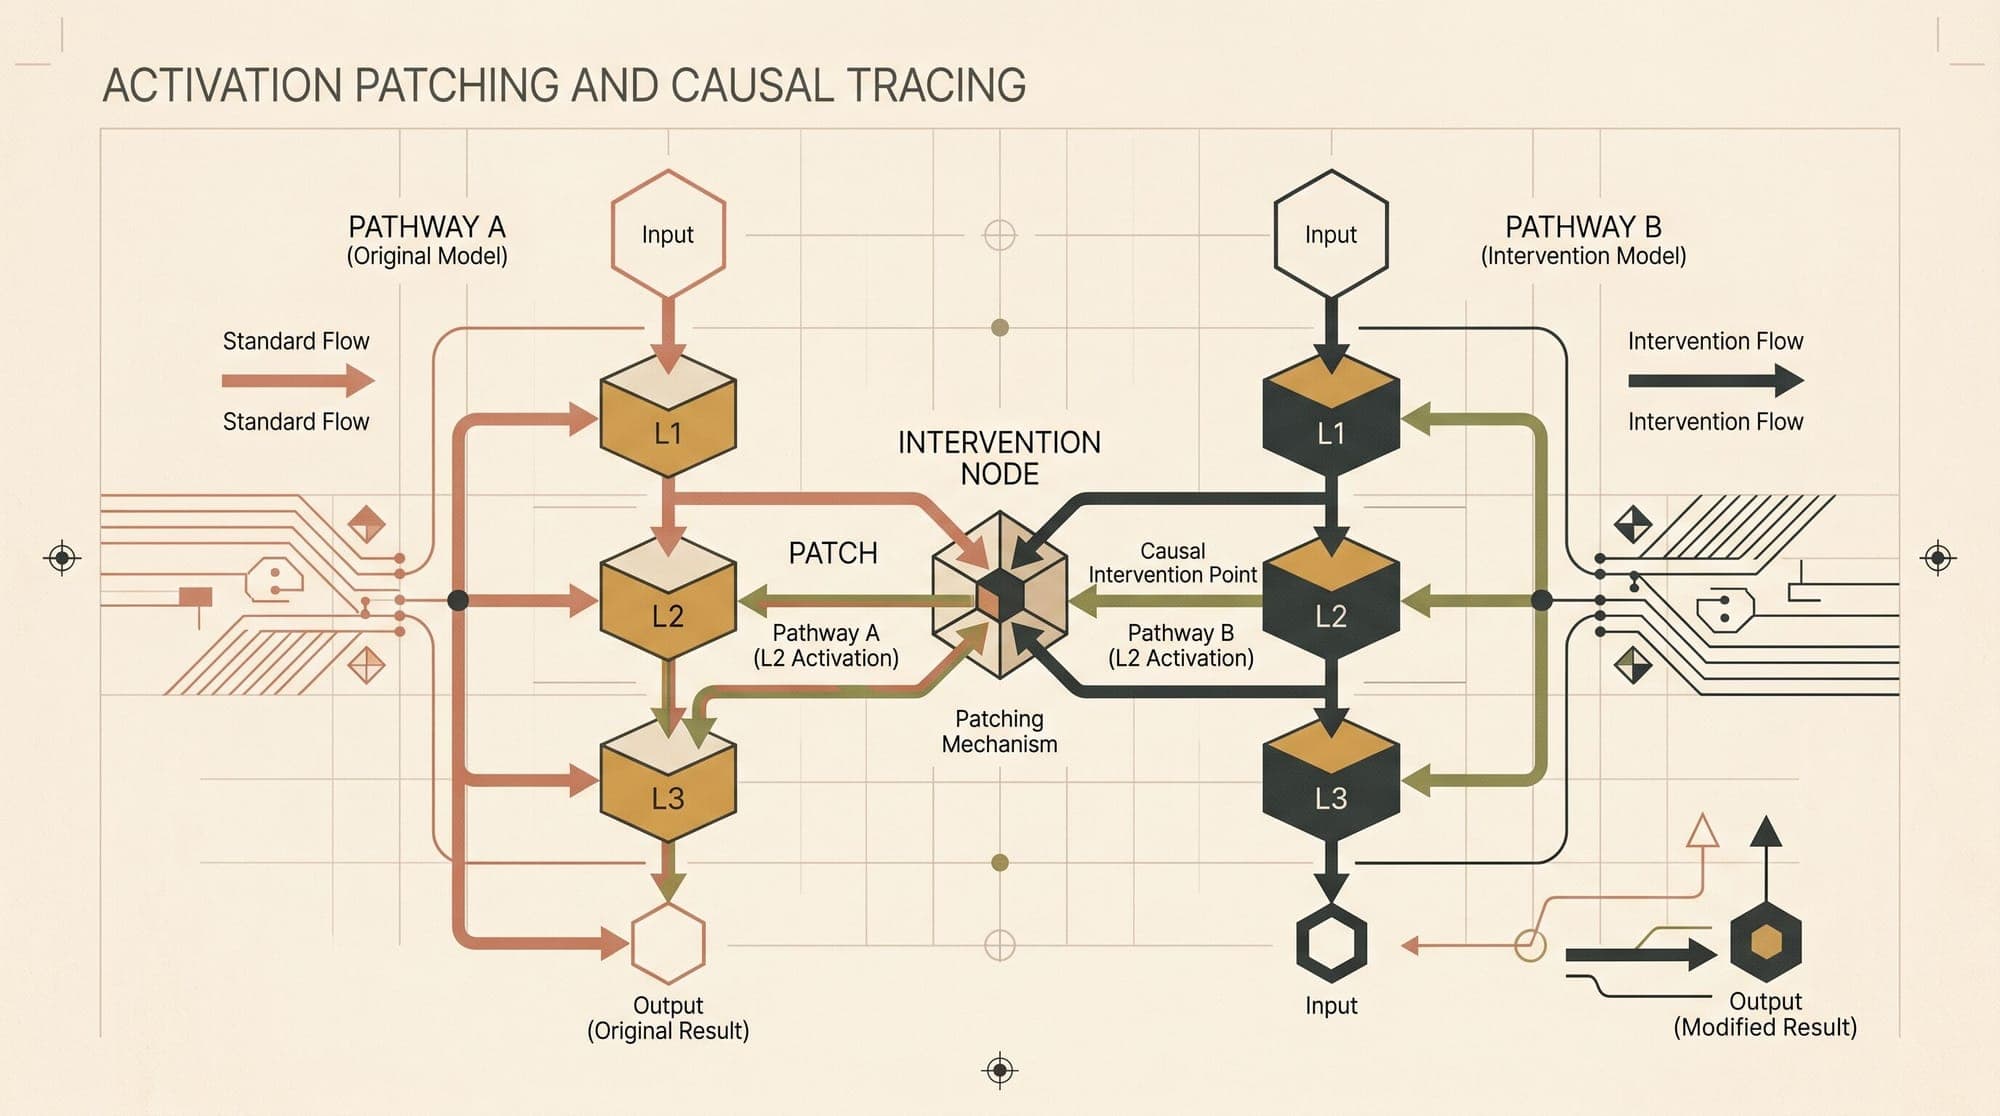
  20. Activation Patching and Causal Tracing: Mathematical Foundations, Counterfactual Interventions, and Circuit Discovery in Large Language Models

    Activation Patching and Causal Tracing: Mathematical Foundations, Counterfactual Interventions, and Circuit Discovery in Large Language Models Mechanistic interpretability aims to reverse-engineer the computational graphs implemented by trained neural networks into human-understandable algorithms. In autoregressive Transformer models, standard observational tools such as attention map visualization and linear probing often fail to distinguish between active computational paths and passive corre

    Education
    8 min read