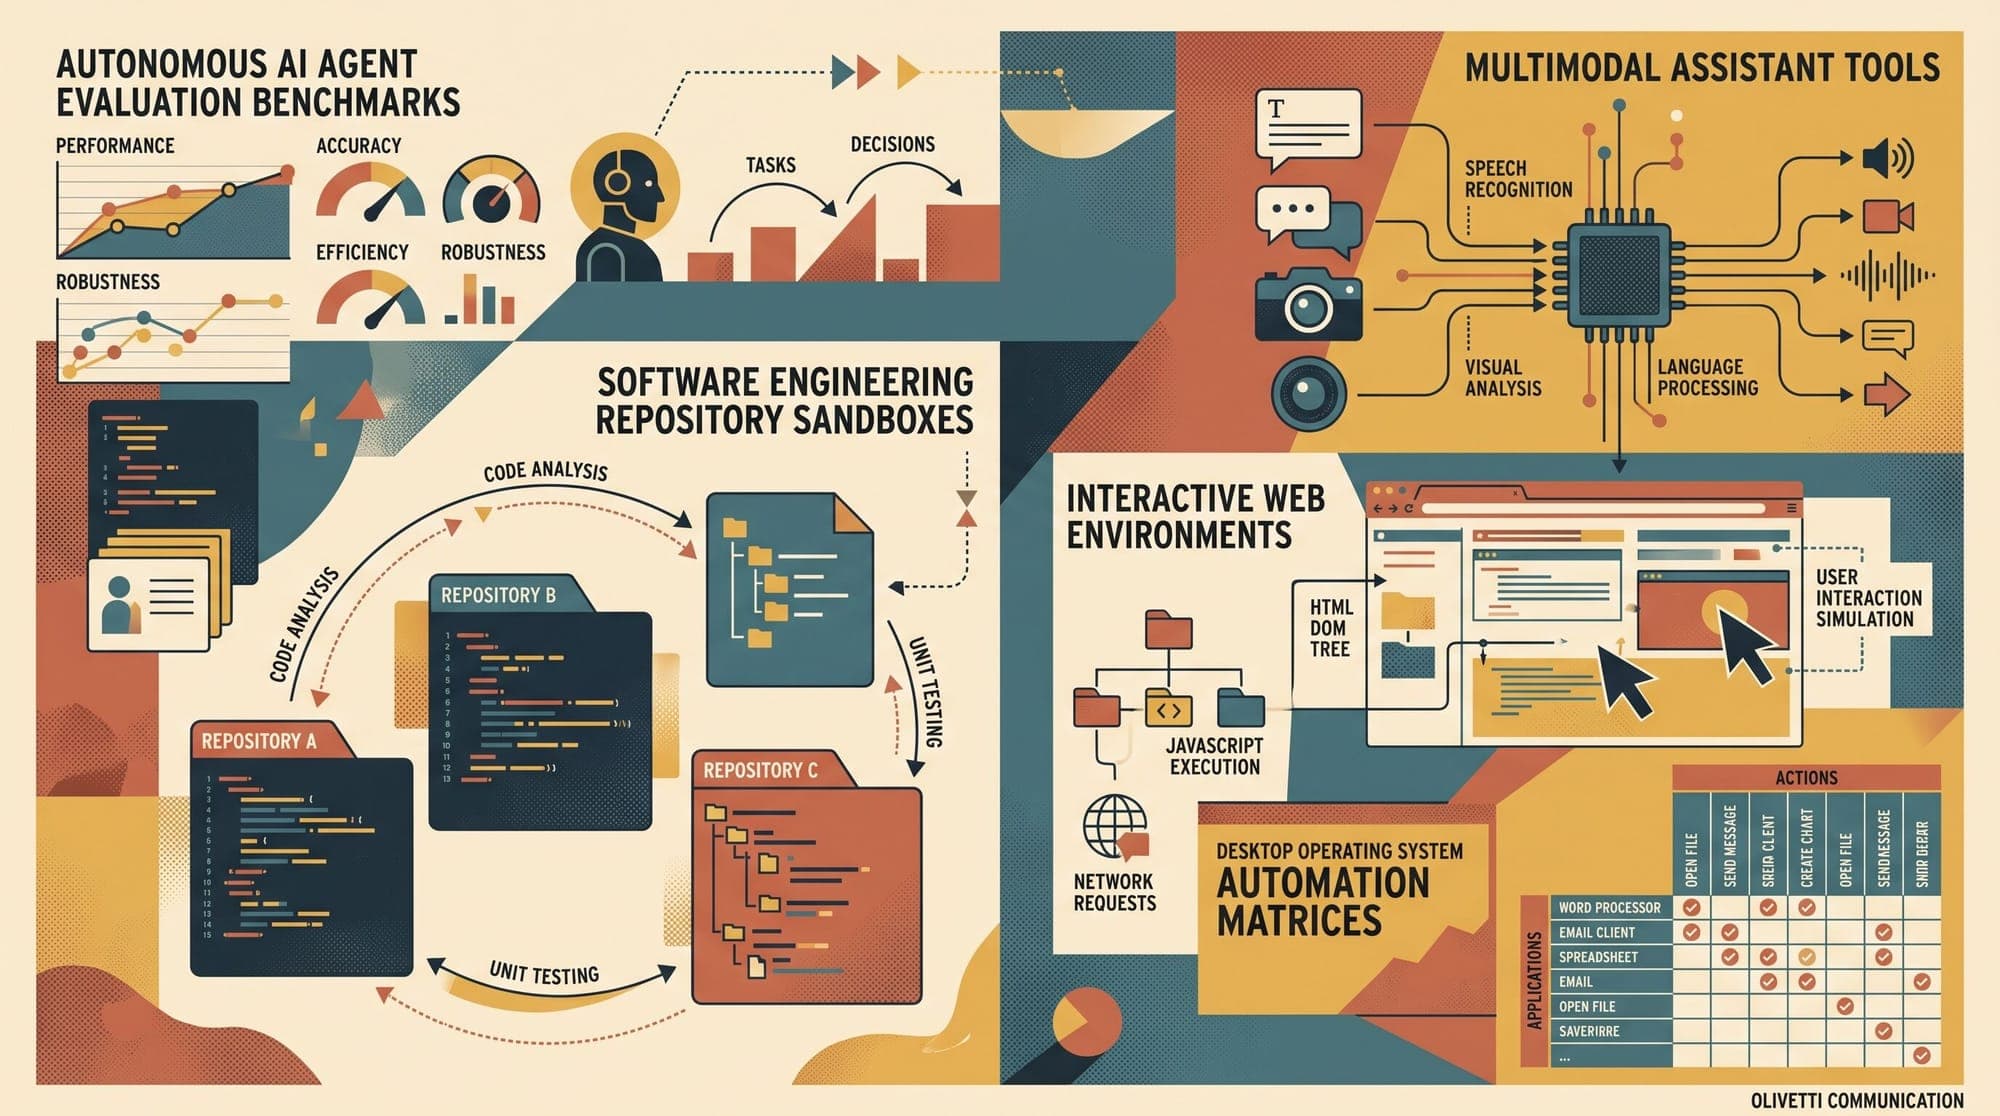
Agent Evaluation Benchmarks in Production: Comparing SWE-bench, GAIA, WebArena, and OSWorld
Evaluating autonomous AI agents requires a fundamental departure from static language model evaluation. While benchmarks like MMLU, GSM8K, and HumanEval measure single-turn next-token prediction on fixed prompts, they fail to evaluate the closed-loop failure modes of autonomous agents. Real-world agents must formulate multi-step plans, execute tool calls, ingest dynamic environment feedback, recover from syntax and runtime errors, and mutate external state across long interaction trajectories.