Post-Training RL Frameworks in Production: Comparing verl, OpenRLHF, TRL, and DeepSpeed-Chat Architecture, Distributed Scheduling, and Serving Trade-Offs
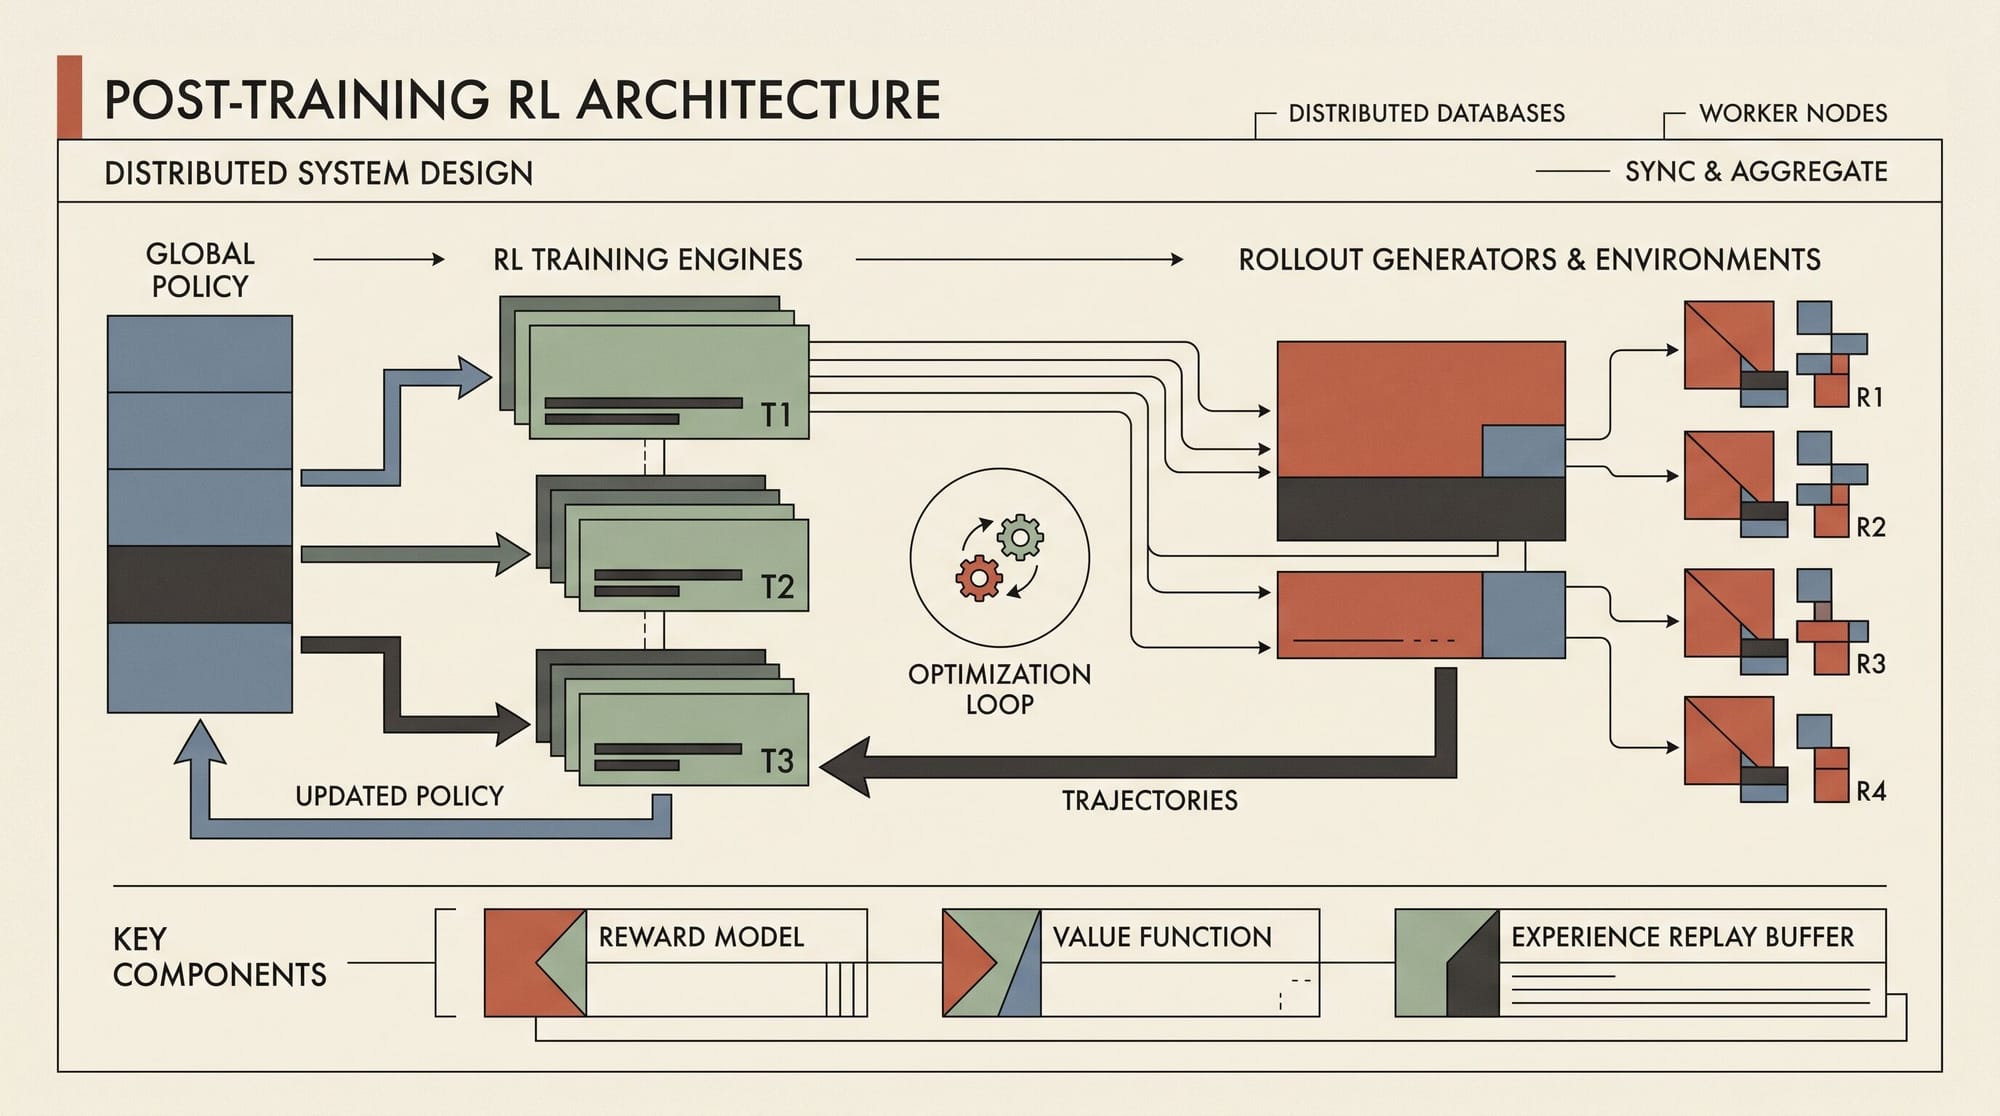
Post-training reinforcement learning (RL) has replaced standard supervised fine-tuning (SFT) as the primary mechanism for frontier model alignment and reasoning expansion. Whether running classic Proximal Policy Optimization (PPO), Direct Preference Optimization (DPO), Group Relative Policy Optimization (GRPO), or Reinforcement Learning with Verifiable Rewards (RLVR), modern post-training pipelines introduce an execution pattern distinct from standard pre-training: they alternate between high-th