Anthropic Reports 90% to 99% Drop in Reasoning Distillation Extractions Under New Safeguards
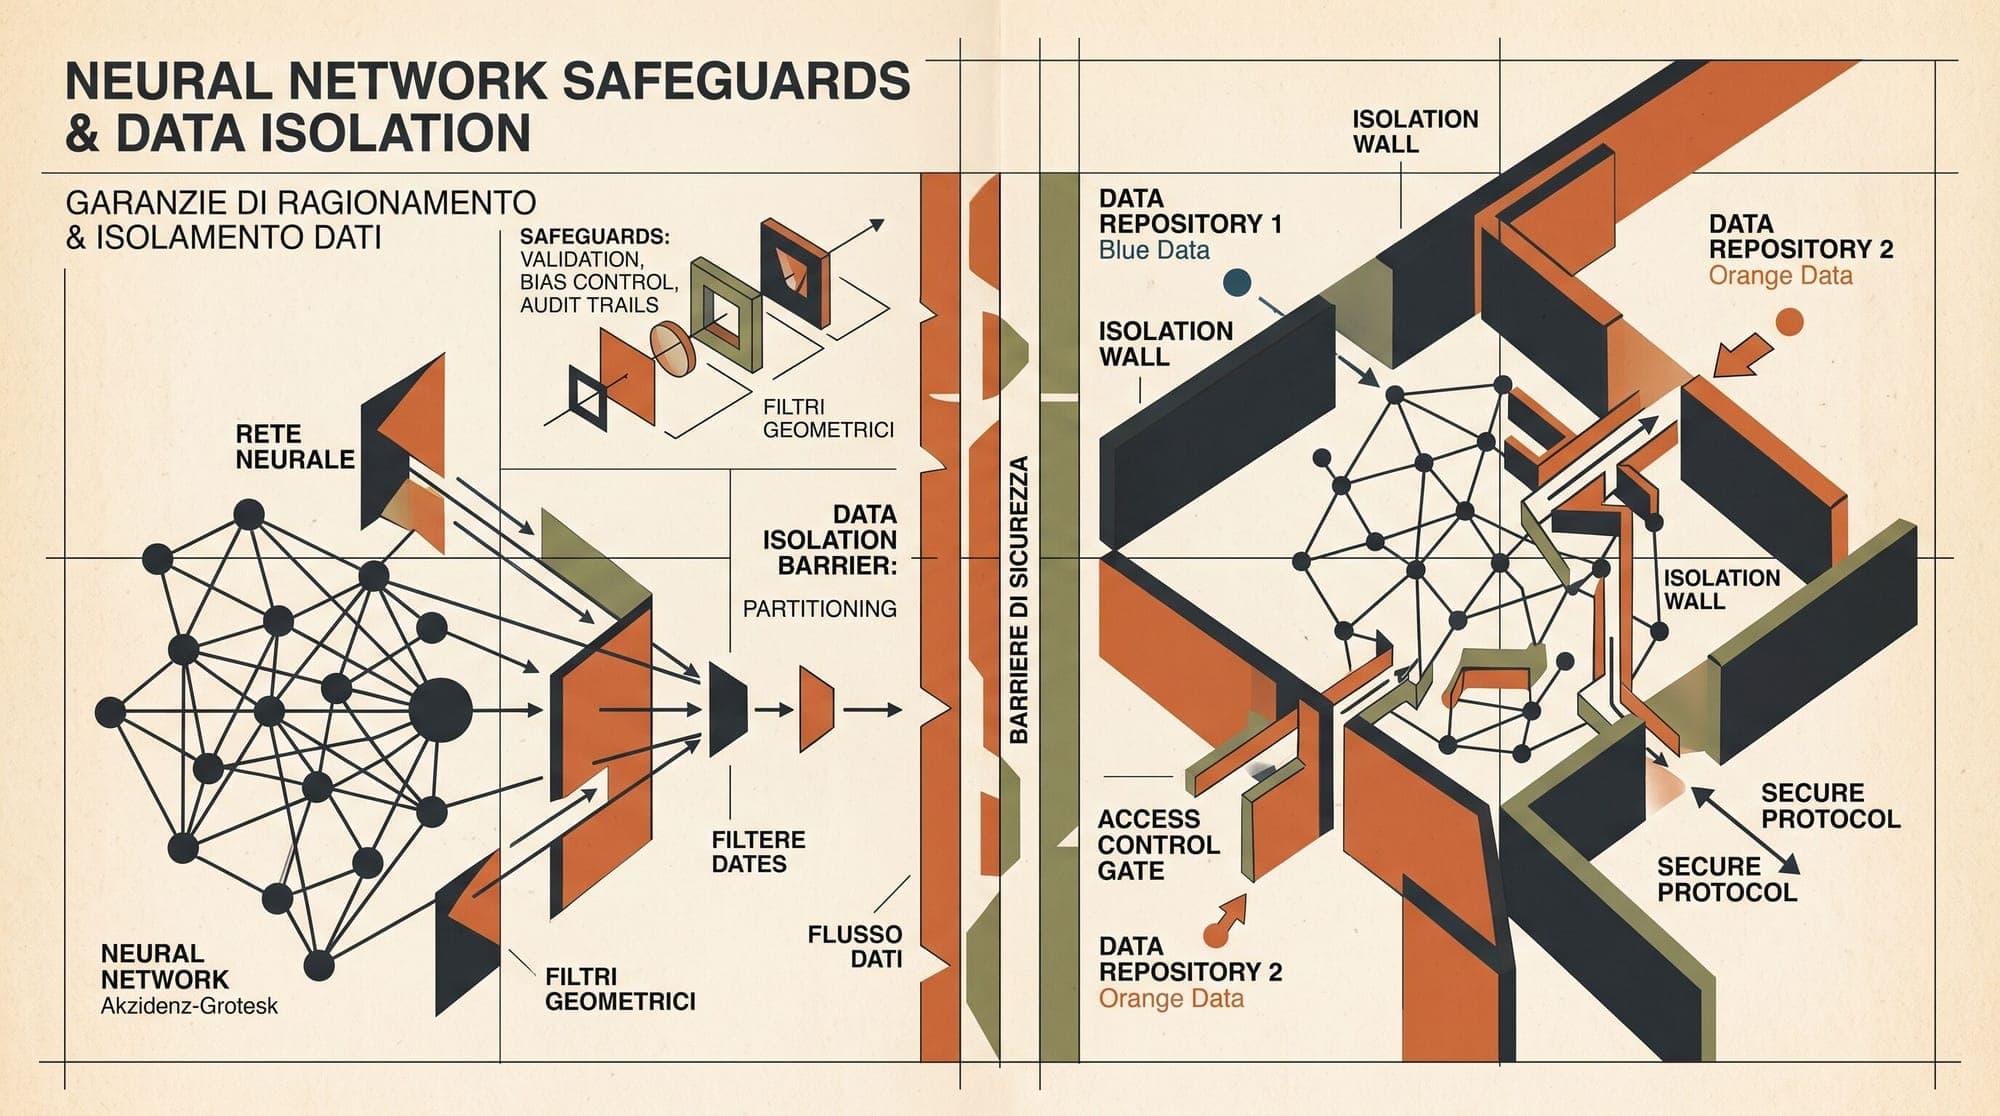
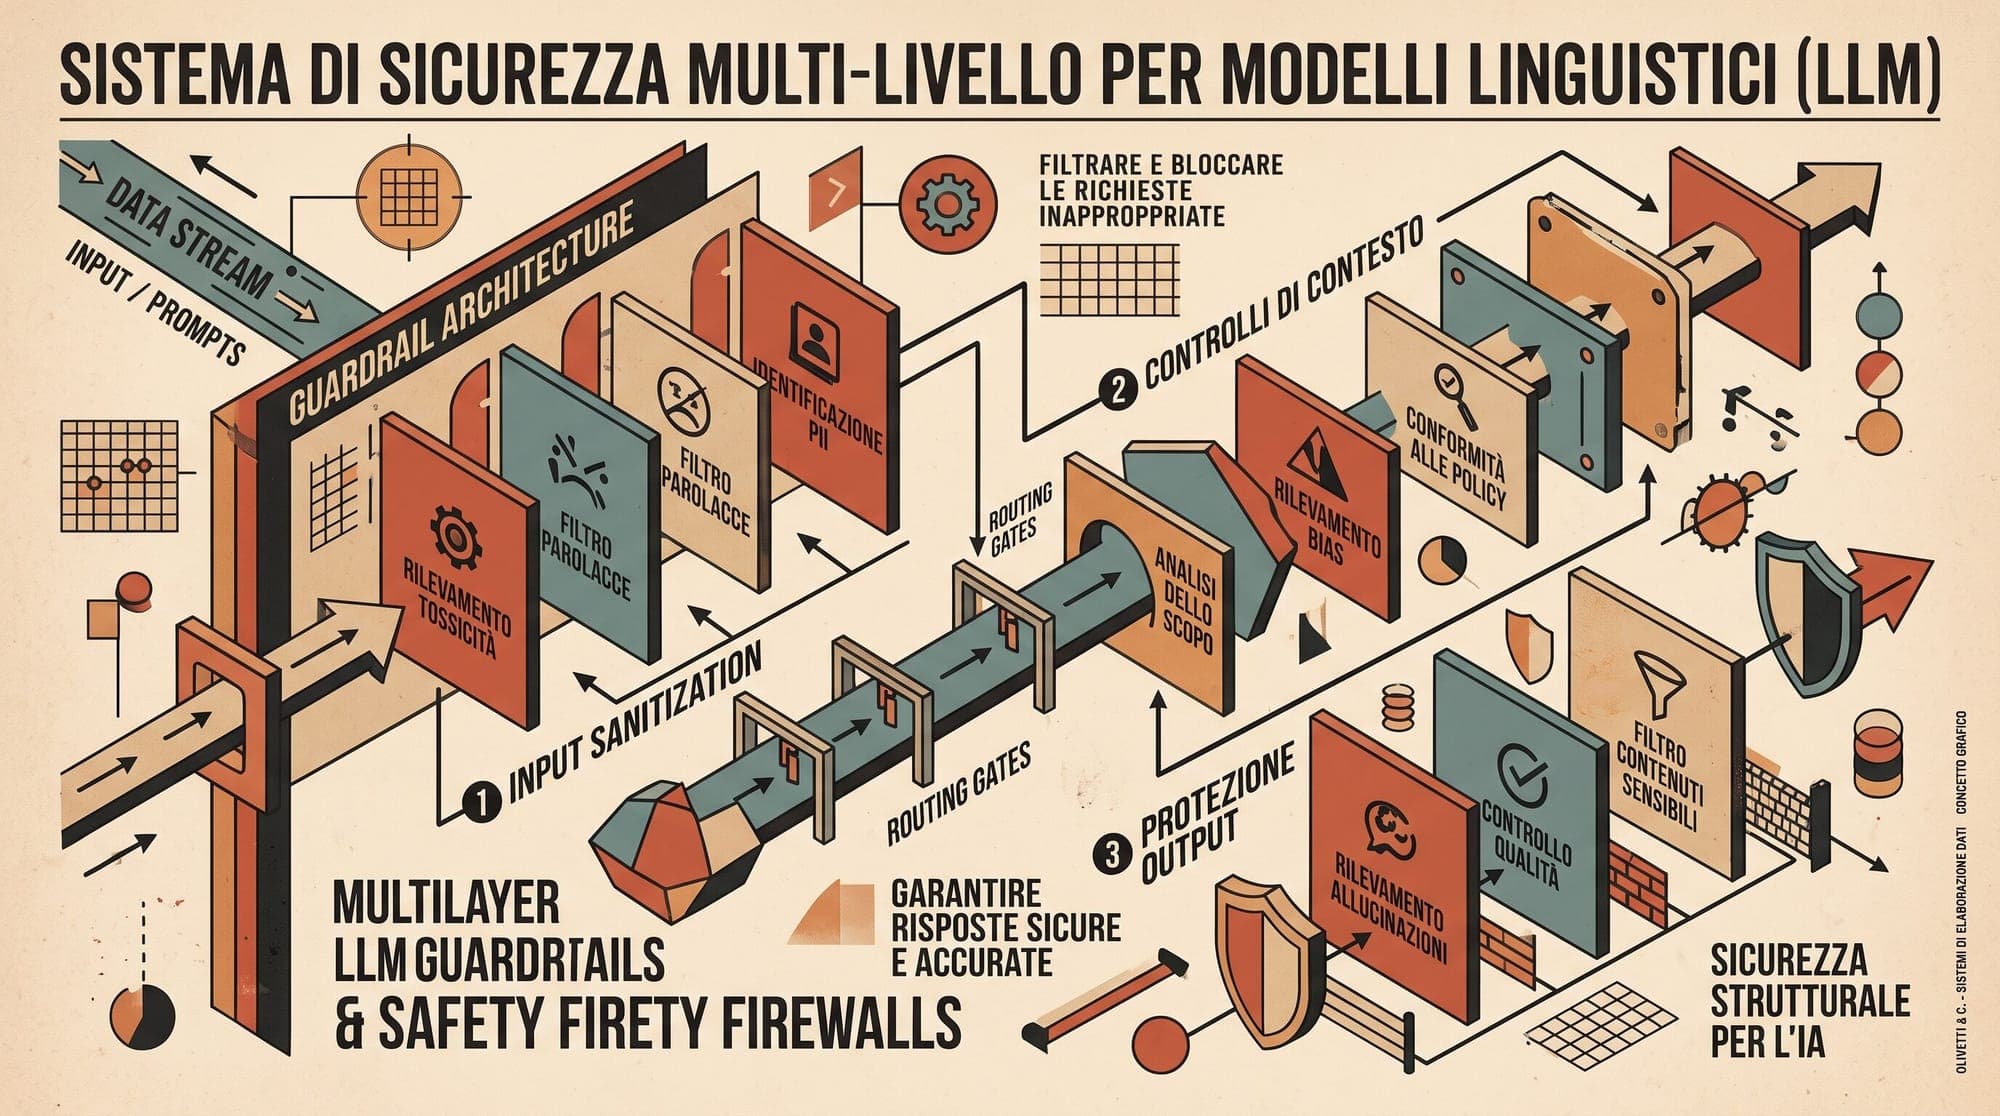
Anthropic has published technical findings detailing its multi-layered defense system against model distillation attacks, reporting a 90% to 99% reduction in reasoning tokens extracted by unauthorized actors. The safeguards combine architectural context locking, multi-stage constitutional classifiers, and aggressive account-level enforcement to protect frontier reasoning chains from being replicated into unaligned or foreign models. Model distillation involves systematically querying a high-cap