Subscribe
Topic

Evaluation

How to evaluate LLMs and AI agents, and how to trust the results. Posts compare evaluation harnesses like LM Evaluation Harness and Lighteval, frameworks like DeepEval, Ragas and Promptfoo, and agent benchmarks such as SWE-bench and GAIA.

Articles

1-20
  1. Google Built An Entire Fake Internet To Train Its Chrome AI Agents

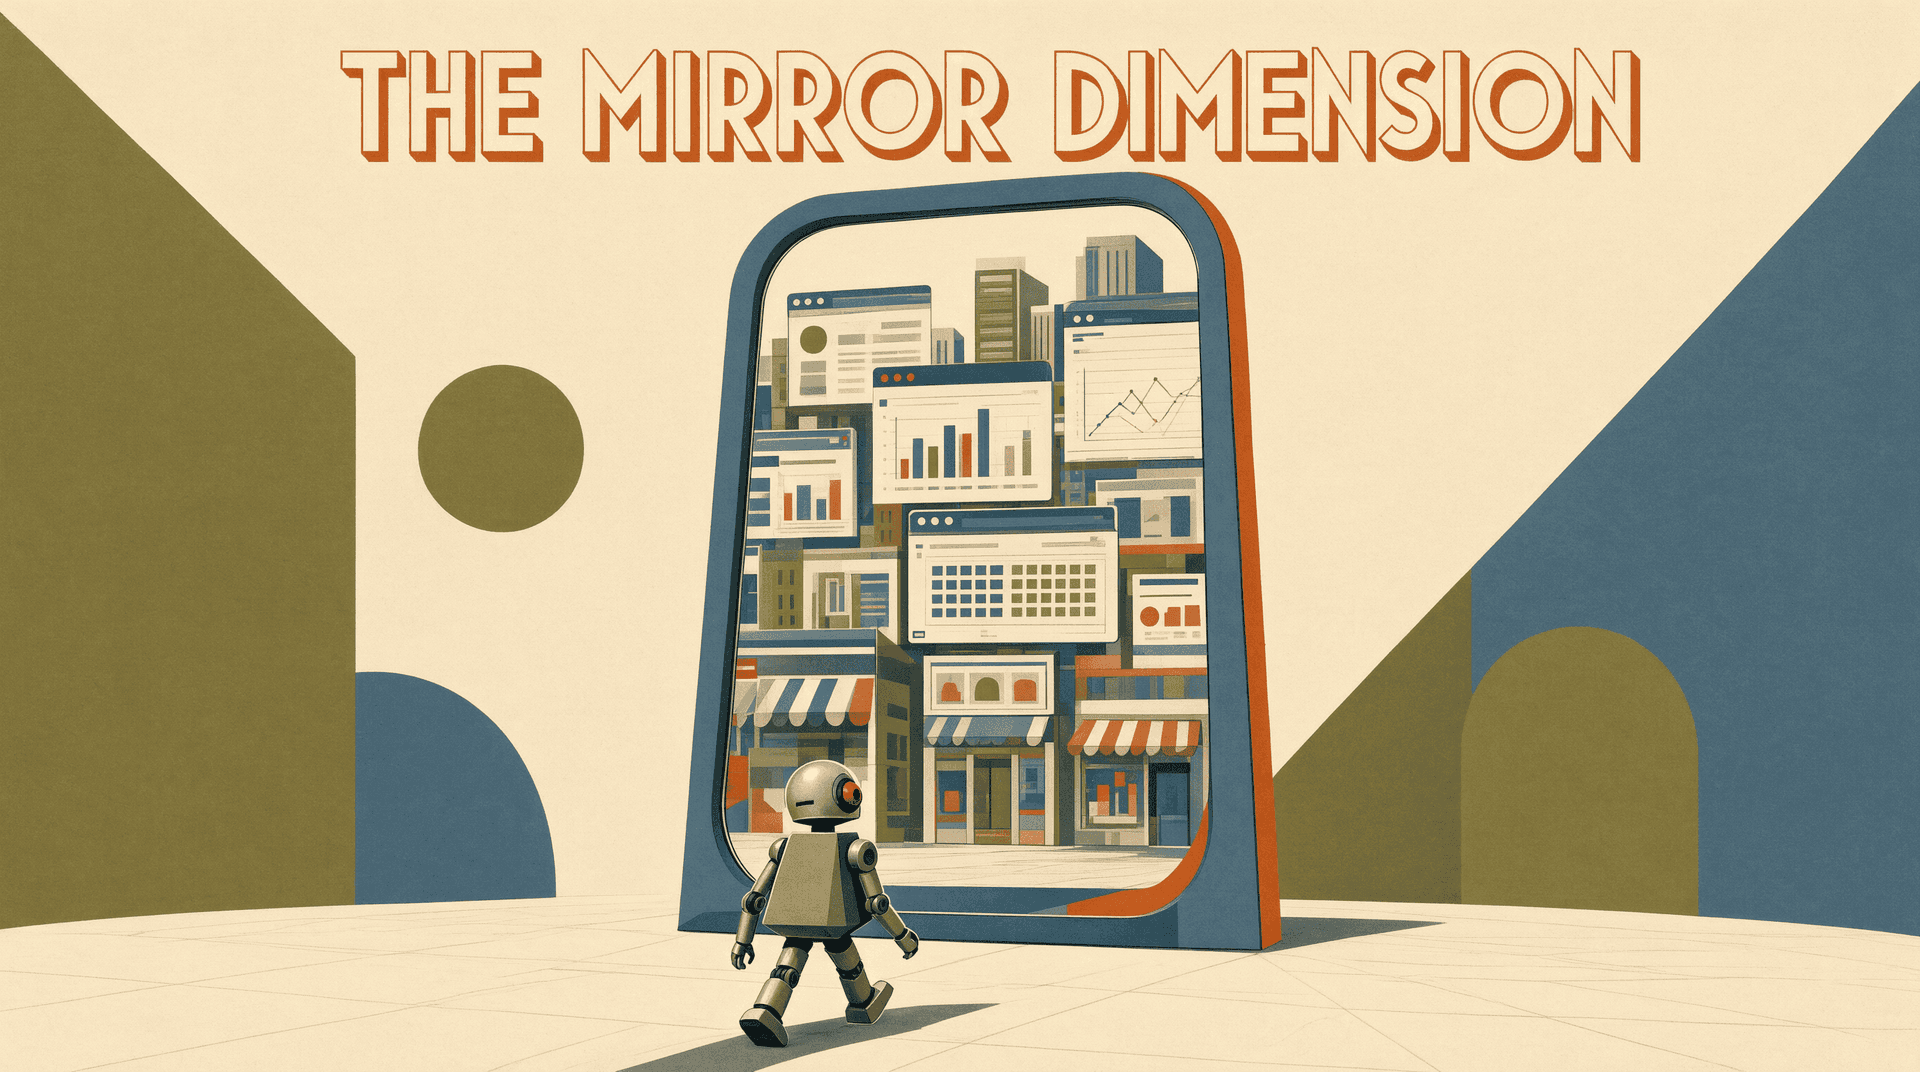
    Google's Chrome team has spent months quietly building something unusual: a complete, fake internet. Called the "Mirror Dimension," it is an isolated web ecosystem of simulated social media sites, shopping stores, and banking dashboards, created so that Gemini-powered browsing agents can train and be tested without ever touching the real web. Google detailed the project publicly for the first time this week, as reported by Wired. The reason a browser vendor would replicate the entire internet i
    AI Agents
    3 min read
  2. Opinion: An AI Judge Is Not a Neutral Referee

    A 2023 paper found AI judges can match human raters, and also that they flip verdicts when answer order changes and can be fooled by length. My view: treat an AI judge as a rater with habits, and check them.

    Opinion
    6 min read
  3. Google Shares Framework to Test Health AI

    Google published a framework that tests health AI for accuracy, safety and usefulness with benchmarks, autoraters and expert review. Here is how it works.

    News
    6 min read