
On November 7, a post on X claimed that the reasoning behavior of Anthropic's Claude Opus 5.5 changed on November 3, without any change to the model name. About three hours later, another user, @theo, posted his own data arguing the shift was in the summaries of Claude's thinking that Claude Code displays, not in the model itself. Developers are still split. Anthropic has not commented publicly. As of 3:25 AM PT on November 9, no posts on the topic were found from Anthropic's X accounts. Here is what each side says, and what the evidence does and does not show.
What did the viral post claim?
@shanemelaugh posted on November 7: "is Opus 5.5 nerfed? I just had Gemini 4 Argon analyze 1,400 Claude Code sessions and it found that on November 3, something definitely happened. the model name didn't change, but the way it does reasoning took a sharp turn." As of about 3:25 AM PT on November 9, the post had about 2,700 likes and about 468,000 views.
Melaugh's chart, titled "Thinking patterns changed on November 3", says "Same model ID. Same CLI version." It plots the daily share of visible thinking blocks from October 9 to November 7. Blocks starting with "I'm..." rose to 61.3%. Blocks using "I should / I need to" fell to 10.9%. Blocks using dashes fell to 6.5%. The shift is marked at about 18:00 UTC on November 3. The chart's own footer says: "Visible summaries show a behavior shift, not proof of changed model weights."
Did the reasoning summarizer change instead?
@theo, listed in his X bio as CEO of T3 Chat, quoted the post with his own data: "Dug into this more. Anthropic appears to be rolling out a change to the reasoning summarizer on a per-account basis. No sign of degraded capability for me. I think they're just trying to fix the reasoning traces (they've been utter garbage for weeks, complained about this yesterday lol)". His post had about 1,250 likes and 86,000 views as of 3:25 AM PT on November 9.
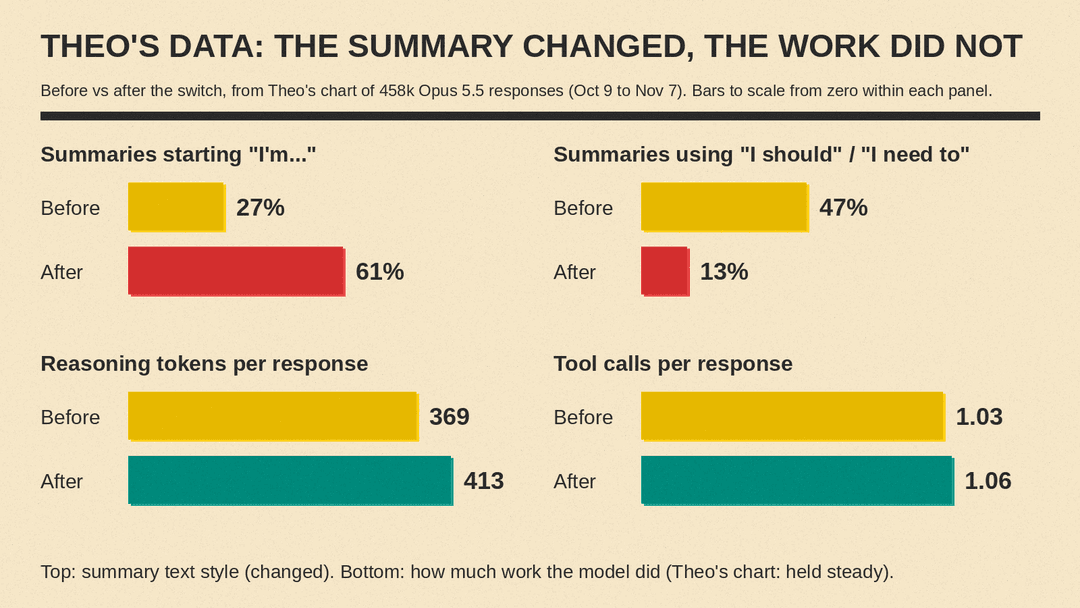
His chart is titled "Opus 5.5's thinking summaries did change. It rolled out account by account. Reasoning volume held steady." It covers 458k Opus 5.5 responses from his Claude Code traffic between October 9 and November 7. Before versus after the switch, summaries starting with "I'm..." went from 27% to 61%, summaries using "I should" or "I need to" went from 47% to 13%, and median summary length went from 325 to 440 characters. What did not change: reasoning tokens per response (369 to 413), reasoning share of output tokens (46% to 49%), output speed (111 to 112 tokens per second), tool calls per response (1.03 to 1.06), and the model ID (claude-opus-5-5) and Claude Code version, which stayed the same.
Theo's accounts switched at different times between October 30 and November 4. One switched on November 3 at 18:00 UTC, the same hour as the viral chart.
What is a thinking summary?
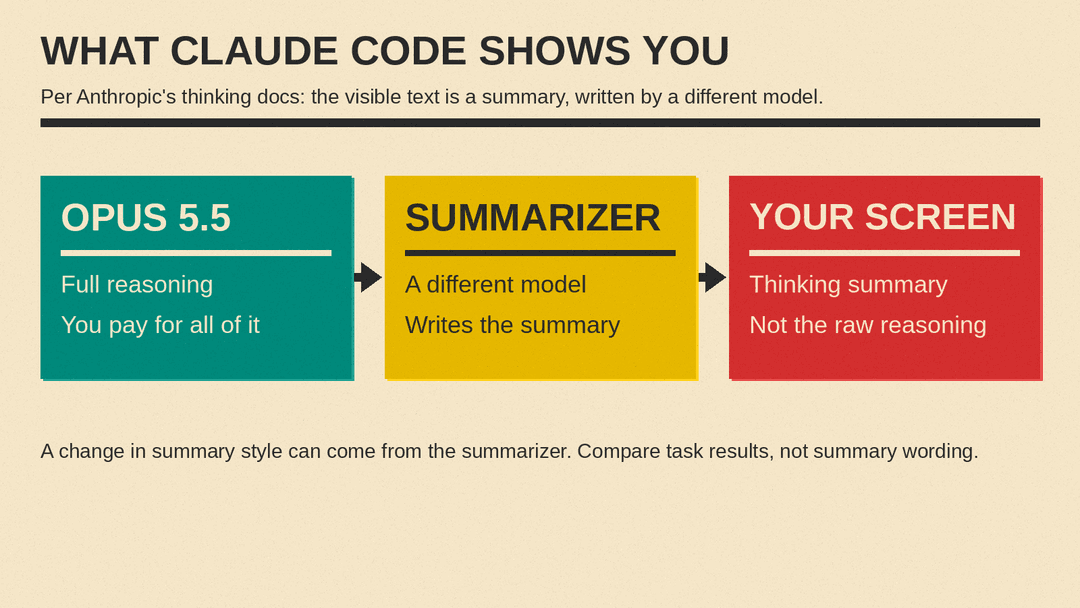
Anthropic's documentation says the text you see "is never the raw chain of thought: the text in a thinking block is a summary of Claude's reasoning". The docs also state that "Summarization is processed by a different model from the one you target in your requests," and that you are charged for the full thinking tokens, not the summary tokens.
So when Claude Code displays reasoning text, that text was written by a separate summarizer model, not by the Opus 5.5 model that did the work. For how thinking tokens work and what they cost, see our reasoning model explainer.
Do people still say Opus 5.5 got worse?
Yes. The Hacker News thread "Is Opus 5.5 nerfed? Thinking patterns changed on November 3" had 209 points and 138 comments as of 3:25 AM PT on November 9.
ghoul2 wrote: "Definitely a significant change. I noticed it in just daily work. Quality of work down, mistakes up, repetitive errors in scripts - rare earlier, now a few every session."
shikck200 wrote: "Token use exploded a week or two ago. I worked for a few hours and hit my 5 hour limit."
Gareth321 wrote: "Obviously they're silently quantising their models or making other efficiency changes."
fai5a1 speculated: "Nerf Opus 5.5, then drop Fable 5.5 just before IPO so it looks better next to its weaker predecessor."
my-huge-pony argued for open models: "Having control over something that writes most of your code is important."
On X, @0xxenonicle wrote: "Since last week I've felt the model getting dumber and dumber for no reason, even with effort set to high."
@garaadrobla checked their own repos and found "last 30 days: 590 commits. 514 co-authored by claude." Of those, 383 came from Sonnet 5.5 and 131 from Opus 5.5. The post added: "the model nobody's fighting about writes most of my code."
Who doubts the nerf claims?
sunaookami wrote on Hacker News: "It's just a new summarizer, the model and performance itself is unchanged." kolinko replied: "+1, this tells nothing about the quality. Or even whether this is an upgrade or downgrade."
orbital-decay wrote: "This is not real model's reasoning chain, they might have just replaced or tuned the model that summarizes it. If you want to track actual degradation you need to run evals."
yfontana, replying to Gareth321, wrote: "Probably because those "nerfs" do not show on sites that track model performance over time." user43928 also replied to Gareth321: "When OpenAI and Anthropic engineers post here on HN that they do not quantize models and silently replace checkpoints in the API, I believe them."
walthamstow wrote: "I'm skeptical about nerfing. Are we saying they are instructing AWS to nerf the version of the model they're running on Bedrock? If they did, there's no way that remains a secret."
bandrami joked that novelty wears off: "That's why people think the models are getting nerfed after a couple of weeks; it's actually their endocrine system getting nerfed."
On X, @nokoxyz posted a restyled chart with the same figures as Melaugh's (61.3%, 10.9% and 6.5%), described as their own check of 1,400 Claude Code sessions, and wrote: "this shows it thinks in a different style now. it doesn't prove it got dumber." A reply from @MrOcelot1976 gave a verdict of "not proven" and argued that changes to the Claude Code app itself were not ruled out. The reply said it was written by Opus 5.5: "I'm Opus 5.5, so this is me checking a claim about myself."
How can you check Opus 5.5 yourself?
This dispute shows why visible thinking text is a weak signal. That text comes from a separate summarizer model, so a change in its style does not show a change in the model doing the work. Evals or test results are better evidence.
If you want your own answer, run your own tests. Give Opus 5.5 a fixed set of real tasks and compare results, not the summary text. Theo's data separates the two kinds of measurements: in his traffic, summary style changed, while reasoning tokens per response went from 369 to 413 and tool calls per response from 1.03 to 1.06. As of 3:25 AM PT on November 9, Anthropic has not commented publicly, so there is no official explanation to check against.
Sources
- Shane Melaugh post
- Theo post
- Anthropic documentation on thinking
- nokoxyz post
- MrOcelot1976 reply
- Hacker News thread
- sunaookami comment
- kolinko comment
- orbital-decay comment
- ghoul2 comment
- shikck200 comment
- Gareth321 comment
- yfontana comment
- user43928 comment
- walthamstow comment
- bandrami comment
- fai5a1 comment
- my-huge-pony comment
- 0xxenonicle post
- garaadrobla post
