Subscribe
Topic / page 2

Engineering

Articles, page 2

21-40
  1. Virtual Memory for AI Agents in Production: Context Window Paging, Working Set Estimation, and Hierarchical Storage Architectures

    Virtual Memory for AI Agents in Production: Context Window Paging, Working Set Estimation, and Hierarchical Storage Architectures As autonomous AI agents shift from single-turn chat interactions to long-horizon workflows spanning days, weeks, or millions of execution steps, managing context has become the primary operational bottleneck. While modern foundation models support nominal context windows ranging from 128k to over 1M tokens, treating the active context window as an unbounded append-on
    AI
    9 min read
  2. Semantic Memory Consolidation in Production AI Agents: Architecture, Episodic Decay Curves, and Procedural Knowledge Distillation

    Long-running autonomous AI agents accumulate hundreds of interaction turns, tool executions, and environment observations across extended deployments. Naive implementations store these raw episodic traces directly in vector databases, retrieving past interactions via dense semantic similarity. In production, this append-only strategy degrades quickly: retrieval queries surface outdated facts, contradictory state assertions pollute prompt context, and the agent fails to extract generalizable prob

    AI
    7 min read
  3. Tabular RAG in Production: Table Serialization, Row-Column Chunking, NL-to-SQL Hybridization, and Dense Entity Linking

    Tabular RAG in Production: Table Serialization, Row-Column Chunking, NL-to-SQL Hybridization, and Dense Entity Linking Standard Retrieval-Augmented Generation (RAG) architectures excel when indexing unstructured prose. Dense semantic embeddings, recursive character chunking, and bi-encoder vector similarity match user queries against passages that follow linear syntactic structures. However, when these pipelines encounter tabular data (such as financial statements, medical registries, inventory

    AI
    7 min read
  4. Compound AI Systems in Production: Architecture, Co-Optimization, and Error Cascades

    Compound AI Systems in Production: Architecture, Co-Optimization, and Error Cascades For the first two years following the release of GPT-4, enterprise AI development focused almost exclusively on model-centric scaling: upgrading to larger parameter checkpoints, expanding prompt context windows, and tuning system prompts. However, production deployments quickly revealed a fundamental constraint: single, monolithic foundation models exhibit diminishing returns on high-complexity, multi-step task

    AI
    7 min read
  5. Vector Compression in Production Search: Comparing SQ, PQ, and RaBitQ Architecture, Recall Retention, and Memory Economics

    In production Retrieval-Augmented Generation (RAG) systems and enterprise search platforms, storing raw floating-point embedding vectors in RAM quickly encounters hard hardware limits. A dataset of 100 million 1536-dimensional embeddings stored in FP32 requires over 614 GB of high-speed memory solely for vector coordinates, before accounting for index graph structures like HNSW or DiskANN. To scale similarity search to billions of vectors while keeping indices memory-resident, production vector

    AI
    4 min read
  6. Context Structuring and Attention Placement in Long-Context LLMs: Mitigating Position Bias, Attention Dispersion, and Information Loss in Production

    Context Structuring and Attention Placement in Long-Context LLMs: Mitigating Position Bias, Attention Dispersion, and Information Loss in Production Modern foundation models support context windows ranging from 128,000 to over 2,000,000 tokens. Serving runtimes and API gateways routinely process entire codebases, multi-year financial statements, and sprawling legal filings in a single inference call. However, supporting a nominal sequence length does not guarantee that a transformer can effecti

    Architecture
    8 min read
  7. Continuous Evaluation and Golden Dataset Curation in Production LLM Systems: Architecture, Log Mining, Synthetic Perturbation, and Semantic Drift Quality Gates

    Continuous Evaluation and Golden Dataset Curation in Production LLM Systems: Architecture, Log Mining, Synthetic Perturbation, and Semantic Drift Quality Gates In production machine learning systems, offline benchmarks suffer from rapid entropy. While engineering teams frequently launch LLM applications backed by static test suites (curated CSVs of 50 to 100 sample prompts, academic benchmarks like MMLU, or synthetic question-answer pairs), these static datasets fail to predict real-world produ

    AI
    7 min read
  8. Prompt Caching Across Cloud LLM Providers: Architecture, TTL Lifecycles, and Economic Break-Even for Anthropic, OpenAI, Gemini, and DeepSeek

    The primary latency and computational bottleneck in large language model inference is the prefill phase. When an application submits a request containing thousands of tokens of static system instructions, OpenAPI tool schemas, few-shot demonstrations, and retrieved document context, the inference server must process all input tokens through every transformer layer before generating the first output token. In high-concurrency production environments, repeating this full forward pass across identi

    LLM
    8 min read
  9. Active RAG in Production: Dynamic Triggering, Forward-Looking Queries, and Interleaved Retrieval Architectures

    Standard Retrieval-Augmented Generation (RAG) relies on a static, single-shot execution model: the system takes a user prompt, executes a vector or hybrid search upfront, prepends the retrieved chunks into the prompt context, and executes autoregressive generation. While this pattern suffices for short question-answering workloads, it breaks down systematically in complex, long-horizon generation tasks such as comprehensive technical reports, multi-step agent trajectories, and iterative problem

    AI
    6 min read
  10. Dynamic Tool Synthesis in Production AI Agents: Architecture, AST Validation, Sandboxed Execution, and Lifecycle Governance

    Dynamic Tool Synthesis in Production AI Agents: Architecture, AST Validation, Sandboxed Execution, and Lifecycle Governance Standard tool-augmented AI agents rely on pre-configured, static API registries. Developers define a fixed set of JSON schemas, OpenAPI specifications, or Python wrapper functions at build time, and the language model selects from this catalog during execution. While sufficient for narrow, deterministic tasks, static registries encounter severe operational bottlenecks in o

    AI
    9 min read
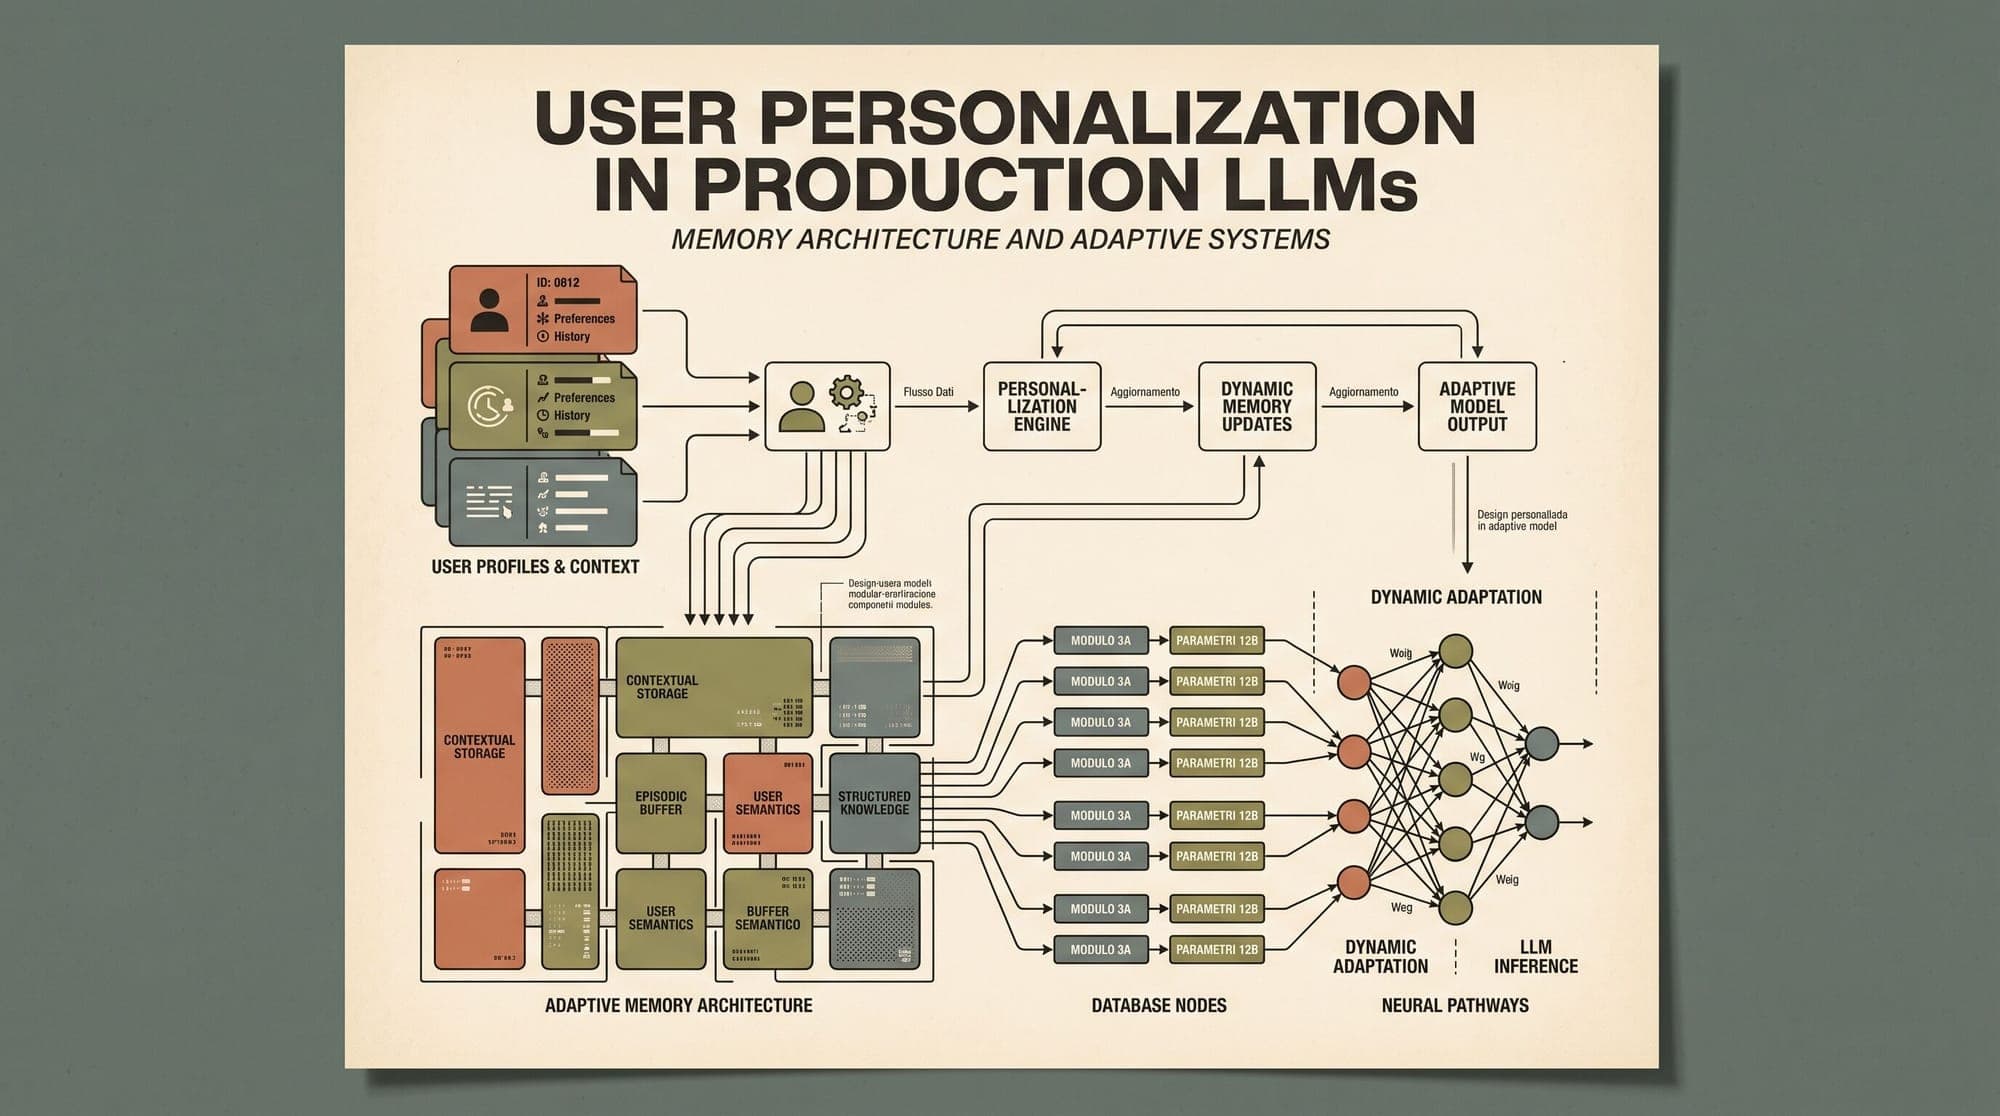
  11. Long-Term User Personalization in Production LLMs: Architecture, Dynamic Profiling, and Privacy Boundaries

    Standard conversational AI deployments treat each user session as an isolated interaction or rely on naive sliding-window context histories. While extending context windows allows models to process thousands of tokens from previous turns, stuffing raw conversational history into prompt contexts introduces severe serving inefficiencies, inflates token economics, and fails to synthesize stable user profiles over time. Deploying long-term personalization in production large language model (LLM) ap

    AI
    5 min read
  12. Fill-in-the-Middle (FIM) and Inline Code Completion in Production: Architecture, Prefix-Suffix Context Windows, Speculative Decoding, and Sub-50ms Serving Latencies

    Fill-in-the-Middle (FIM) and Inline Code Completion in Production: Architecture, Prefix-Suffix Context Windows, Speculative Decoding, and Sub-50ms Serving Latencies Inline code completion is the most latency-sensitive deployment of large language models in production software engineering. Unlike conversational assistants or background agentic batch jobs, inline code completion operates directly inside an active editor typing loop. Developers type at speeds ranging from 40 to 120 words per minut

    AI
    7 min read
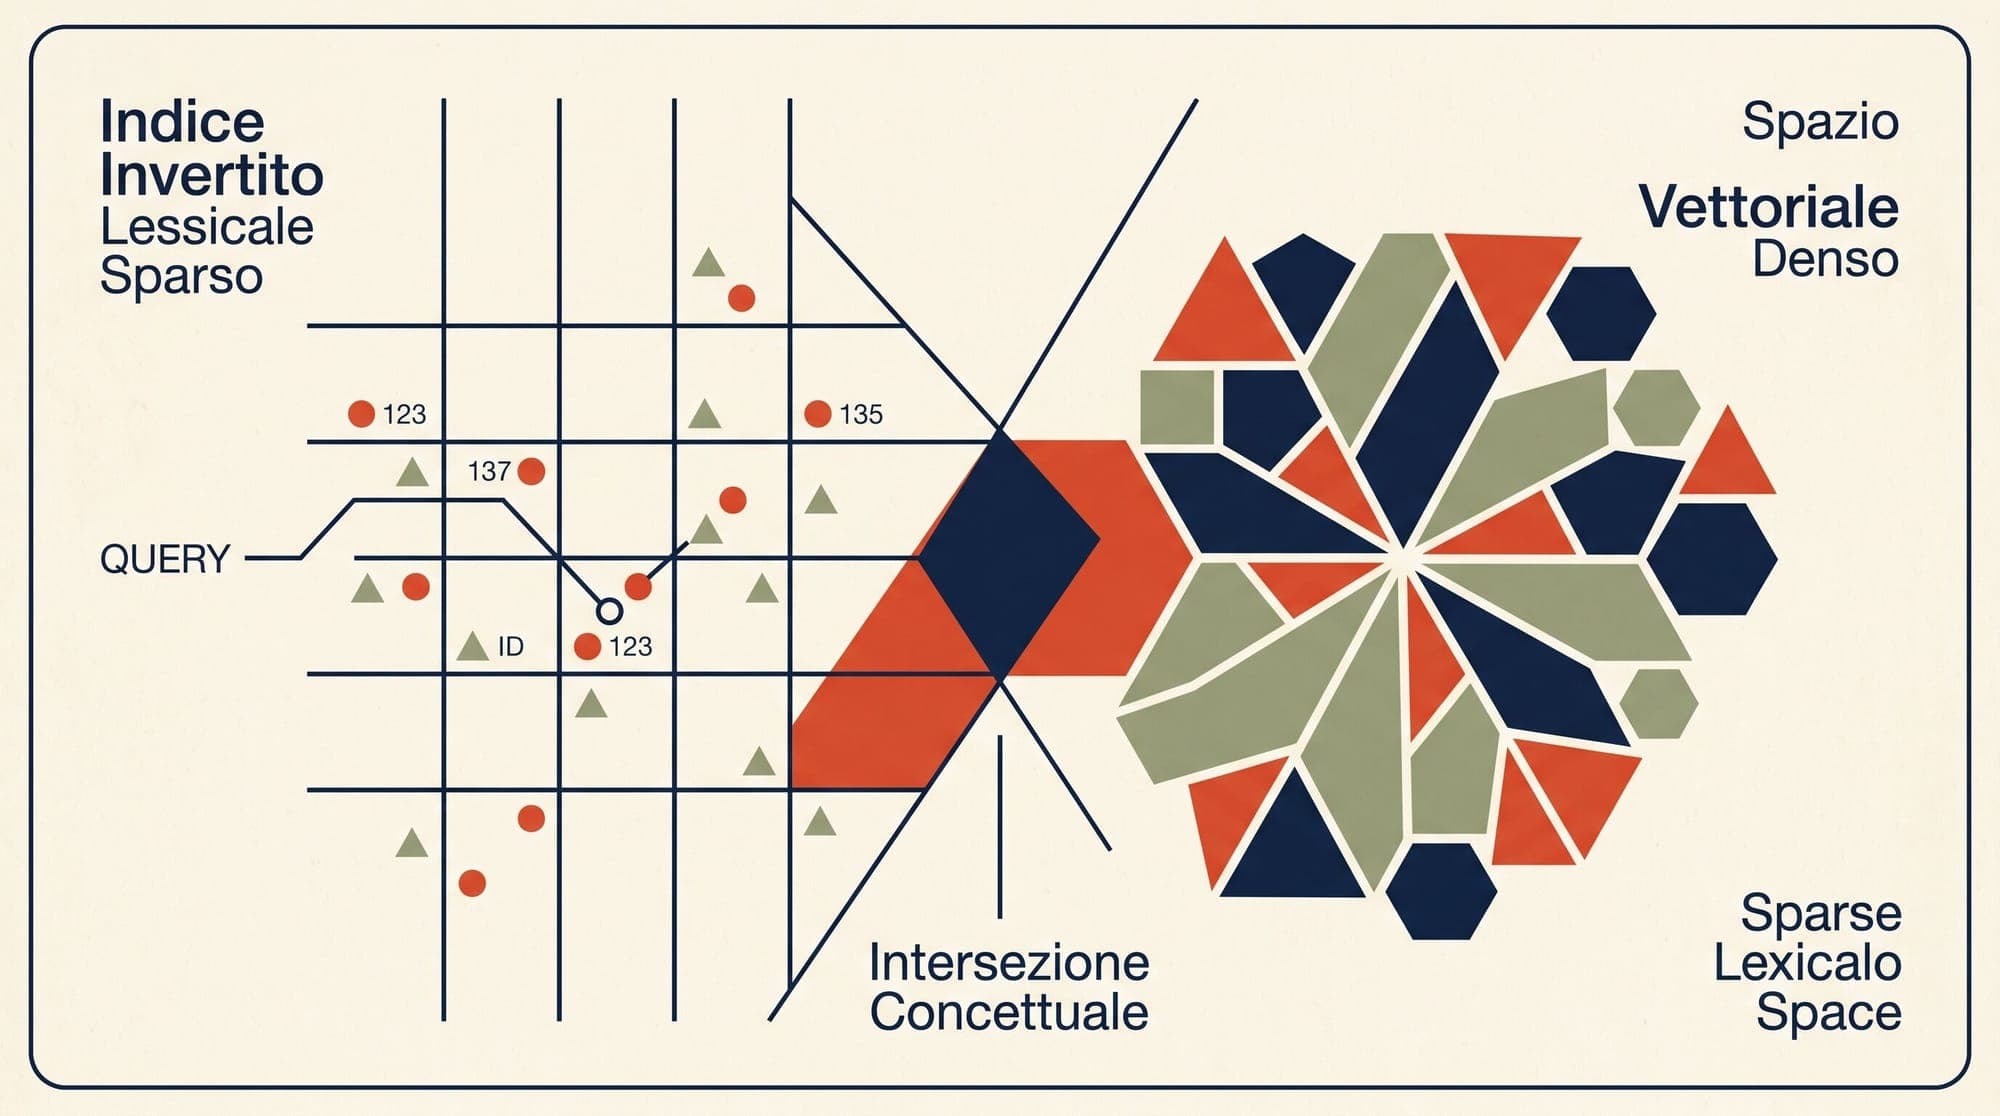
  13. Sparse-Dense Hybrid Retrieval in Production: Learned Lexical Weights, SPLADE vs. BGE-M3, Inverted Index Pruning, and Serving Economics

    Modern Retrieval-Augmented Generation (RAG) and enterprise search architectures increasingly encounter the operational limits of pure dense vector search. Dense bi-encoders project text passages into continuous latent spaces (typically 768 to 3,072 dimensions). While dense representations excel at conceptual matching and paraphrasing, they systematically struggle with exact keyword precision, rare alphanumeric tokens, product SKUs, and domain-specific jargon. Furthermore, serving dense vectors a

    Retrieval
    6 min read
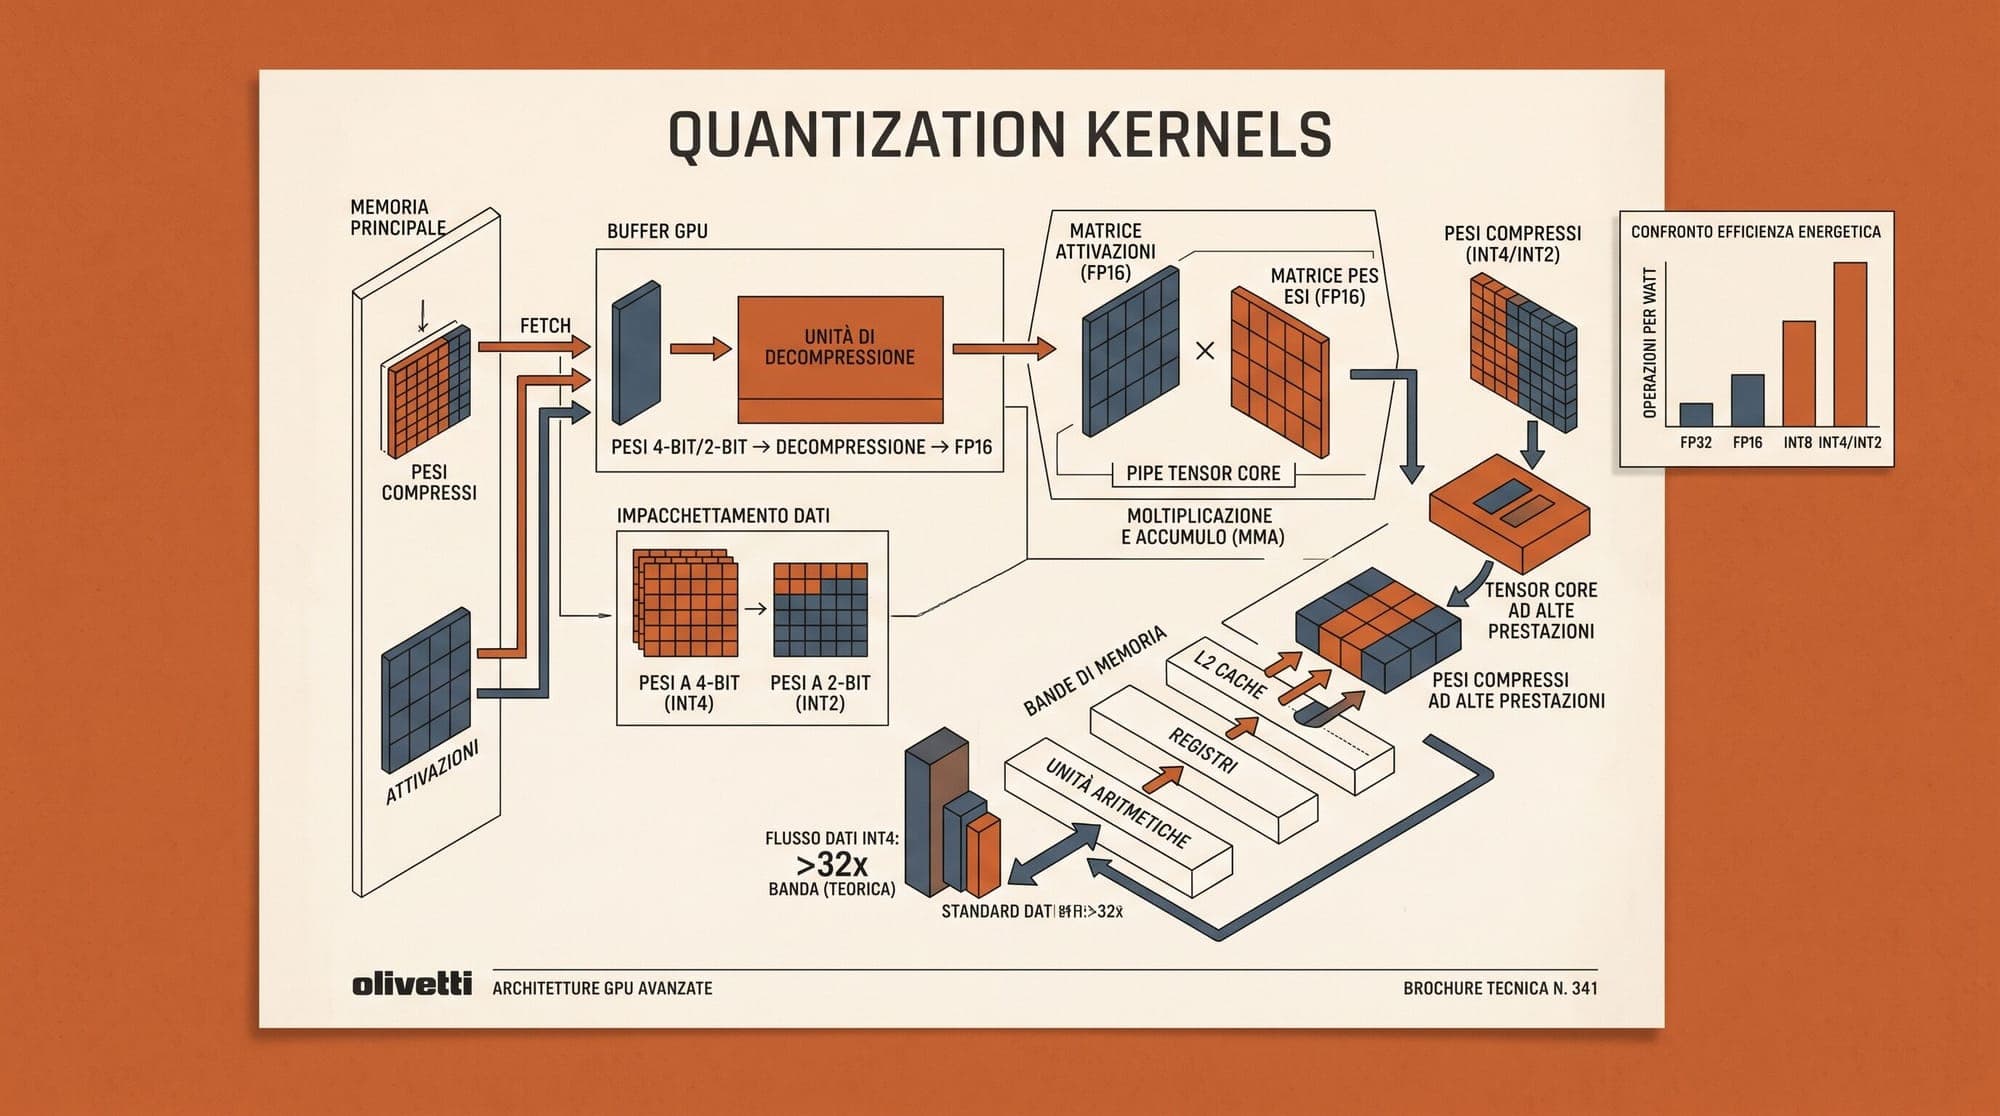
  14. Low-Precision Quantization Kernels in Production: Comparing Marlin, ExLlamaV2, FlashInfer, and BitBLAS

    Low-Precision Quantization Kernels in Production: Comparing Marlin, ExLlamaV2, FlashInfer, and BitBLAS Architecture, Memory Bandwidth, and Decoding Throughput Autoregressive large language model (LLM) serving operates under two distinct compute regimes: a compute-bound prefill phase and a memory-bandwidth-bound decode phase. While processing the initial prompt involves matrix-matrix multiplications (GEMM) with high arithmetic intensity, generating tokens one by one requires matrix-vector multip

    AI
    9 min read
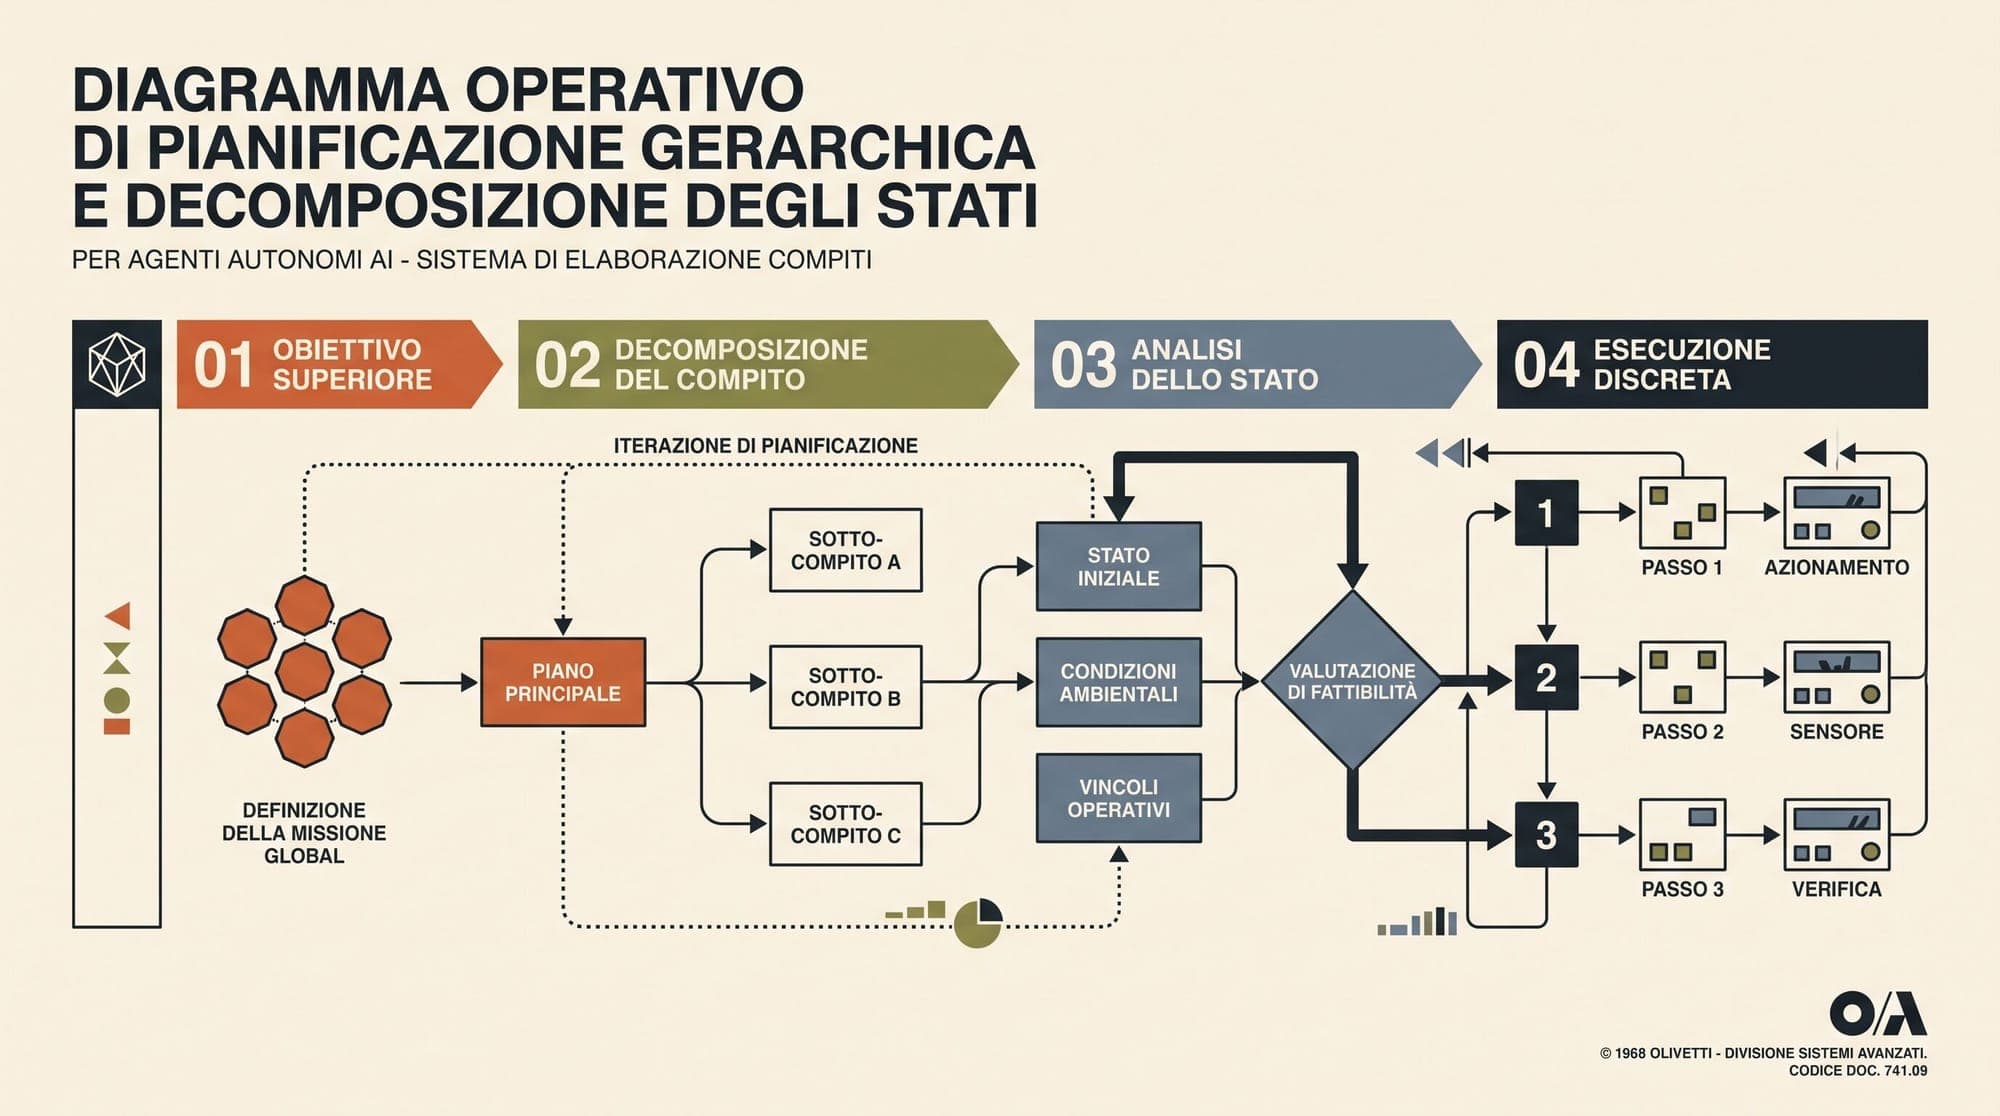
  15. Agent Task Planning and Decomposition in Production: Plan-and-Solve vs. ReAct, Hierarchical Task Graphs, and Dynamic Replanning Architectures

    Autonomous AI agents deployed in production environments frequently fail when tasks require long-horizon reasoning across dozens of sequential tool calls. While single-turn tool calling is well-handled by modern frontier models, multi-step workflows introduce compounding failure modes: plan drift, unrecoverable tool exceptions, context window saturation, and premature task termination. Building resilient agent systems requires moving beyond simple prompt-driven loops. Production engineering has

    AI
    5 min read
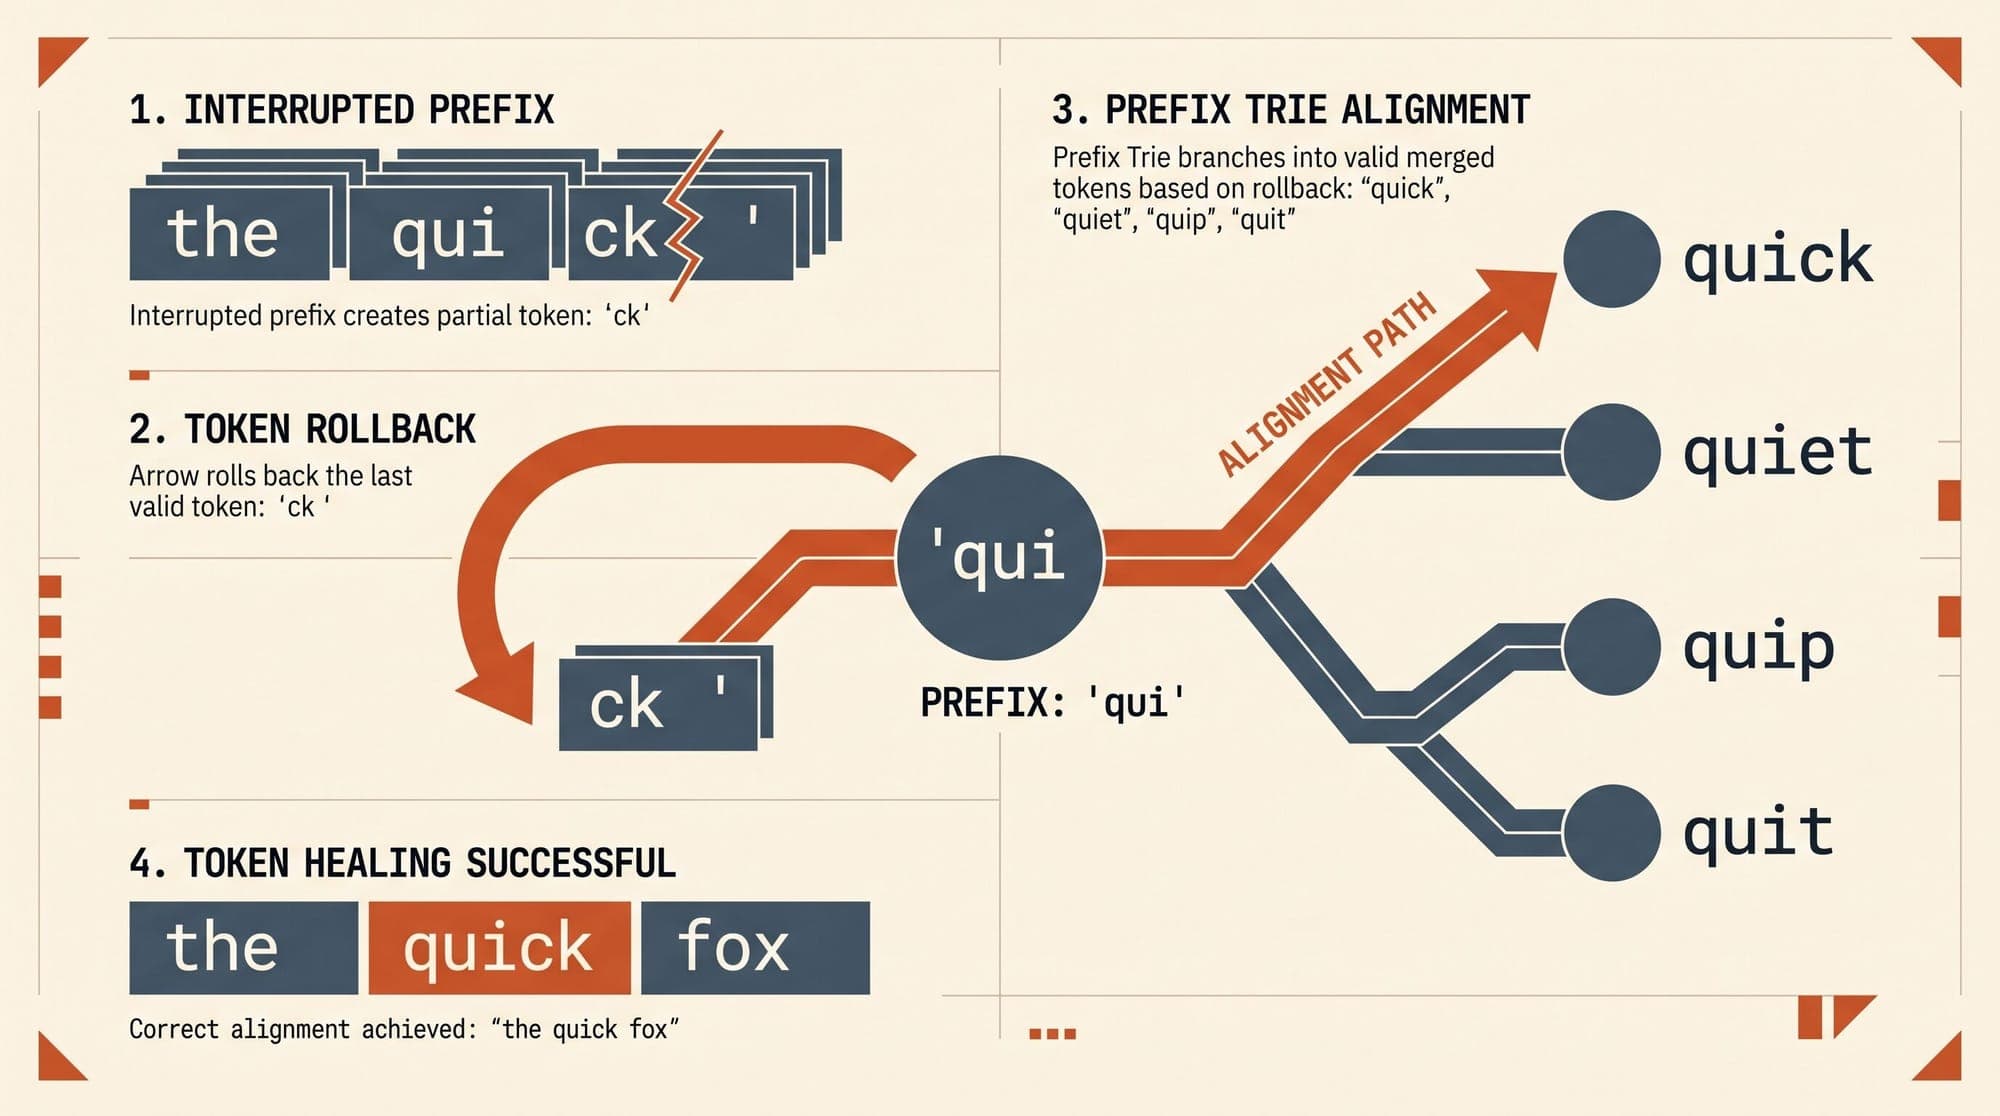
  16. Token Healing and Partial Token Alignment in Production LLM Serving: Architecture, Prefix Trie Rollback, and Serving Trade-Offs

    Modern large language models operate on discrete subword tokens generated by greedy compression algorithms like Byte-Pair Encoding (BPE), WordPiece, or Unigram. While subword tokenization enables high compression rates and fixed vocabulary sizes, it introduces a structural defect at the interface between raw user text and autoregressive inference: the partial token problem, commonly known as the prompt boundary problem. When a user prompt terminates mid-token or at a punctuation boundary that c

    LLM
    7 min read
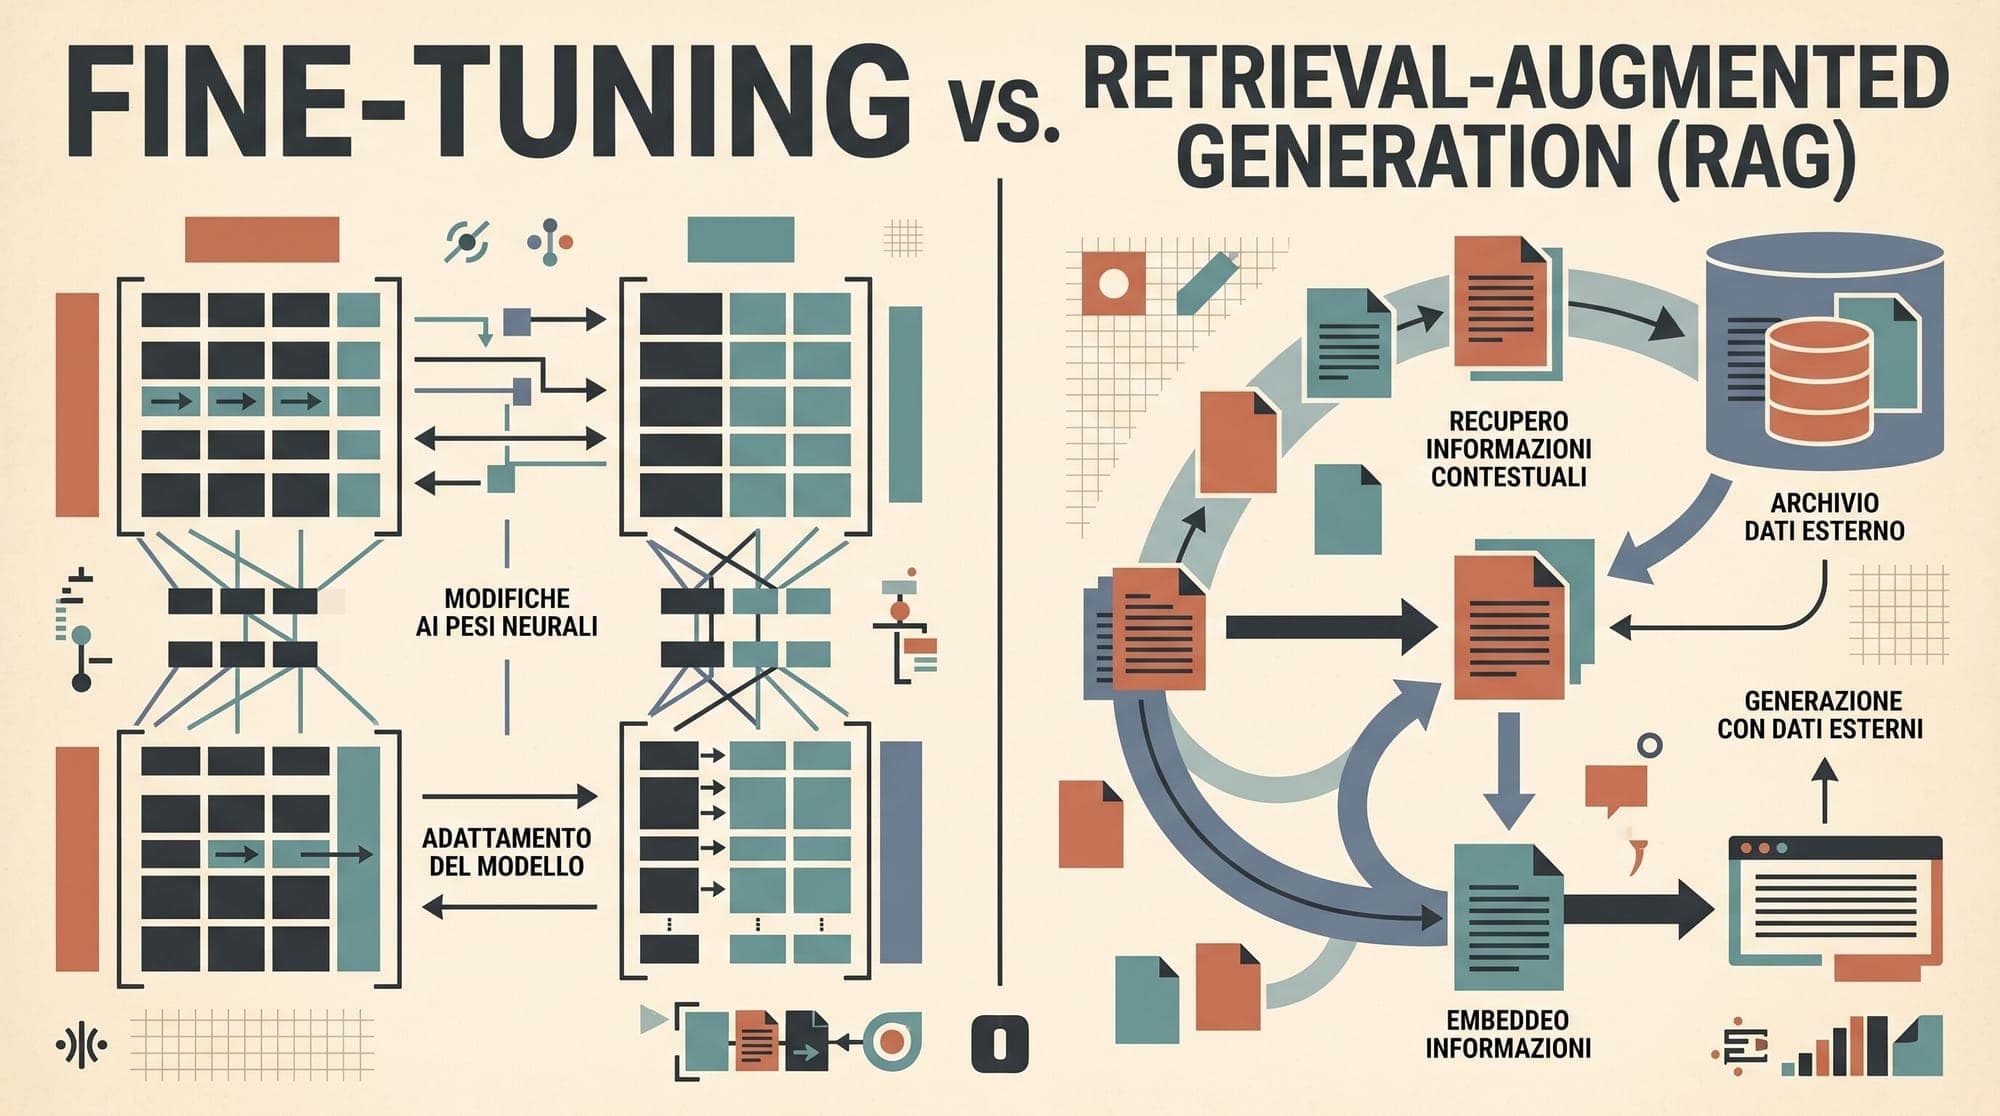
  17. Fine-Tuning vs. RAG in Production: Knowledge Injection, Task Adaptation, Latency Economics, and Hybrid Architecture Trade-Offs

    When adapting large language models to domain-specific enterprise workloads, engineering teams face a fundamental architectural choice: modify the model's parametric weights via fine-tuning, or supply dynamic context at inference time via Retrieval-Augmented Generation (RAG). While early discussions often framed this decision as a binary trade-off, empirical evaluations demonstrate that fine-tuning and retrieval serve fundamentally different mathematical and operational functions. Fine-tuning e

    AI
    6 min read
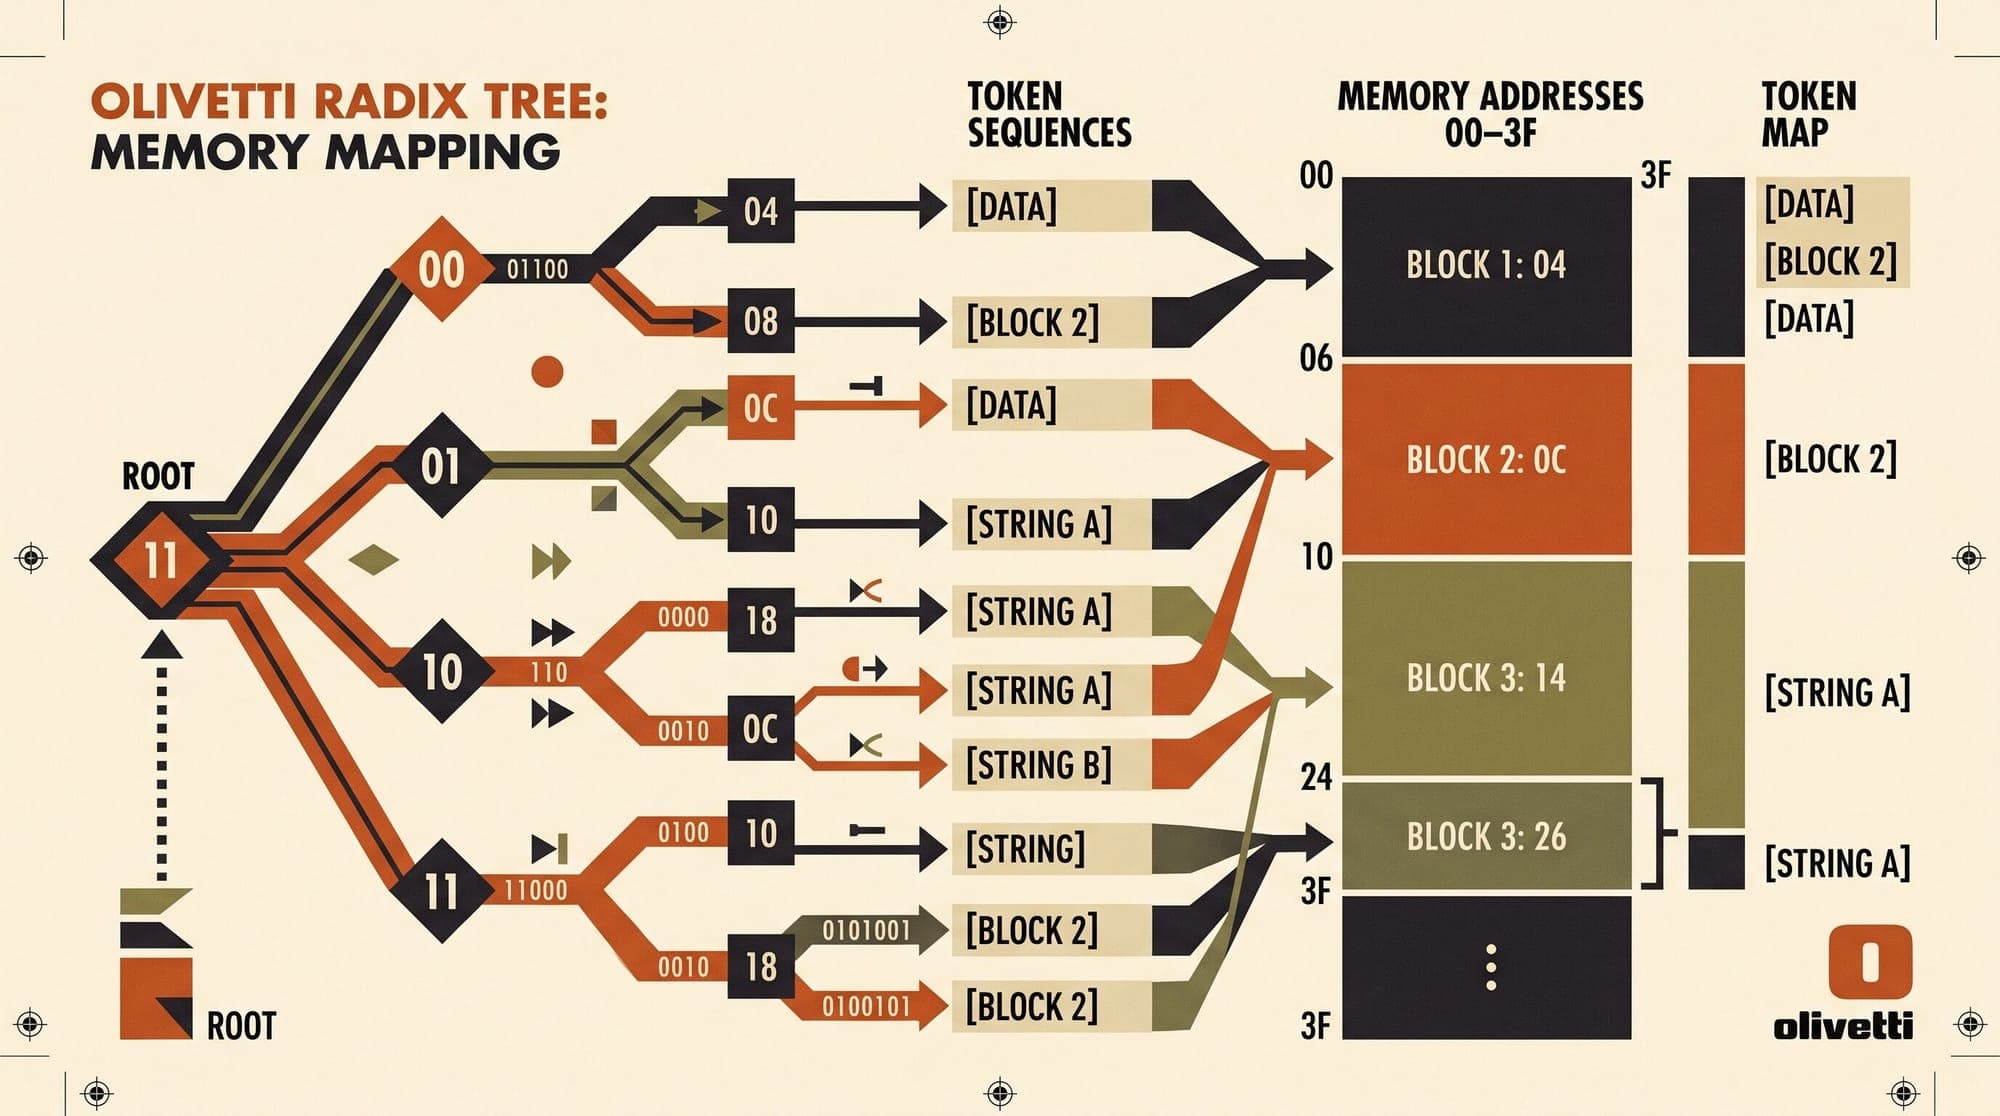
  18. Prefix-Tree KV Cache Management in Production: RadixAttention, Tree-Structured LRU Eviction, and Token-Level Sharing in SGLang and vLLM

    Prefix-Tree KV Cache Management in Production: RadixAttention, Tree-Structured LRU Eviction, and Token-Level Sharing in SGLang and vLLM Autoregressive large language model inference is heavily constrained by memory bandwidth and the computational overhead of the prefill phase. For workloads such as multi-turn conversations, autonomous agent tool loops, few-shot prompt evaluations, and tree-search decoding, consecutive requests often share substantial token prefixes. In a standard multi-turn ses

    AI
    7 min read
  19. GPU Cluster Storage in Production: GPUDirect Storage, NVMe-oF, Parallel File Systems, and Checkpointing Throughput

    Training frontier large language models and serving hundred-billion parameter checkpoints places extreme demands on storage subsystems. While compute clusters frequently deploy thousands of GPUs connected via high-bandwidth interconnects like NVLink and InfiniBand, storage architectures often become severe bottlenecks during two critical operational phases: distributed checkpointing and cold-start model weight loading. A standard 70-billion parameter model in BF16 precision generates approximat

    AI
    7 min read
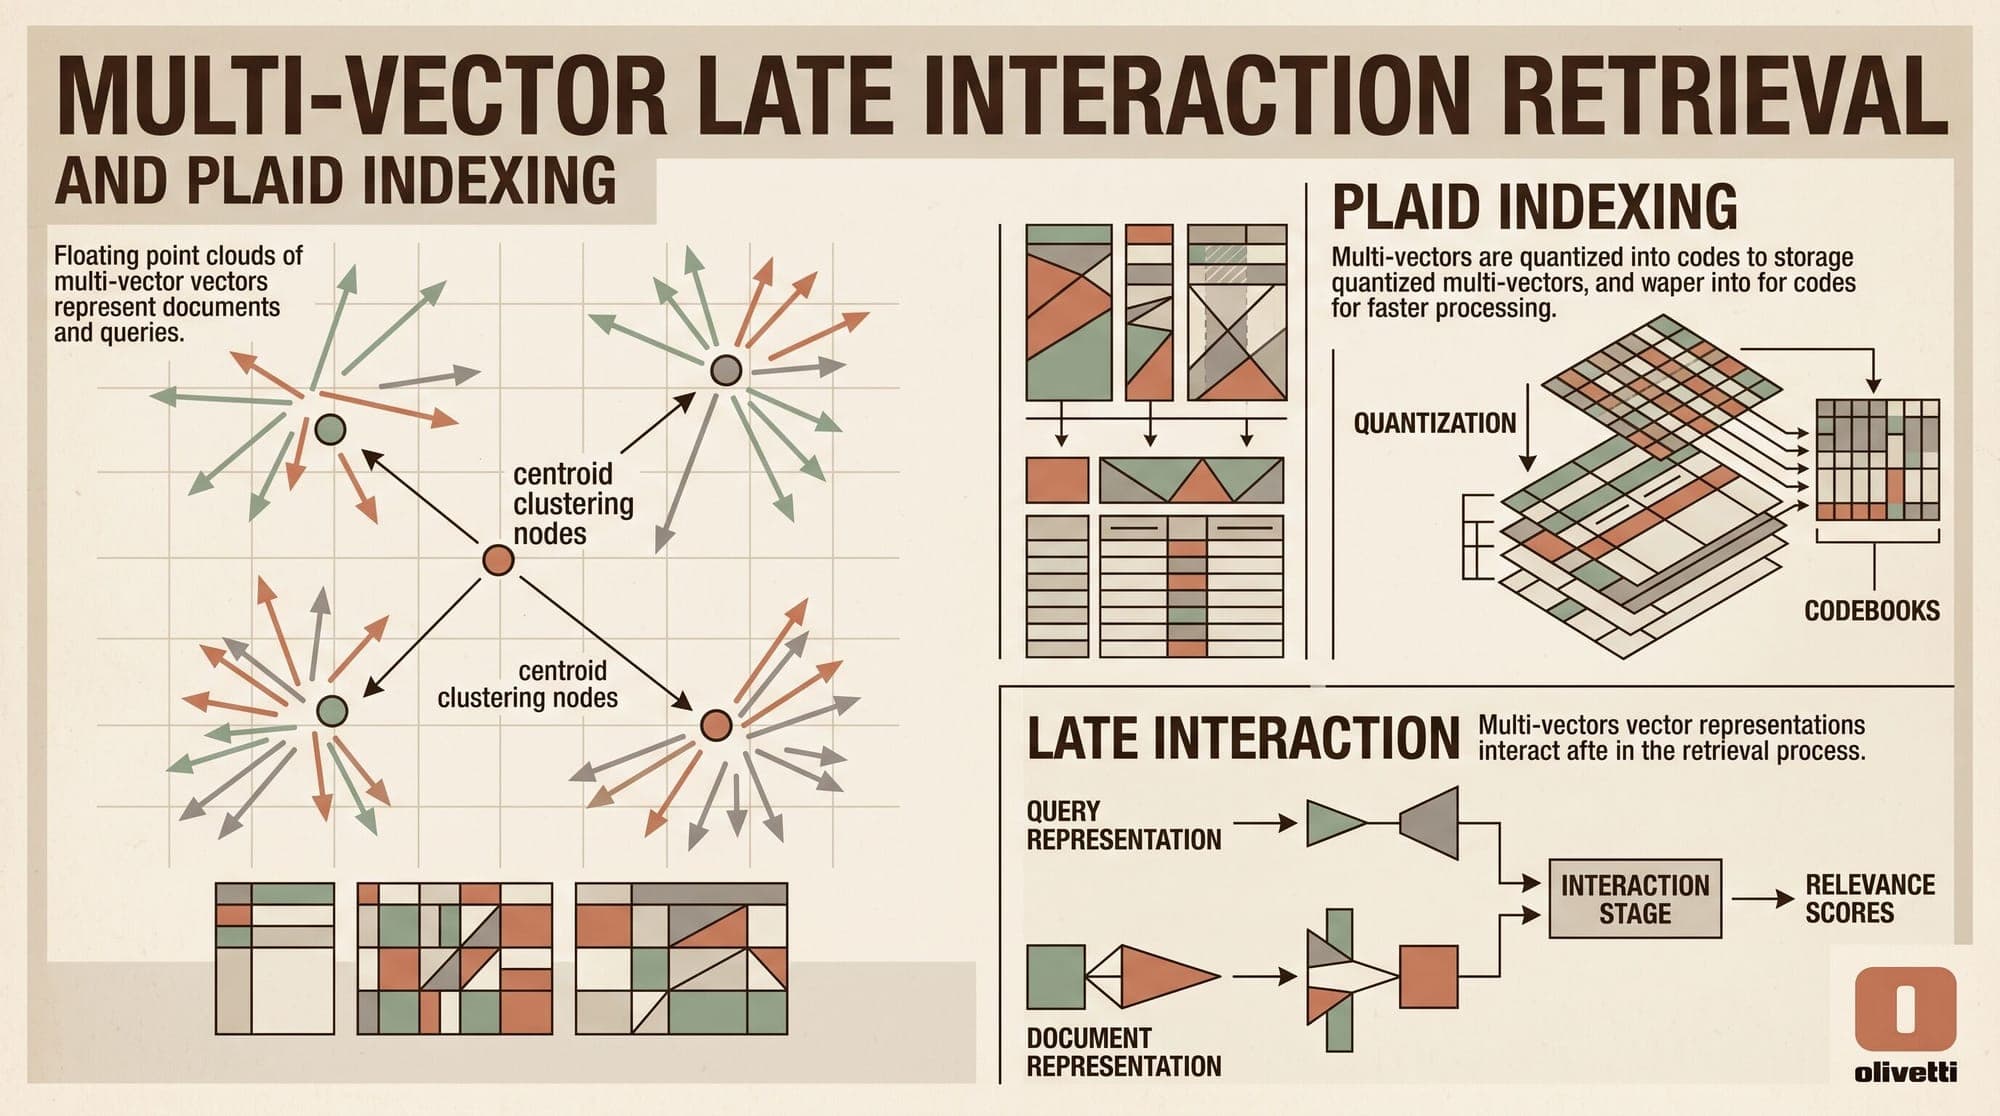
  20. Multi-Vector Late Interaction in Production: PLAID Indexing, Residual Compression, and Serving Architectures

    Multi-Vector Late Interaction in Production: PLAID Indexing, Residual Compression, and Serving Architectures Dense single-vector embeddings and cross-encoder rerankers represent the two traditional extremes of neural information retrieval. Single-vector models collapse entire documents into a single dense representation (typically 768 to 3,072 dimensions), losing token-level nuance, lexical precision, and localized facts. Cross-encoders preserve token interactions across the entire input sequen

    AI
    7 min read