Label Smoothing Regularization: Mathematical Foundations, Maximum Entropy Dynamics, and the Regular Simplex Geometry in LLMs
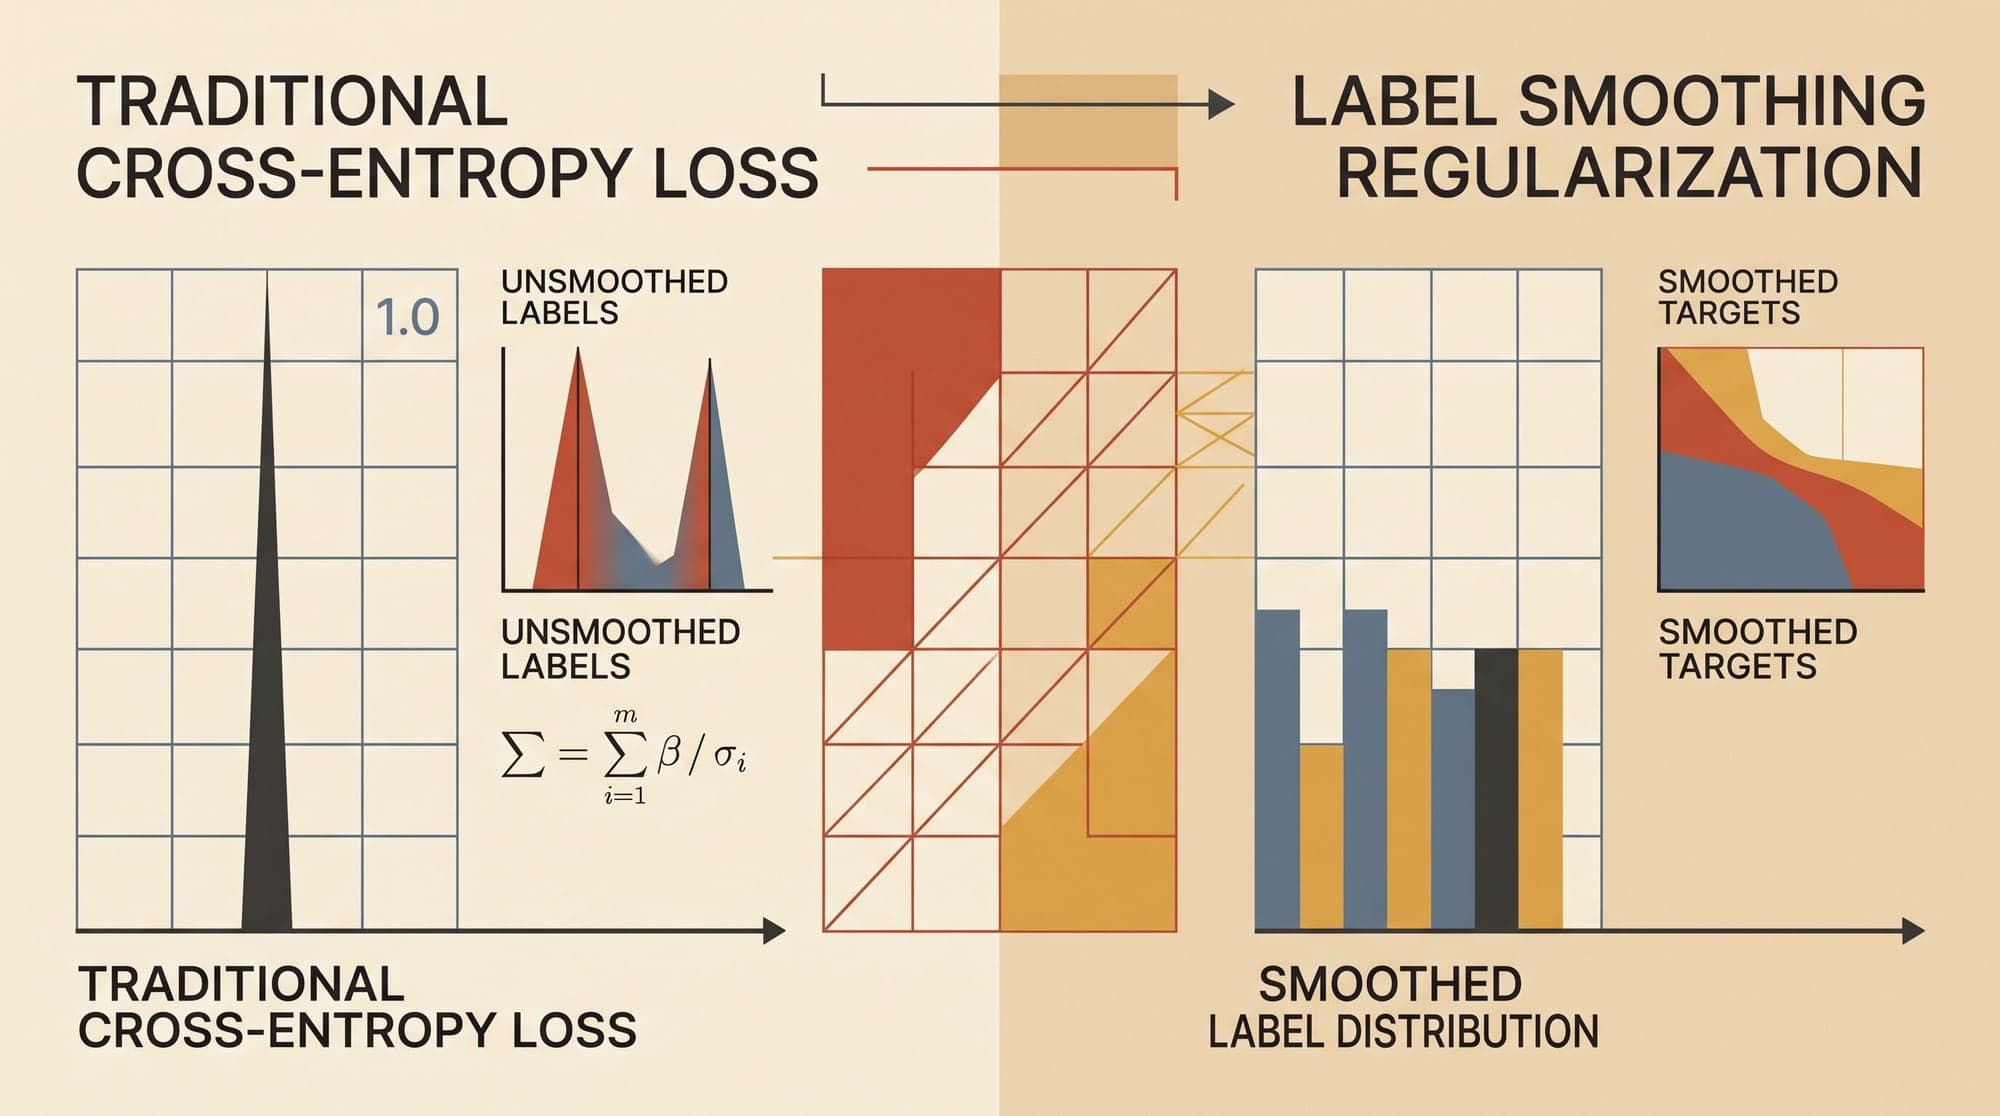
In supervised classification and autoregressive language modeling, standard cross-entropy loss trains neural networks against discrete, one-hot target distributions. While intuitive, one-hot supervision creates an inherent optimization pathology: minimizing the cross-entropy objective to zero requires pushing the logit of the target class toward positive infinity while driving all competing non-target logits toward negative infinity. In deep networks, this dynamic inflates parameter norms, cause