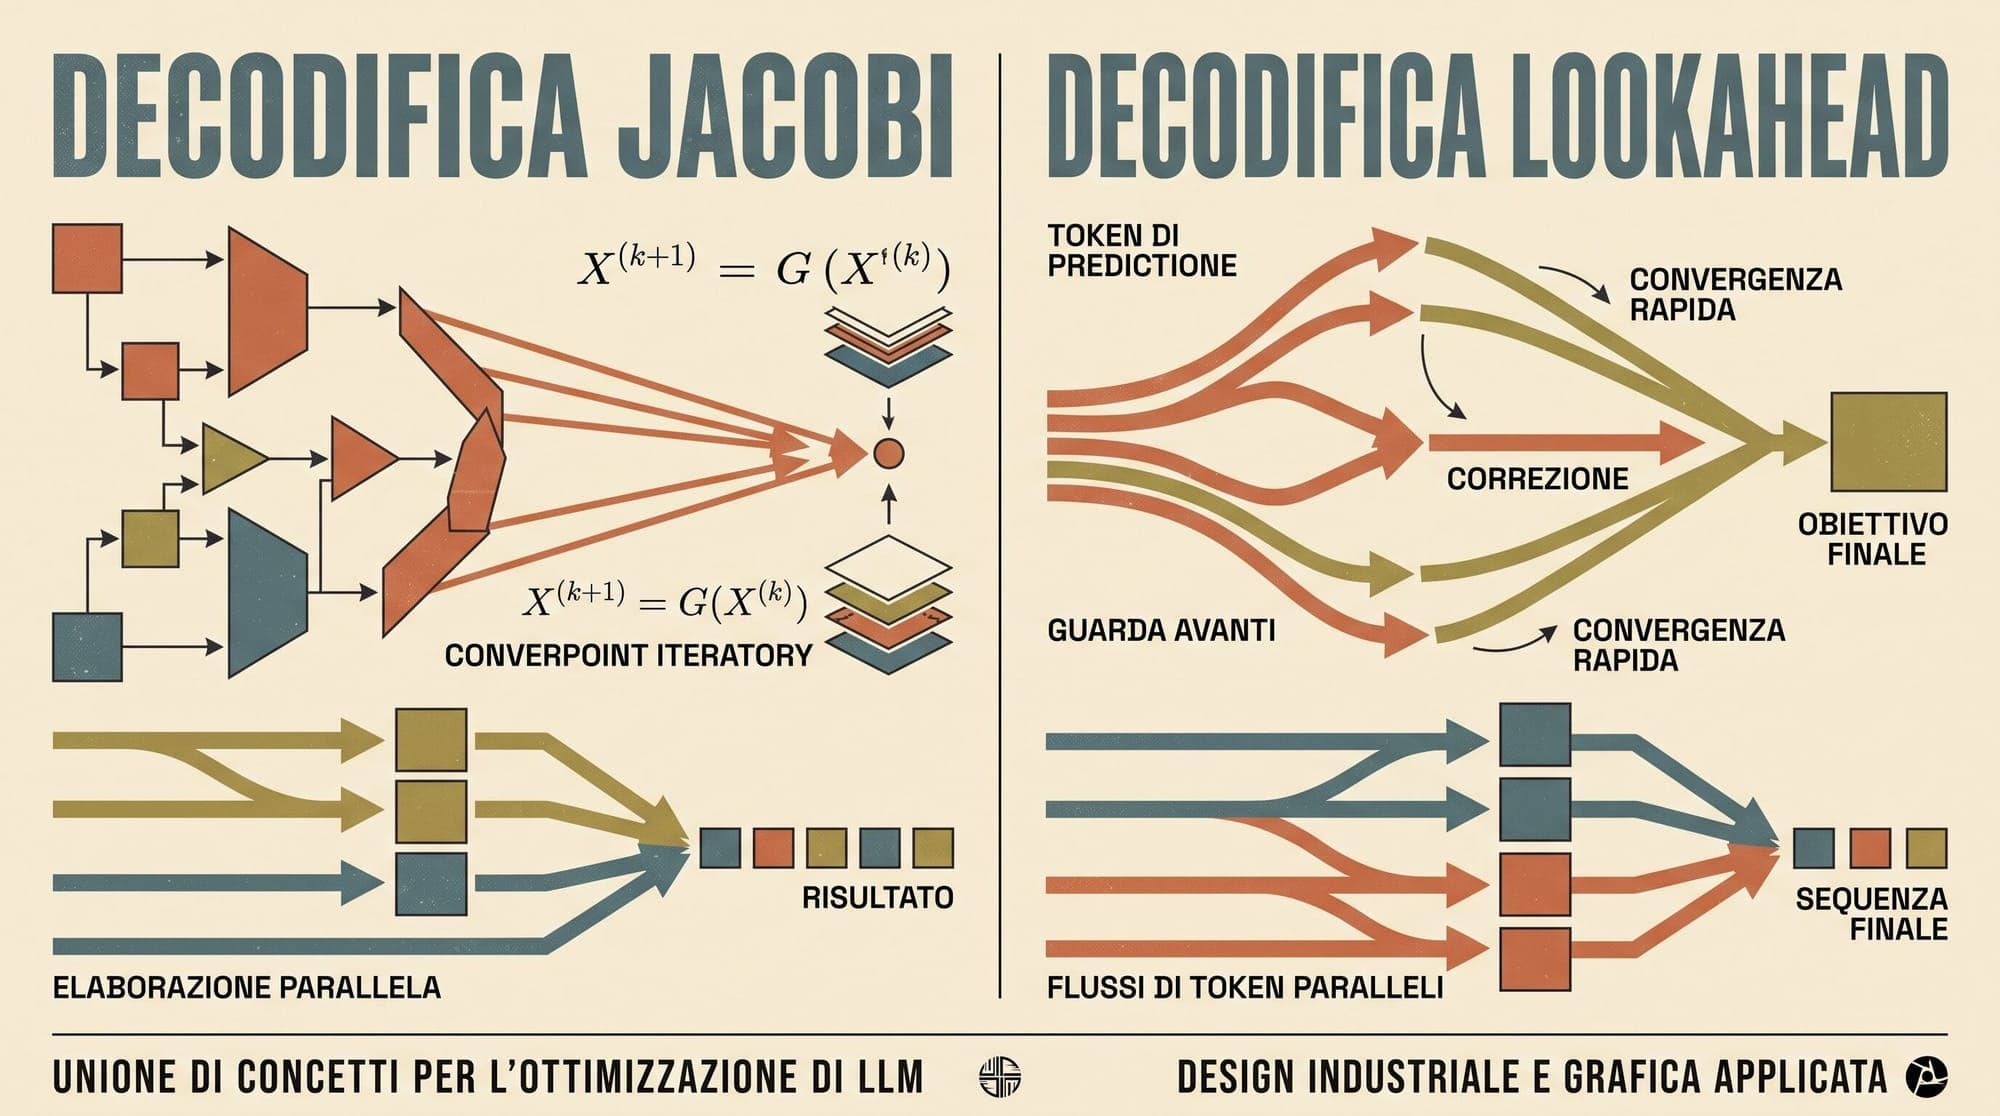
Jacobi and Lookahead Decoding: How Parallel Fixed-Point Iteration Accelerates Autoregressive Inference Without Draft Models
Standard autoregressive generation in large language models operates as a strictly sequential process. To generate a sequence of $K$ tokens, an inference engine must execute $K$ successive forward passes through the network. In single-request serving regimes (batch size 1), each forward pass is heavily memory-bandwidth bound: the GPU must stream billions of model parameters from High Bandwidth Memory (HBM) into on-chip SRAM to process a single token, leaving tensor compute cores severely underut