
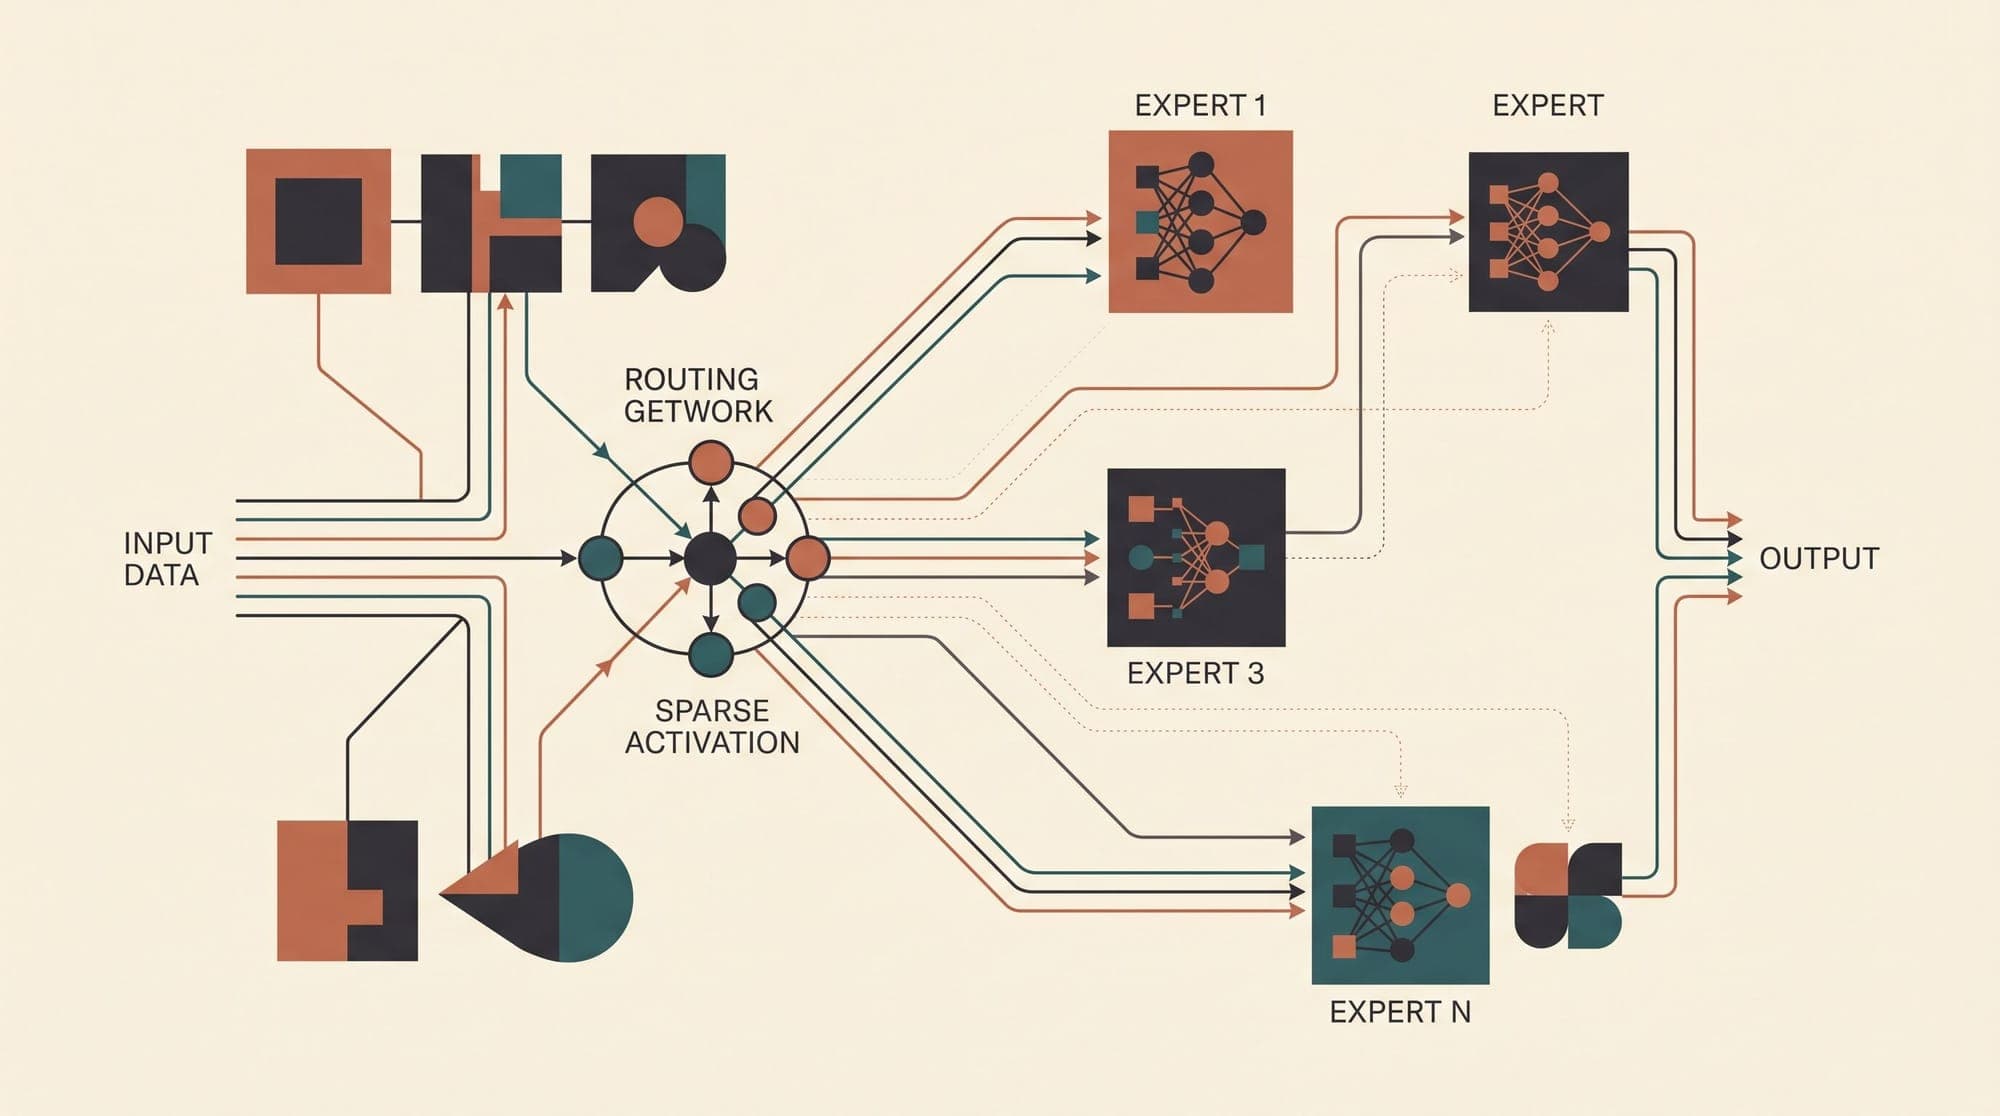
US AI research lab Reflection AI has released Beam 1.0, a 501-billion-parameter open-weight Mixture-of-Experts (MoE) foundation model licensed under Apache 2.0. The release includes weights in BF16, FP8, and NVFP4 precision formats alongside training harnesses and inference integration for vLLM, SGLang, and Ollama.
Architecture and Sparse Compute Profile
Beam is built across 52 layers with an interleaved local and global attention structure, maintaining a 3:1 ratio between sliding-window and global attention layers. While total model parameters reach 501.3 billion across 256 routed experts, the architecture activates approximately 23.4 billion parameters per token during forward passes.
The model features an effective context length of 1 million tokens, extended from a 256,000-token pretraining phase through mid-training context expansion. Memory requirements during full context evaluation scale dynamically:
- 32,000 tokens: 1.2 GiB per sequence
- 128,000 tokens: 4.6 GiB per sequence
- 1,000,000 tokens: 36.08 GiB per sequence (BF16 with dynamic cache)
At FP8 precision, full parameter weights occupy roughly 576 GB of VRAM, fitting single 8-GPU high-memory nodes. At NVFP4 precision on Blackwell hardware, the memory footprint decreases to approximately 288 GB.
Training Infrastructure and Compute Investment
Pretraining for Beam processed 23.8 trillion tokens across a cluster of 6,144 NVIDIA GB300 GPUs over a four-week span. Post-training reinforcement learning ran over 100 million rollouts across 10,500 GB300 GPUs during an additional four-week period, targeting agentic tool use, mathematical reasoning, and terminal execution.
Benchmark Results and Evaluation
In benchmark evaluations reported by Reflection AI and verified in Hugging Face technical documentation, Beam shows strengths in software engineering and competitive performance in terminal workflows:
- SWE-bench Verified: 81.6% in BF16 (80.2% in FP8, 80.7% in NVFP4)
- SWE-bench Pro v1: 66.1% in BF16
- Terminal-Bench v2.1: 80.1% in BF16
- AIME 2026: 97.7% in BF16
- DeepSWE v1.1: 43.3%
The permissive Apache 2.0 license allows self-hosting, fine-tuning, and commercial deployment without licensing restrictions. Model checkpoints and inference integration code are available immediately on Hugging Face. For how developers and benchmarkers reacted after launch, see our Beam reactions roundup.
