Category / page 38

Models & Assistants

1121 articles

Articles, page 38

741-760 of 1121
  1. Quantization-Aware Training in Large Language Models: How Fake Quantization, STE, and Learned Step Sizes Preserve Low-Bit Accuracy

    Quantization-Aware Training (QAT) is a model compression paradigm that integrates precision loss directly into the training or fine-tuning graph. While Post-Training Quantization (PTQ) calibrates fixed floating-point weights without updating underlying network parameters, QAT simulates the numerical discretization of weights, activations, and key-value (KV) caches during both forward and backward passes. This closed-loop optimization forces neural network weights to co-adapt to discrete integer
    AI
    9 min read
  2. Adobe Firefly Expands Generative Audio Tools and Integrates Gemini Omni Flash

    Adobe has broadened its generative production suite with the general availability of three dedicated AI audio generation modules in Adobe Firefly, alongside the integration of Google's multimodal Gemini Omni Flash model. The audio capabilities expand Firefly from static imagery and video synthesis into integrated soundtrack design, voice synthesis, and scene audio generation, fully cleared for commercial workflows. Generative Audio Modules and Commercial Licensing The expanded audio suite in

    AI
    2 min read
  3. Pew Study Finds 35% of Post-ChatGPT Webpages Show Signs of AI Authorship

    More than one-third of English-language webpages published since the launch of ChatGPT show measurable evidence of being generated or heavily edited by large language models, according to a study released by the Pew Research Center. The analysis examined nearly 500,000 English-language web documents indexed across a five-year window in the Common Crawl archive, spanning periods before and after OpenAI introduced ChatGPT in November 2022. Using detection technology developed by Open Pangram, res

    AI
    2 min read
  4. Monte Carlo Tree Search in Large Language Models: How Selection, Expansion, Simulation, and Backpropagation Guide Deliberate Reasoning

    Standard autoregressive language models generate text token by token via left-to-right greedy decoding or stochastic sampling. While this System 1 approach suffices for fluency and single-turn synthesis, it struggles with complex mathematical reasoning, multi-step logical deduction, and long-horizon planning. Because autoregressive decoders lack native backtracking mechanisms, an error introduced at step t persists and compounds across all subsequent steps t+1 through T. To overcome this struct

    AI
    7 min read
  5. CI/CD for LLM Applications: Automated Regression Testing, Golden Datasets, and Pull Request Quality Gates

    Deploying generative AI applications into production environments requires a fundamental shift in software quality assurance. Traditional continuous integration (CI) workflows rely on deterministic assertions: given a fixed input, a function must return an exact expected output. Large language models (LLMs) break this paradigm because their outputs vary across runs, token probabilities drift with prompt alterations, and natural language responses cannot be validated with binary equality checks.

    AI
    6 min read
  6. Robot.com Signs Seven-Year Enterprise Deployment Agreement with Sodexo

    Autonomous robotics developer Robot.com has signed a seven-year commercial agreement with food services and facilities management corporation Sodexo to scale autonomous delivery operations across college campuses throughout North America. The contract represents Robot.com's largest enterprise deployment to date. The agreement expands a partnership established in 2021, when Sodexo participated in Robot.com's (then Kiwibot) $7.5 million pre-Series A financing round and deployed initial fleets acr

    AI
    2 min read
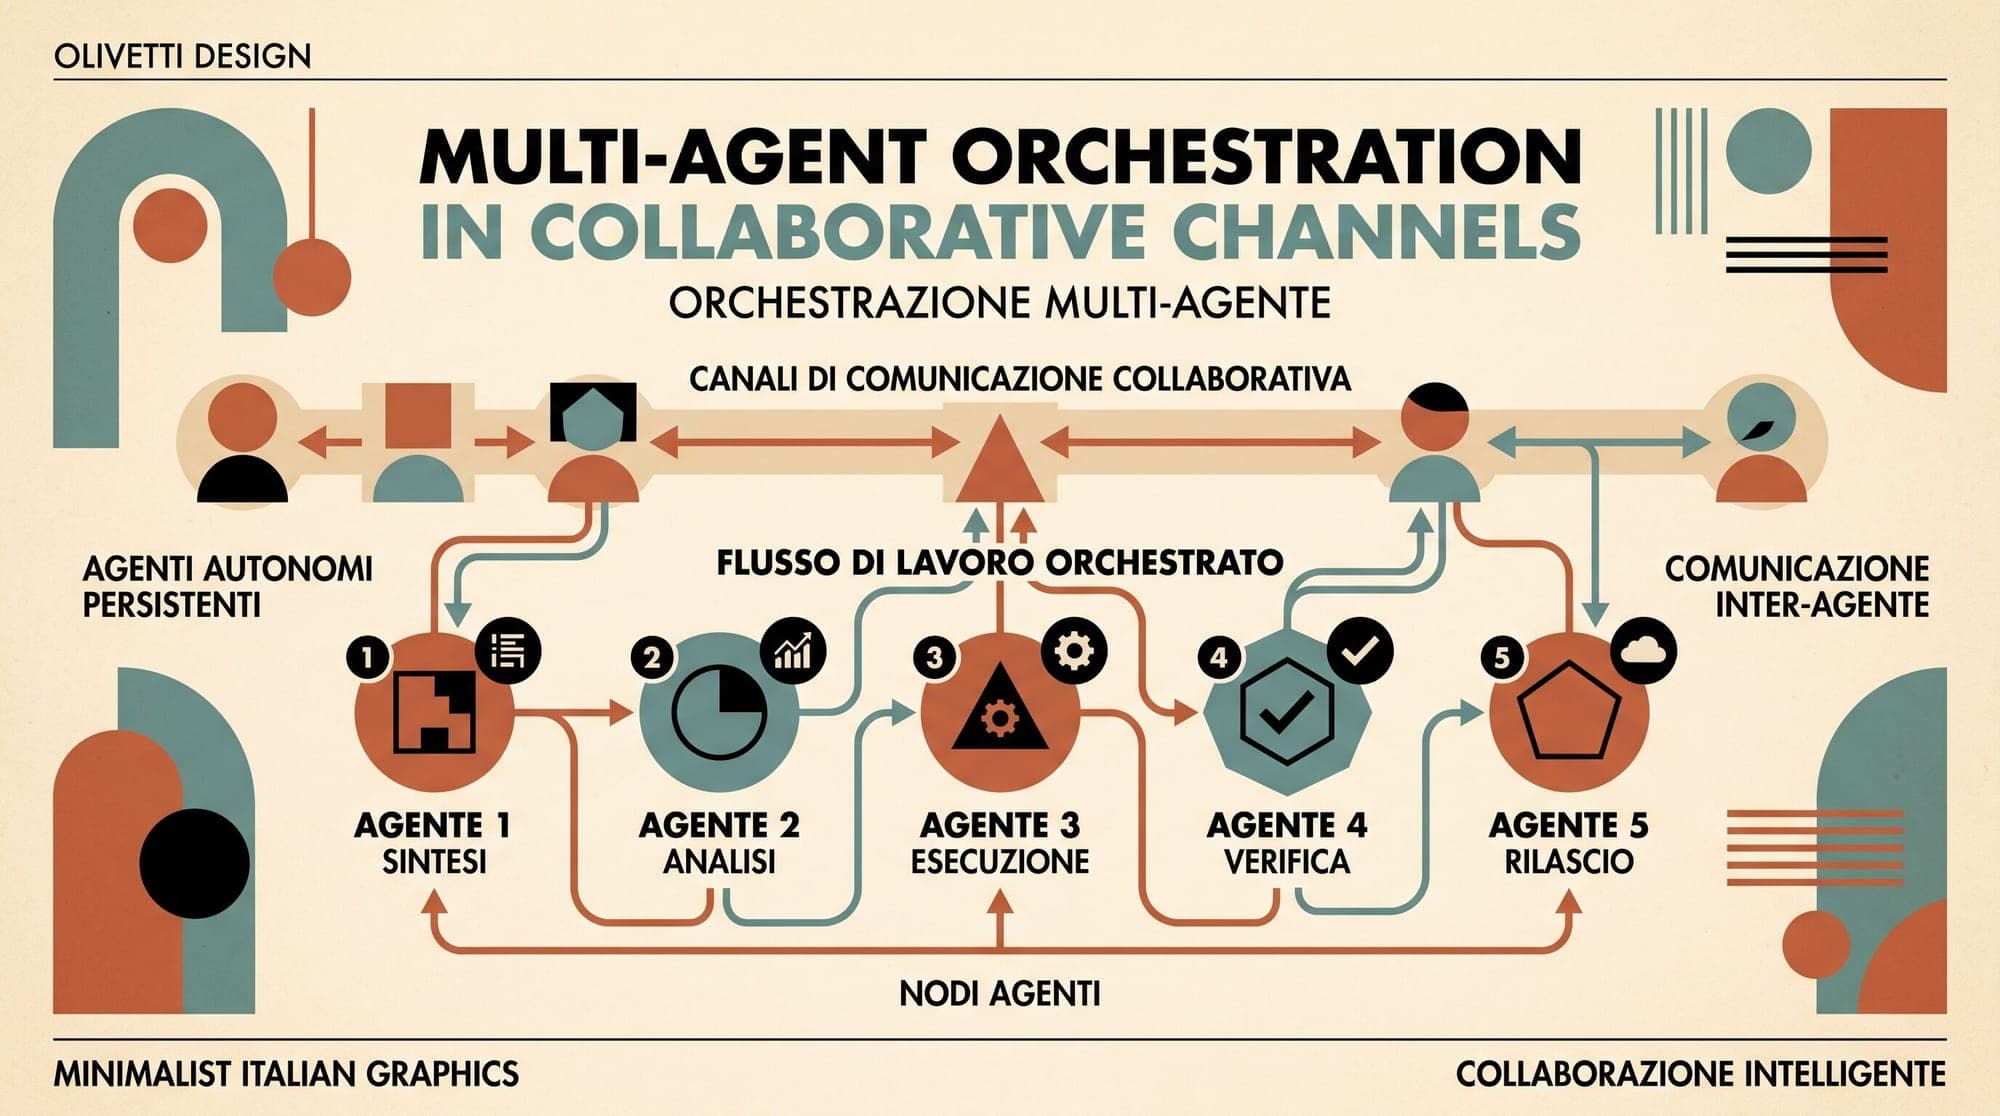
  7. NanoClaw Launches Slack Integration for Persistent Multi-Agent Workspaces

    NanoCo has released a native Slack Marketplace integration for its open-source autonomous agent harness, NanoClaw. The integration allows teams to provision persistent, multi-agent AI workforces directly within Slack channels using conversational prompts. Unlike standard single-bot integrations or ephemeral background subagents, NanoClaw assigns each newly generated agent a distinct Slack identity, complete with individual avatars, handles, permission boundaries, and dedicated memory contexts.

    AI
    2 min read
  8. Google's Gemma Open Models Pass 1 Billion Downloads as Variants Top 100,000

    Google DeepMind announced that its Gemma family of open-weight models has surpassed one billion cumulative downloads since its initial launch in early 2024. Alongside the download milestone, the laboratory reported that third-party developers have published more than 100,000 distinct fine-tuned variants and derivative architectures across community model hubs. The milestone marks the first cumulative adoption metrics released by Google for the Gemma ecosystem. To accompany the figures, Google l

    AI
    2 min read
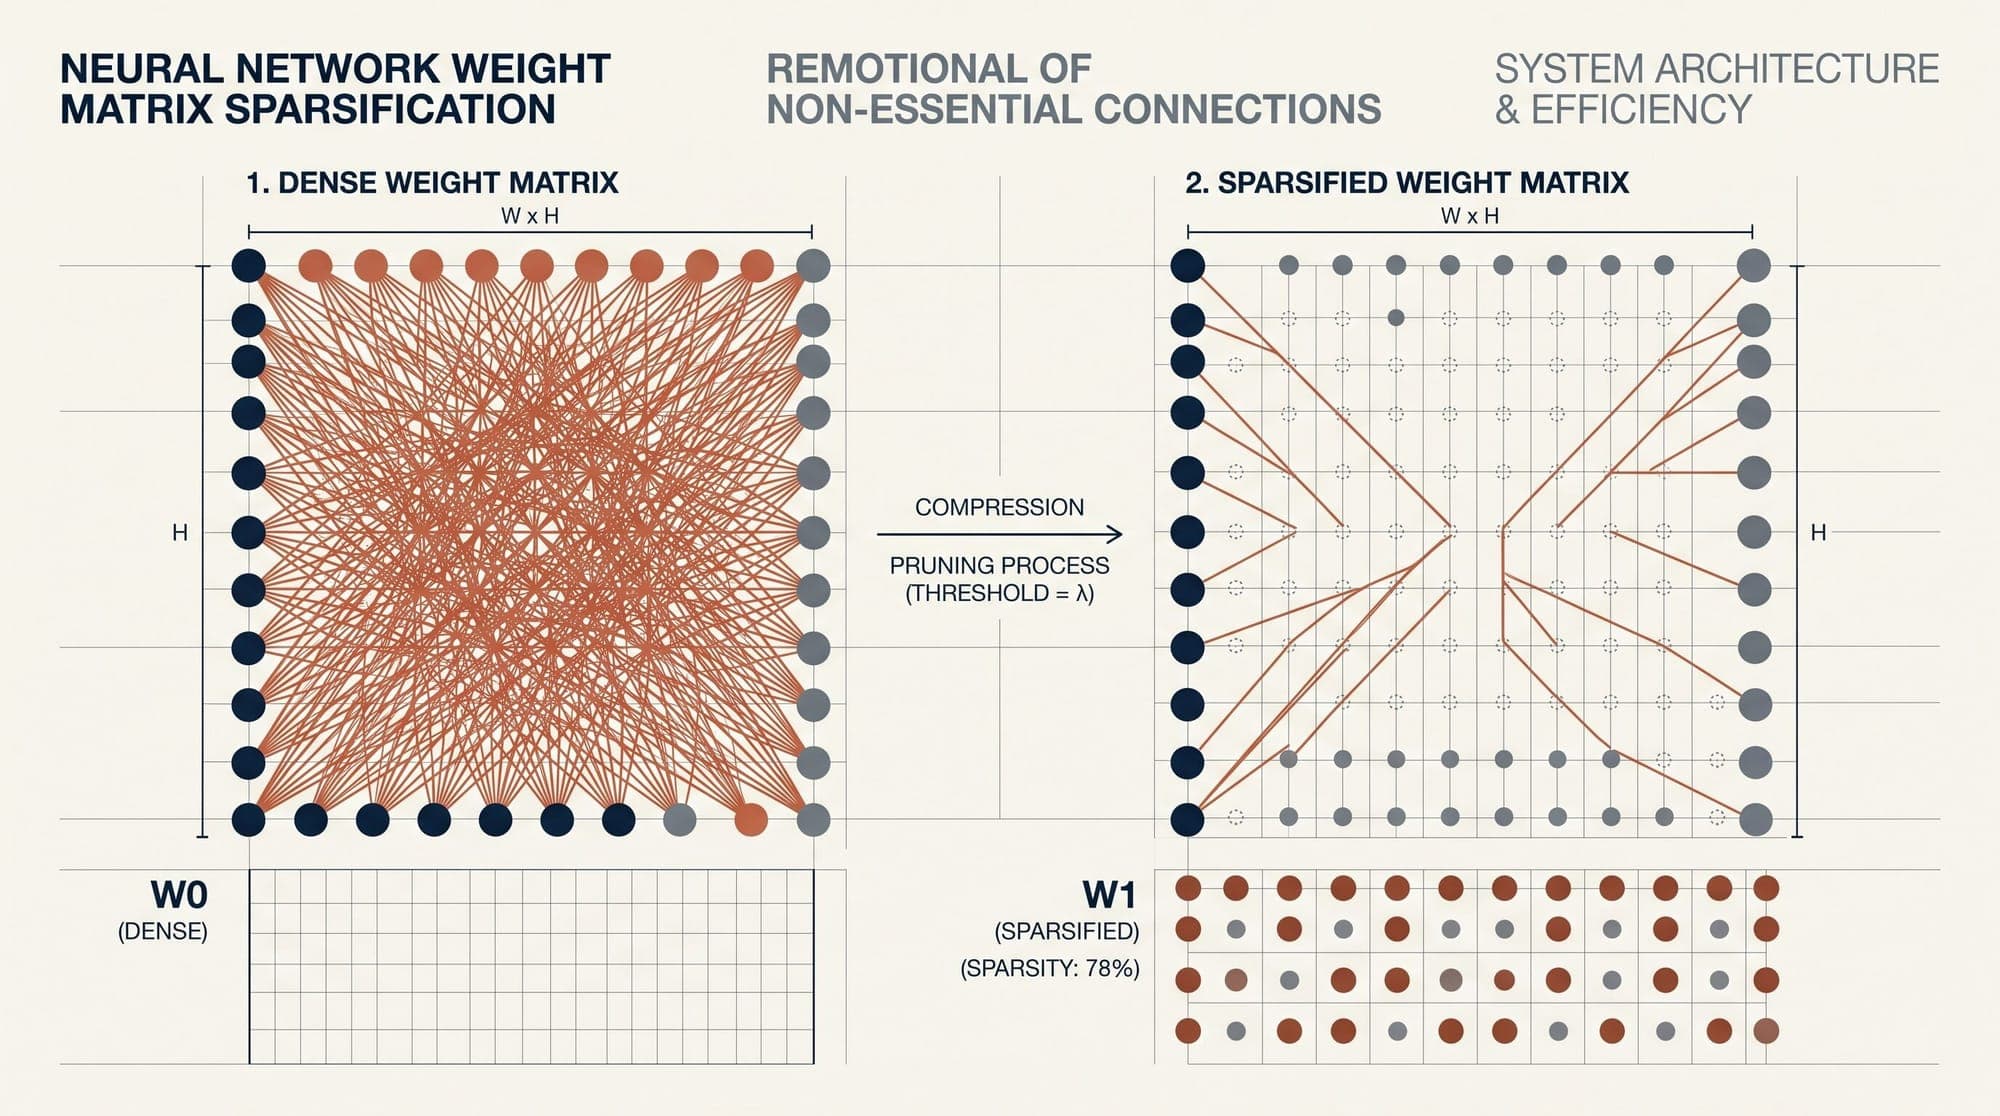
  9. Weight Pruning in Large Language Models: How SparseGPT, Wanda, and Semi-Structured 2:4 Sparsity Compress Neural Networks Without Retraining

    Modern large language models require tens to hundreds of gigabytes of high-bandwidth memory to store billions of parameters. While post-training quantization compresses model footprints by reducing numerical precision from 16-bit floating point to 8-bit or 4-bit integers, weight pruning attacks model size along an orthogonal axis: setting redundant parameter values exactly to zero. Historically, pruning deep neural networks required iterative cycles of magnitude thresholding and compute-heavy r

    AI
    6 min read
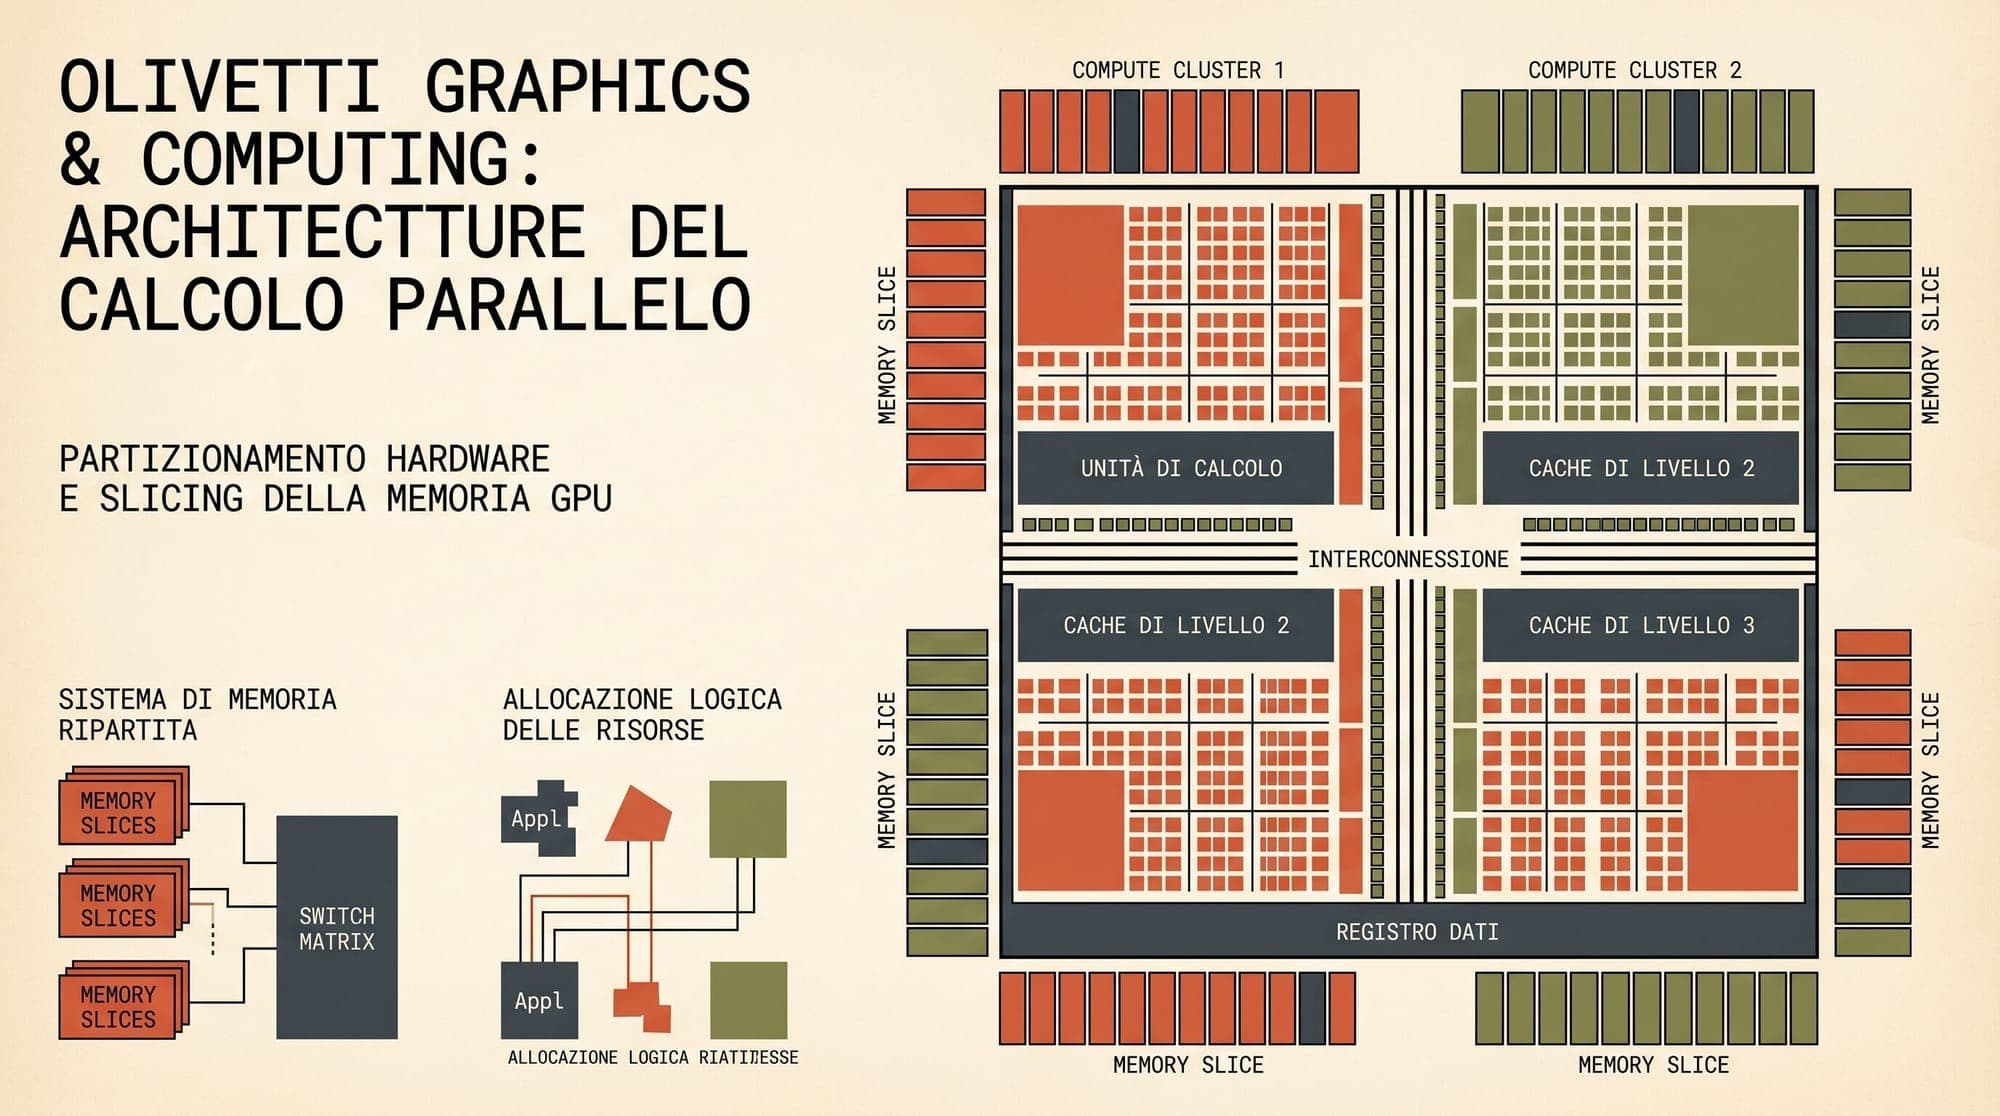
  10. GPU Slicing in Production AI Systems: Comparing MIG, MPS, Time-Slicing, and Dynamic Partitioning

    GPU Slicing in Production AI Systems: Comparing MIG, MPS, Time-Slicing, and Dynamic Partitioning Modern production AI systems rarely deploy a single standalone large language model. Contemporary compound AI architectures rely on heterogeneous pipelines comprising embedding models (such as BGE or E5), cross-encoder rerankers, safety classifiers (such as Llama Guard), speculative decoding draft models, and vision-language encoders. While primary generation models typically require dedicated multi

    AI
    7 min read
  11. Meta Releases Pocket in the US for Prompt-Based Game Generation

    Meta has released Pocket in the United States, expanding access to an experimental mobile application designed to generate and share lightweight interactive games through natural language prompting. The app first launched as a regional test in Brazil in late June 2026 before receiving its broader version 26.0 update on August 20, 2026. Pocket represents the product integration of Meta's earlier acquisition of the startup Atma Sciences, the original developers behind the Gizmo mobile platform.

    AI
    2 min read
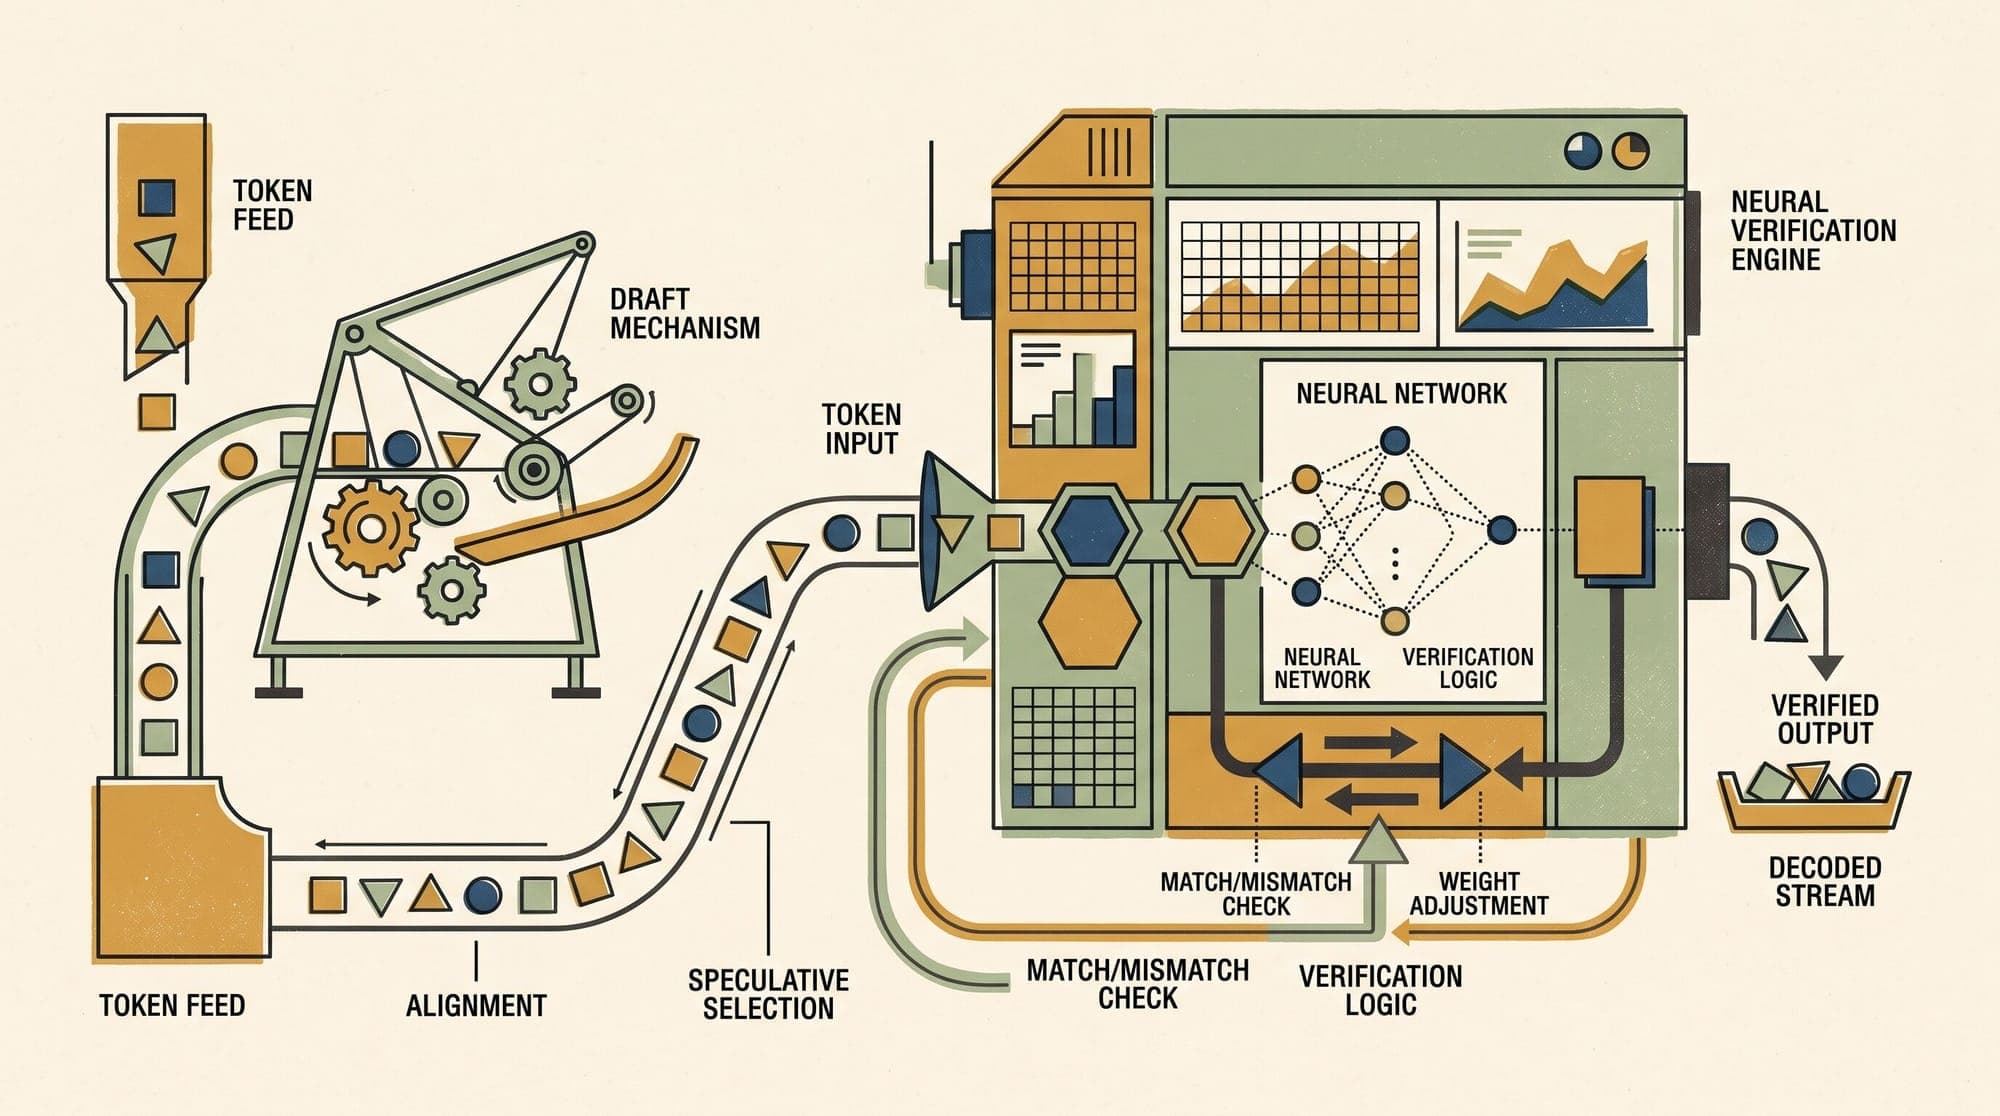
  12. Liquid AI Ships LFM2.5-DSpark Draft Models for Up to 3.2x Faster Inference

    Liquid AI has released speculative decoding draft checkpoints for three models across its LFM2.5 series: LFM2.5-1.2B-Instruct, LFM2.5-2.6B, and the mixture-of-experts model LFM2.5-8B-A1B. The release introduces small companion models designed to accelerate auto-regressive generation without altering final token distributions. The draft models are available in Safetensors and GGUF formats on Hugging Face, with immediate support implemented for SGLang and llama.cpp. Architecture and Draft Desig

    AI
    2 min read
  13. Tree of Thoughts in Large Language Models: How Search Trees, State Evaluation, and Backtracking Expand Deliberate Reasoning

    Standard autoregressive large language models generate text sequentially from left to right. At each step $t$, the network samples the next token according to a conditional probability distribution over the vocabulary: P(w_t | w_1, w_2, ..., w_{t-1}) While Chain-of-Thought (CoT) prompting (Wei et al., 2022) encourages models to output intermediate reasoning steps, the underlying computational process remains a linear path through token space. If the model makes an early logical error or choose

    AI
    6 min read
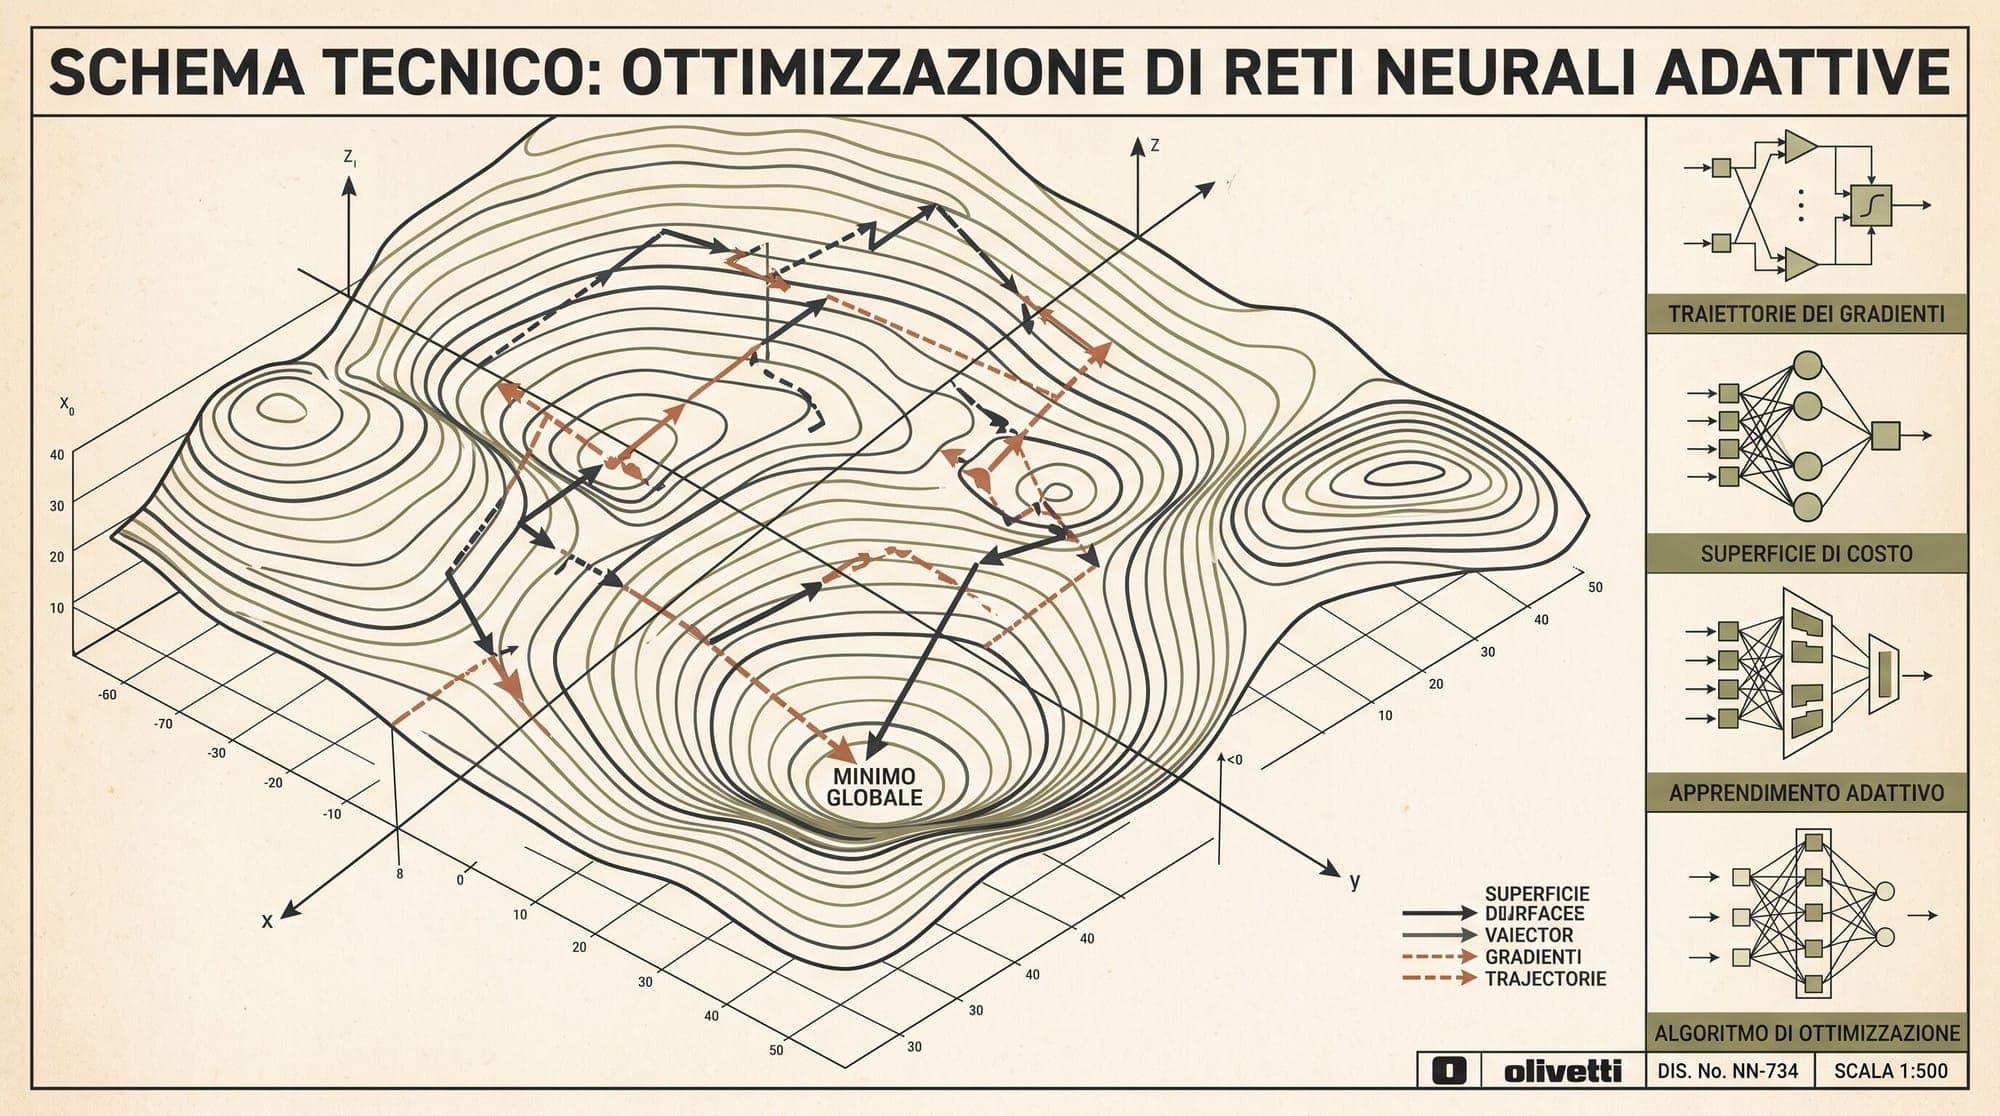
  14. Adaptive Optimizers in Large Language Model Pre-Training: How AdamW, Adafactor, and Lion Scale Gradient Updates Across Billions of Parameters

    Adaptive Optimizers in Large Language Model Pre-Training: How AdamW, Adafactor, and Lion Scale Gradient Updates Across Billions of Parameters Large language model pre-training requires optimizing billions of parameters over trillions of tokens across distributed GPU clusters. Standard stochastic gradient descent (SGD) fails in this regime because Transformer loss landscapes are severely ill-conditioned, with gradient magnitudes differing by orders of magnitude across layers and token positions.

    AI
    11 min read
  15. Waymo Details Custom 5nm ASIC and Heterogeneous Compute Architecture for Robotaxis

    Alphabet subsidiary Waymo has disclosed the architectural specifications of the computing platform powering its sixth-generation autonomous driving system, revealing a custom 5-nanometer application-specific integrated circuit (ASIC) engineered specifically for front-end sensor ingestion and edge machine learning. The disclosure, authored by VP of Engineering Satish Jeyachandran and Compute Lead Daniel Rosenband, details how the company processes raw data from onboard sensor arrays in real time

    Autonomous Vehicles
    2 min read
  16. Speculative Tool Execution and Parallel Action Graphs in Production AI Agents: DAG Scheduling, Optimistic Concurrency, and Side-Effect Rollback

    Autonomous AI agents operating in complex environments (such as software engineering, scientific discovery, and automated workflow orchestration) face an operational bottleneck: execution latency. While foundation models have become faster at token generation, the standard agent interaction loop remains strictly serial. A model reasons, outputs a single tool call, halts generation, waits for the external environment to return a result, appends the output to context, and resumes reasoning. In mu

    AI
    5 min read
  17. Classifier-Free Guidance: How Score Extrapolation and Implicit Classification Steer Generative Models

    Conditional generative models face an inherent tension between mode coverage and prompt adherence. When a model is trained to maximize data log-likelihood, its learned distribution matches the broad, messy variety of the underlying dataset. In unconditional generation, this diversity is desirable. In conditional generation, however, unconditional priors dilute the prompt: models generate generic, average samples that only weakly align with nuanced text descriptions, spatial layouts, or class lab

    AI
    9 min read
  18. Mistral Launches Agentic Search Toolkit with Active Navigation Primitives

    Mistral AI has released Agentic Search, a document retrieval system and developer toolkit designed to replace standard one-shot retrieval-augmented generation with an interactive navigation loop. The capability is integrated into the Mistral Search Toolkit and available within Libraries across Mistral Studio and Vibe. Traditional RAG architectures retrieve a fixed set of top-k text chunks during an initial query pass and require the language model to generate a final answer immediately. In long

    Mistral
    2 min read
  19. Contrastive Language-Image Pre-Training (CLIP): How Joint Multi-Modal Embeddings Bridge Vision and Language

    Before 2021, computer vision models were largely constrained by closed-set supervised classification. Deep convolutional networks like ResNet were trained to predict one of exactly 1,000 discrete categories on ImageNet via a final linear layer and a softmax cross-entropy objective. This setup created rigid models: classifying an unencountered category or adapting to downstream domain shifts required throwing away the classification head, collecting thousands of labeled samples, and retraining or

    AI
    8 min read
  20. Generalist AI Releases GEN-1.5: One-Shot In-Context Learning for Robotic Manipulation

    Robotics research startup Generalist AI announced GEN-1.5, an embodied foundation model capable of learning closed-loop physical manipulation tasks from a single demonstration without gradient updates or fine-tuning. The model adapts through in-context physical prompting, mirroring the few-shot learning dynamics originally identified in autoregressive language models. GEN-1.5 processes multimodal inputs including multi-view video, proprioceptive signals, sensor feeds, and natural language instr

    Robotics
    2 min read