China AI Labs Sell Half-Price Tokens on Tmall for Double 11
Zhipu, MiniMax, Alibaba Cloud, Qwen Office and Qoder cut token and subscription plans to half price or less on Tmall for Double 11. The deals, the catch.
News on Qwen, Alibaba's family of open AI models. Recent stories cover Qwen 3.8 27B and its overthinking habit, Qwen3.8-Flash-Next, Unsloth's GGUFs for Qwen, Thomson Reuters building a legal LLM on Qwen, and 150K+ Qwen derivatives on Hugging Face.
Zhipu, MiniMax, Alibaba Cloud, Qwen Office and Qoder cut token and subscription plans to half price or less on Tmall for Double 11. The deals, the catch.
Alibaba opened a Qwen4-Max preview on Token Plan and Qoder until Nov 25. Its docs list a 1M-token context, but no benchmarks or open weights yet.
Nous Research fine-tuned Qwen3.8-27B into Arete-27B. On its own test, answers with propaganda fell from 22% to 0.9%, with no meaningful loss on skill tests.
Qwen is Alibaba's AI model family. The Qwen3.8 lineup, how its licenses differ, how to try it, and what Alibaba has said about Qwen 4.
Apple began testing Apple Intelligence in China on Nov 4 in an iOS 27.3 developer beta, with Alibaba's Qwen in Siri, Writing Tools and Visual Intelligence.
On October 29, 2026, Alibaba Cloud's CTO reportedly said "Qwen4 next week" in Amsterdam. What the slide showed, what is confirmed, and the Qwen Code clue.
Mistral Large 4, DeepSeek-V4.1-Flash and Qwen3.8-2.4T-A95B compared on cost per task, license, hardware and fit, from model cards and Artificial Analysis.
DiffuSpace's Clover-35B-A3B-Preview is an Apache 2.0 diffusion language model built from Qwen3.6-35B-A3B. How it works, its claimed scores and how to run it.
Alibaba has released the open weights for Qwen3.8-Flash-Next, a 125B-parameter multimodal Mixture-of-Experts (MoE) model that acts as an early architectural preview for the upcoming Qwen4 family. Operating with only 6B active parameters per token alongside a 51B N-gram embedding layer, the model targets cost efficiency across long-context reasoning, agentic coding, and multimodal workloads. For how it fits with Qwen3.8-Max, the open 2.4T weights and the Omni models, see our Qwen3.8 explainer. U
Thomson Reuters has unveiled "Thomson," its first proprietary domain-specific language model built specifically for legal workflows. Developed over two years at an investment of roughly $40 million in engineering and compute infrastructure, the model is designed to perform specialized legal analysis without ongoing dependence on third-party frontier API providers like OpenAI or Anthropic. The model is built on top of Alibaba's open-weight Qwen architecture, utilizing Qwen3.5-397B as its foundat
Alibaba Group Holding announced a proposed equity placement in Hong Kong to raise HK$80 billion ($10.2 billion), allocating 100% of net proceeds to expand its full-stack artificial intelligence capabilities across custom silicon, cloud compute infrastructure, and foundation model development. Transaction Structure and Market Scale According to terms reviewed by Reuters, Alibaba is offering 710 million ordinary shares at HK$112.70 per share, representing a 3.6% discount to its latest closing p
Hugging Face has published its State of Open Models: Summer 2026 report, detailing seven months of platform metrics that highlight a widening divergence between benchmark attention and production deployment. According to the analysis covering January through August 2026, public model repositories on the Hub grew from 2.43 million to 2.96 million, public datasets surpassed 1 million for the first time, and Spaces expanded to 1.44 million. Despite the catalog expansion, usage remains heavily conc
Unsloth AI has published its Dynamic V3.0 quantization suite for Alibaba's Qwen 3.8 27B model family, releasing optimized GGUF and NVFP4 checkpoints alongside public calibration matrices. The release claims a greater than 10 percent increase in top-1 percent accuracy at identical file sizes compared to standard baseline quantizations, while introducing an ultra-low-bit dynamic tier that operates within 8GB of memory. Qwen 3.8 27B is a dense vision-language model utilizing hybrid attention layer
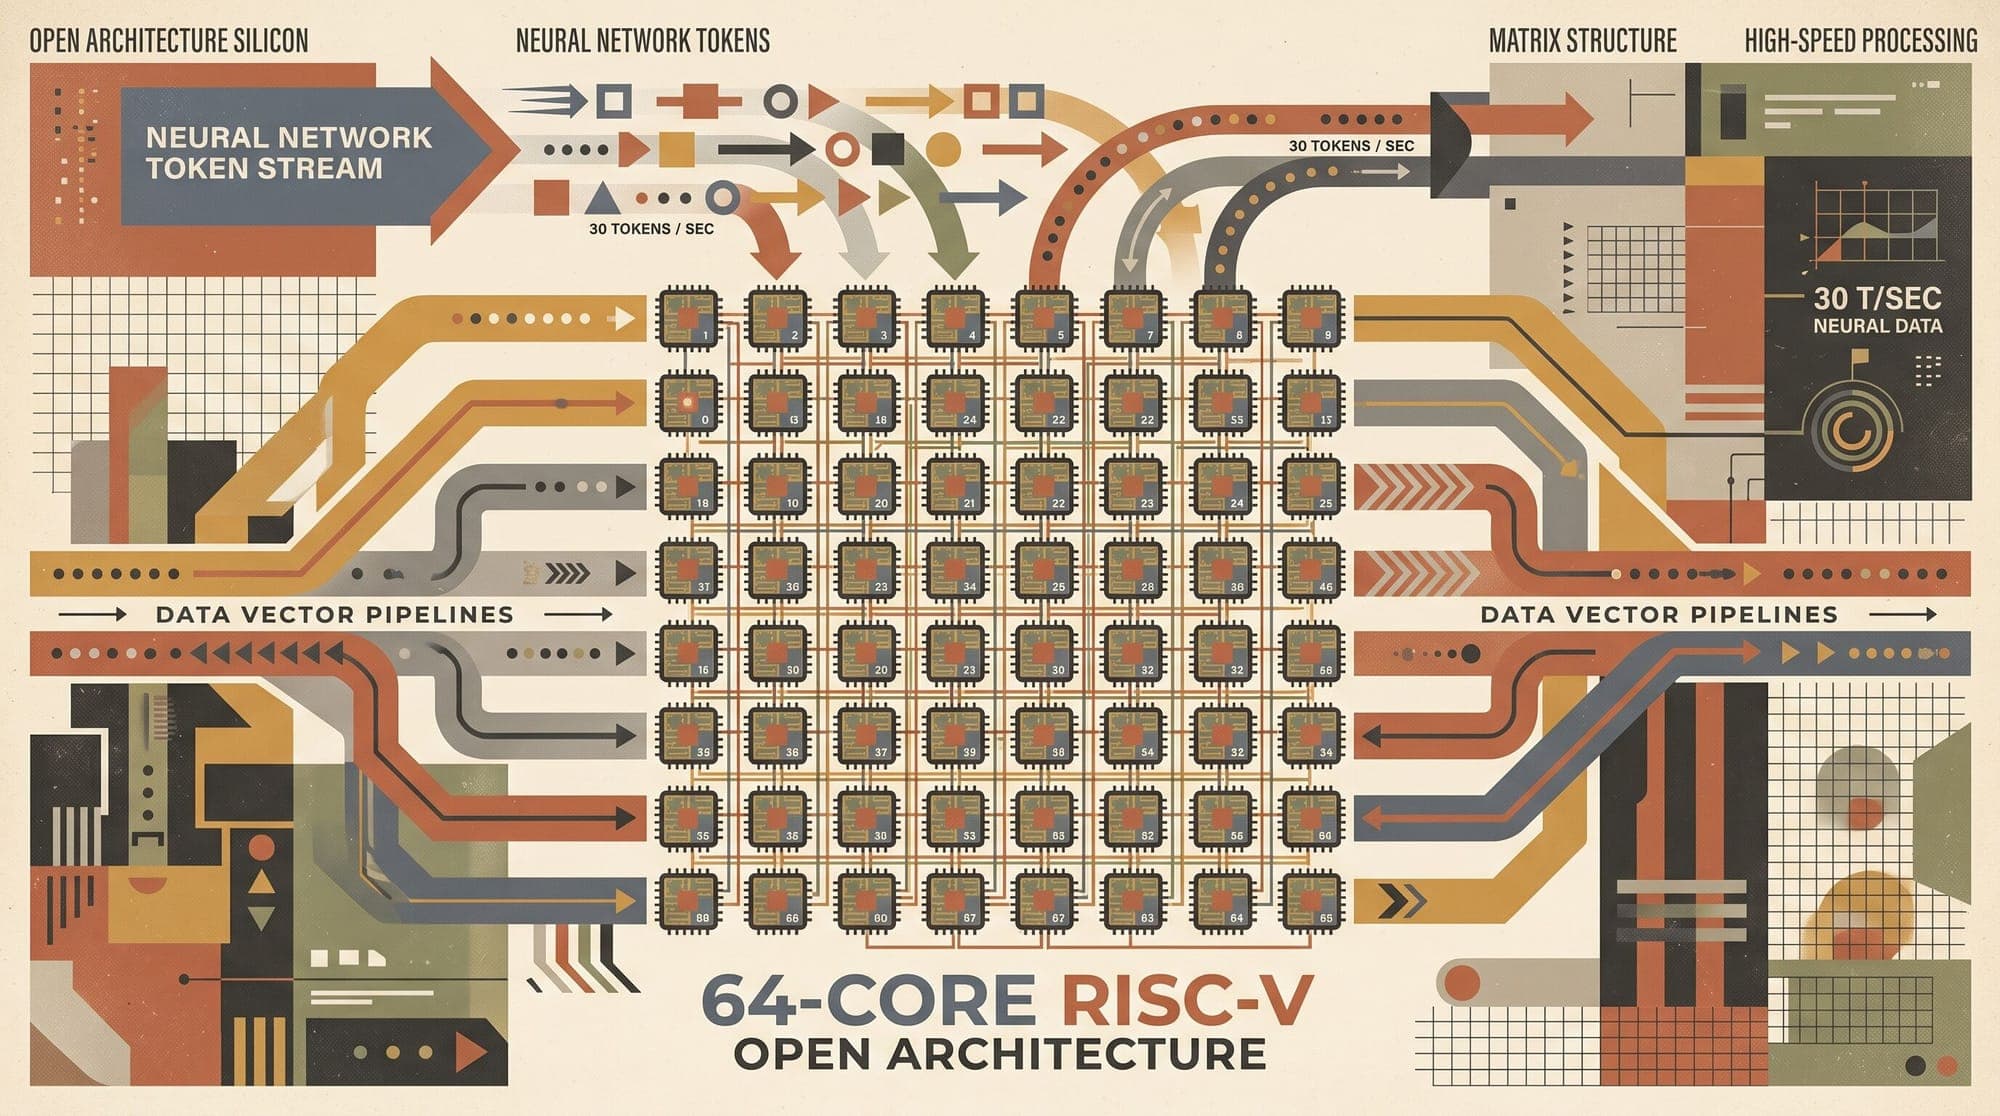
Alibaba's semiconductor division, T-Head, announced day-zero native inference support for its latest open-weight model, Qwen 3.8 27B, running directly on the XuanTie C950 RISC-V server processor. Operating without discrete graphics processing units, the 64-core RISC-V chip delivered sustained decode throughput of 30 tokens per second alongside a time-to-first-token latency of 1.9 seconds. Update, October 29, 2026: a developer has since gone the other way and compiled a 32-bit RISC-V CPU into th
Alibaba's Qwen research lab released Qwen 3.8 27B, a 27-billion-parameter Apache 2.0 licensed AI model available in 17GB GGUF format that can run on high-end consumer laptops. The model supports vision, long contexts, and tool calling. Our Qwen3.8 explainer shows where the 27B sits in the rest of the family. The over-thinking problem Qwen's documentation describes the model as defaulting to xhigh for reasoning effort, a setting designed for complex tasks demanding thorough analysis. In practi