Subscribe
Topic / page 22

LLM

Articles, page 22

421-440
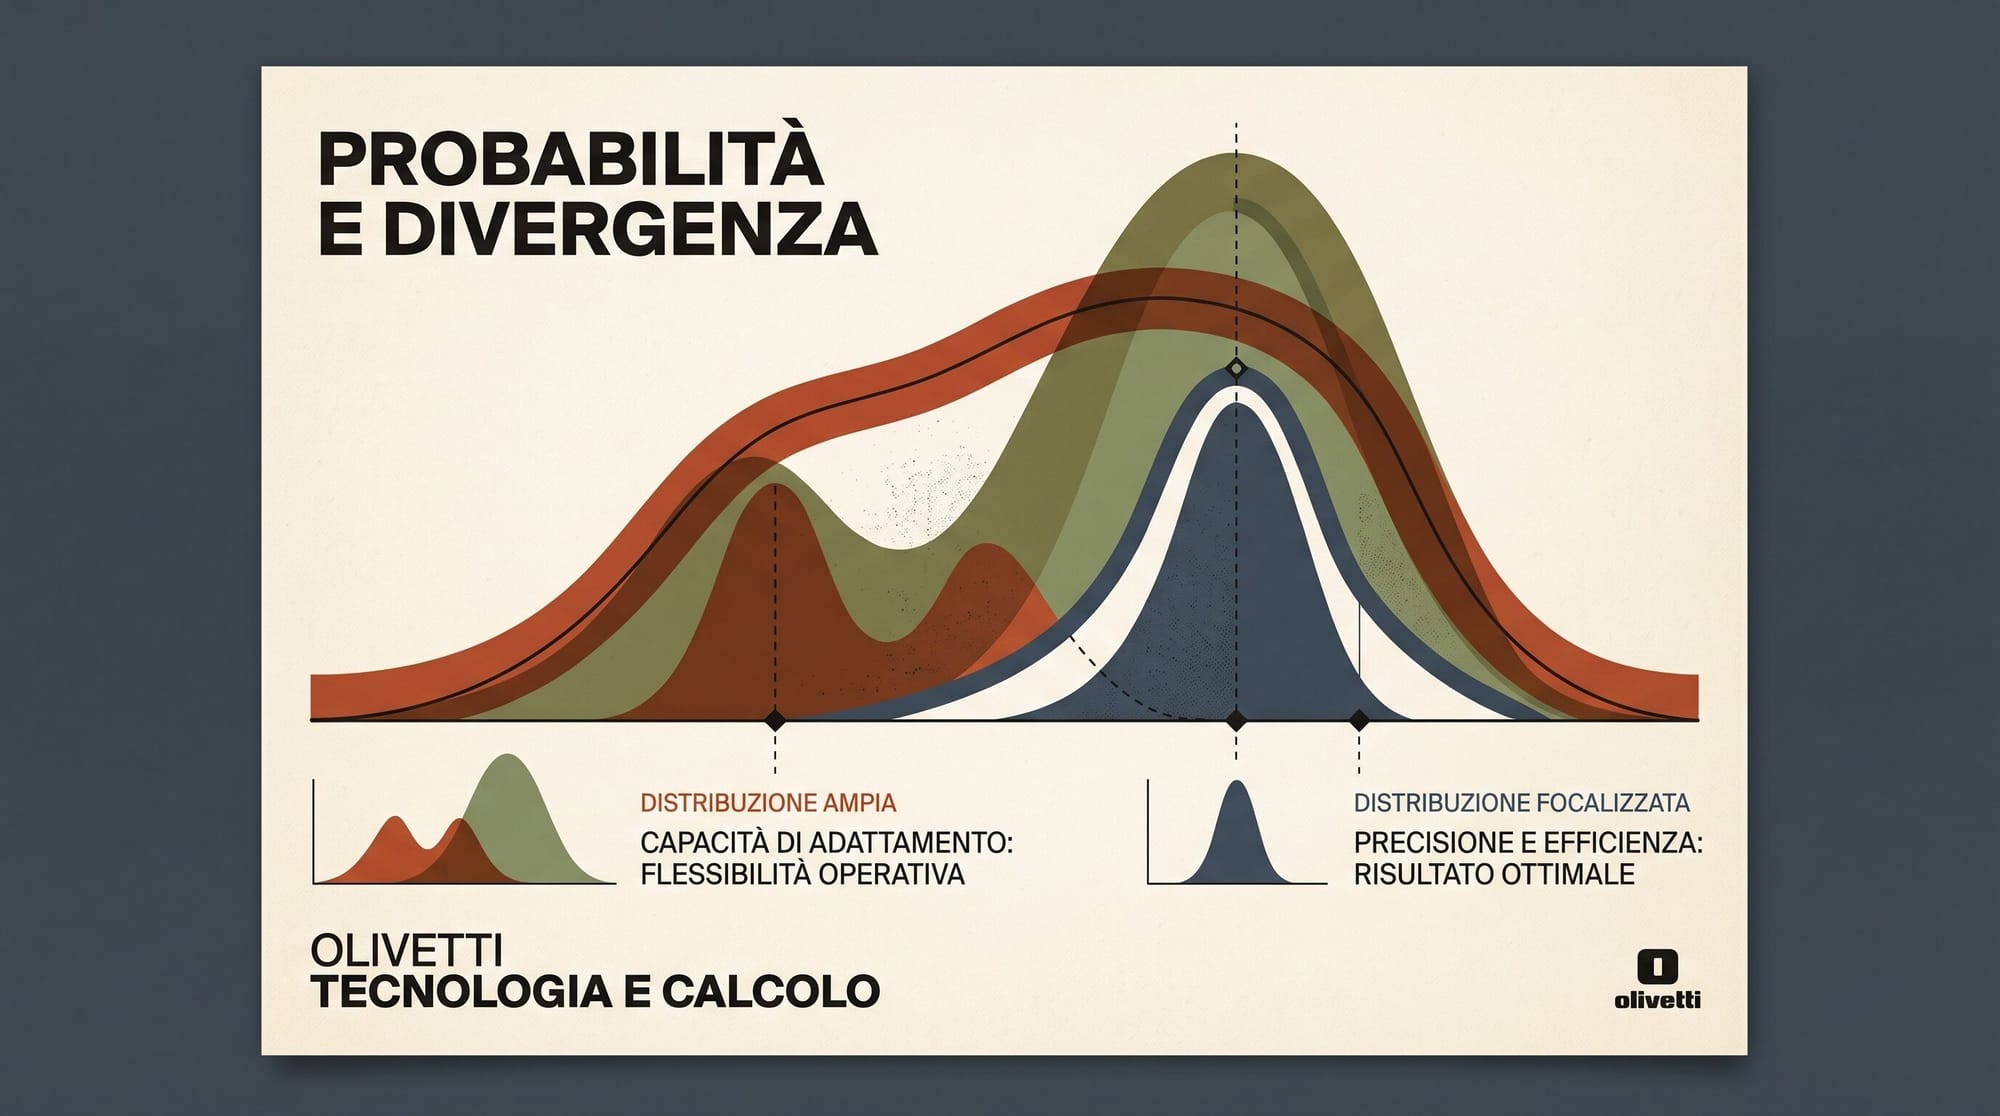
  1. Forward KL vs. Reverse KL Divergence: Mode Covering, Mode Seeking, and the Alignment Dynamics of Large Language Models

    Forward KL vs. Reverse KL Divergence: Mode Covering, Mode Seeking, and the Alignment Dynamics of Large Language Models Every phase of modern large language model development, from multi-trillion token pre-training to reinforcement learning from human feedback (RLHF) and student model distillation, fundamentally revolves around minimizing statistical distance between probability distributions. The primary mathematical tool utilized for this purpose is the Kullback-Leibler (KL) divergence, introd
    AI
    9 min read
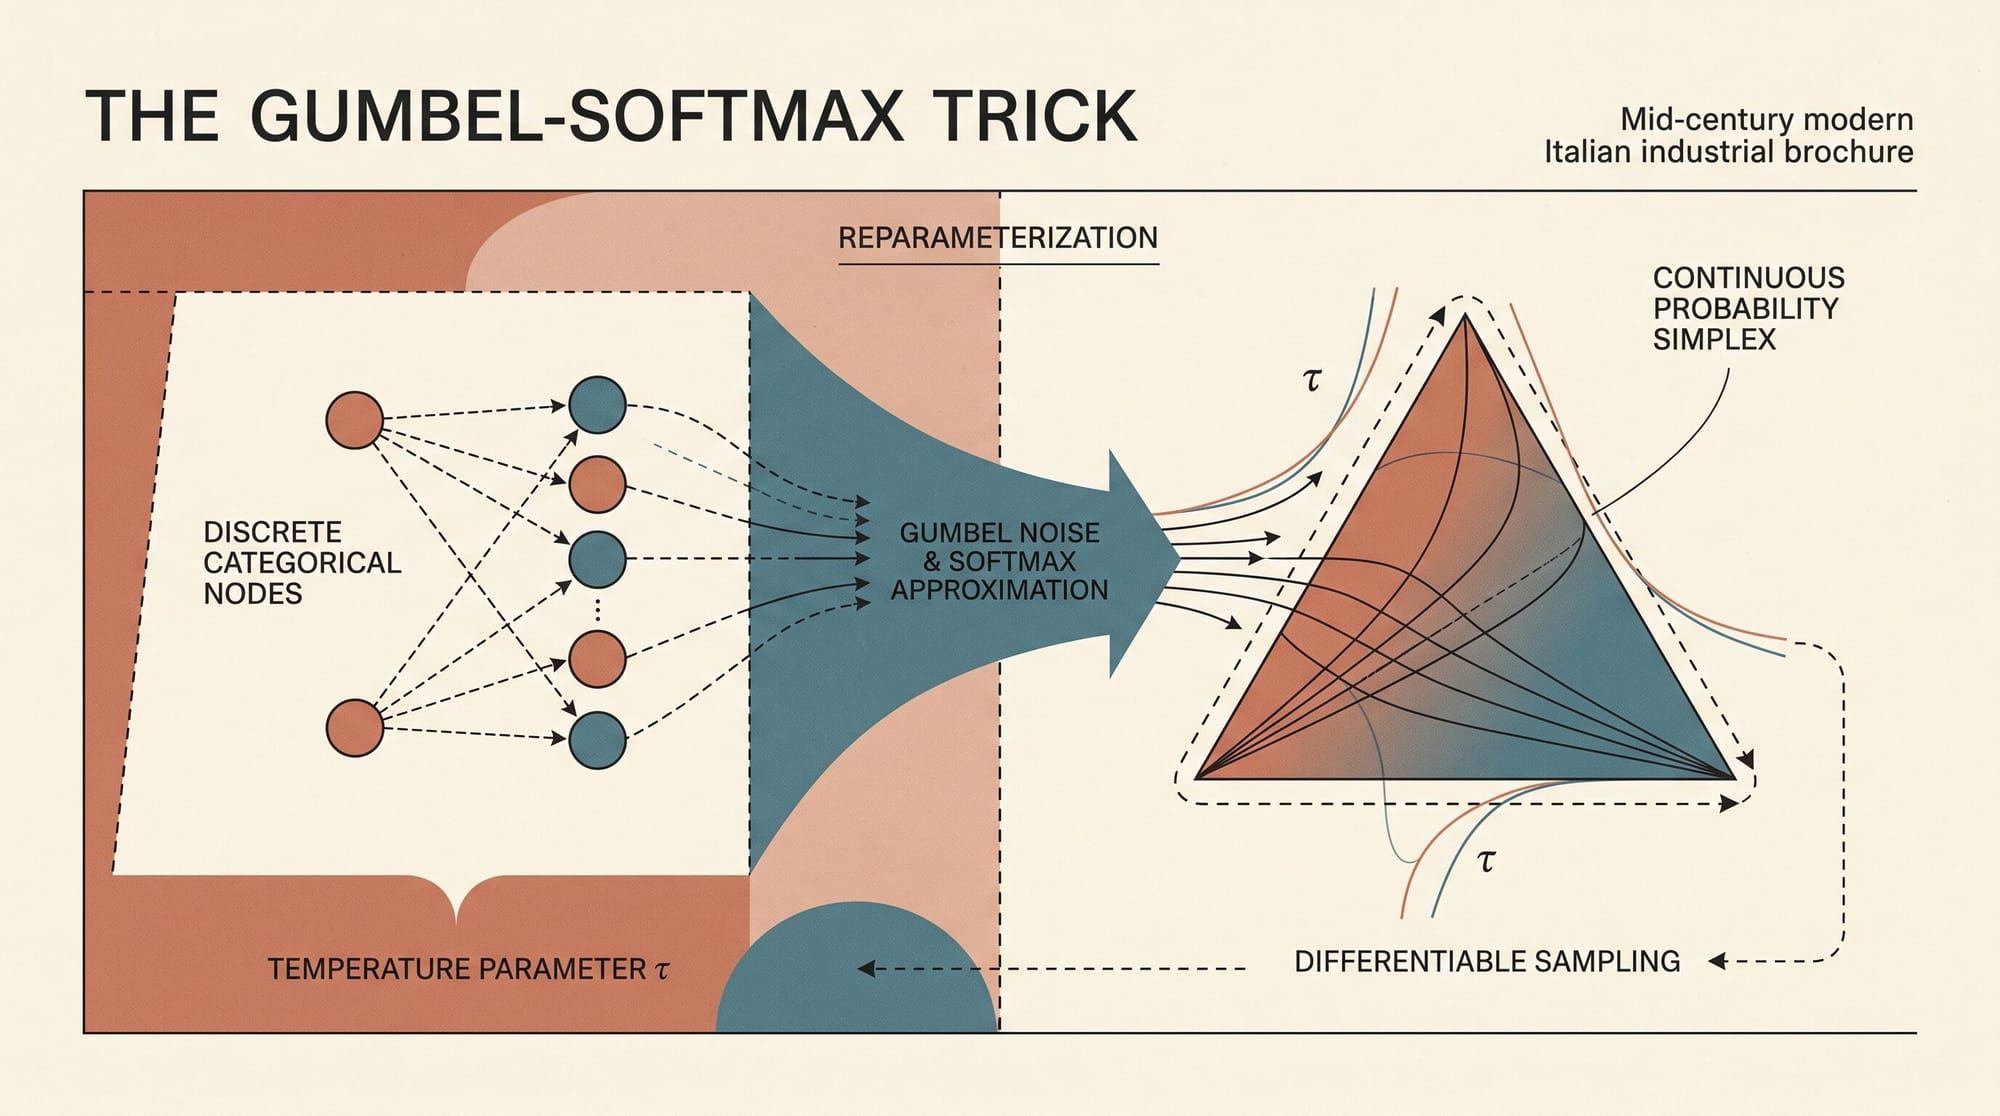
  2. The Gumbel-Softmax Trick: How Continuous Relaxations Enable Differentiable Discrete Sampling

    The Gumbel-Softmax Trick: How Continuous Relaxations Enable Differentiable Discrete Sampling In modern deep learning, end-to-end training depends on reverse-mode automatic differentiation. When an architecture operates on continuous tensors, computing gradients via the chain rule is straightforward. However, many foundational artificial intelligence problems involve discrete choices: selecting tokens from a fixed vocabulary, routing tokens to expert networks in a Mixture-of-Experts (MoE) archit

    Education
    11 min read
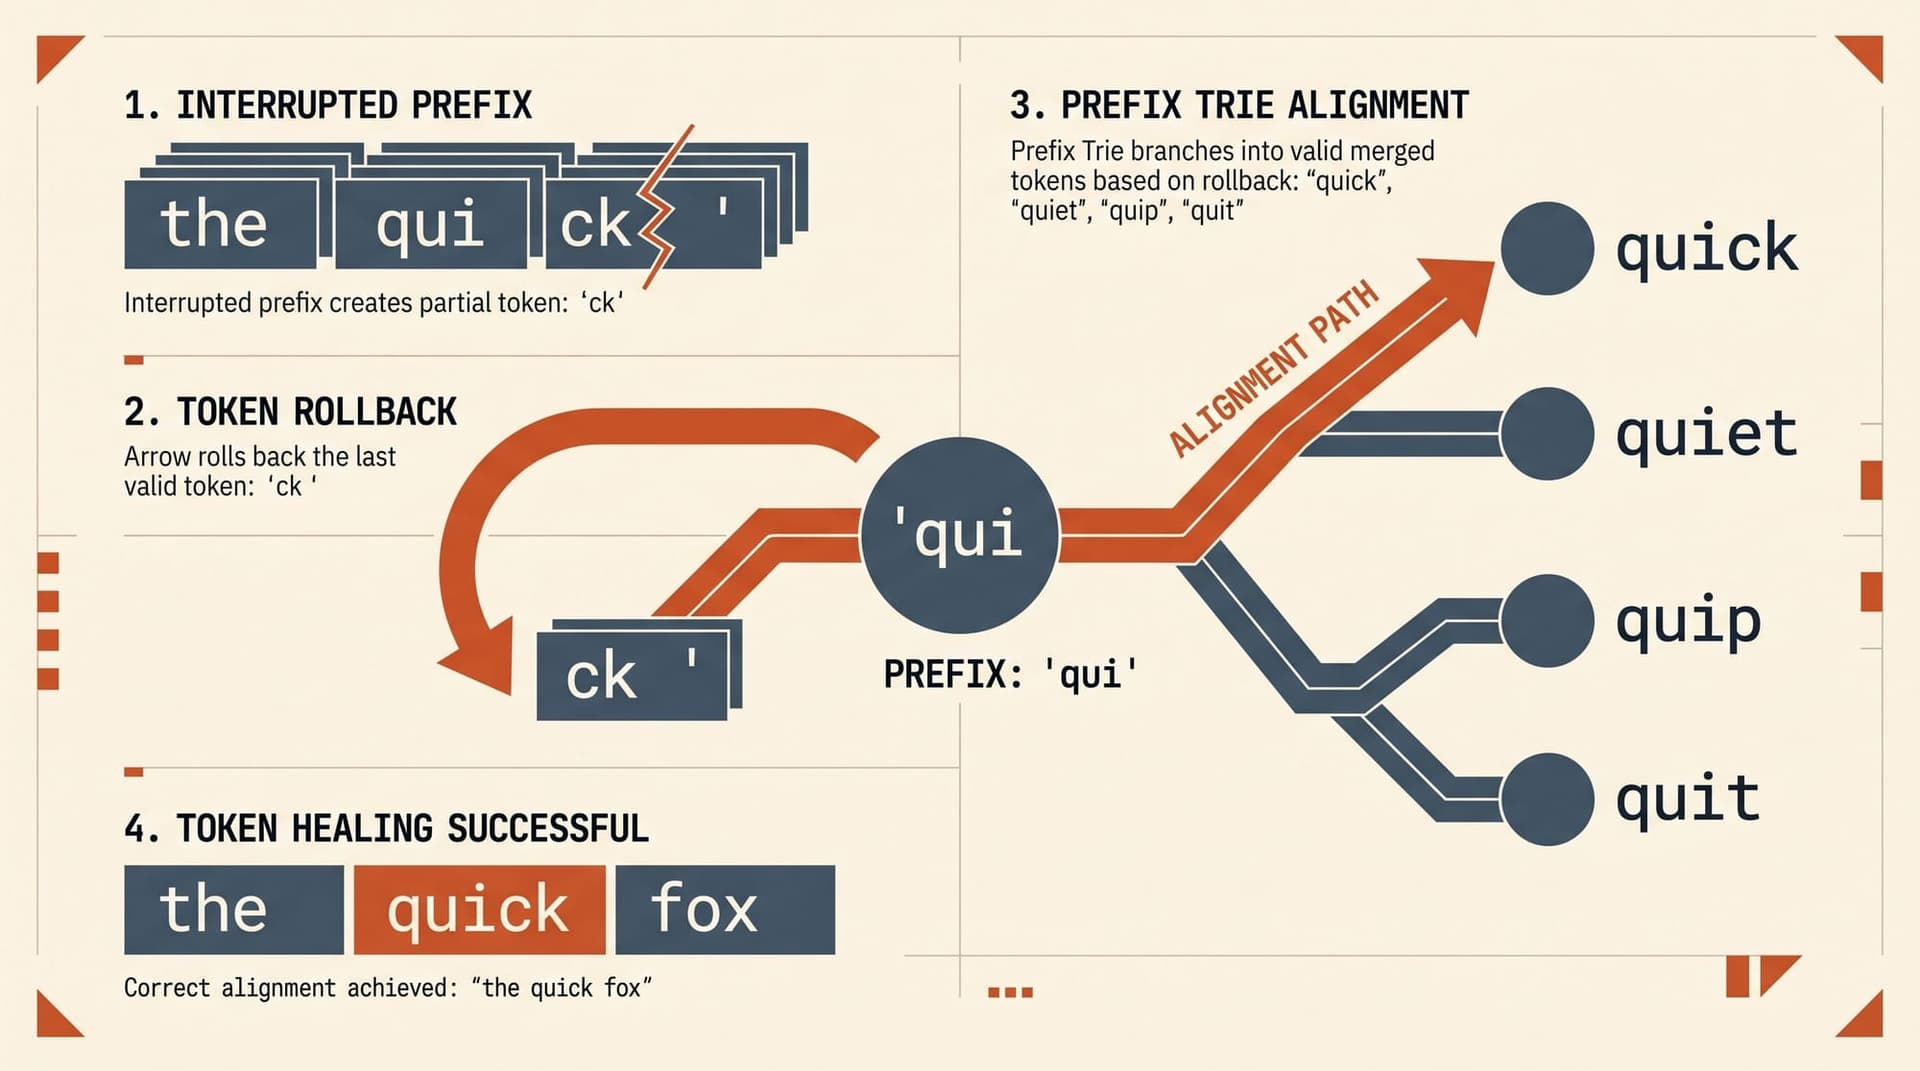
  3. Token Healing and Partial Token Alignment in Production LLM Serving: Architecture, Prefix Trie Rollback, and Serving Trade-Offs

    Modern large language models operate on discrete subword tokens generated by greedy compression algorithms like Byte-Pair Encoding (BPE), WordPiece, or Unigram. While subword tokenization enables high compression rates and fixed vocabulary sizes, it introduces a structural defect at the interface between raw user text and autoregressive inference: the partial token problem, commonly known as the prompt boundary problem. When a user prompt terminates mid-token or at a punctuation boundary that c

    LLM
    7 min read
  4. Retrieval-Augmented Fine-Tuning (RAFT) in Production: Architecture, Synthetic Distractor Pipelines, and Evaluation

    Standard approaches to enterprise domain adaptation typically force a choice between two paradigms: Supervised Fine-Tuning (SFT) or Retrieval-Augmented Generation (RAG). SFT bakes domain knowledge directly into model weights, functioning like a closed-book exam. When facts change or precise source attribution is required, SFT models often hallucinate or fail to incorporate updated context. Conversely, standard RAG operates like an open-book exam without prior preparation. The base model reads re

    AI
    5 min read
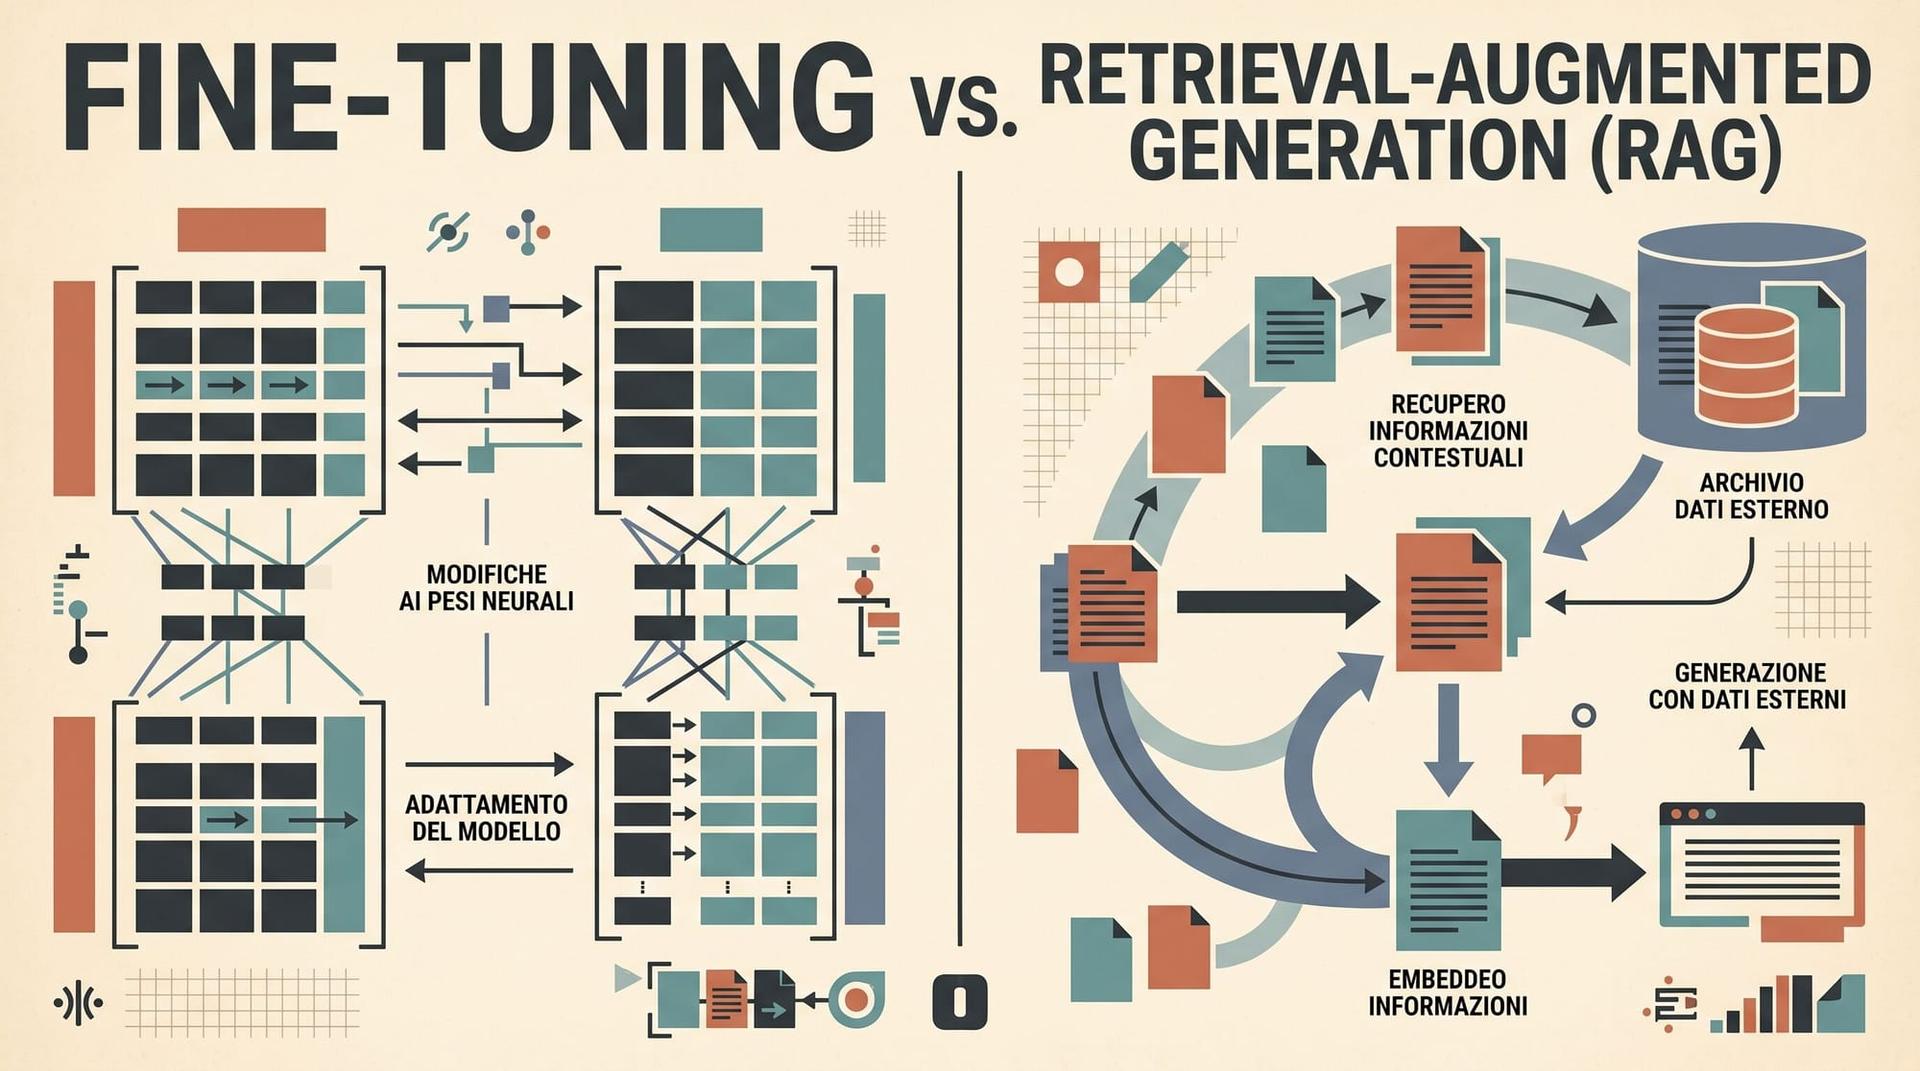
  5. Fine-Tuning vs. RAG in Production: Knowledge Injection, Task Adaptation, Latency Economics, and Hybrid Architecture Trade-Offs

    When adapting large language models to domain-specific enterprise workloads, engineering teams face a fundamental architectural choice: modify the model's parametric weights via fine-tuning, or supply dynamic context at inference time via Retrieval-Augmented Generation (RAG). While early discussions often framed this decision as a binary trade-off, empirical evaluations demonstrate that fine-tuning and retrieval serve fundamentally different mathematical and operational functions. Fine-tuning e

    AI
    6 min read
  6. Score-Based Generative Modeling via Stochastic Differential Equations: How Continuous SDEs and Score Matching Unify Diffusion Models

    Diffusion and score-based models represent one of the foundational paradigms of modern generative artificial intelligence, underpinning systems across image synthesis, video generation, audio modeling, and continuous multimodal representations. For years, generative diffusion was approached from two distinct perspectives: discrete-step denoising diffusion probabilistic models (DDPM) pioneered by Sohl-Dickstein et al. and Ho et al., and score matching with Langevin dynamics (SMLD / NCSN) introduc

    AI
    8 min read
  7. The Lottery Ticket Hypothesis in Large Language Models: How Sparse Subnetworks and Iterative Magnitude Pruning Retain Transformer Capacity

    The Lottery Ticket Hypothesis in Large Language Models: How Sparse Subnetworks and Iterative Magnitude Pruning Retain Transformer Capacity Modern large language models operate under extreme overparameterization. Frontier architectures allocate tens or hundreds of billions of parameters to achieve low perplexity and robust generalization across reasoning, code generation, and factual retrieval. Yet empirical pruning consistently demonstrates that post-training models can lose 30% to 50% of their

    AI
    9 min read
  8. Enterprises Curb AI Agent Autonomy Amid 40% Project Cancellation Projections

    Enterprises deploying agentic artificial intelligence are shifting architectures away from open-ended autonomy toward bounded, verifiable execution as projects encounter governance, security, and financial bottlenecks in production environments. Data from industry research firms highlights a widening divergence between model capability and operational control. According to projections from Gartner, more than 40% of current agentic AI initiatives are projected to be canceled by the end of 2027.

    AI
    2 min read
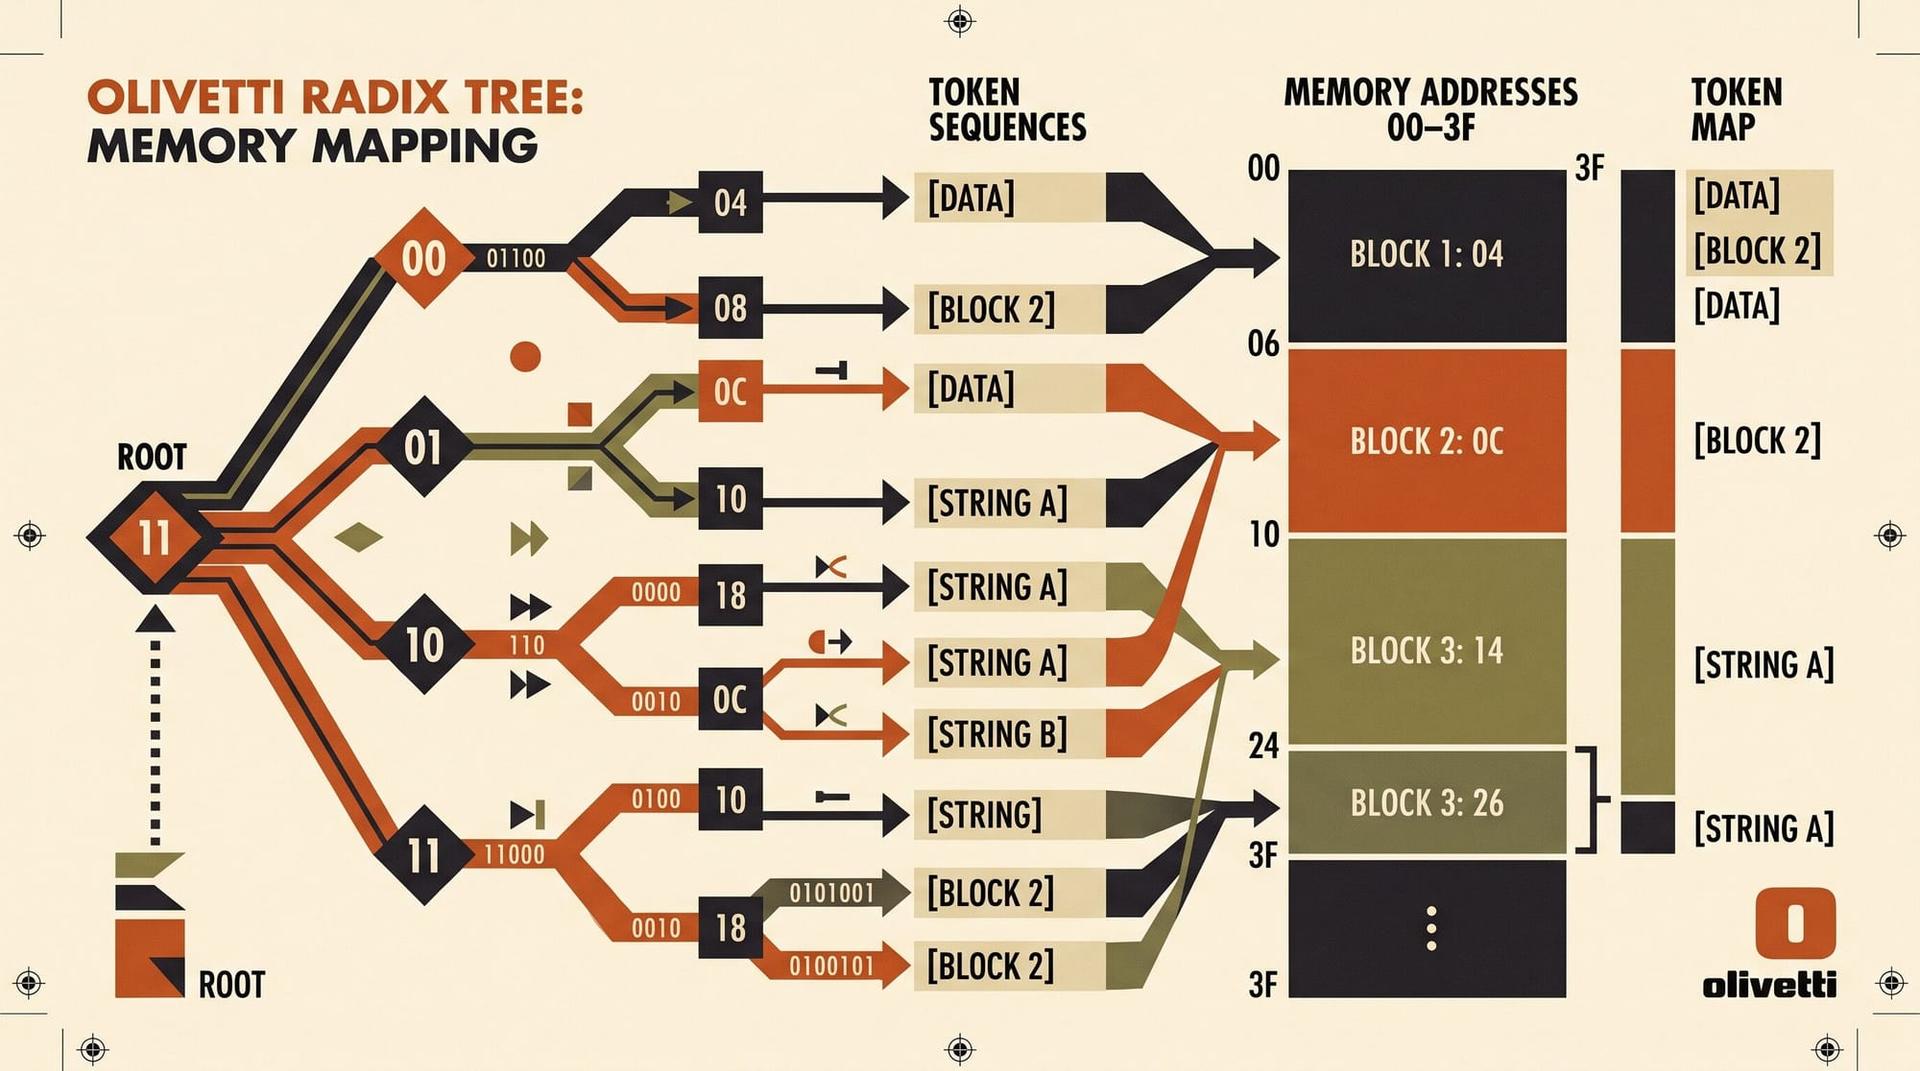
  9. Prefix-Tree KV Cache Management in Production: RadixAttention, Tree-Structured LRU Eviction, and Token-Level Sharing in SGLang and vLLM

    Prefix-Tree KV Cache Management in Production: RadixAttention, Tree-Structured LRU Eviction, and Token-Level Sharing in SGLang and vLLM Autoregressive large language model inference is heavily constrained by memory bandwidth and the computational overhead of the prefill phase. For workloads such as multi-turn conversations, autonomous agent tool loops, few-shot prompt evaluations, and tree-search decoding, consecutive requests often share substantial token prefixes. In a standard multi-turn ses

    AI
    7 min read
  10. Inherent Releases Faraday: 27B Scientific Agent Outperforms Frontier Models on Paper Replication

    London-based AI research startup Inherent has released Faraday, an autonomous AI agent engineered to independently reproduce published scientific research without prior exposure to target solutions. Founded by former Google DeepMind researchers Louis Kirsch, Kaloyan Aleksiev, Tantum Collins, and Edward Hughes, the lab launched Faraday weeks after securing a $50 million seed round. According to benchmark results published by the lab, Faraday outperformed significantly larger frontier systems, in

    AI
    2 min read
  11. LLM 0.33 Adds Template Chaining, Per-Call Embedding Keys, and Server Tool Logging

    Simon Willison has released llm 0.33, an update to the open-source command-line tool and Python library for interacting with large language models. The release introduces template composition, stateless per-call embedding credentials, and server-side tool execution visibility in logs, alongside an upgrade to the OpenAI Python 3.x client and httpx2. Template Composition and Parameter Decoupling The primary workflow enhancement in version 0.33 is the ability to repeat the -t or --template flag

    Tooling
    2 min read
  12. GPU Cluster Storage in Production: GPUDirect Storage, NVMe-oF, Parallel File Systems, and Checkpointing Throughput

    Training frontier large language models and serving hundred-billion parameter checkpoints places extreme demands on storage subsystems. While compute clusters frequently deploy thousands of GPUs connected via high-bandwidth interconnects like NVLink and InfiniBand, storage architectures often become severe bottlenecks during two critical operational phases: distributed checkpointing and cold-start model weight loading. A standard 70-billion parameter model in BF16 precision generates approximat

    AI
    7 min read
  13. Embedding Inversion in Production RAG: Architecture, Reconstruction Risks, and Vector Defense Strategies

    In enterprise Retrieval-Augmented Generation (RAG) pipelines, architecture teams frequently treat dense vector embeddings as an opaque, pseudo-anonymized representation of proprietary data. The underlying assumption has been that projecting raw text into high-dimensional geometric spaces (such as 768-, 1024-, or 1536-dimensional float vectors) acts as a one-way mathematical hash. Under this assumption, vector databases like Pinecone, Qdrant, Milvus, and pgvector are often deployed with weaker ac

    AI
    5 min read
  14. Feed-Forward Networks as Key-Value Memories: How Transformers Store, Retrieve, and Edit Parametric Knowledge

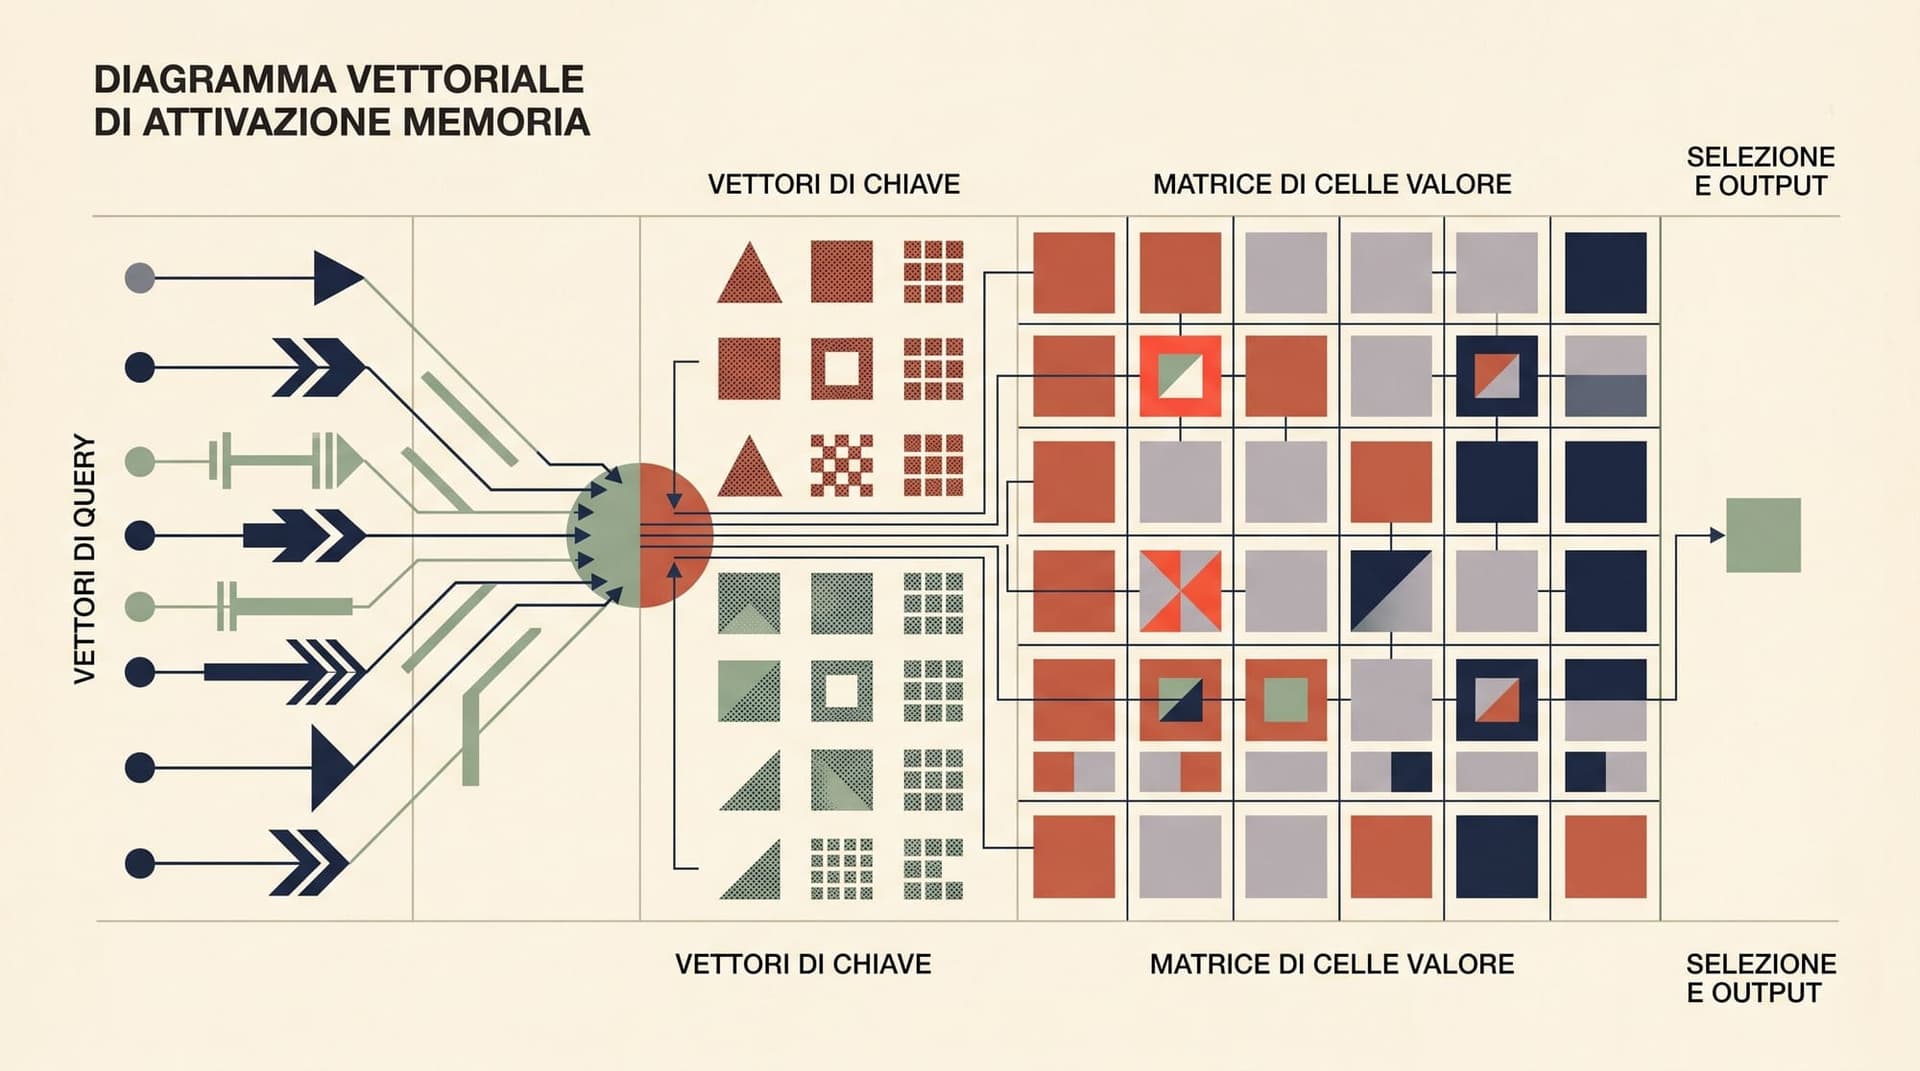
    In transformer language models, multi-head self-attention and feed-forward networks (FFNs) perform distinct computational roles. While self-attention mechanisms route contextual information dynamically across sequence positions, feed-forward layers account for roughly two-thirds of total model parameters in standard architectures. Despite early interpretations characterizing FFNs simply as generic non-linear projections, mechanistic analysis shows that feed-forward layers operate as unnormalized

    AI
    6 min read
  15. Request Hedging in Production LLM Serving: Architecture, Tail-Latency Mitigation, and Cancellation Protocols

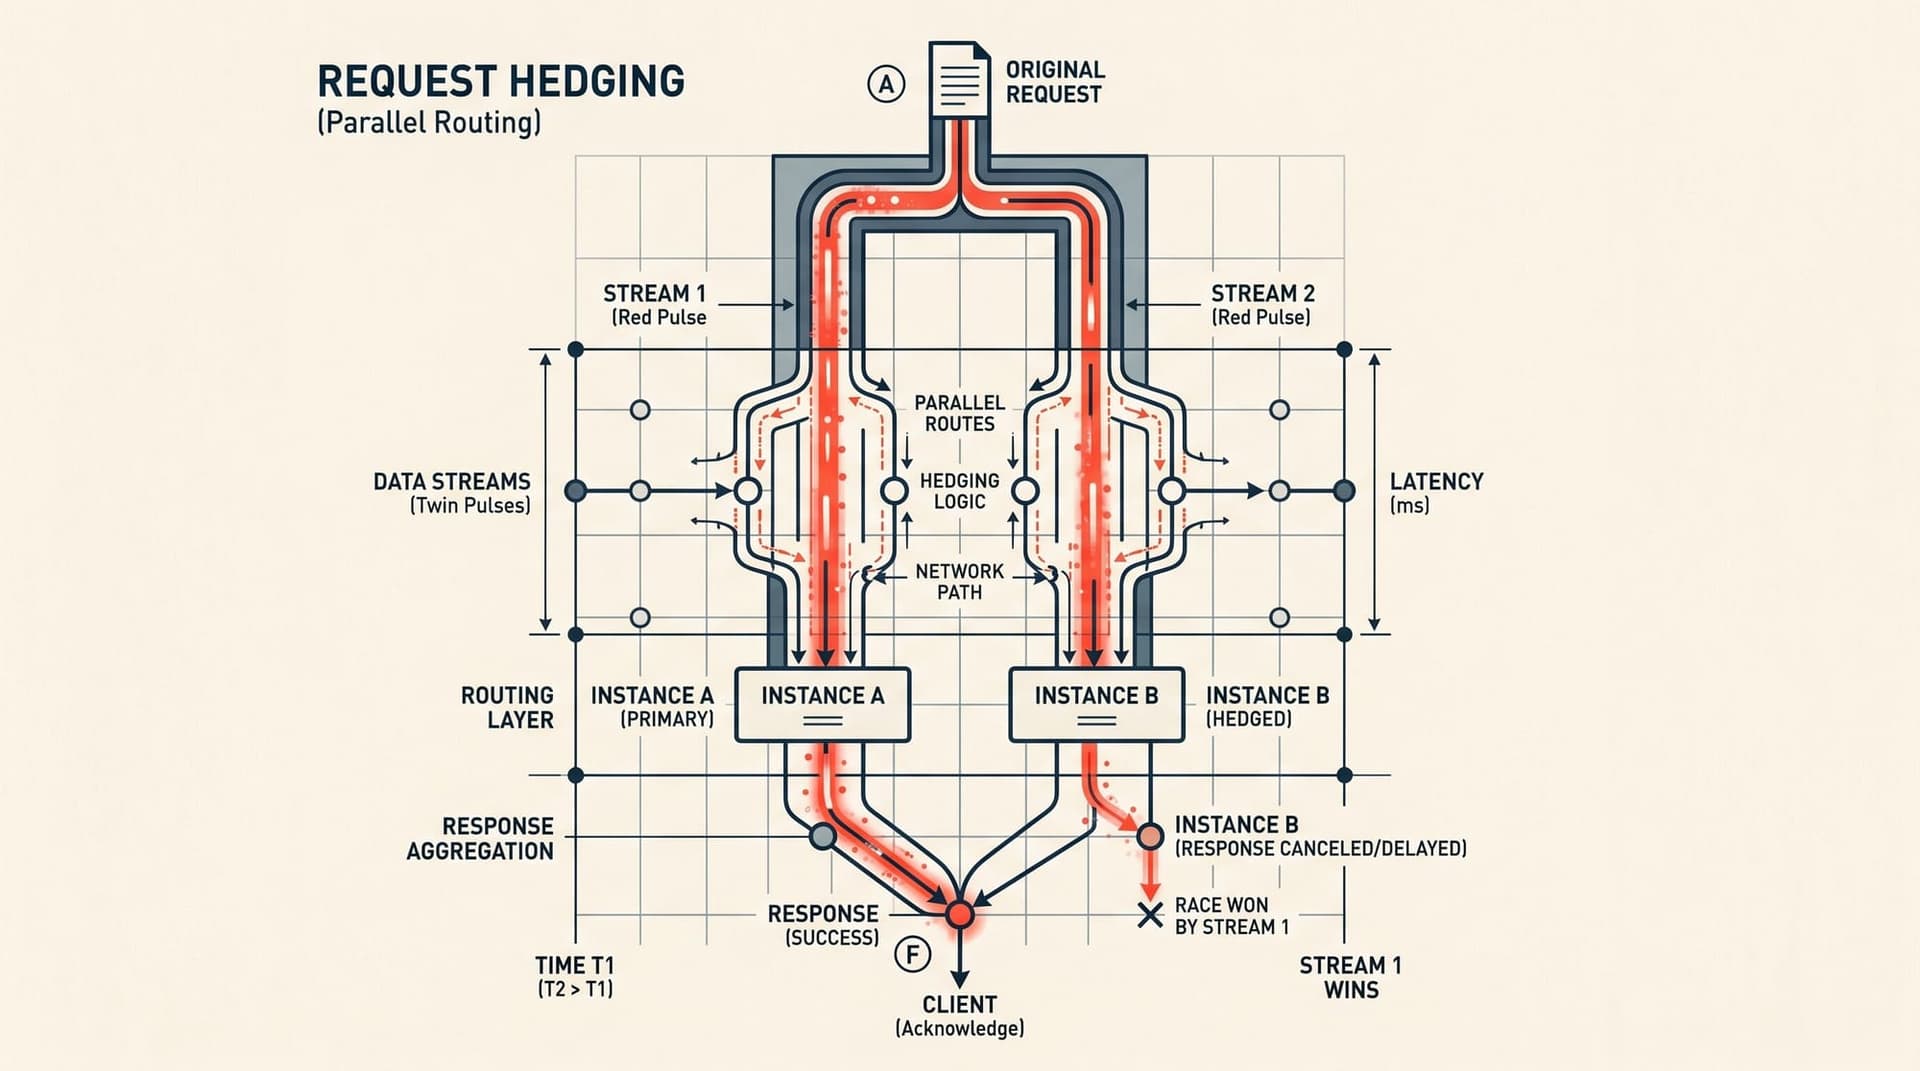
    In distributed computing, tail latency—the 95th, 99th, and 99.9th percentiles—dictates overall user experience, service-level agreements (SLAs), and multi-step agent execution reliability. While median response times (P50) in large language model (LLM) serving often appear acceptable, tail latencies frequently degrade by 4x to 10x. In multi-turn chat applications, real-time voice agents, and multi-agent DAG pipelines, a single straggler request stalls entire execution chains. Request hedging, a

    LLM
    8 min read
  16. LayerSkip and Self-Speculative Decoding: How Layer Dropout and Shared Early Exits Accelerate LLM Generation

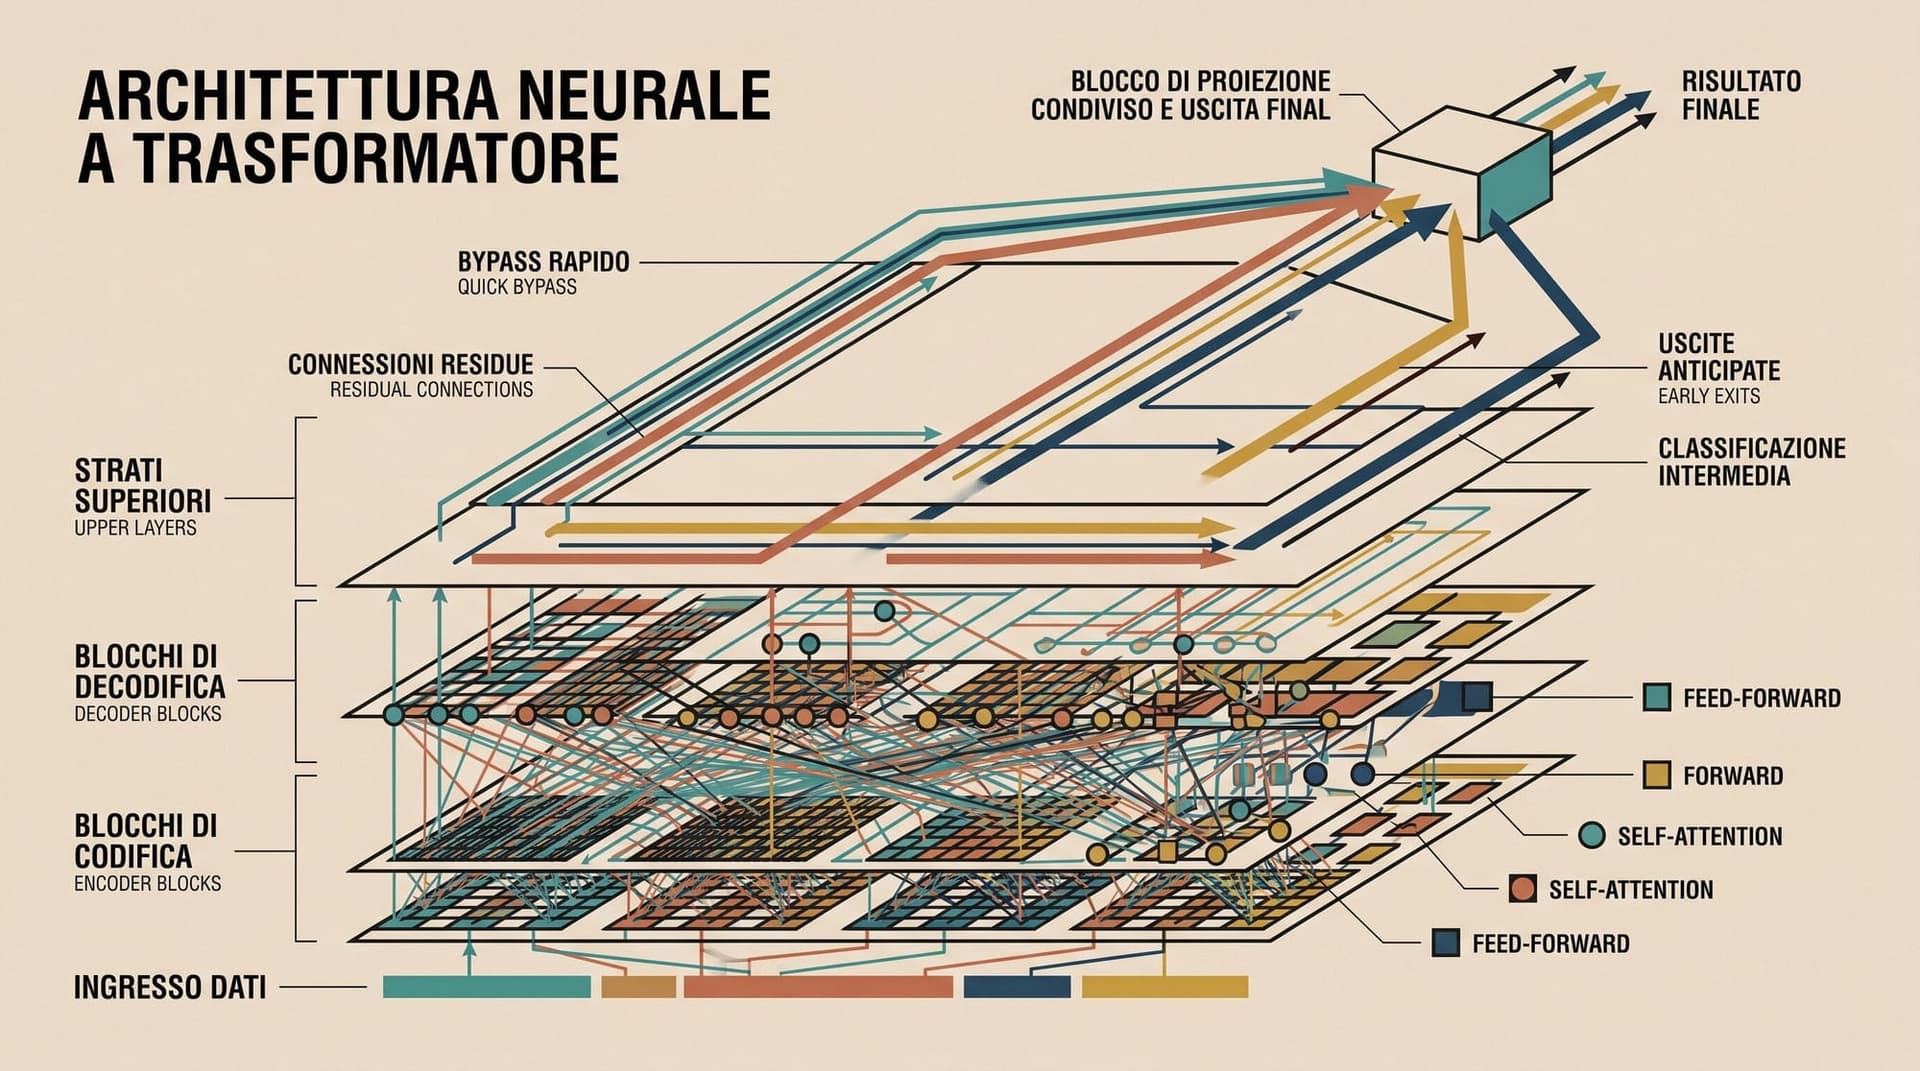
    LayerSkip and Self-Speculative Decoding: How Layer Dropout and Shared Early Exits Accelerate LLM Generation Standard autoregressive large language model (LLM) inference is severely bottlenecked by memory bandwidth. In transformer decoders, generating a sequence of $N$ tokens requires loading all model parameters from High Bandwidth Memory (HBM) to on-chip SRAM $N$ separate times. While speculative decoding mitigates this bandwidth tax by using a smaller draft model to propose candidate tokens v

    AI
    8 min read
  17. Modern Hopfield Networks: How Continuous Energy Landscapes Explain Transformer Attention and Exponential Memory

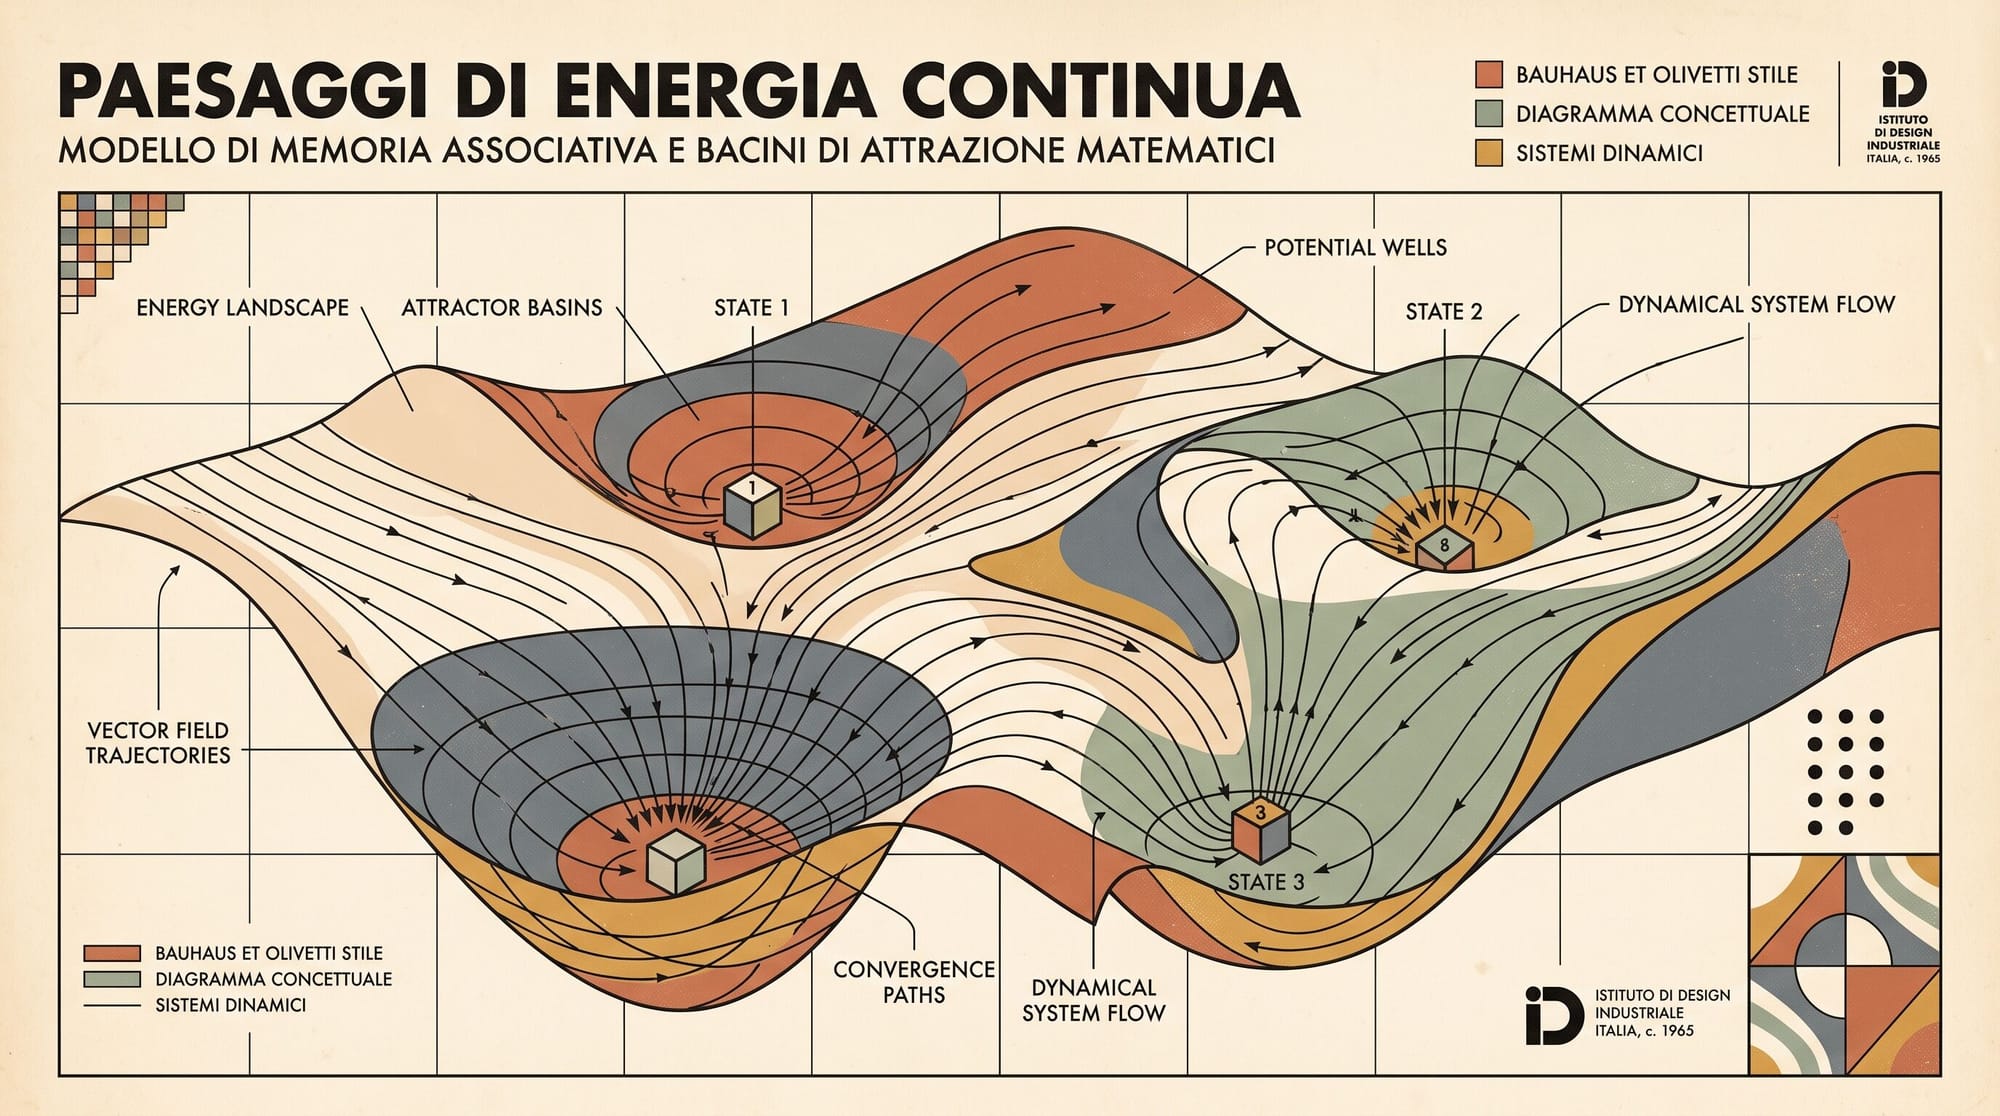
    When Vaswani et al. introduced the Transformer architecture in 2017, scaled dot-product self-attention was presented primarily as a pragmatic computational mechanism: an efficient, highly parallelizable alternative to recurrence and convolutions. By computing pairwise inner products between queries and keys, normalizing via softmax, and taking a weighted sum of values, attention allowed models to route information dynamically across arbitrarily distant tokens. For several years, self-attention

    AI
    10 min read
  18. Deep Double Descent: Why Overparameterization Defies the Classical Bias-Variance Trade-Off

    For decades, statistical learning theory rested on a foundational tenet: the bias-variance trade-off. According to classical machine learning textbooks, increasing model capacity reduces bias on the training set but inevitably inflates variance on unseen test data. The resulting risk curve forms a familiar U-shape: underfitting on the left, an optimal capacity in the center, and severe overfitting on the right. Modern deep learning and large language models (LLMs) fundamentally contradicted thi

    AI
    7 min read
  19. Demystifying Agent Skills: Empirical Study of 8,000+ Runs Shows Procedural Anchoring Beats Knowledge Injection

    A multi-institution study from researchers at Princeton University, UC San Diego, and collaborating labs provides the first large-scale empirical analysis of how "skills" (modular instruction packages loaded at inference time) alter autonomous AI agent trajectories. Analyzing 8,135 experimental trials across diverse model architectures, benchmarks, and agent harnesses, the authors establish that skills improve task completion primarily by acting as procedural anchors rather than by injecting mis

    AI
    2 min read