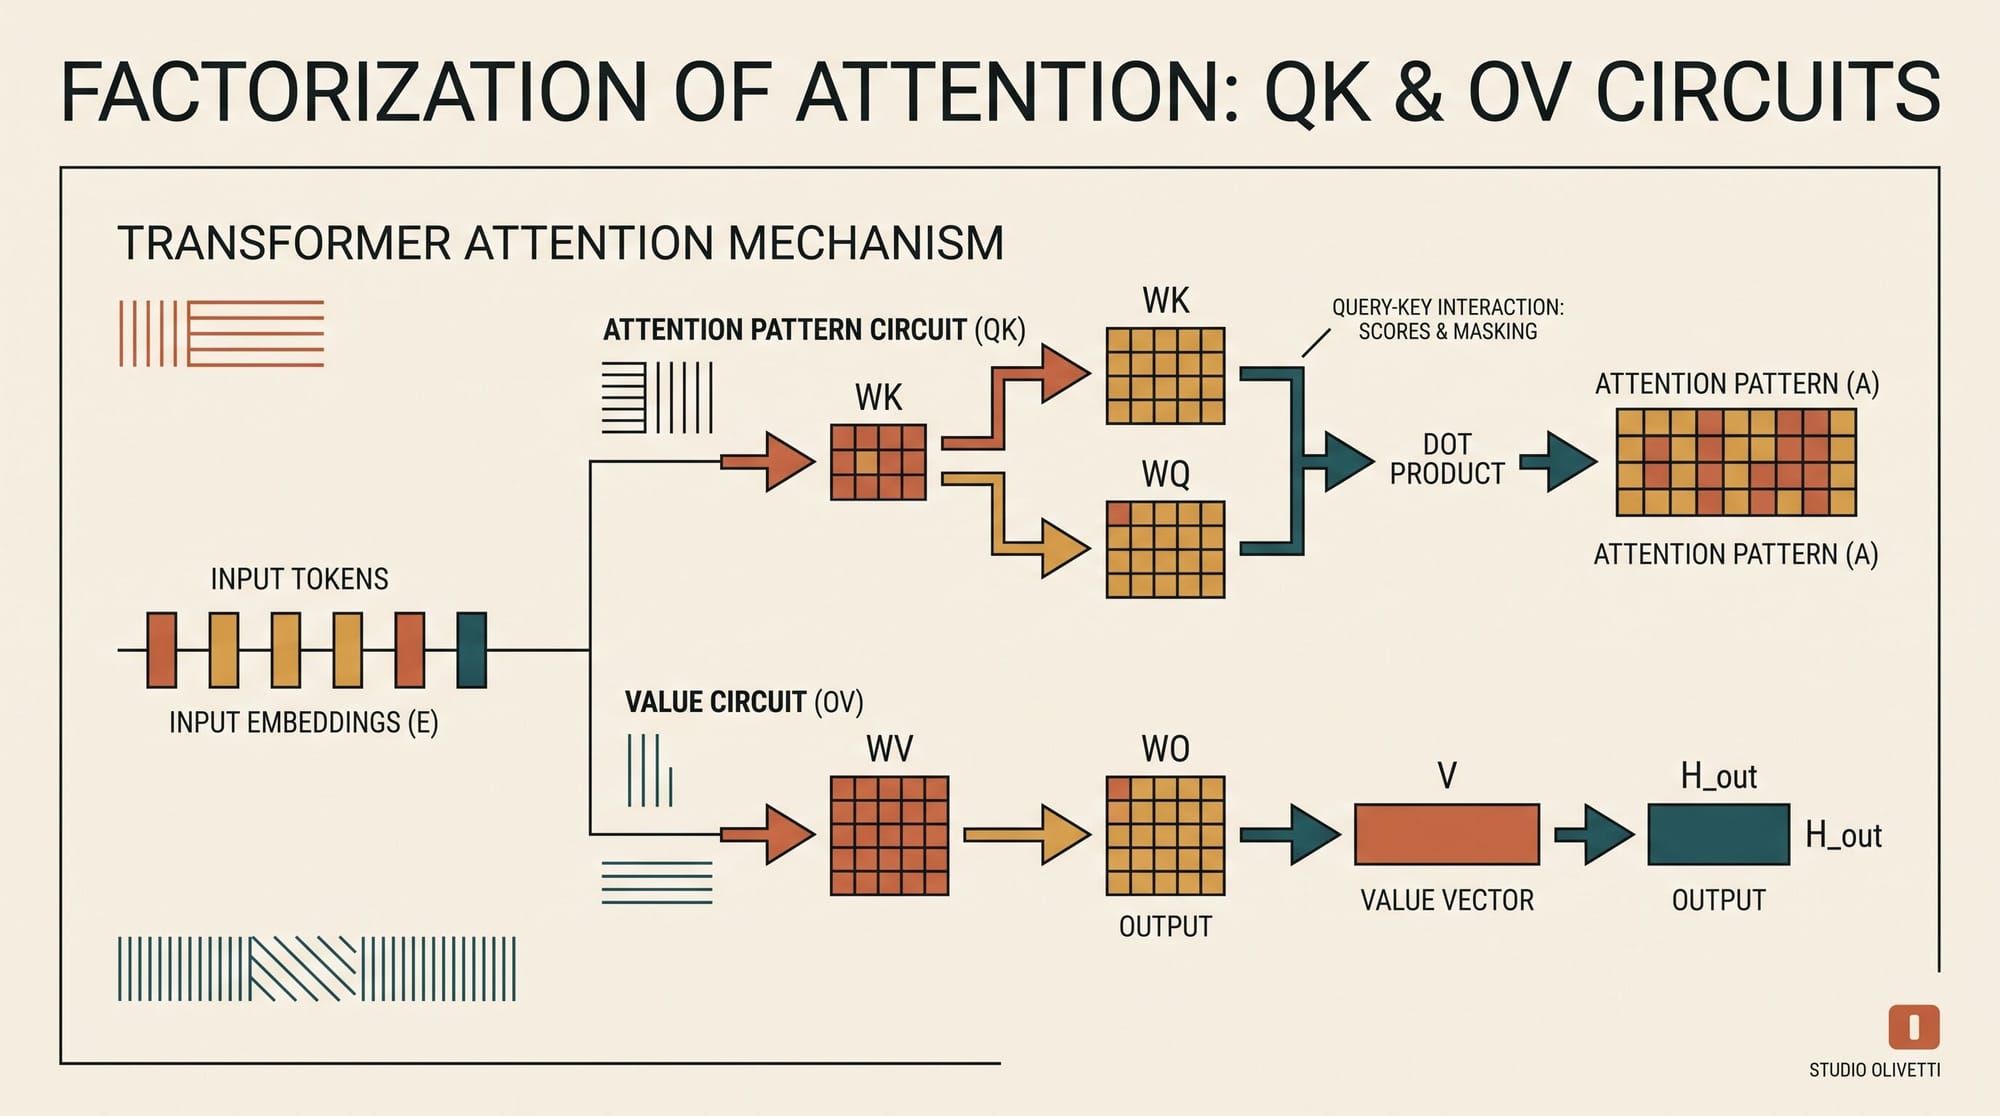
The QK and OV Circuits in Transformers: How Bilinear Attention Routing and Subspace Projections Move Information
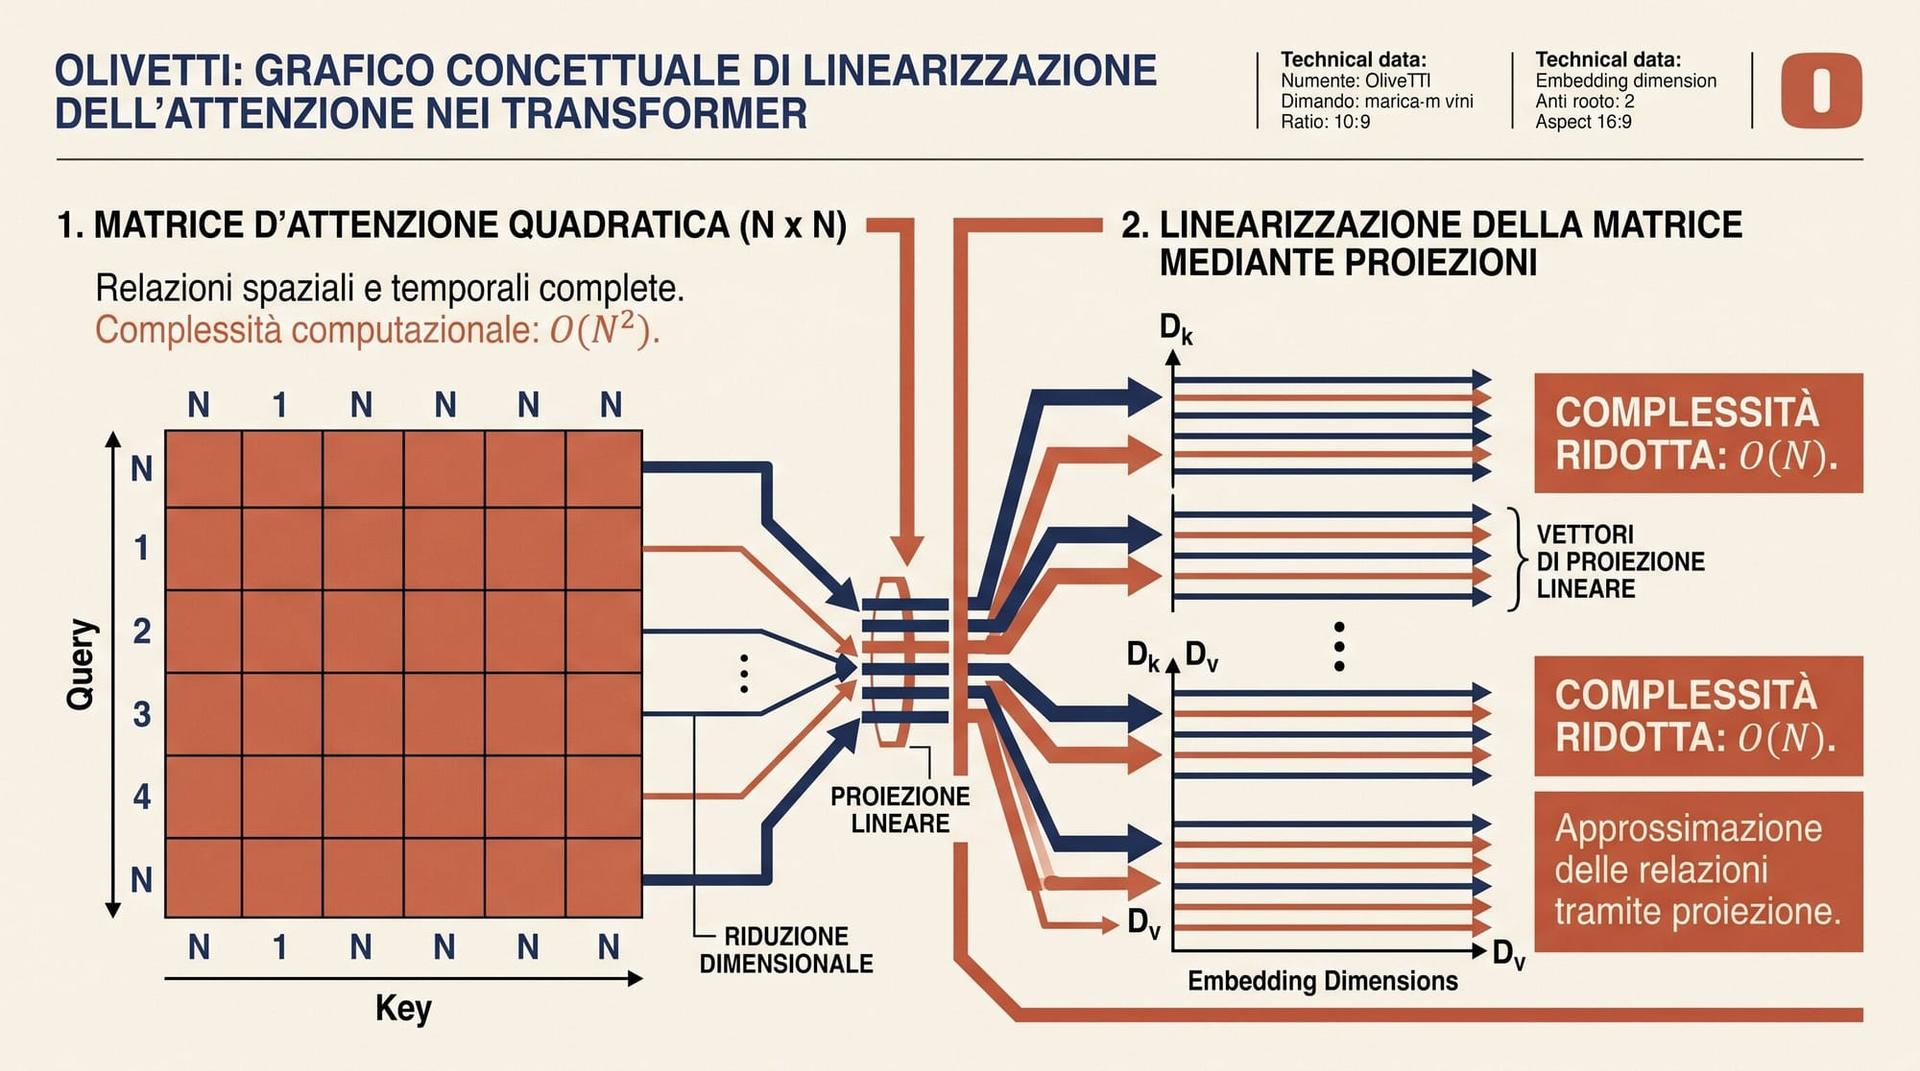
The QK and OV Circuits in Transformers: How Bilinear Attention Routing and Subspace Projections Move Information The standard mathematical presentation of multi-head self-attention, introduced in Vaswani et al. (2017), describes the layer as a sequence of matrix projections followed by scaled dot-product operations, concatenation, and an output projection. While computationally efficient for parallel GPU hardware, this formulation obscures the fundamental linear mechanics governing how transfor