Research / page 9

Research

470 articles

Articles, page 9

161-180 of 470
  1. Wasserstein GANs: How Earth Mover's Distance, Kantorovich-Rubinstein Duality, and Gradient Penalties Fixed Generative Adversarial Training

    Wasserstein GANs: How Earth Mover's Distance, Kantorovich-Rubinstein Duality, and Gradient Penalties Fixed Generative Adversarial Training Generative Adversarial Networks (Goodfellow et al., 2014) established an influential paradigm for generative modeling: formulating data synthesis as a minimax game between a generator mapping latent noise to data space and a discriminator distinguishing synthetic samples from real empirical data. Despite early empirical success, the original GAN formulation
    AI
    11 min read
  2. Latent Reasoning in Large Language Models: How Continuous Thoughts and Recurrent Hidden States Bypass Discrete Tokenization

    Standard autoregressive language models solve multi-step reasoning tasks by generating explicit verbal scratchpads. Under the Chain-of-Thought (CoT) paradigm formalized by Wei et al. (2022), a Transformer expands its effective computational depth by emitting intermediate natural language tokens into the prompt context. Each emitted token provides an additional forward pass through the network's layers, transforming reasoning into a sequence of left-to-right text predictions. While language-base

    AI
    8 min read
  3. Speech-to-Text Serving in Production: Comparing Faster-Whisper, Moonshine, SenseVoice, and NeMo Canary Architecture, Streaming Latency, and GPU Economics

    In conversational voice AI and real-time agentic workflows, the speech-to-text (STT) layer sets the hard lower bound on system responsiveness. Human conversational cadence expects turn-taking latencies between 200ms and 500ms. When an AI pipeline must accommodate downstream large language model (LLM) time-to-first-token generation (100ms to 250ms) and text-to-speech (TTS) audio synthesis (100ms to 200ms), the automatic speech recognition (ASR) stage cannot exceed 100ms to 150ms of processing ove

    AI
    8 min read
  4. Unlikelihood Training in Large Language Models: How Negative Candidate Loss and Sequence-Level Penalties Suppress Repetition Loops and Hallucinations

    Unlikelihood Training in Large Language Models: How Negative Candidate Loss and Sequence-Level Penalties Suppress Repetition Loops and Hallucinations Autoregressive language models generate text by iteratively predicting the probability distribution of the next token conditioned on preceding tokens. While standard maximum likelihood estimation (MLE) via cross-entropy loss serves as the universal training objective across modern foundation models, it possesses a fundamental structural asymmetry:

    AI
    13 min read
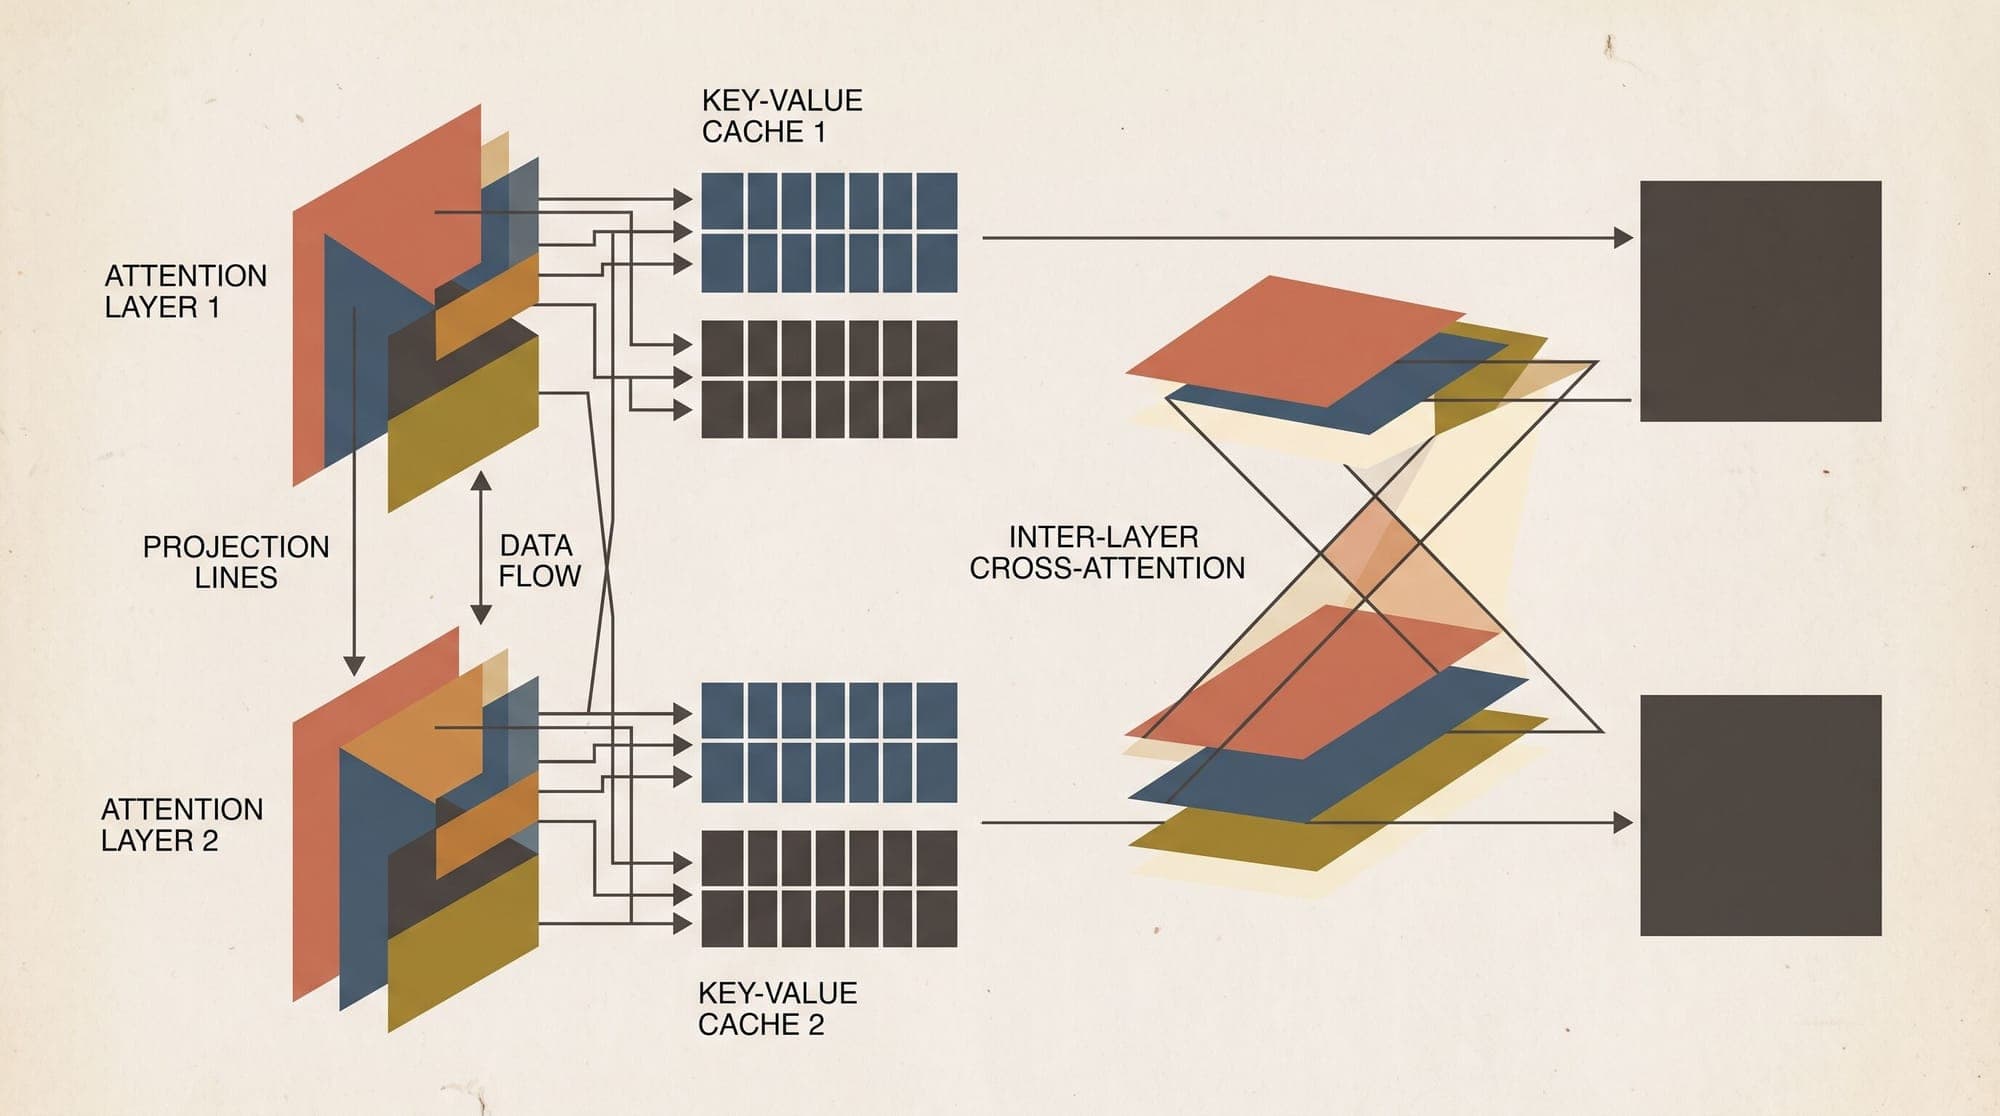
  5. Cross-Model KV Cache Transfer in Production: Architecture, Closed-Form Ridge Projections, and Cascaded Serving Economics

    Modern enterprise LLM serving architectures frequently rely on multi-model pipelines to balance inference cost, generation latency, and output quality. In model routing cascades, lightweight 8B models triage incoming queries and escalate complex reasoning tasks to 70B or MoE models. In speculative decoding pipelines, smaller draft models propose token sequences verified by larger target models. In long-horizon AI agent swarms, sub-agents frequently switch between specialized models across multi-

    LLM
    8 min read
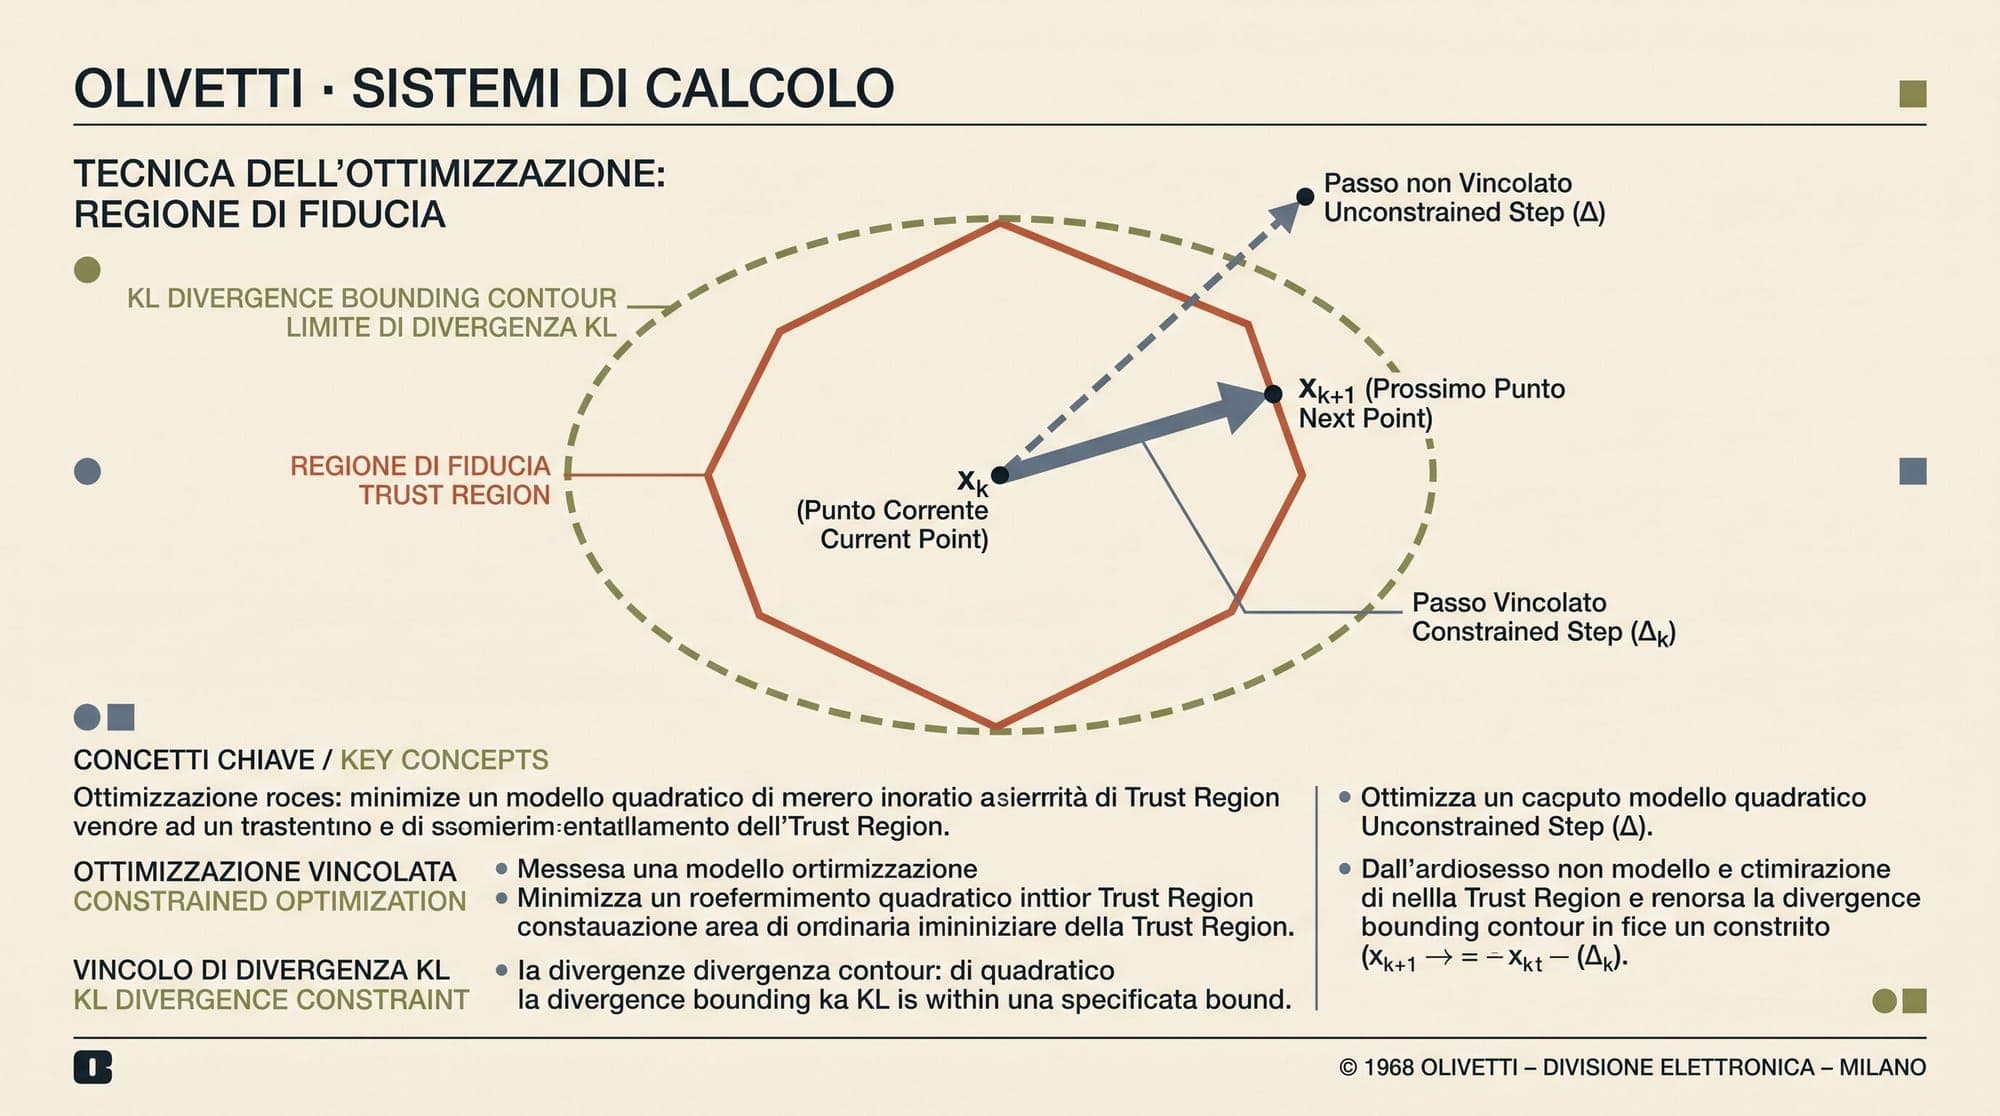
  6. Trust Region Policy Optimization: Mathematical Foundations, Monotonic Improvement Guarantees, and Conjugate Gradient Updates

    Trust Region Policy Optimization: Mathematical Foundations, Monotonic Improvement Guarantees, and Conjugate Gradient Updates In policy gradient reinforcement learning, optimization dynamics differ fundamentally from standard supervised learning. In supervised regression or classification, the underlying data distribution $P(x, y)$ remains stationary throughout training; a sub-optimal parameter update merely yields high loss on the current batch without corrupting future sample collection. In re

    AI
    9 min read
  7. Vector Quantization for LLM Weights in Production: Comparing QuIP#, AQLM, and VPTQ Architecture, Dequantization Kernels, and 2-Bit Serving Economics

    Vector Quantization for LLM Weights in Production: Comparing QuIP#, AQLM, and VPTQ Architecture, Dequantization Kernels, and 2-Bit Serving Economics Scalar post-training quantization methods such as GPTQ and AWQ have become the standard for compressing large language models to 4-bit integer formats (INT4). At 4 bits per parameter, scalar techniques preserve over 98% of baseline 16-bit floating-point (FP16/BF16) model accuracy across common benchmarks. However, pushing scalar quantization below

    AI
    9 min read
  8. OpenAI Integrates GPT-5.6 Family into AWS Kiro with Reported 82% Cost Drop

    OpenAI has made its flagship GPT-5.6 model family available within Kiro, the spec-driven software development environment developed by Amazon Web Services. The release brings OpenAI's frontier reasoning and coding tiers, including Sol, Terra, and Luna, directly into AWS's agentic engineering platform. According to joint evaluations conducted by AWS and OpenAI on Terminal-Bench 2.1, executing complex software engineering tasks with GPT-5.6 Terra inside Kiro reduced total token expenditures by ro

    OpenAI
    3 min read
  9. NVIDIA Enters Full Production on Groq 3 LPX, Hitting 3,400 Tokens per Second in Benchmarks

    NVIDIA has moved its Groq 3 LPX dedicated inference accelerator into full commercial production. Announced at Hot Chips 2026, the rack-scale accelerator system is designed as a purpose-built extension for NVIDIA's Vera Rubin NVL72 data center platform, targeting the compounding decode latency bottlenecks created by multi-step autonomous AI agents. European neocloud provider Nebius Group N.V. has committed as the first cloud infrastructure customer to deploy the accelerators, integrating them in

    Hardware
    3 min read
  10. The Fisher Information Matrix and Natural Gradient Descent: How Information Geometry, Riemannian Manifolds, and Curvature Invariance Reshape Neural Optimization

    The Fisher Information Matrix and Natural Gradient Descent: How Information Geometry, Riemannian Manifolds, and Curvature Invariance Reshape Neural Optimization Standard gradient descent operates under an implicit, often unexamined assumption: that parameter space is Euclidean. When an optimizer updates network weights via $\theta_{t+1} = \theta_t - \eta \nabla_\theta \mathcal{L}(\theta)$, it calculates the direction of steepest descent within an arbitrary coordinate system. If the network is r

    AI
    10 min read
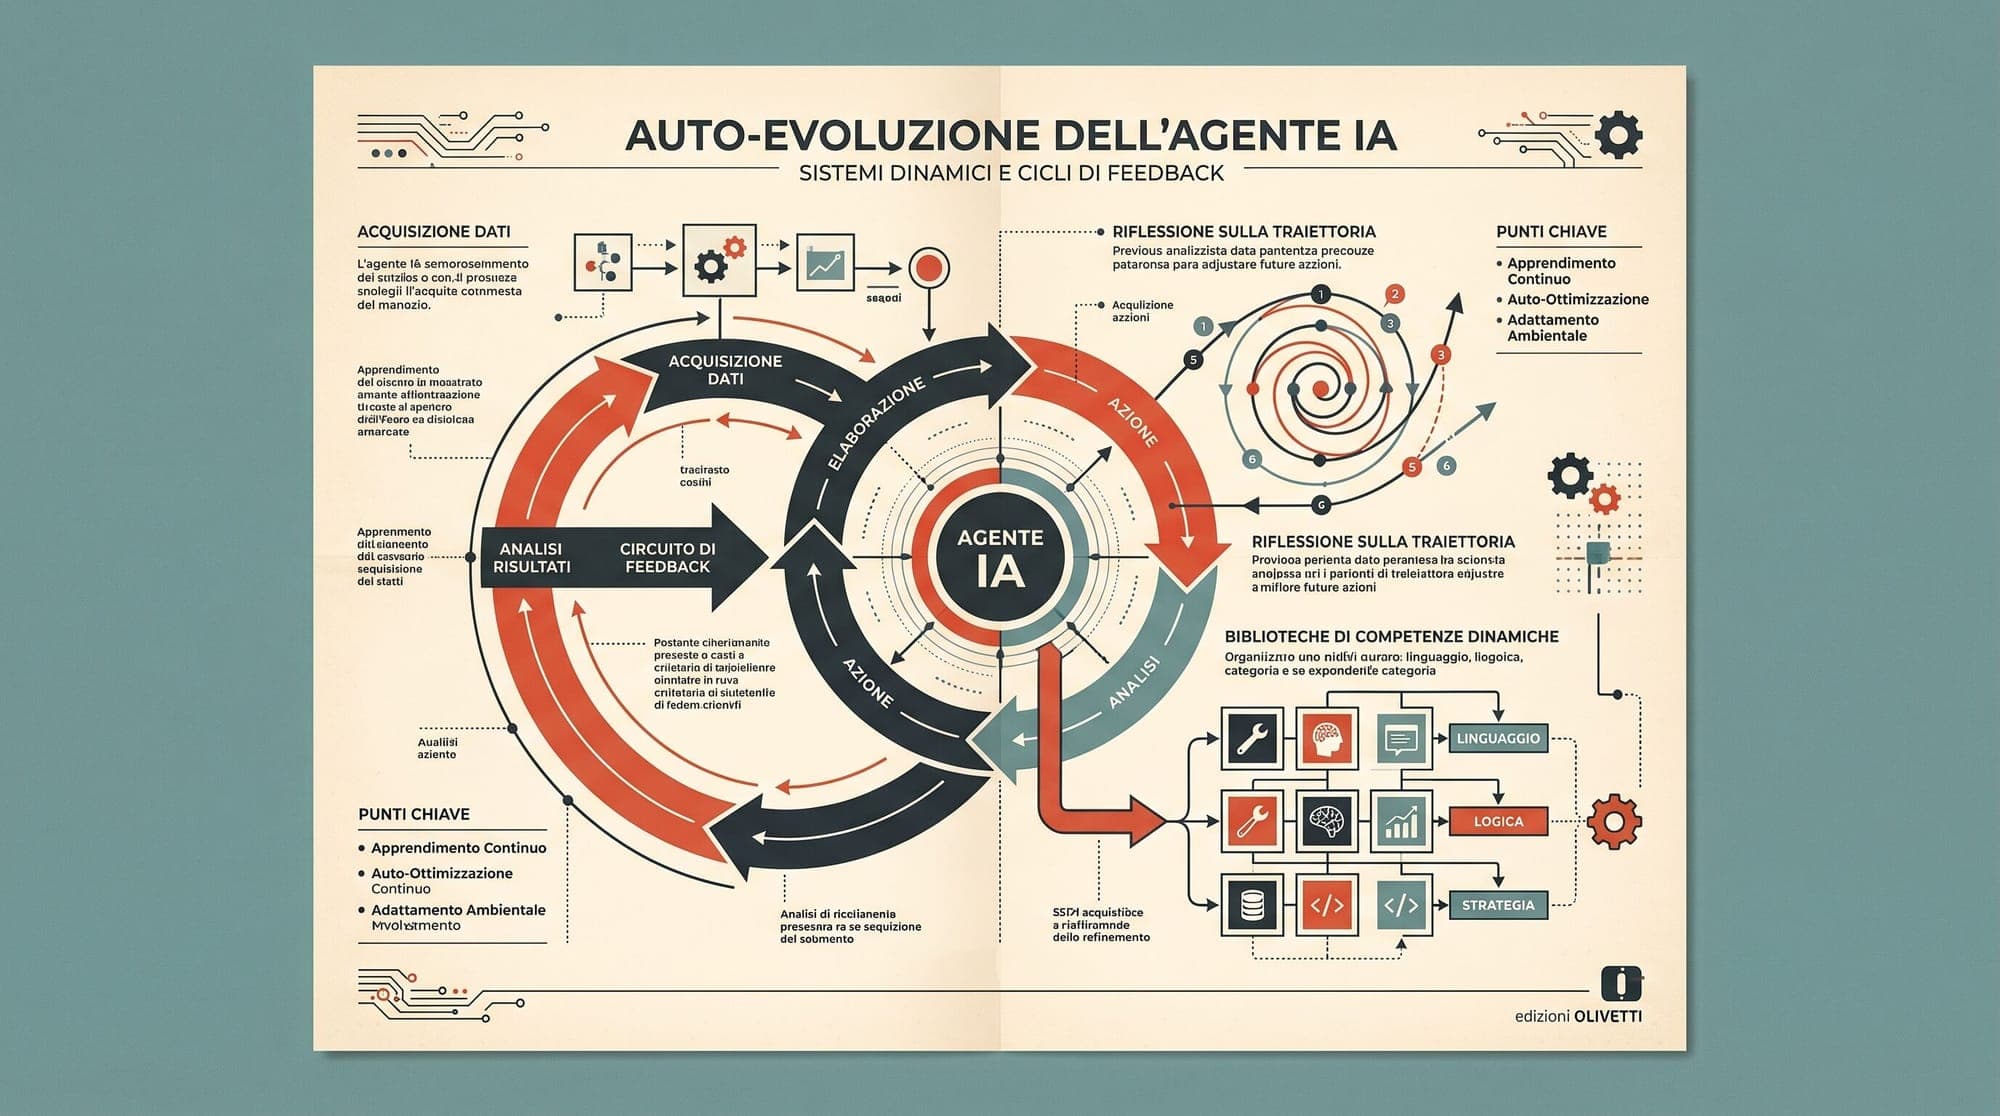
  11. Agent Self-Evolution and Experiential Learning in Production: Trajectory Reflection, Skill Library Curation, and Verifiable Policy Distillation

    Deploying autonomous AI agents into complex environments reveals a persistent operational bottleneck: frozen model weights. When an agent fails at a non-trivial workflow, traditional engineering setups rely on humans to diagnose the failure, rewrite prompt templates, adjust few-shot exemplars, or add custom heuristic wrappers. This manual iteration loop fails to scale across diverse, long-horizon production environments where agents encounter thousands of unique edge cases daily. To break this

    AI
    6 min read
  12. Temperature Scaling and Model Calibration in Deep Neural Networks: Mathematical Foundations, Expected Calibration Error, and Post-Hoc Logit Optimization

    Modern deep neural networks achieve high classification accuracy and generative benchmark performance across vision, language, and decision-making tasks. However, optimization for raw accuracy does not ensure that predicted softmax probabilities correspond to true posterior probabilities. A model that assigns a 0.90 probability to an output should be correct exactly 90% of the time. When empirical accuracy systematically diverges from predicted confidence, the model is miscalibrated. Research b

    Deep Learning
    11 min read
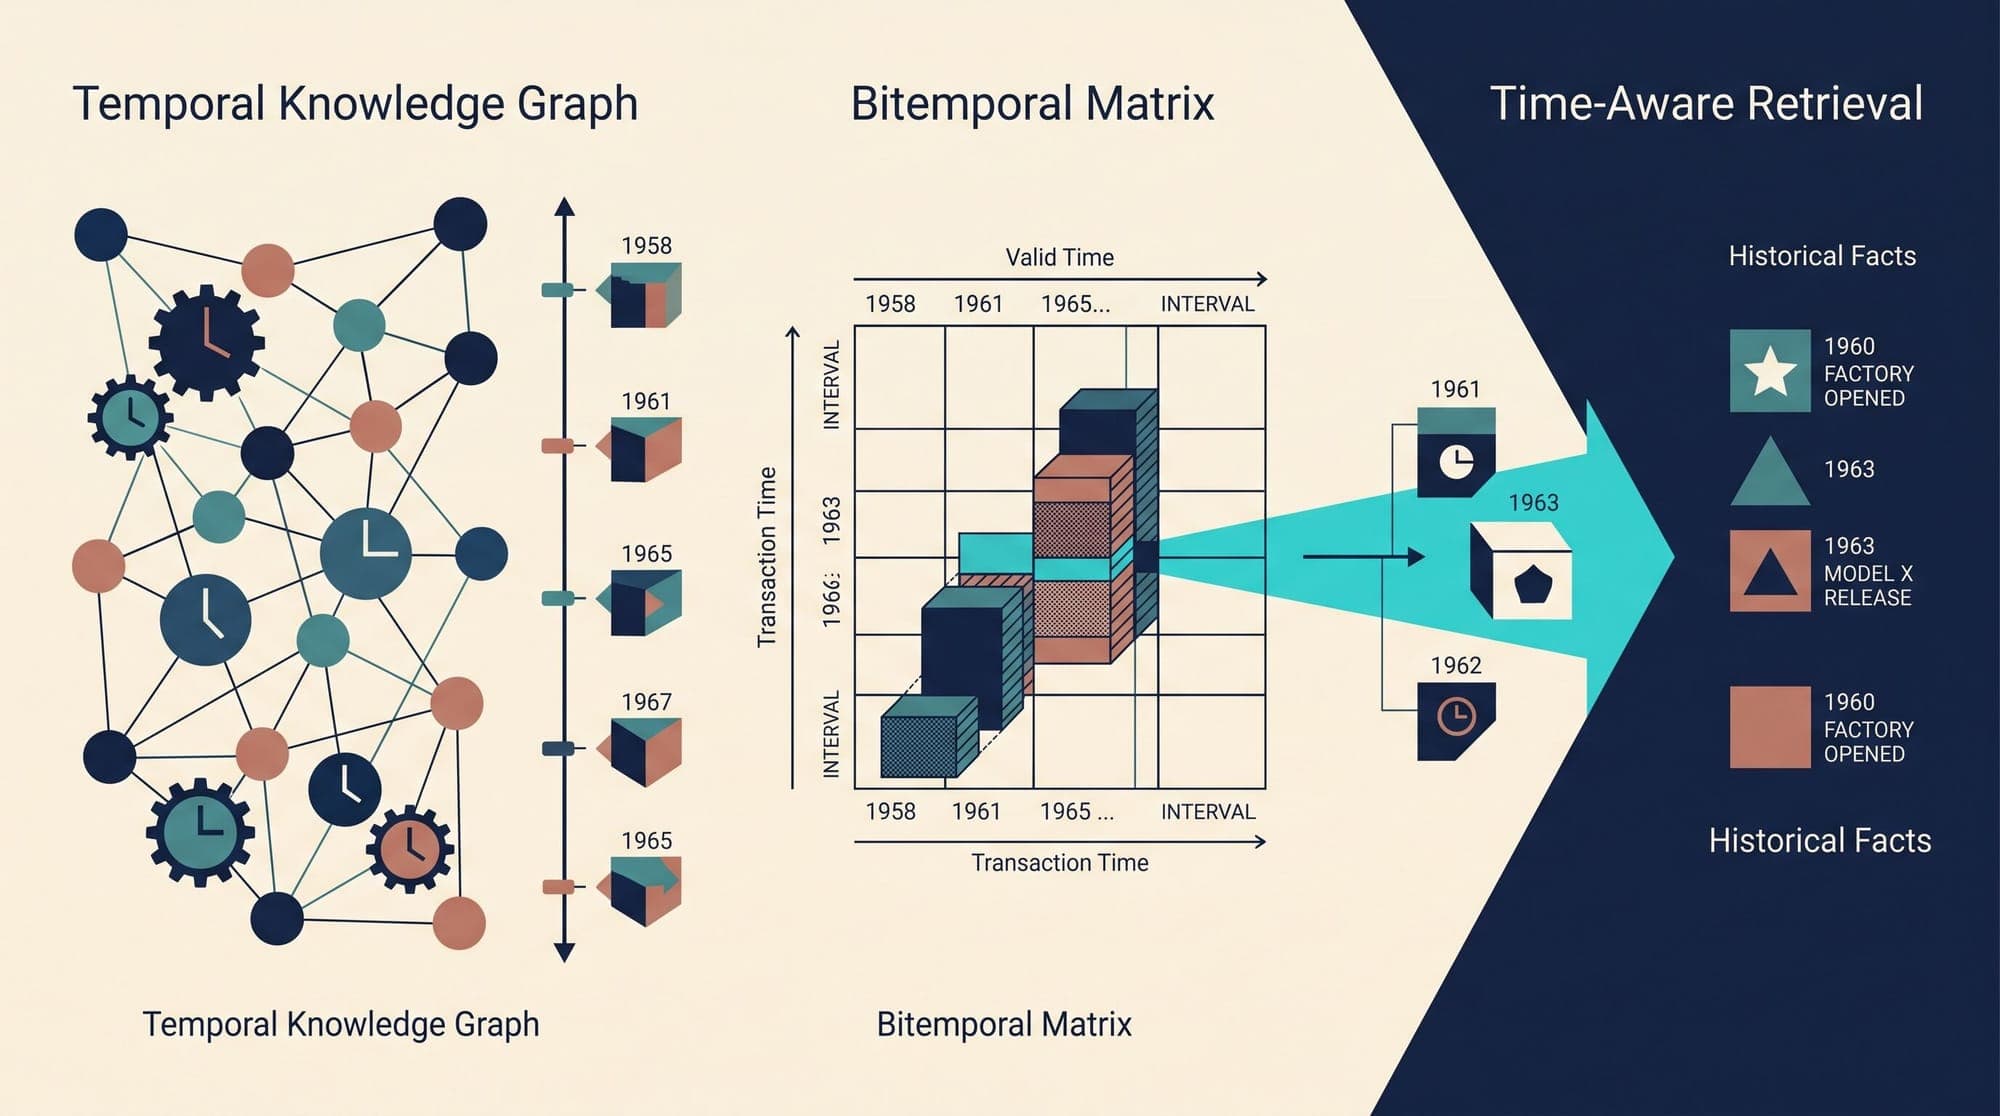
  13. Temporal Knowledge Graphs in Production RAG: Bitemporal Schemas, Dynamic Entity Resolution, and Point-in-Time Context Retrieval

    Temporal Knowledge Graphs in Production RAG: Bitemporal Schemas, Dynamic Entity Resolution, and Point-in-Time Context Retrieval Standard Retrieval-Augmented Generation (RAG) pipelines operate on a flat assumption: facts retrieved from a vector database or static knowledge graph are treated as timeless truths. When an enterprise corpus contains documents spanning multiple quarters or years, this timeless representation breaks down. Information changes: executives step down, compliance policies a

    Analysis
    6 min read
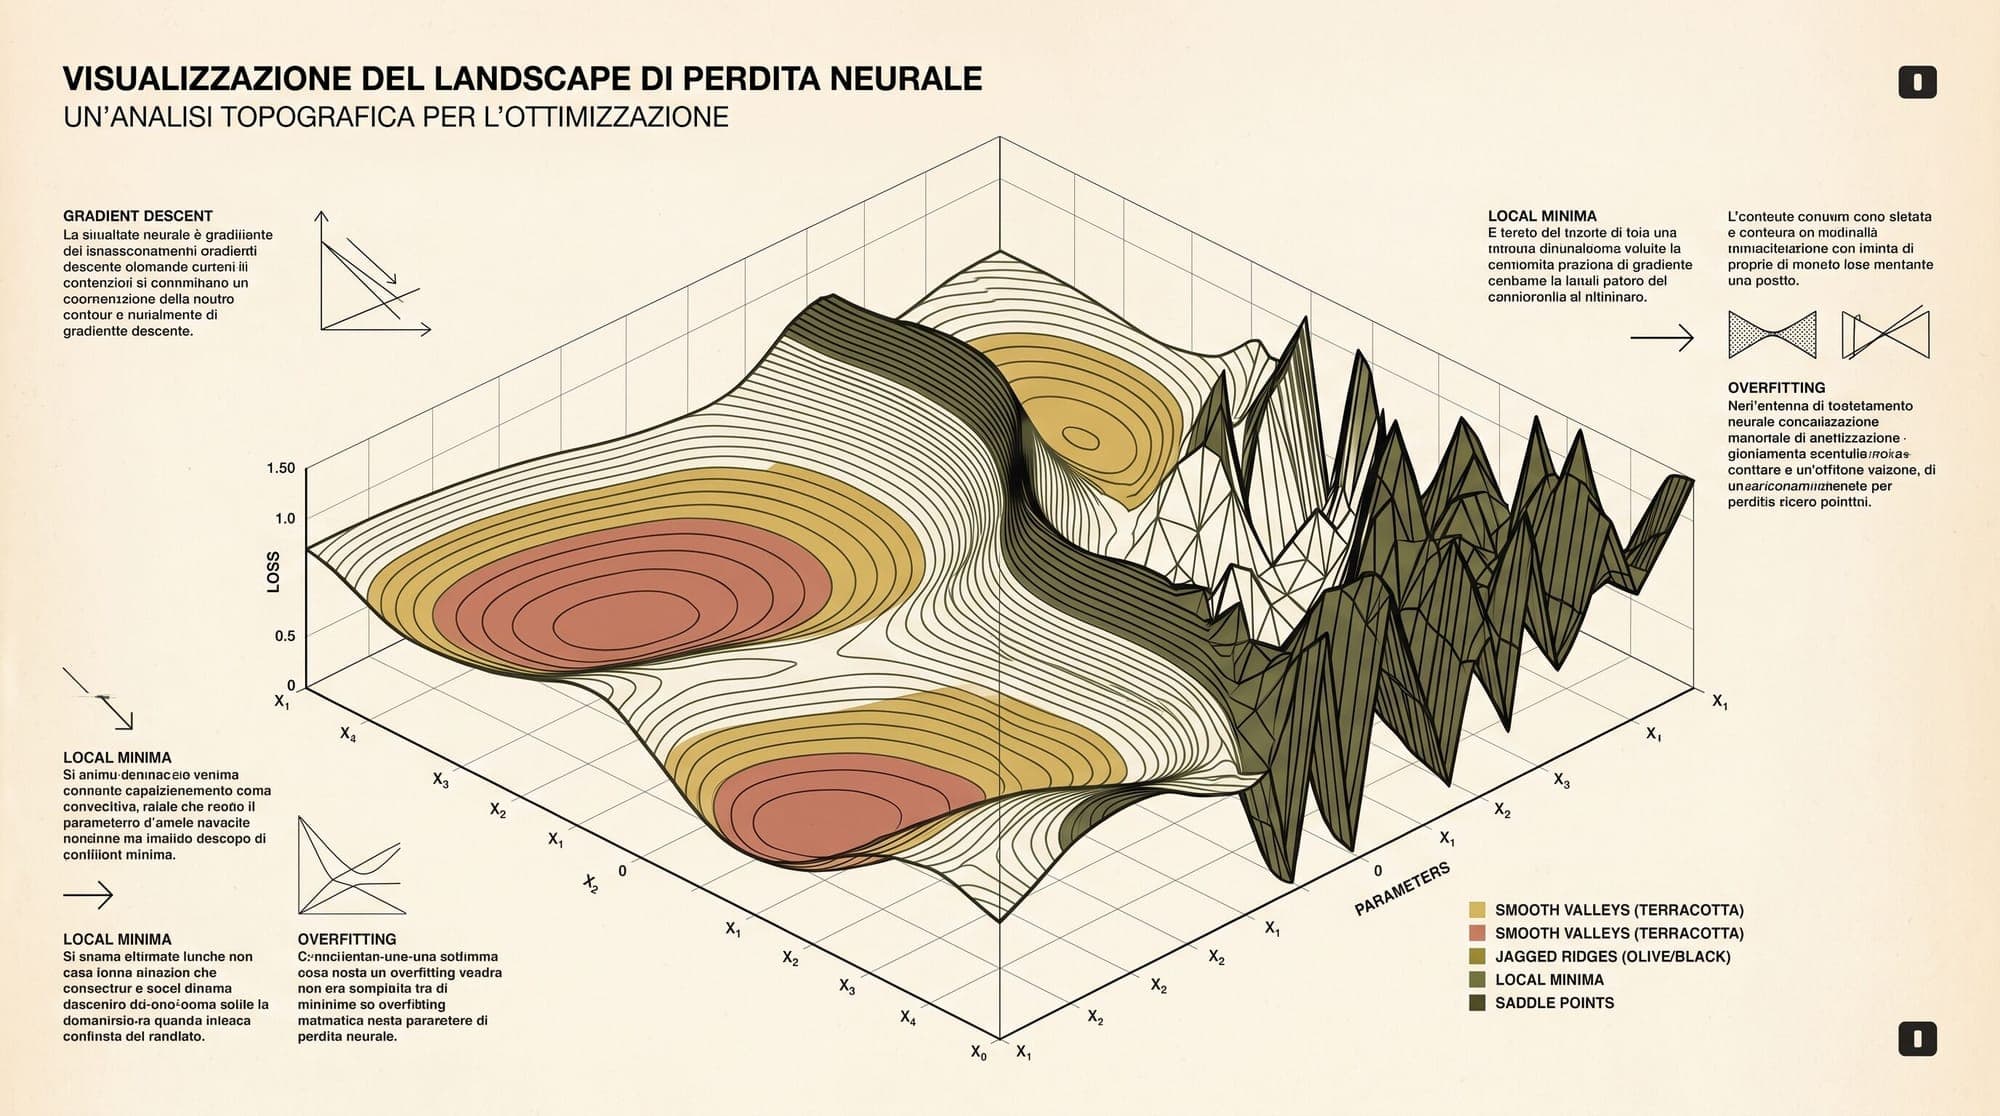
  14. Loss Landscapes in Deep Neural Networks: How Filter Normalization, Hessian Curvature, and Basin Flatness Explain Generalization

    The parameter space of modern deep learning models spans millions to hundreds of billions of dimensions. In this high-dimensional space, the empirical risk objective forms a complex geometric surface known as the loss landscape. Despite the extreme non-convexity of deep neural networks, standard first-order optimization algorithms such as stochastic gradient descent (SGD) and Adam regularly converge to parameter configurations that achieve both low training error and robust test set generalizati

    AI
    9 min read
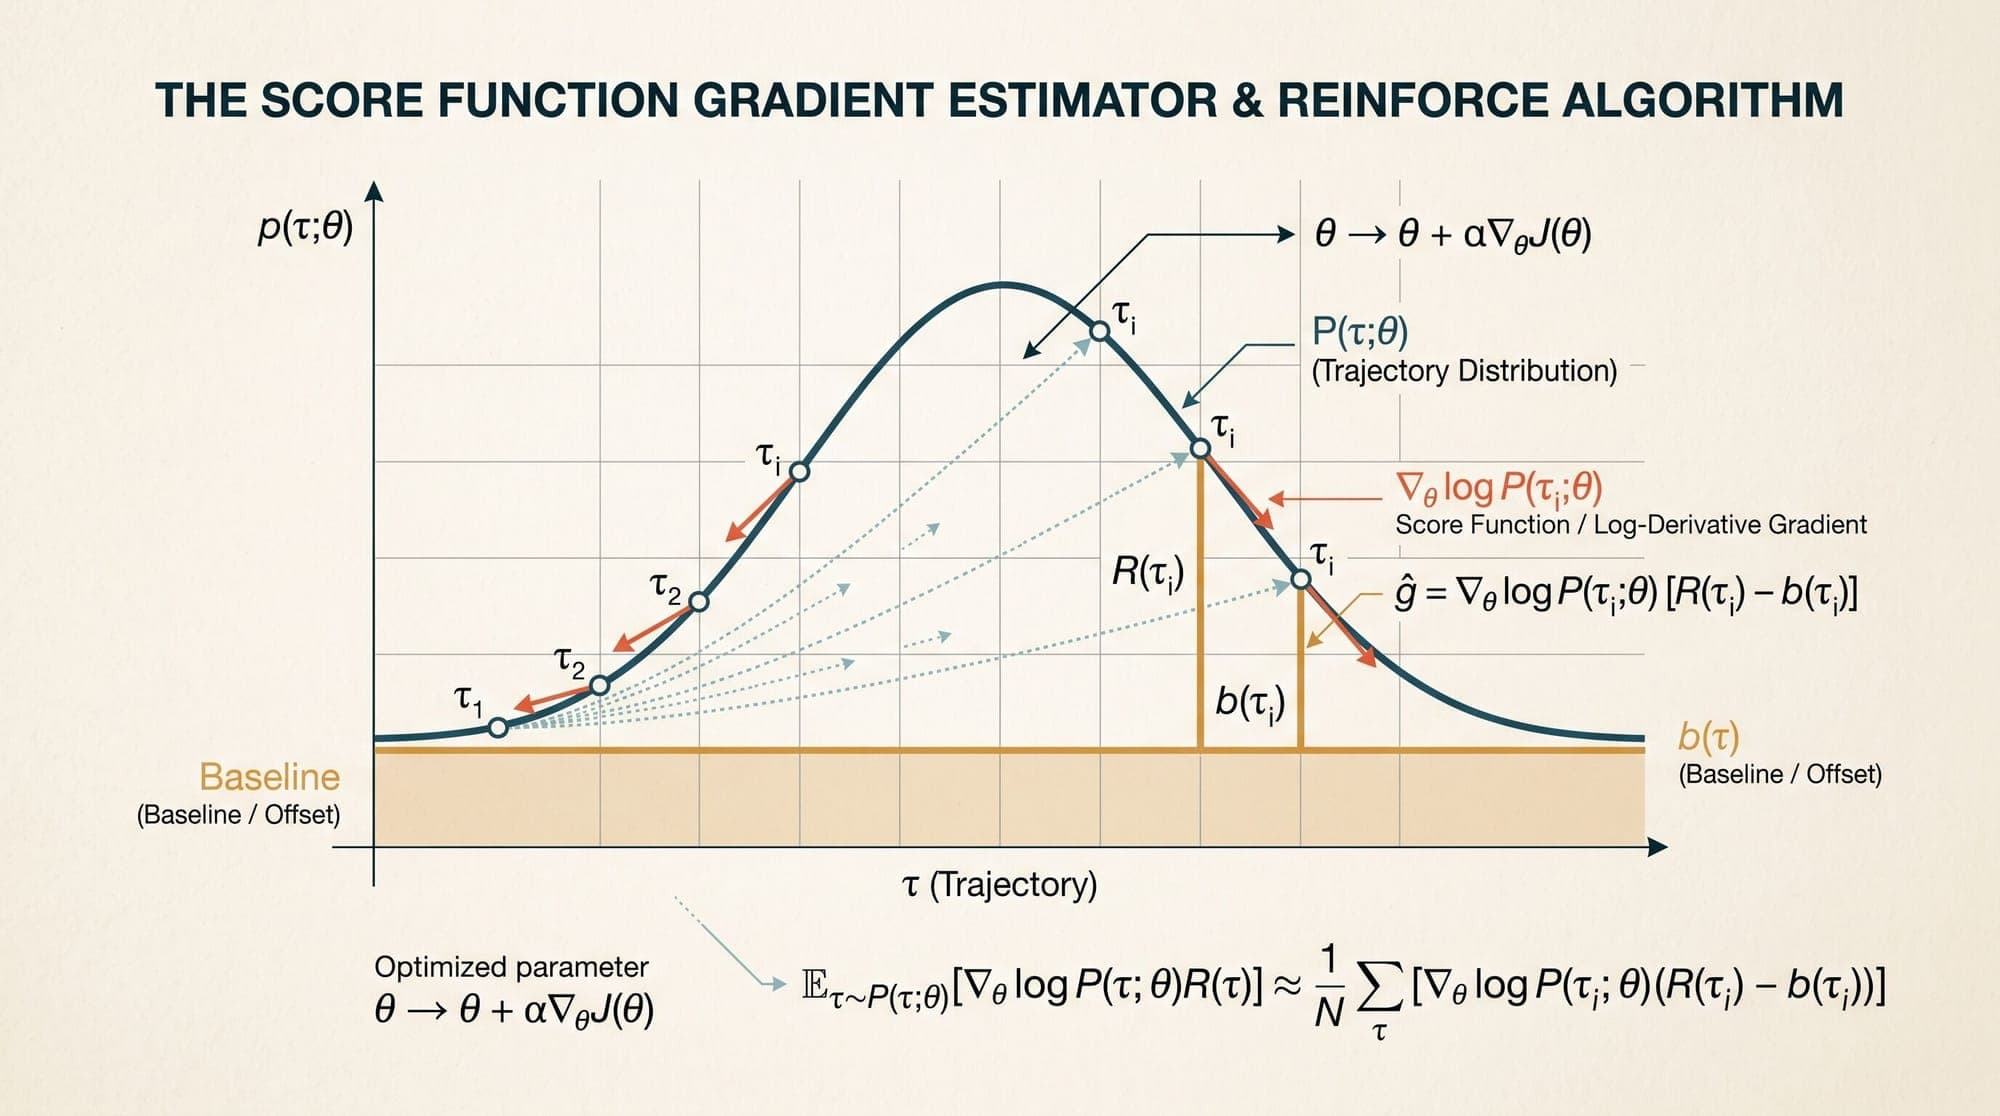
  15. The Score Function Estimator: Mathematical Foundations of REINFORCE, Log-Derivative Tricks, and Baseline Variance Reduction

    In modern artificial intelligence, standard backpropagation relies on continuous differentiability: every operation between model parameters and the final loss must provide well-behaved analytical Jacobian matrices. However, many of the most critical optimization challenges in machine learning break this continuity. Autoregressive token generation in large language models, discrete tool invocation, programmatic compiler execution, and black-box reward environments are fundamentally non-different

    Reinforcement Learning
    10 min read
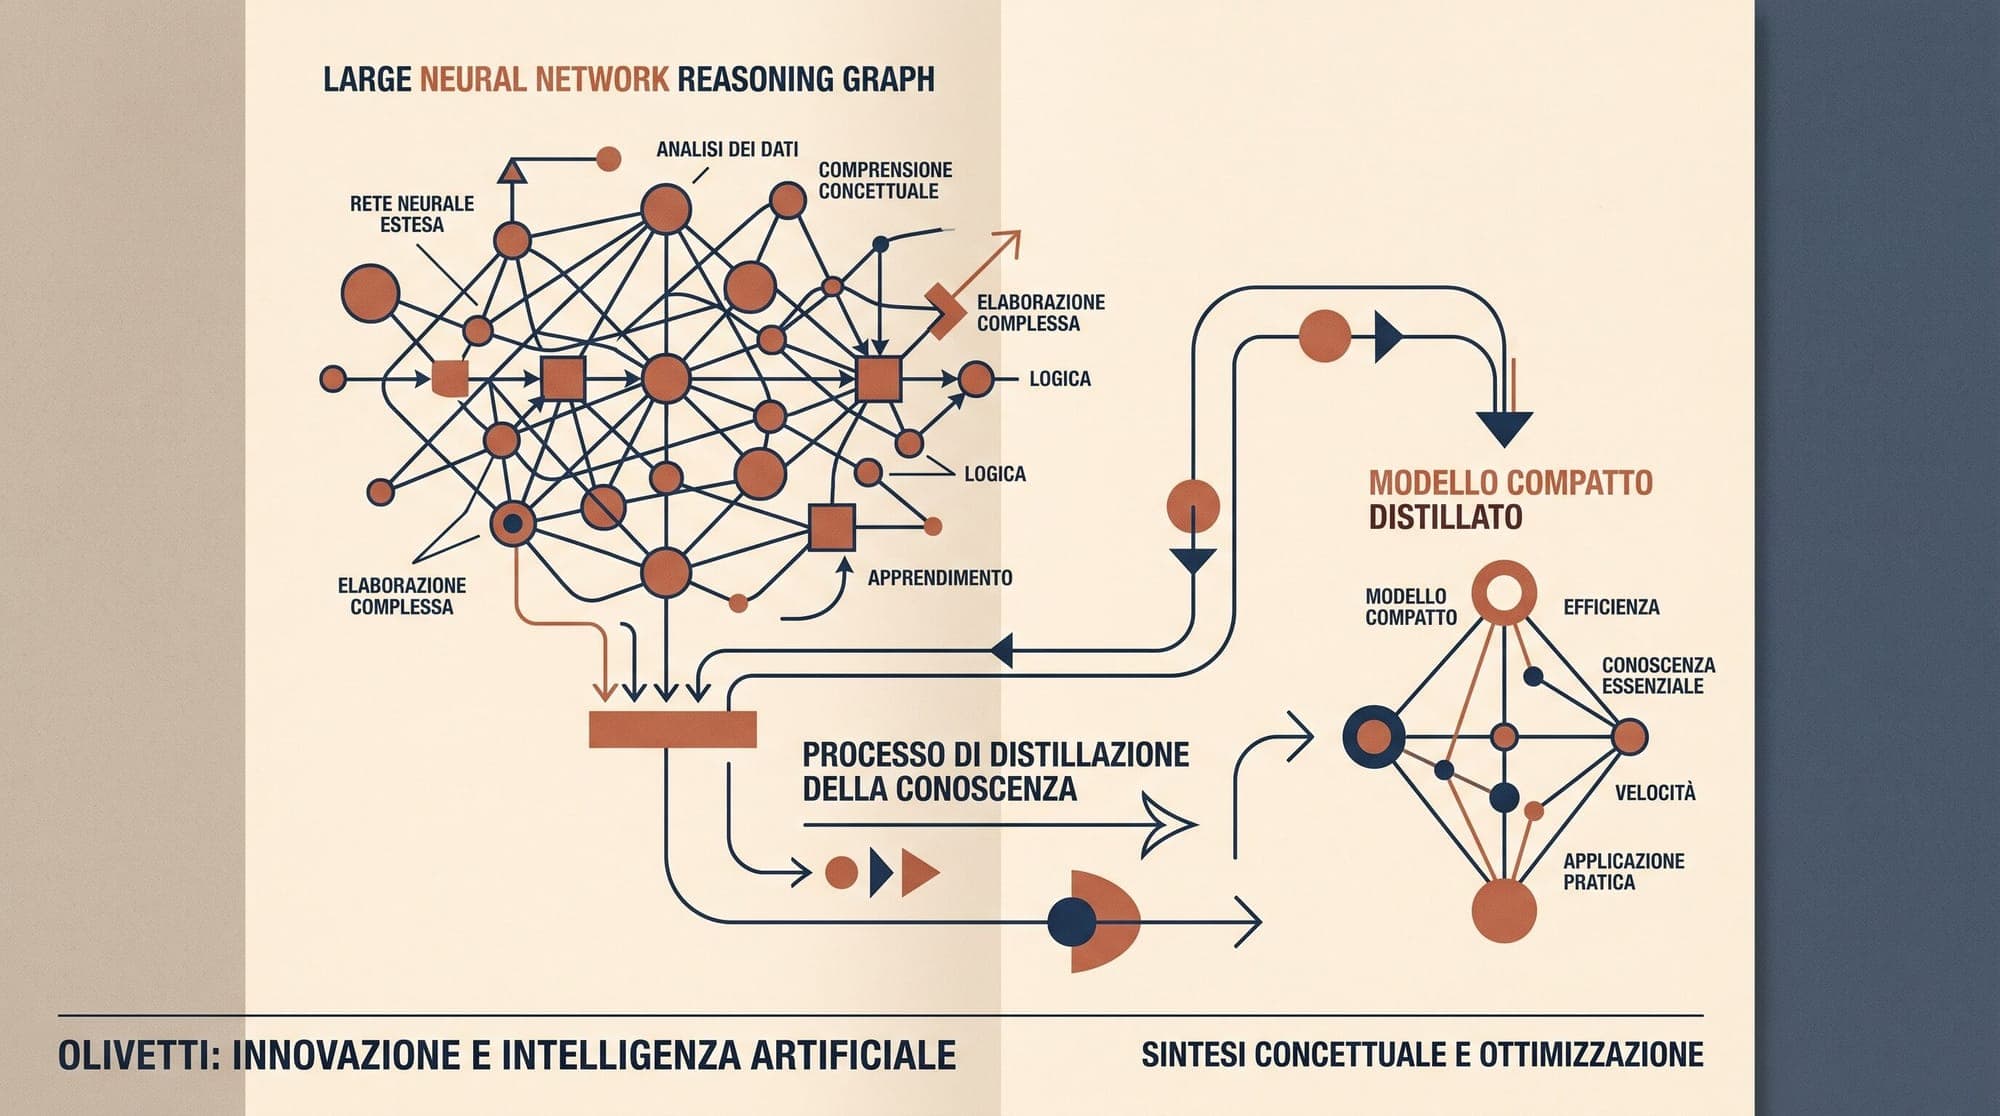
  16. Reasoning Model Distillation in Production: Trajectory Curation, Thinking-Token Formatting, Over-Thinking Mitigation, and Student RL Alignment

    Reasoning Model Distillation in Production: Trajectory Curation, Thinking-Token Formatting, Over-Thinking Mitigation, and Student RL Alignment Distilling frontier reasoning models into compact language models has emerged as one of the most effective strategies for deploying low-latency, cost-efficient inference pipelines. Rather than training small models purely on input-output answer pairs, reasoning distillation transfers the intermediate exploration, backtracking, and verification trajectori

    LLM
    5 min read
  17. Alignment and Uniformity on the Hypersphere: How Geometric Losses Govern Contrastive Representation Learning

    Alignment and Uniformity on the Hypersphere: The Geometric Foundations of Contrastive Representation Learning Contrastive representation learning serves as the foundational objective behind modern neural embeddings, powering dense retrieval systems, visual-language models such as CLIP, and metric learning pipelines. While early literature justified contrastive learning through the InfoMax principle (maximizing mutual information between augmented views), theoretical and empirical analyses have

    Machine Learning
    11 min read
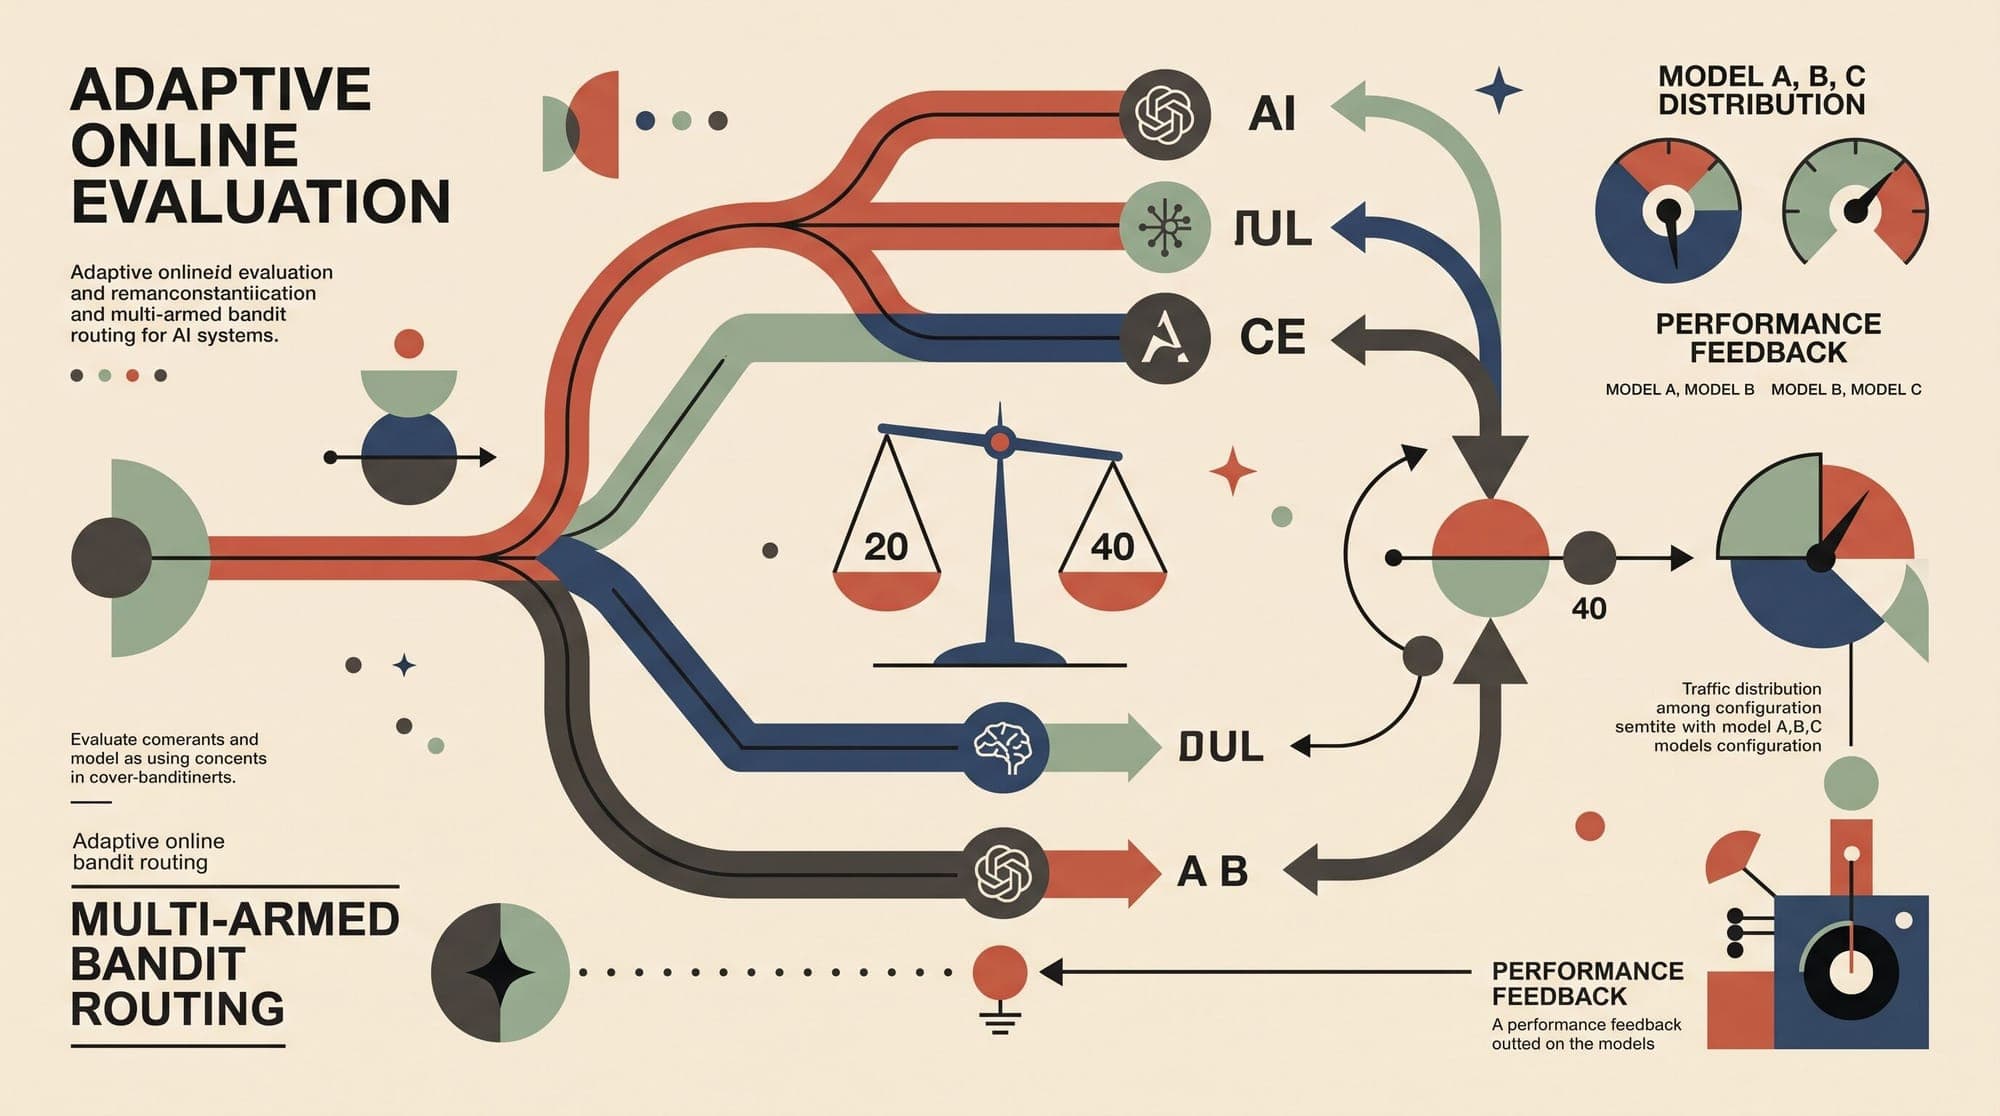
  18. Online Evaluation and Multi-Armed Bandit Routing in Production LLM Systems: Interleaving, Counterfactual Estimation, and Adaptive Traffic Allocation

    Online Evaluation and Multi-Armed Bandit Routing in Production LLM Systems: Interleaving, Counterfactual Estimation, and Adaptive Traffic Allocation Static offline benchmarks such as MMLU, HumanEval, and synthetic LLM-as-a-judge evaluation pipelines have become standard fixtures in modern AI development. However, production engineering teams frequently observe that offline benchmark improvements fail to translate into tangible user satisfaction or business outcomes. Static evaluation suites suf

    AI
    12 min read
  19. Teacher Forcing and Exposure Bias in Autoregressive Models: Mathematical Foundations, Compounding Errors, and Mitigation Strategies

    Teacher Forcing and Exposure Bias in Autoregressive Models: Mathematical Foundations, Compounding Errors, and Mitigation Strategies Autoregressive sequence models form the computational backbone of modern language modeling, code synthesis, and multi-step reasoning agents. From decoder-only Transformers like GPT and Claude to recurrent architectures, these systems factorize the joint probability of a sequence of tokens $y = (y_1, y_2, \dots, y_T)$ into a product of conditional probabilities: $$

    AI
    10 min read
  20. Study Exposes Citation Monoculture Across Frontier LLMs as Recursive Drafting Compounds Bias

    Study Exposes Citation Monoculture Across Frontier LLMs as Recursive Drafting Compounds Bias As large language models take over literature reviews and automated research workflows, a collaborative study from UT Austin, Stevens Institute of Technology, Washington University in St. Louis, Rice University, and the University of Notre Dame demonstrates that frontier models suffer from severe citation monoculture. Even when all identifying metadata is removed, LLMs across vendors converge on a narro

    research
    2 min read