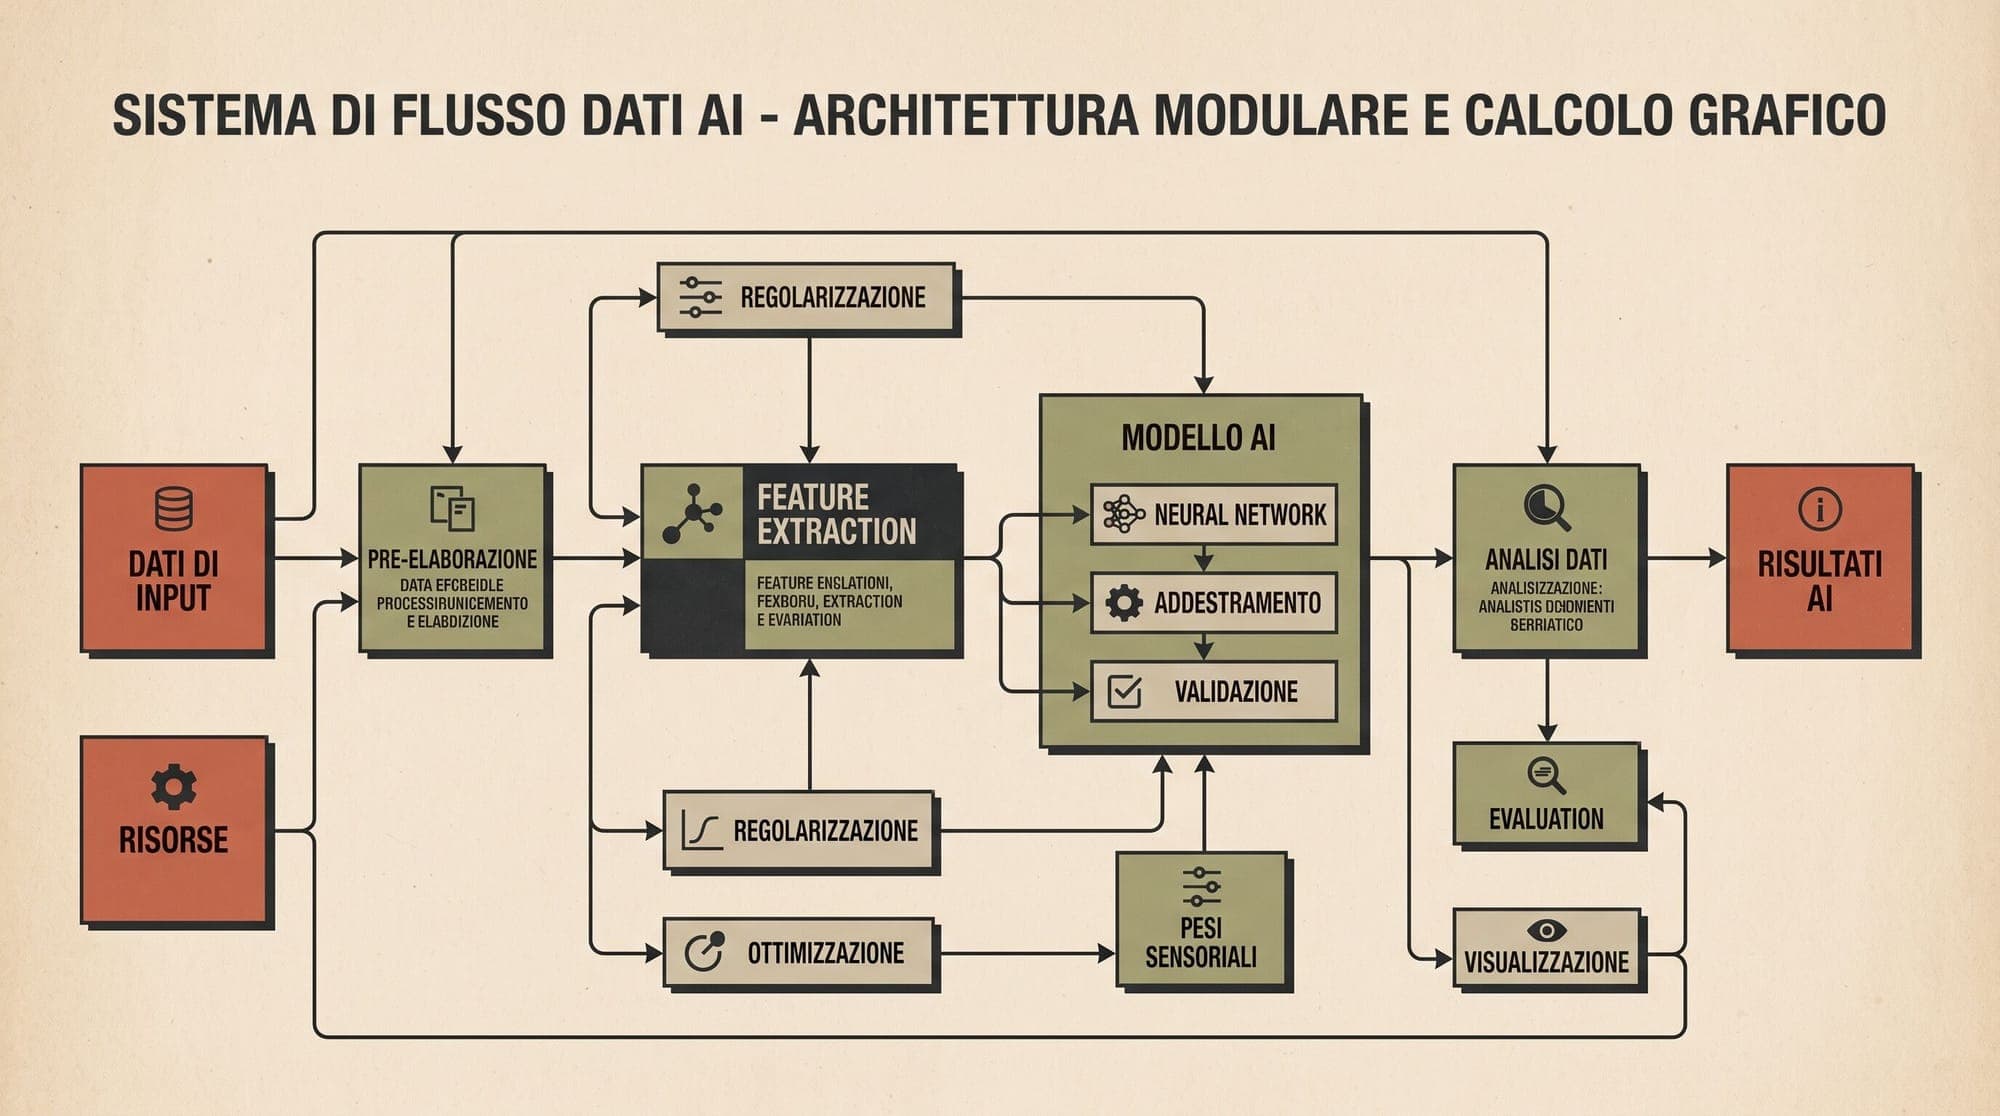
BitNet b1.58: Mathematical Foundations of 1.58-Bit Ternary Quantization, Absmean Scaling, and Multiplication-Free LLM Architectures
Standard Large Language Models (LLMs) rely on 16-bit floating-point (FP16 or BF16) matrix multiplications for both pre-training and autoregressive inference. While post-training quantization techniques (such as GPTQ, AWQ, and dynamic FP8/INT4 scaling) compress weights after training, they often introduce perplexity degradation at ultra-low bitwidths ($<4$ bits) or still require floating-point dequantization at runtime. Quantization-aware pre-training architectures directly tackle this computati