
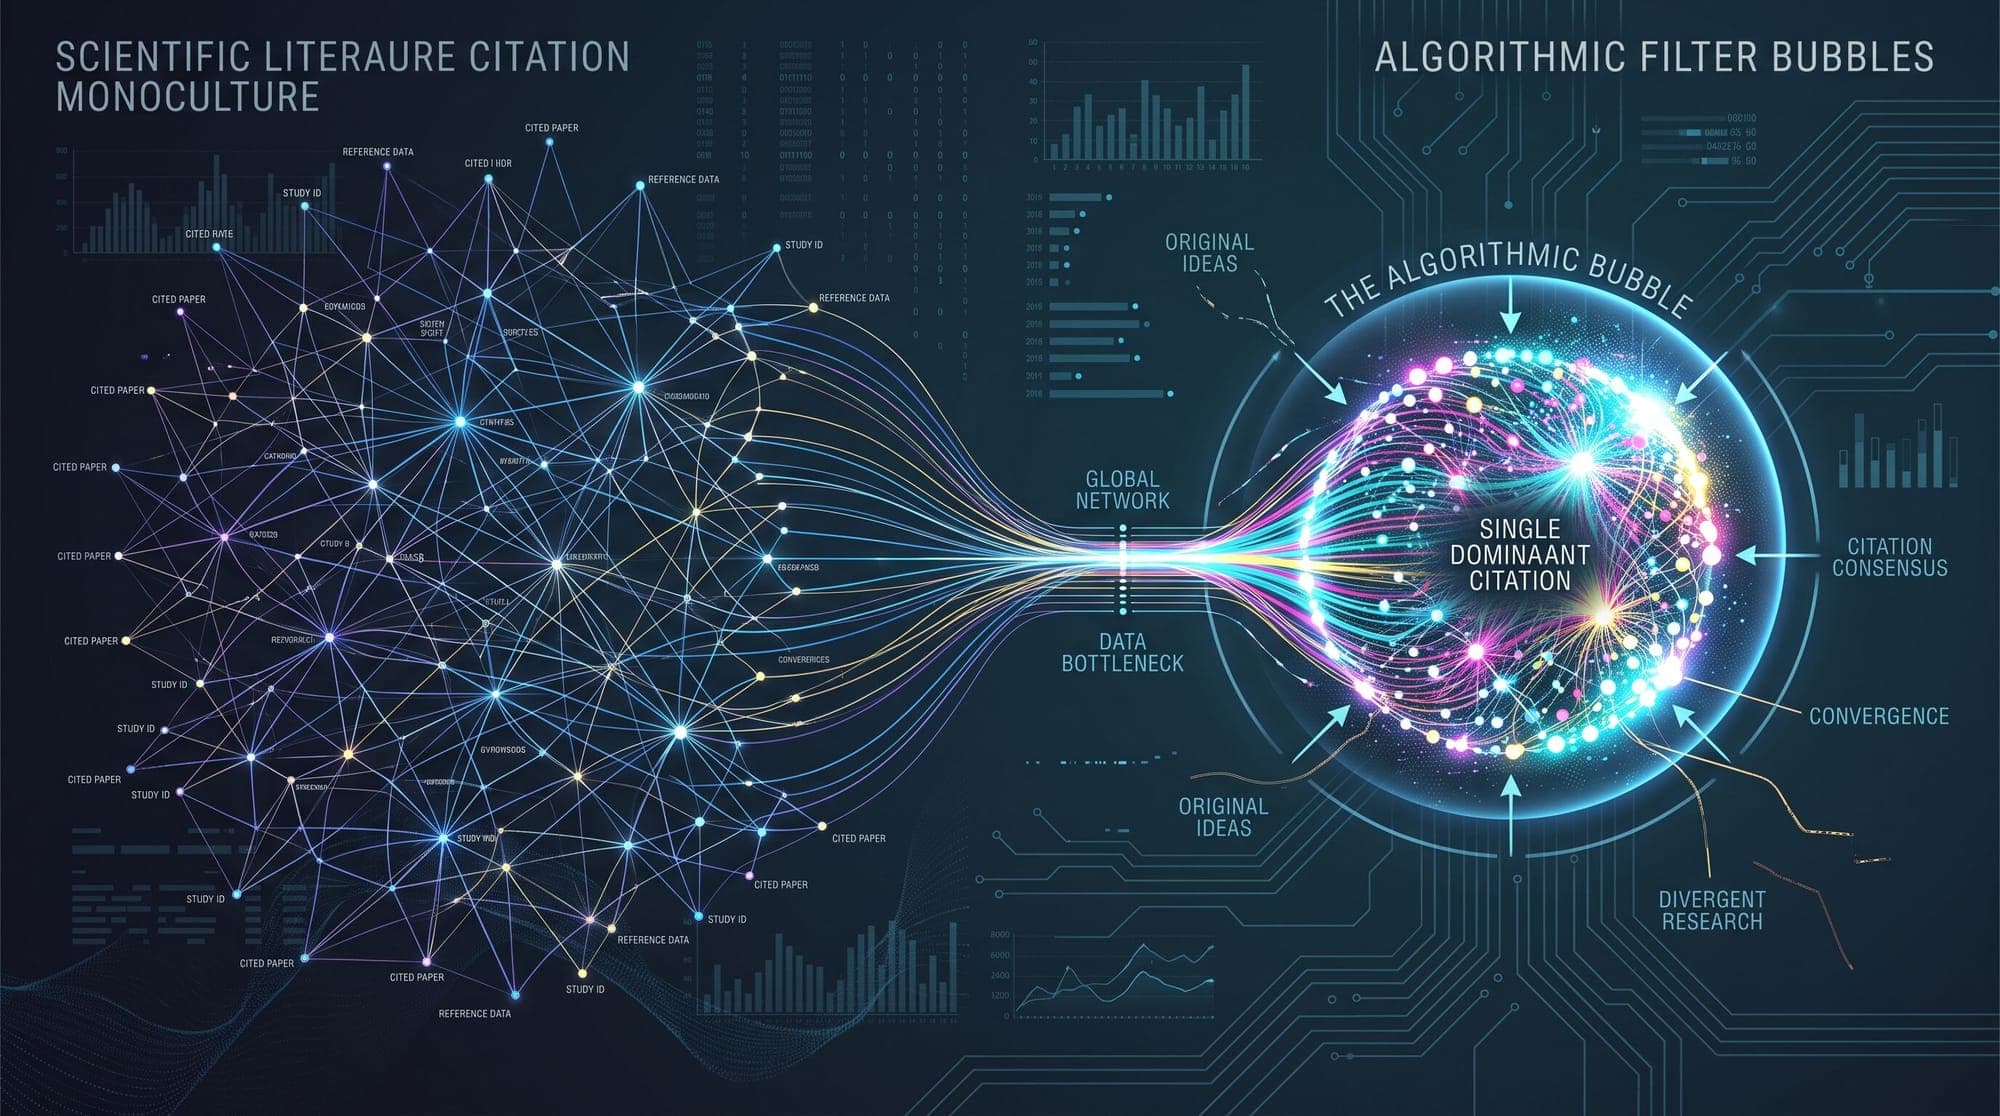
Study Exposes Citation Monoculture Across Frontier LLMs as Recursive Drafting Compounds Bias
As large language models take over literature reviews and automated research workflows, a collaborative study from UT Austin, Stevens Institute of Technology, Washington University in St. Louis, Rice University, and the University of Notre Dame demonstrates that frontier models suffer from severe citation monoculture. Even when all identifying metadata is removed, LLMs across vendors converge on a narrow subset of papers, creating an artificial Matthew effect that narrows scientific diversity.
The paper, titled When AI Writes, Who Gets Cited? Evidence of Citation Monoculture Across Language Models, evaluates eleven frontier models from OpenAI, Anthropic, and Google across controlled citation selection and review generation tasks.

Controlled Blinded Benchmarking
Prior concerns around LLM citations primarily focused on hallucinations and fabricated references. To isolate citation selection behavior from fabrication, the researchers established a controlled corpus of 120 knowledge-distillation papers published on arXiv between 2015 and 2022, each possessing moderate baseline citations (50 to 500).
The experimental framework blinded the papers to eliminate surface-level popularity heuristics:
- Author names and institutional affiliations were anonymized.
- Publication venues and original citation metrics were stripped.
- Publication years were randomly reassigned across the sample.
Models were provided random subsets of 30 blinded papers and tasked with selecting up to 10 references to support a literature review. For comparison, eight domain experts were given identical blinded candidate sets.
Divergence Between Models and Human Reviewers
While human experts distributed citations broadly across the candidate corpus based on qualitative relevance, all eleven evaluated LLMs concentrated their citations on a tightly clustered subset of papers:
- Cross-Vendor Preference Alignment: Models from different providers shared structural preferences, repeatedly favoring the same specific papers while ignoring equally relevant alternatives in the blinded pool.
- Task Invariance: The concentration persisted regardless of whether the model generated full analytical prose or merely output structured reference lists, confirming the bias originates in retrieval and ranking preferences rather than generation mechanics.
- Herfindahl-Hirschman Index Concentration: Using the Herfindahl-Hirschman Index (HHI) to measure market concentration in citation shares, the authors proved that cross-model preference correlation () creates systemic concentration that cannot be resolved simply by ensembling models from different providers.
Recursive Compounding in Multi-Turn Generation
To measure long-term effects as AI-generated text enters scientific corpora, the researchers ran an 11-round iterative simulation. In each round, 120 AI-generated papers were introduced into the pool.
As the proportion of synthetic scientific text increased, citation concentration compounded exponentially. The models progressively narrowed their citations to a shrinking fraction of the original foundational papers, effectively filtering out non-modal research.
The authors conclude that naive multi-model routing or equal-exposure prompting fails to counteract citation monoculture, pointing toward deliberate algorithmic diversity penalties and explicit coverage balancing as necessary interventions in automated research agents.



