Research / page 10

Research

470 articles

Articles, page 10

181-200 of 470
  1. Integrated Gradients: How Axiomatic Attribution Solves the Gradients-at-Saturation Problem in Deep Neural Networks

    Integrated Gradients: How Axiomatic Attribution Solves the Gradients-at-Saturation Problem in Deep Neural Networks Feature attribution methods in deep learning aim to answer a fundamental interpretability question: given an input vector and a trained neural network, how much did each input dimension contribute to the model's final output score? In natural language processing and computer vision, practitioners routinely need to identify which input tokens, pixels, or tabular variables drove a sp
    AI
    10 min read
  2. Semantic Memory Consolidation in Production AI Agents: Architecture, Episodic Decay Curves, and Procedural Knowledge Distillation

    Long-running autonomous AI agents accumulate hundreds of interaction turns, tool executions, and environment observations across extended deployments. Naive implementations store these raw episodic traces directly in vector databases, retrieving past interactions via dense semantic similarity. In production, this append-only strategy degrades quickly: retrieval queries surface outdated facts, contradictory state assertions pollute prompt context, and the agent fails to extract generalizable prob

    AI
    7 min read
  3. Stochastic Weight Averaging: How Geometric Ensembling Finds Flatter Optima and Improves Generalization

    Stochastic Weight Averaging (SWA): How Geometric Ensembling Finds Flatter Optima and Improves Generalization During the optimization of deep neural networks, standard Stochastic Gradient Descent (SGD) and adaptive optimizers often struggle to find solutions that generalize robustly to unseen data. While learning rate decay allows optimizers to settle into local minima on the empirical training loss surface, empirical and theoretical analyses reveal that standard gradient descent tends to halt n

    AI
    8 min read
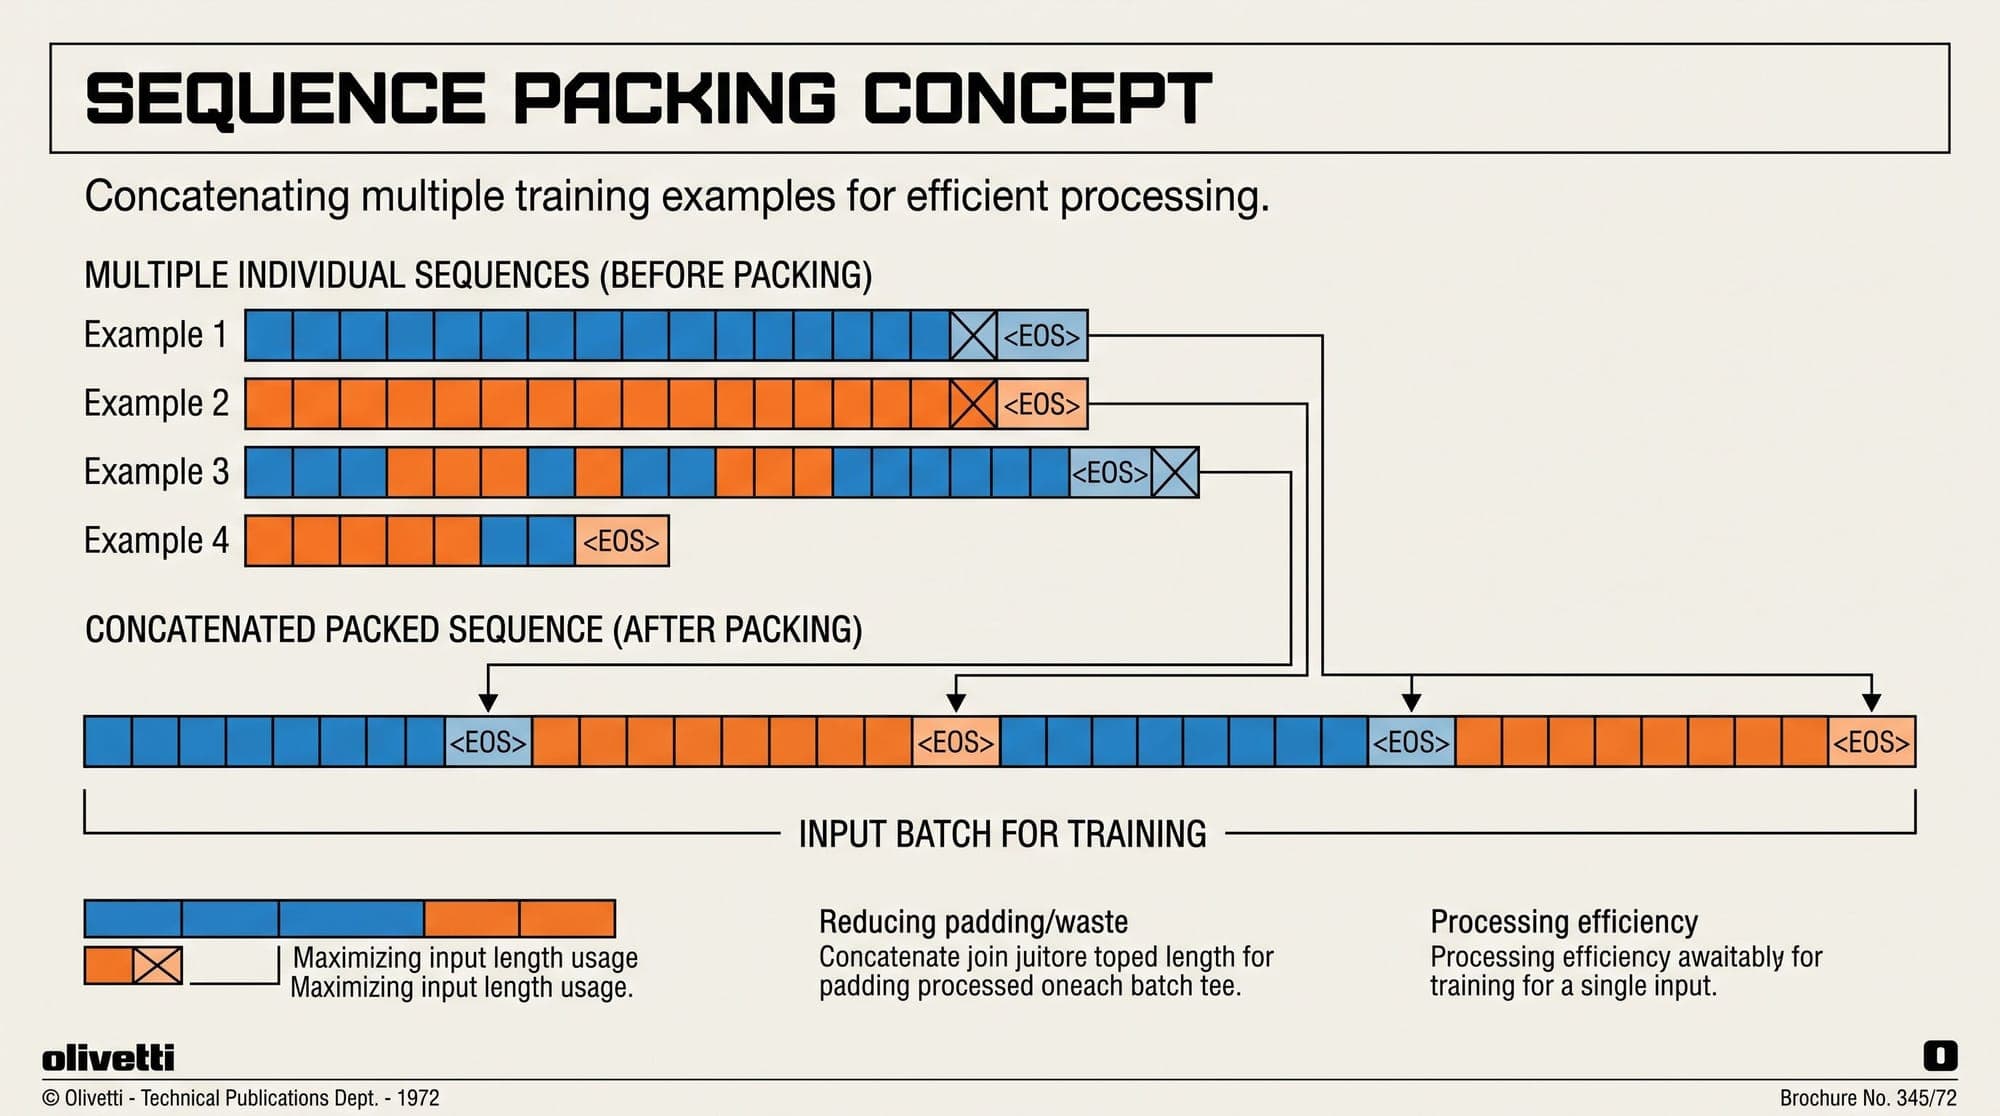
  4. Sequence Packing and Loss Masking in Production SFT: Architecture, Trade-Offs, and Framework Implementations

    Sequence Packing and Loss Masking in Production SFT: Architecture, Trade-Offs, and Framework Implementations Supervised fine-tuning pipelines routinely waste 40–70% of FLOPs on padding tokens. Sequence packing eliminates that waste by concatenating multiple training examples into a single long tensor, but it introduces three hard constraints: attention must not leak across example boundaries, loss must be computed only on the intended target spans (typically assistant responses), and the data c

    AI
    6 min read
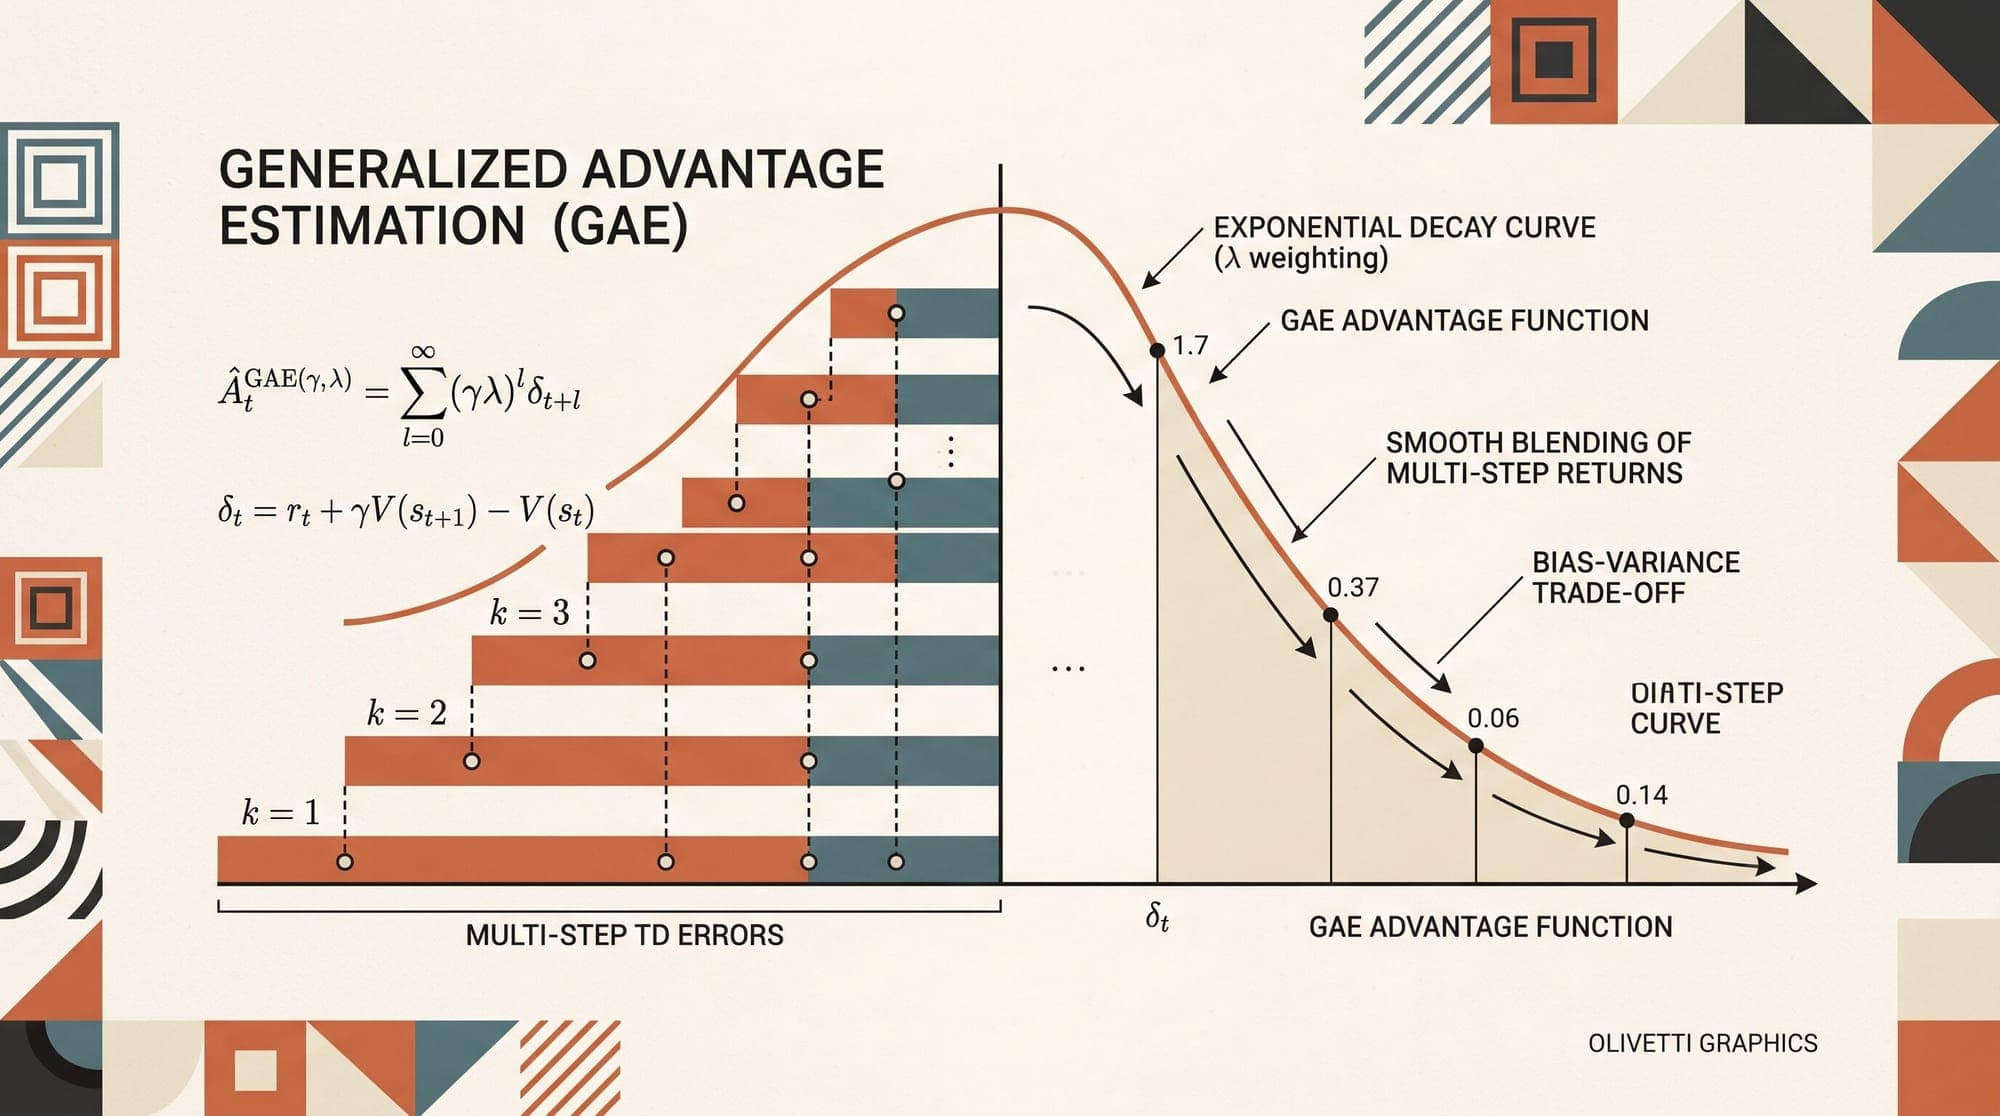
  5. Generalized Advantage Estimation: How Exponential Weighting Balances Bias and Variance in Policy Optimization

    Policy gradient algorithms form the theoretical backbone of modern policy optimization, ranging from continuous robotic control to reinforcement learning from human feedback (RLHF) in frontier large language models. A persistent challenge in policy optimization is variance: estimating the gradient of expected cumulative reward over stochastic trajectories generates high-variance Monte Carlo signals that require massive sample sizes and risk destabilizing gradient updates. Generalized Advantage

    AI
    6 min read
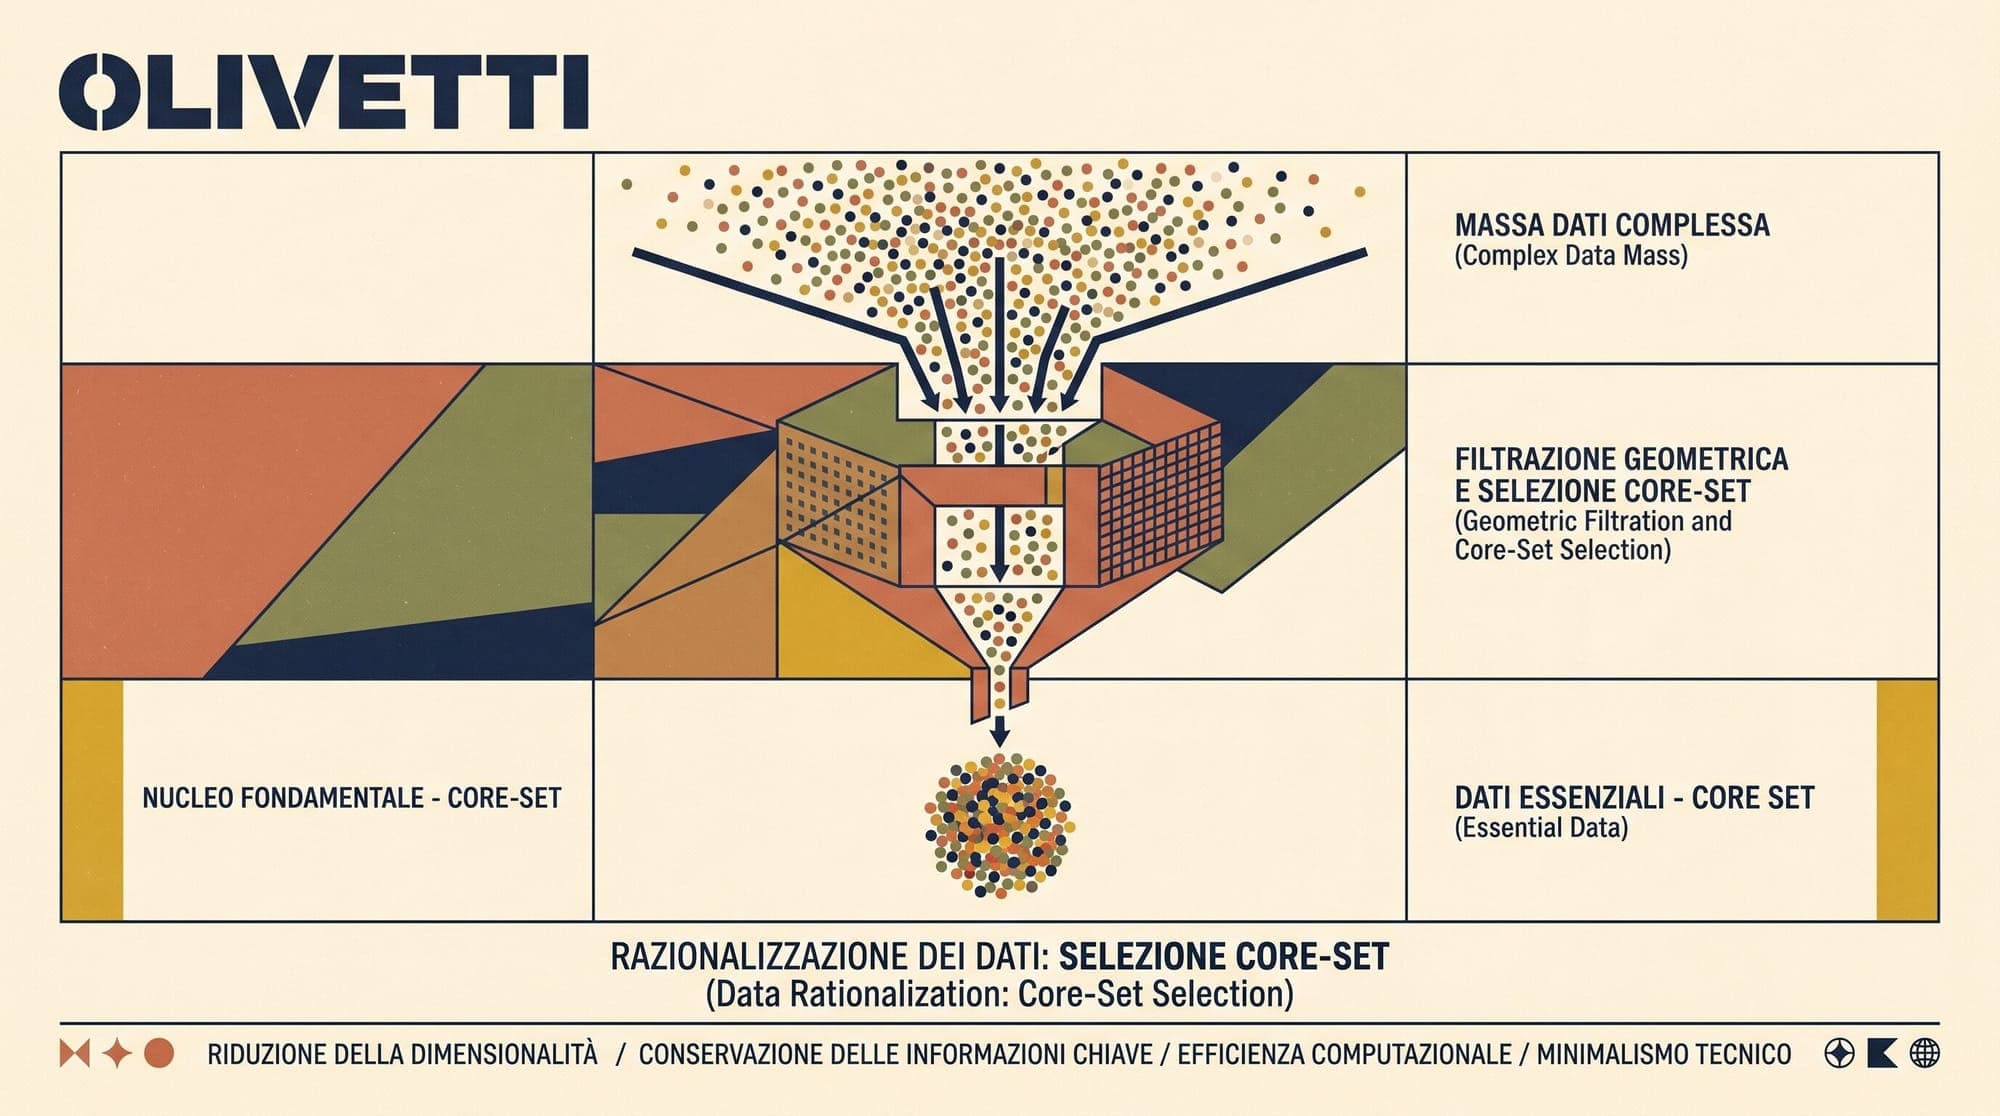
  6. Data Pruning and Core-Set Selection in Deep Learning: How EL2N, GraNd, and Memorization Dynamics Break Power-Law Scaling

    Modern foundation models are trained on tens of trillions of tokens, requiring millions of GPU hours. Yet empirical analyses consistently reveal that massive portions of web-crawled corpora and large-scale vision datasets are either highly redundant, uninformative, or dominated by unlearnable noise. Standard empirical scaling laws (such as those formulated by Kaplan et al. and Chinchilla) model generalization error as a power-law function of total training samples ($L(N) \propto N^{-\alpha}$). H

    AI
    7 min read
  7. Long-Context Evaluation in Production: Why Synthetic Needles Fail, Multi-Hop Stress Testing, and Benchmarking Effective Context Size

    Frontier model providers frequently market sequence lengths spanning 128K, 1M, or 2M tokens. However, engineering teams deploying these models in production environments for codebase refactoring, multi-turn agent execution, or complex document analysis regularly observe severe retrieval failures and reasoning breakdowns well before hitting context boundaries. The primary culprit behind this disconnect is the widespread reliance on vanilla Needle In A Haystack (NIAH) evaluations. While standard

    AI
    6 min read
  8. Energy-Based Models: How Energy Landscapes, Contrastive Divergence, and Langevin Dynamics Unify Generative Learning

    Energy-Based Models: How Energy Landscapes, Contrastive Divergence, and Langevin Dynamics Unify Generative Learning Probabilistic modeling in machine learning fundamentally centers on estimating data distributions over high-dimensional spaces. Standard generative architectures achieve this by enforcing structural constraints: autoregressive models factorize joint distributions through causal chains, normalizing flows constrain network architectures to invertible bijections with tractable Jacobi

    AI
    9 min read
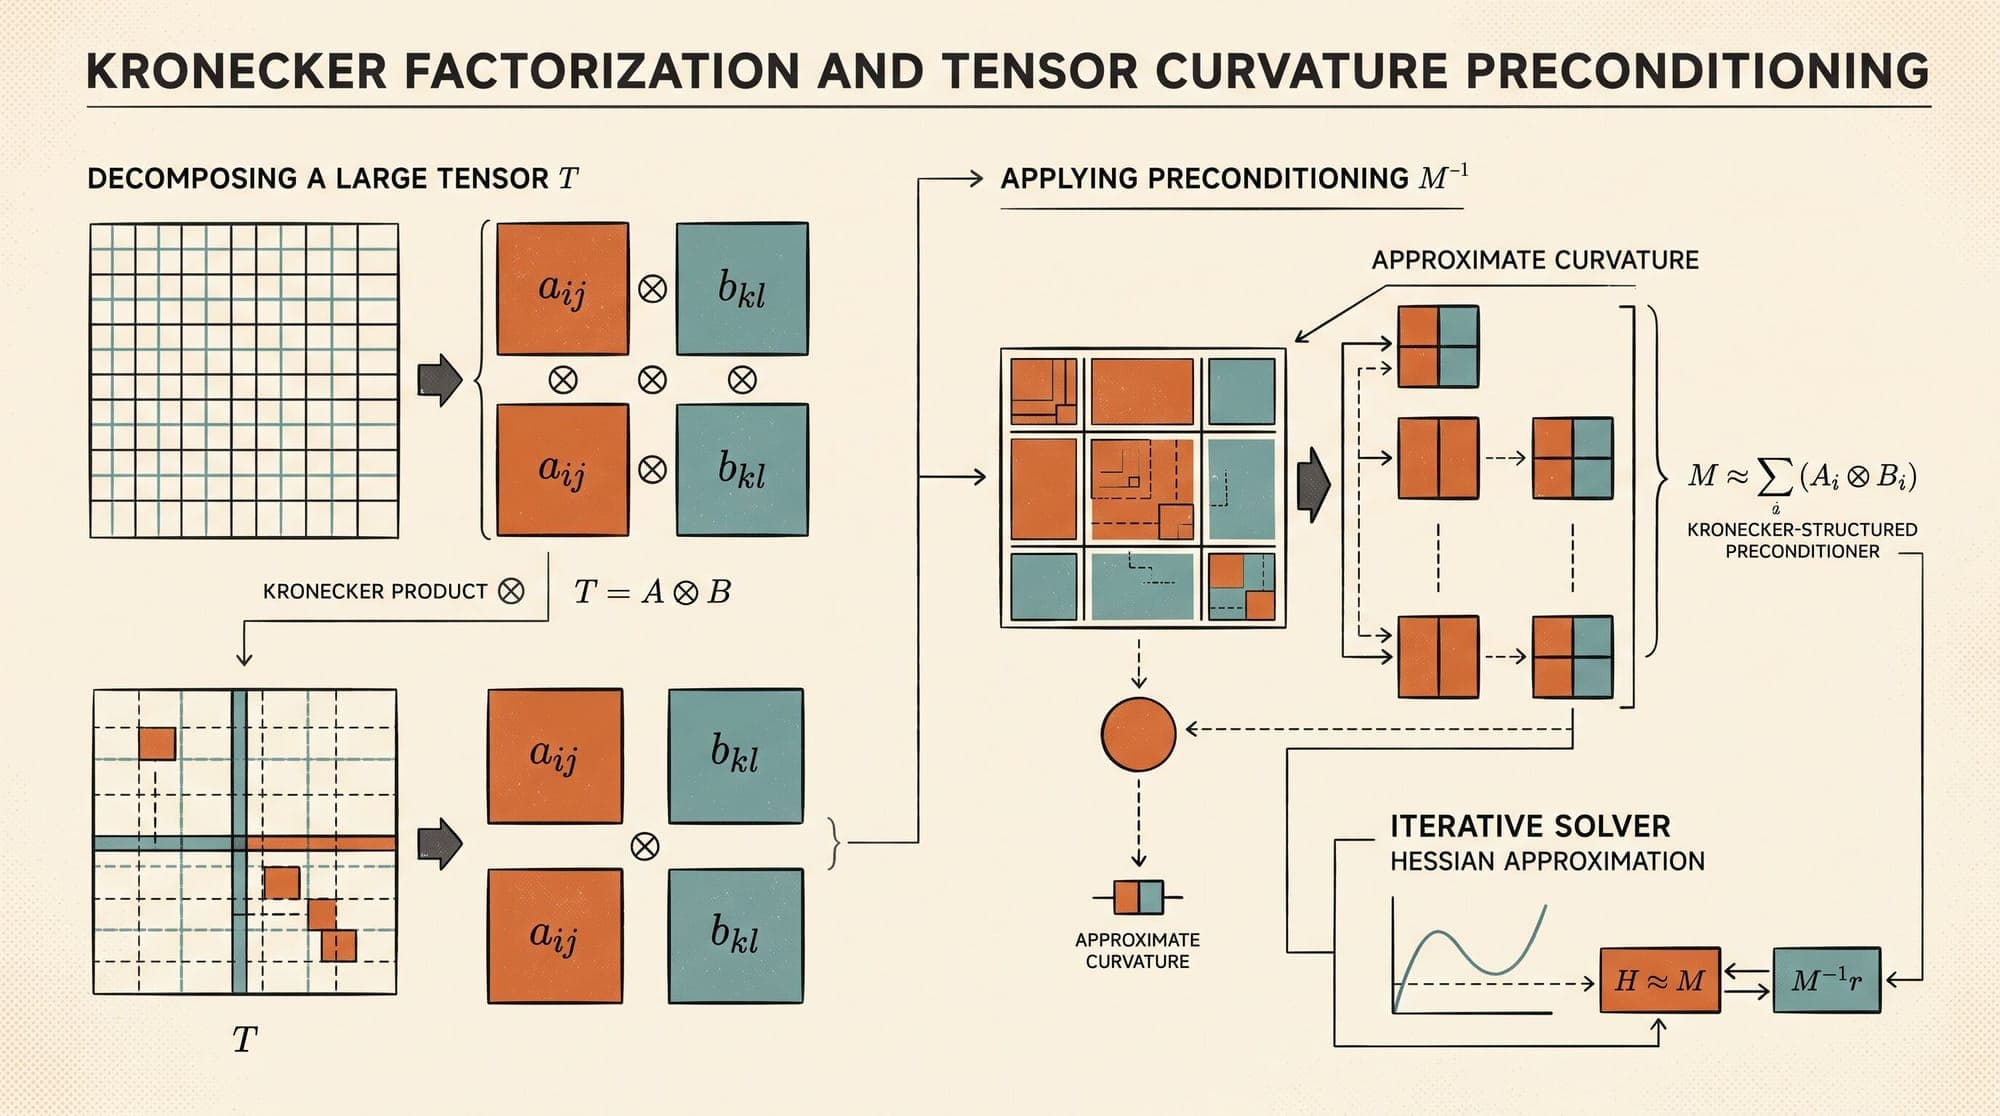
  9. Kronecker-Factored Approximate Curvature (K-FAC) and Shampoo: How Kronecker Preconditioning Scales Second-Order Optimization

    Kronecker-Factored Approximate Curvature (K-FAC) and Shampoo: How Kronecker Preconditioning Scales Second-Order Optimization Standard deep neural network pre-training relies almost exclusively on first-order stochastic gradient methods. Optimizers such as AdamW maintain running averages of individual parameter gradients and uncentered second moments, applying a coordinate-wise diagonal preconditioner. While computationally efficient, diagonal scaling ignores off-diagonal cross-layer and intra-l

    AI
    9 min read
  10. Multi-Agent Debate and Consensus Protocols in Production: Topologies, Stopping Criteria, and Error Cascade Prevention

    Single-model inference pipelines face severe structural limits when handling high-stakes reasoning, multi-step code synthesis, and mission-critical verification. While techniques like self-consistency decoding sample multiple independent trajectories from a single model to find majority consensus, they fail when the underlying model exhibits systemic bias or correlated hallucinations. When an LLM harbors a flawed premise, sampling ten independent stochastic paths frequently yields ten variations

    AI
    7 min read
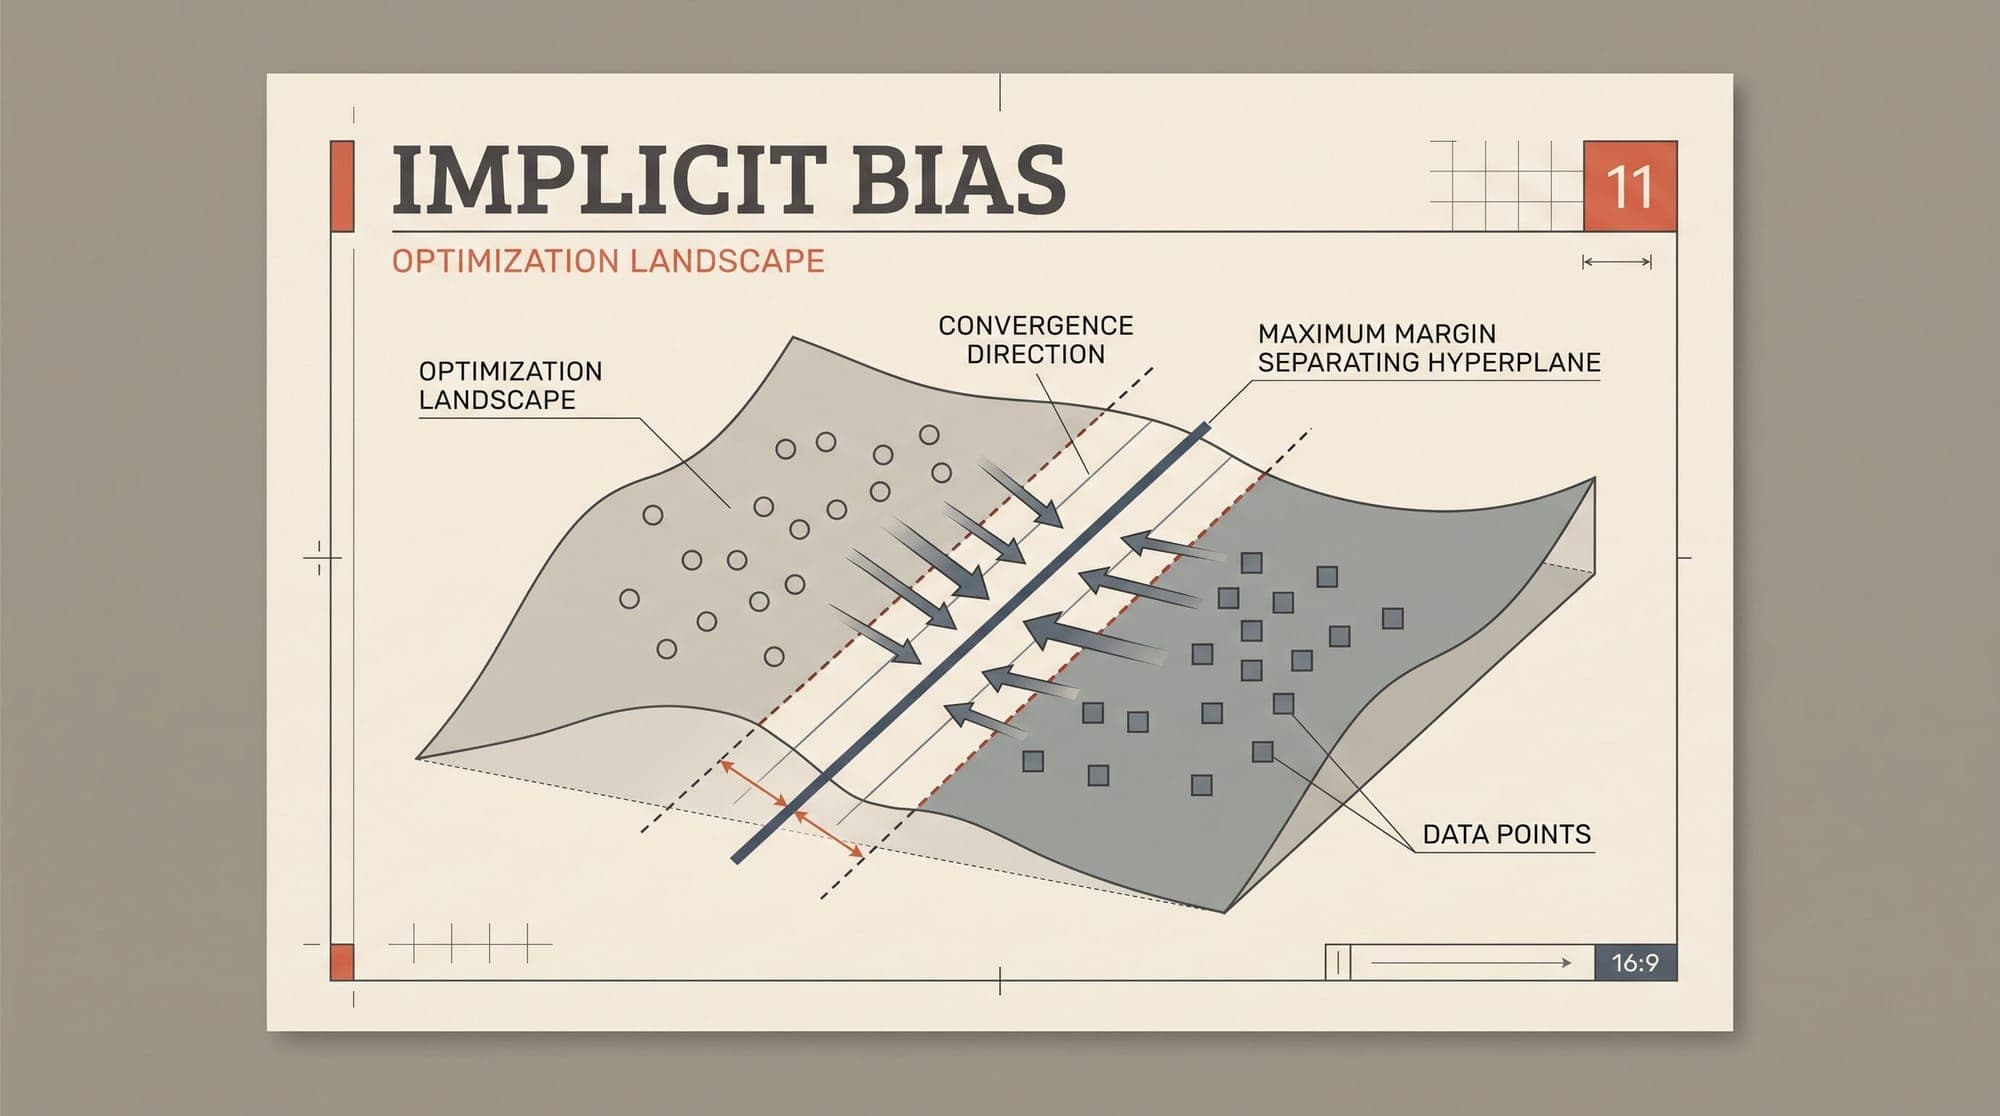
  11. Implicit Bias of Gradient Descent: How Optimization Geometry Replaces Explicit Regularization

    When engineers train a neural network with plain stochastic gradient descent and no weight decay, the result often generalizes instead of collapsing into an overfit mess. Classical learning theory predicts disaster: with more parameters than data points, unregularized training should find a memorizing interpolating solution with no predictive power. Instead, gradient descent reliably lands on solutions that look chosen. This systematic preference — the implicit bias of gradient descent — is one

    AI
    6 min read
  12. Compound AI Systems in Production: Architecture, Co-Optimization, and Error Cascades

    Compound AI Systems in Production: Architecture, Co-Optimization, and Error Cascades For the first two years following the release of GPT-4, enterprise AI development focused almost exclusively on model-centric scaling: upgrading to larger parameter checkpoints, expanding prompt context windows, and tuning system prompts. However, production deployments quickly revealed a fundamental constraint: single, monolithic foundation models exhibit diminishing returns on high-complexity, multi-step task

    AI
    7 min read
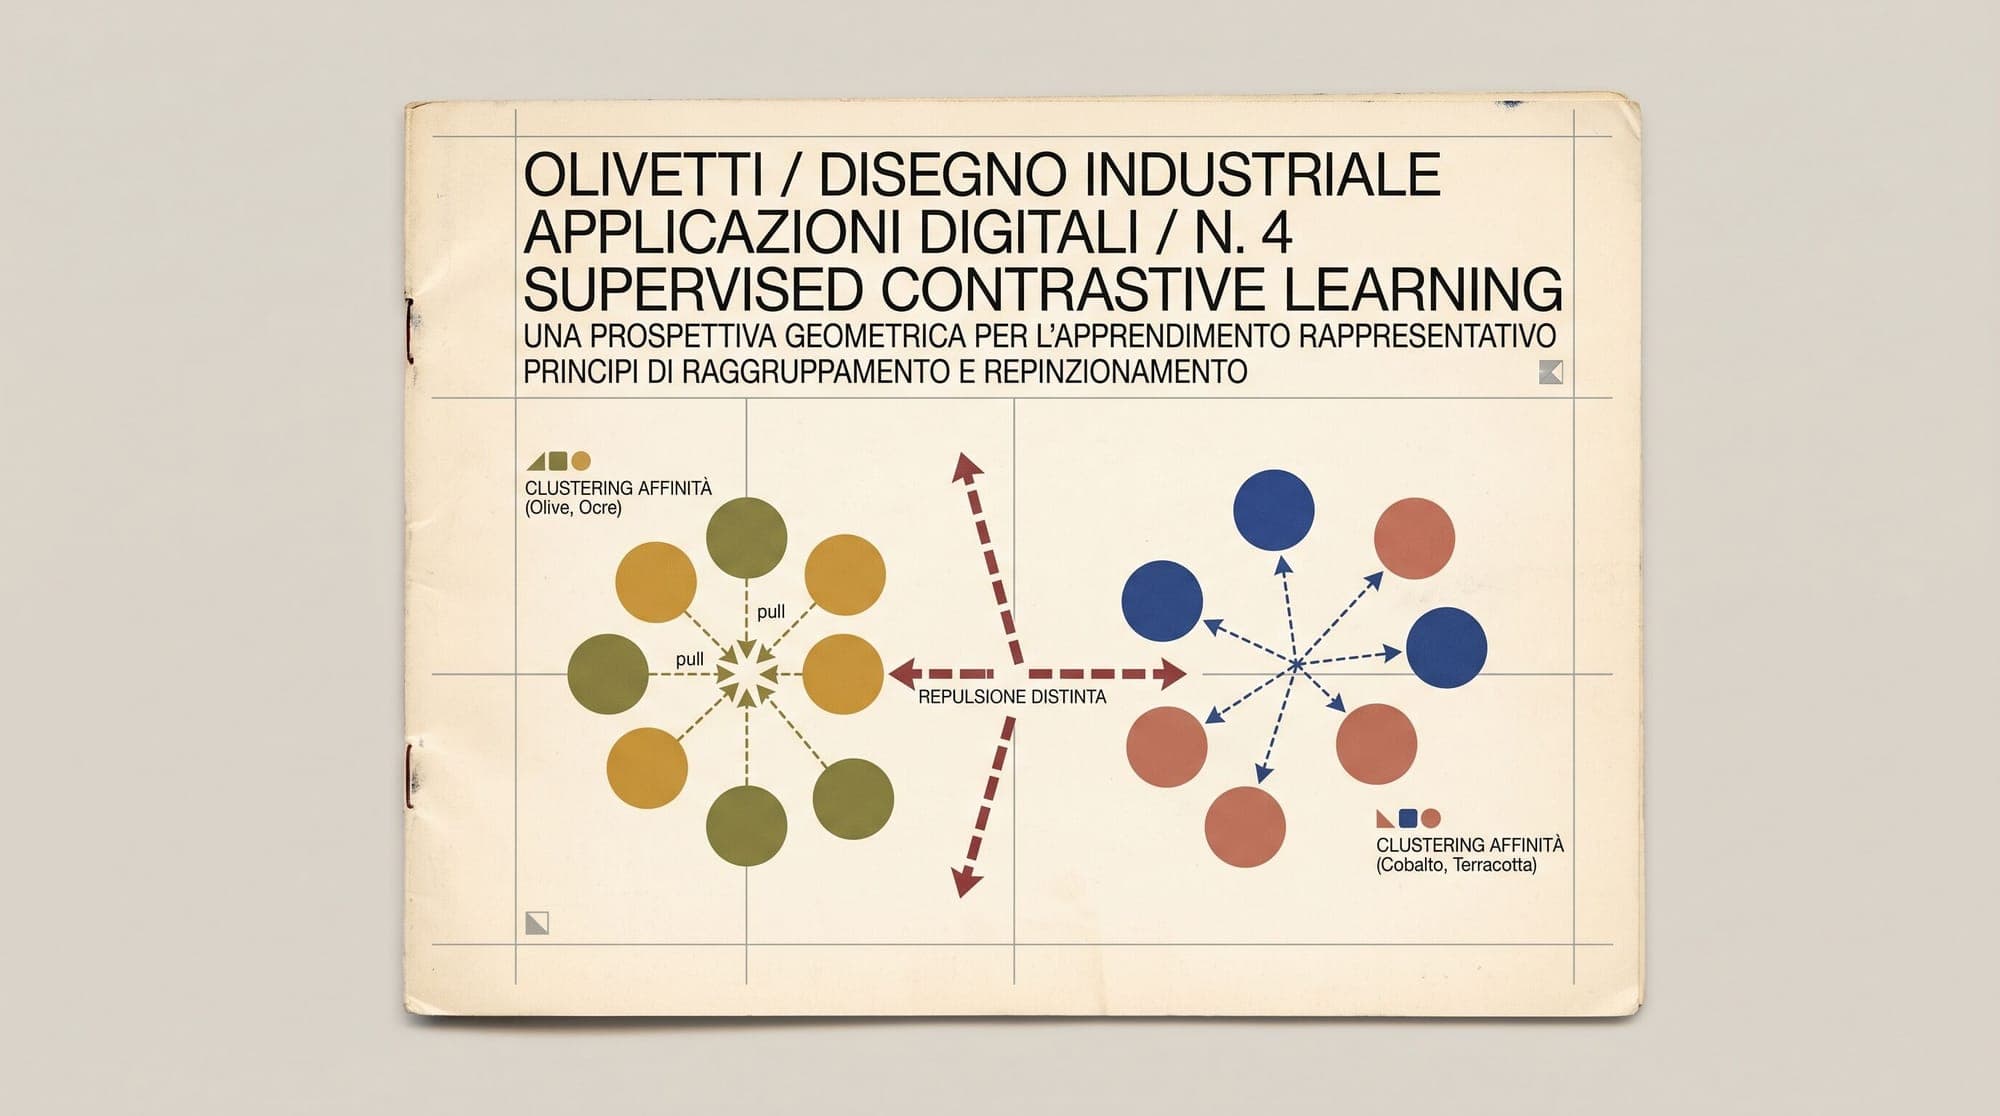
  13. Supervised Contrastive Learning: How Multi-Positive InfoNCE and Geometric Alignment Outperform Cross-Entropy

    Supervised Contrastive Learning: How Multi-Positive InfoNCE and Geometric Alignment Outperform Cross-Entropy For decades, the categorical cross-entropy loss function served as the default objective for supervised neural network training. By minimizing the negative log-likelihood of ground-truth class logits, cross-entropy drives neural network backpropagation across computer vision, natural language processing, and speech recognition. Despite its ubiquity, cross-entropy introduces structural sh

    AI
    8 min read
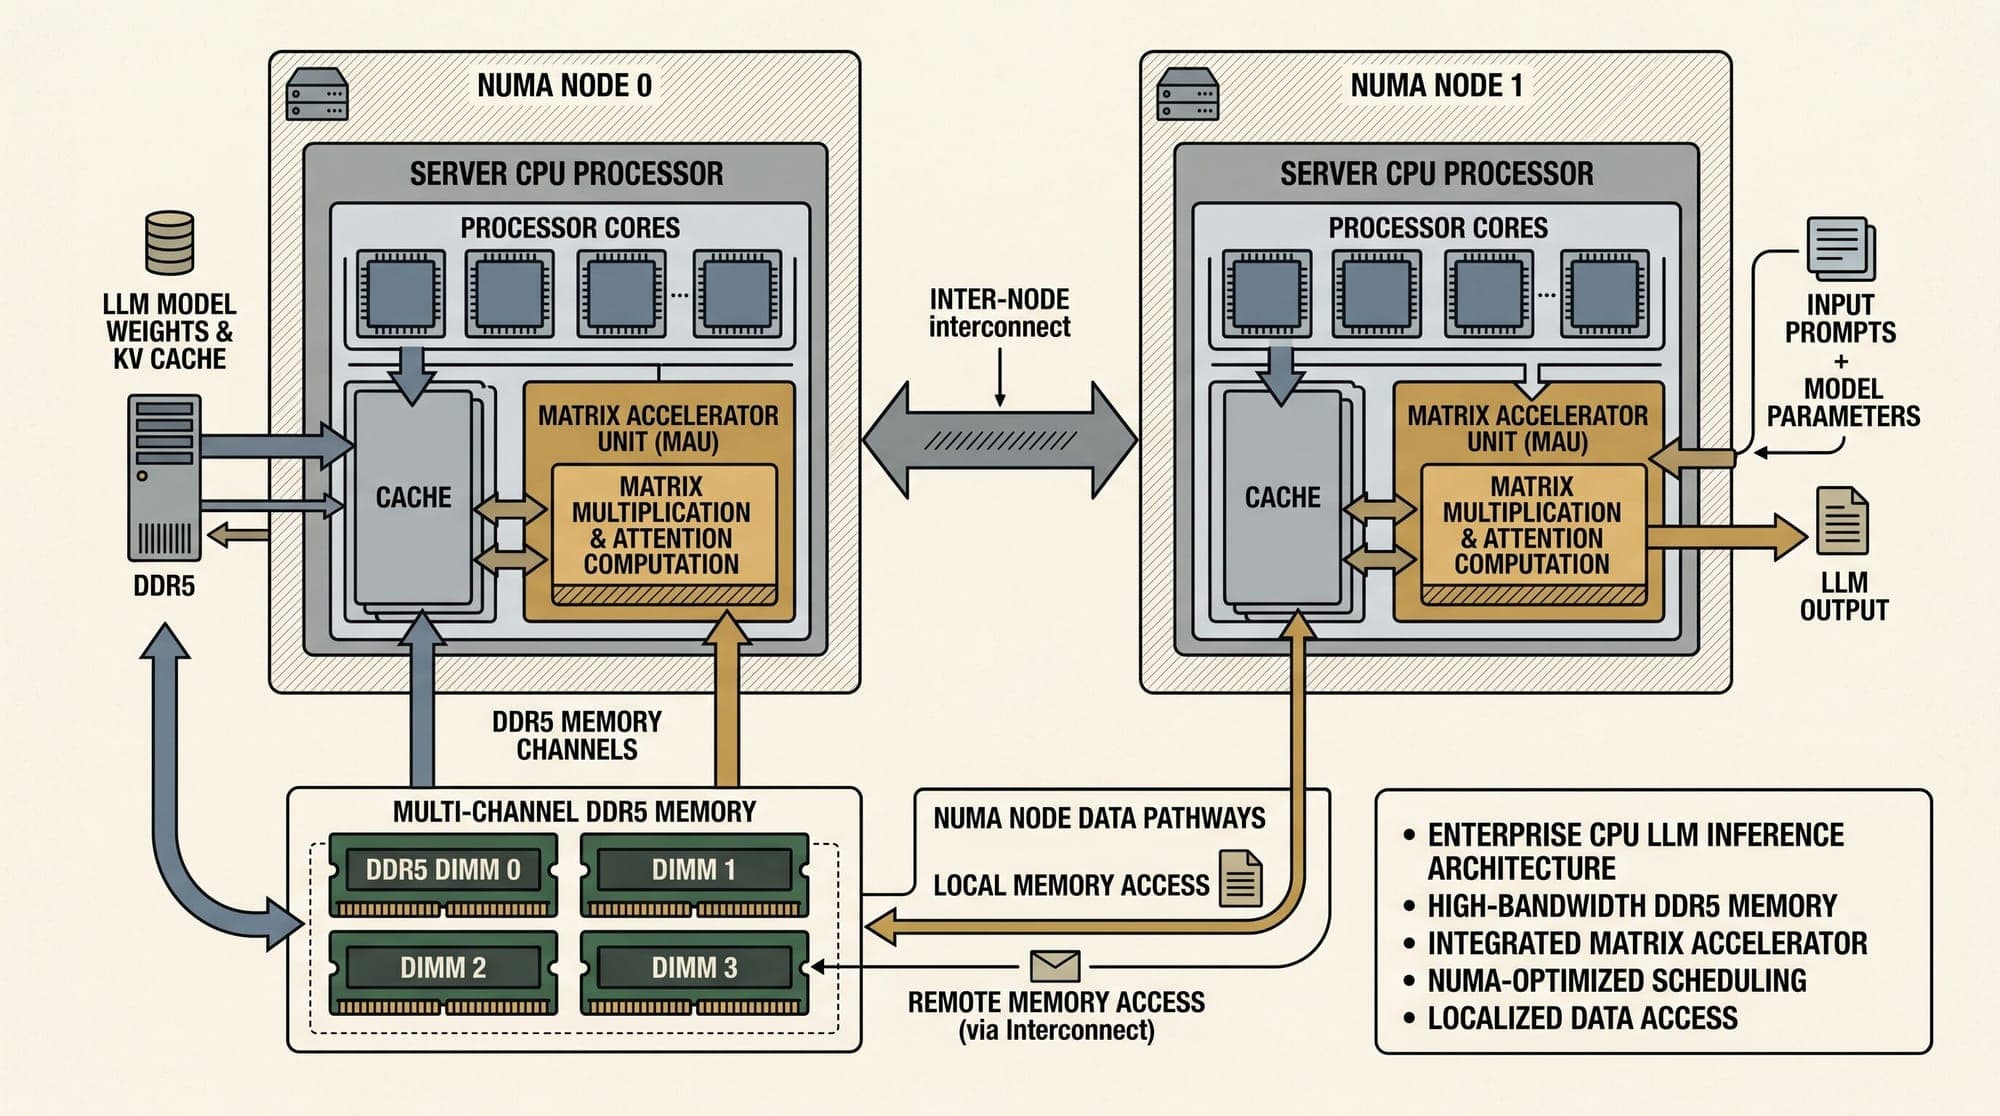
  14. LLM Inference on Enterprise CPUs in Production: Architecture, NUMA Topologies, Matrix Extensions, and Serving Economics

    Deploying large language models has historically been treated as an exclusively GPU-centric problem. Accelerators like NVIDIA H100 and A100 GPUs provide multi-terabyte-per-second High Bandwidth Memory (HBM) and tensor cores essential for training and high-concurrency serving. However, the operational economics of enterprise inference often diverge from frontier training requirements. Many enterprise applications, including internal code assistance, document extraction, low-concurrency agents, an

    AI
    6 min read
  15. The Edge of Stability: How Progressive Sharpening and Hessian Dynamics Govern Deep Learning Optimization

    In classical convex optimization, the behavior of gradient descent is dictated by the Lipschitz smoothness constant of the objective function. If a function $f(\theta)$ has an $L$-smooth gradient—meaning the largest eigenvalue of its Hessian matrix is bounded by $\lambda_{\max}(\nabla^2 f(\theta)) \le L$—gradient descent with learning rate $\eta$ is guaranteed to monotonically reduce the loss if and only if $\eta < 2/L$. When the step size exceeds this threshold ($\eta > 2/\lambda_{\max}$), stan

    AI
    7 min read
  16. Cross-Datacenter Distributed LLM Training in Production: DiLoCo, Local SGD, Communication Compression, and High-Latency Fault Tolerance

    Cross-Datacenter Distributed LLM Training in Production: DiLoCo, Local SGD, Communication Compression, and High-Latency Fault Tolerance Scaling frontier large language model pre-training within a single datacenter is encountering severe physical limits. Hyperscalers and AI laboratories increasingly face localized power grid saturation, where individual datacenter campuses cannot secure the 500 megawatt to multi-gigawatt utility allocations required for next-generation clusters. Consequently, in

    AI
    9 min read
  17. Relative Positional Encodings in Transformers: How Shaw's Attention, Transformer-XL, and T5 Relative Biases Preserve Translation Invariance

    Relative Positional Encodings in Transformers: How Shaw's Attention, Transformer-XL, and T5 Relative Biases Preserve Translation Invariance Standard self-attention operations in transformer architectures possess no inherent awareness of sequence order. Because scaled dot-product attention computes interactions across sets of tokens without regard to index ordering, early models relied on absolute positional encodings to inject sequential structure. While absolute encodings assign rigid coordina

    AI
    9 min read
  18. Tool-Call Failure Recovery in Production AI Agents: Syntactic Repair, Schema Coercion, Parameter Inoculation, and Dynamic Fallback Architectures

    Tool-Call Failure Recovery in Production AI Agents: Syntactic Repair, Schema Coercion, Parameter Inoculation, and Dynamic Fallback Architectures Autonomous language model agents operate by interleaving natural language reasoning traces with structured tool invocations. However, when deployed in multi-turn production environments, raw tool calling exhibits significant fragility. Empirical studies from benchmark suites such as $\tau$-bench (arXiv:2406.12045) and the Berkeley Function Calling Lead

    Agents
    8 min read
  19. SimCLR and MoCo: How Momentum Encoders, Dynamic Queues, and InfoNCE Scaled Self-Supervised Representation Learning

    Self-supervised visual representation learning underwent a foundational transformation in 2020 with the introduction of contrastive learning frameworks. Prior to this period, pre-training computer vision models without human annotations relied on heuristic pretext tasks such as jigsaw puzzle solving, rotation prediction, or autoencoding color channels. These methods forced networks to learn low-level geometric or statistical artifacts rather than generalizable semantic abstractions. Contrastive

    AI
    8 min read
  20. LLM Evaluation Arenas in Production: Bradley-Terry Modeling, Active Matchmaking, Style Bias Control, and Bootstrapped Elo Calibration

    LLM Evaluation Arenas in Production: Bradley-Terry Modeling, Active Matchmaking, Style Bias Control, and Bootstrapped Elo Calibration Static benchmarks such as MMLU, GSM8K, and HumanEval face severe limitations in production machine learning environments. Modern foundation models rapidly saturate static multiple-choice questions, training datasets frequently suffer from benchmark contamination, and synthetic test suites fail to capture open-ended, multi-turn user intent. Consequently, engineeri

    AI
    9 min read