
Google DeepMind's think tank says progress could carry AI straight past AGI into superintelligence
Google DeepMind's newly formed policy arm is telling its audience not to stop thinking at human-level AI. In an essay published this week on the DeepMind Institute site, researcher Tim Genewein argues that "while far from certain, AI could continue to advance at its current pace - and possibly even accelerate - towards artificial general superintelligence, or ASI."
The essay, titled "What comes after AGI?", is a plain-language distillation of a 60-page technical report Genewein and colleagues posted to arXiv in June, "From AGI to ASI." That paper was led by Genewein and includes Shane Legg, a DeepMind co-founder and the firm's chief AGI scientist, and Marcus Hutter, who formalized the mathematical theory of universal intelligence the report leans on. The DeepMind Institute itself launched in September as a standing publishing platform inside Google DeepMind, run by Legg, Google executive James Manyika and Demis Hassabis.
What counts as superintelligence, according to the paper
The authors set a deliberately high bar. AGI means a system at roughly median human performance across a broad set of cognitive tasks. ASI means something further along the continuum: a system that consistently outperforms large, well-coordinated groups of human experts - think tens of thousands of them working for years on a single problem - on virtually all tasks of human interest, not just narrow domains. Beating humans at chess or folding proteins does not qualify; matching an entire research field in a fraction of the time does.
The math behind the "cognitive industrialization" claim
The essay's central empirical argument is arithmetic rather than speculative. It decomposes the last decade of AI progress into three compounding trends:
- Compute per dollar has grown roughly 1.5x per year for six decades under Moore's-law-type dynamics.
- The training compute needed to reach a fixed performance level has fallen 3-6x per year over the last decade, with inference efficiency improving around 3x per year.
- Spending on AI hardware has grown roughly 2.5x per year, and the largest frontier training runs grow more than 4x per year.
Multiplied together, that is at least 10x annual growth in global effective compute stock. On efficiency alone, the essay estimates the cost of a given cognitive workload falls about 4x per year - work that costs $1 billion in tokens today would cost roughly $1,000 in a decade. It cites a recent Epoch study finding the consumer price of hitting a fixed benchmark score has fallen more than 13x per year since 2023.
If those curves hold, the practical ceiling on data centers and chips might still allow the effective population of today's-class agents to grow more than a thousand-fold by 2030 and more than a billion-fold within ten years. Genewein's framing: sheer scale may have "a quality of its own," and billions of agents acting faster than humans could itself bridge the gap from AGI to a weak form of ASI.
Four pathways, and why blocking one will not work
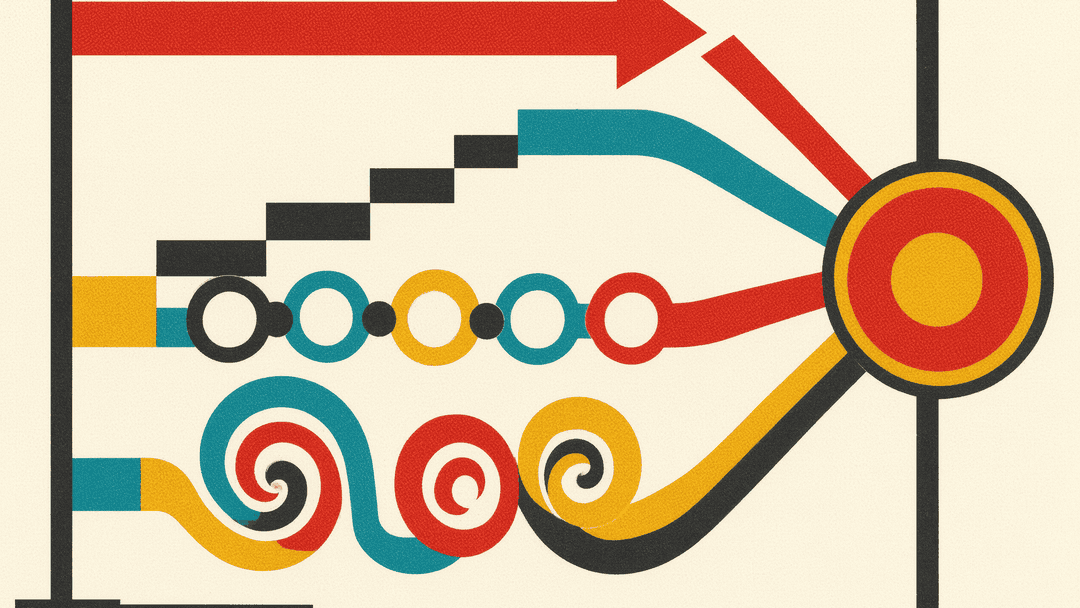
Beyond raw scaling, the essay maps four routes to stronger cognitive capabilities: scaling models and data further; technological paradigm shifts to fix gaps in continual learning, world modeling and genuine concept invention; multi-agent coordination that turns fleets of AGI instances into "group agents" with superlinear output; and recursive self-improvement, where AI systems speed up the design of their successors, fastest in domains with automated verification like mathematics.
Each route has named bottlenecks - the data wall, diminishing returns on model size, power and grid limits, coordination inefficiencies that grow with agent population, and RSI loops that stall without reliable evaluation. The governance point is the sharpest: because the pathways compound and substitute for each other, restricting any single input such as training compute "won't be enough to stop overall progress," and suppressing one dimension while others advance risks a capability "overhang" that releases in a sudden jump once the blockade lifts.
The tone is hedged in every paragraph - "serious possibility," "not a given," "far from certain" - but the conclusion is unambiguous about what the authors think should happen next: model, measure and forecast the road to ASI at an industrial scale, across frontier labs and public institutions, because "human-level AGI... is far from the upper limit of intelligence."
The essay lands while the industry's wealth machine is at full visible capacity: Anthropic completed what Bloomberg called a record-breaking IPO two days after this essay began circulating, and OpenAI is expected to reach public markets next year. Whether investors are pricing in AGI, superintelligence, or just enterprise Claude subscriptions, the labs' own researchers are now publishing the roadmap - and the guardrails argument - in advance.
Sources
- Tim Genewein, "What comes after AGI?", DeepMind Institute, November 2026. https://institute.deepmind.com/essays/what-comes-after-agi
- "From AGI to ASI," Genewein, Legg, Hutter et al., arXiv, June 2026. https://arxiv.org/abs/2606.12683
- Techmeme item on the essay, November 19, 2026. https://www.techmeme.com/261119/p57
- "Google DeepMind launches institute to widen the AGI debate," TechCrunch, September 2026. https://techcrunch.com/2026-09-17/google-deepmind-launches-institute-to-widen-the-agi-debate/
