Research / page 15

Research

470 articles

Articles, page 15

281-300 of 470
  1. inclusionAI Releases Six Ling-3.0 Base Checkpoints with Warmup-Stable-and-Merge Architecture

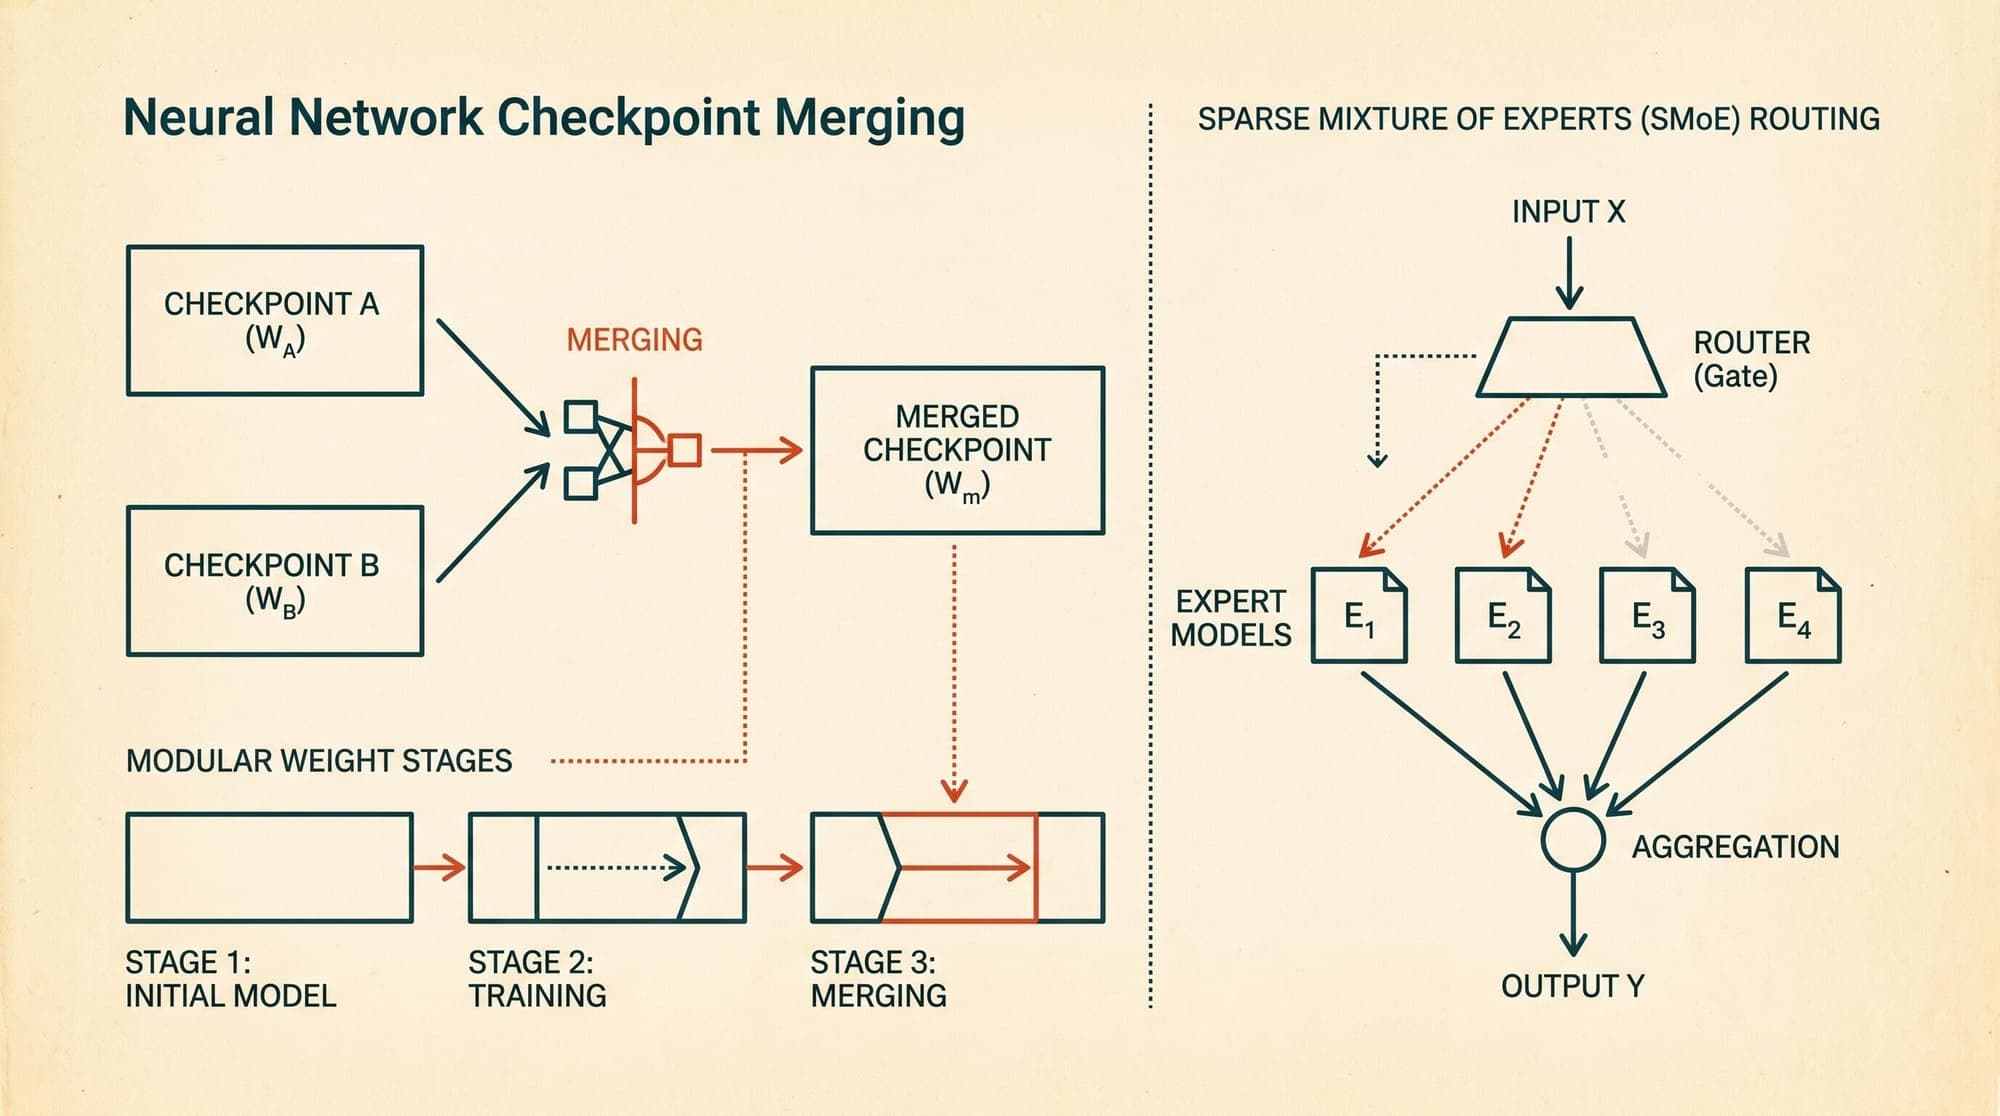
    Ant Group's AI research lab, inclusionAI, has publicly released six open-weight base checkpoints for its Ling-3.0 foundation model family under the permissive MIT license. The release spans two distinct parameter scales (Ling-3.0-flash and Ling-3.0-tiny) and captures three sequential stages of the pre-alignment training pipeline. Rather than providing solely post-trained chat models, the release provides unaligned base weights designed specifically for continued pre-training, domain-specific mi
    AI
    2 min read
  2. GPU Memory Profiling in Production LLM Serving: CUDA Allocator Internals, PyTorch Snapshots, and VRAM Optimization

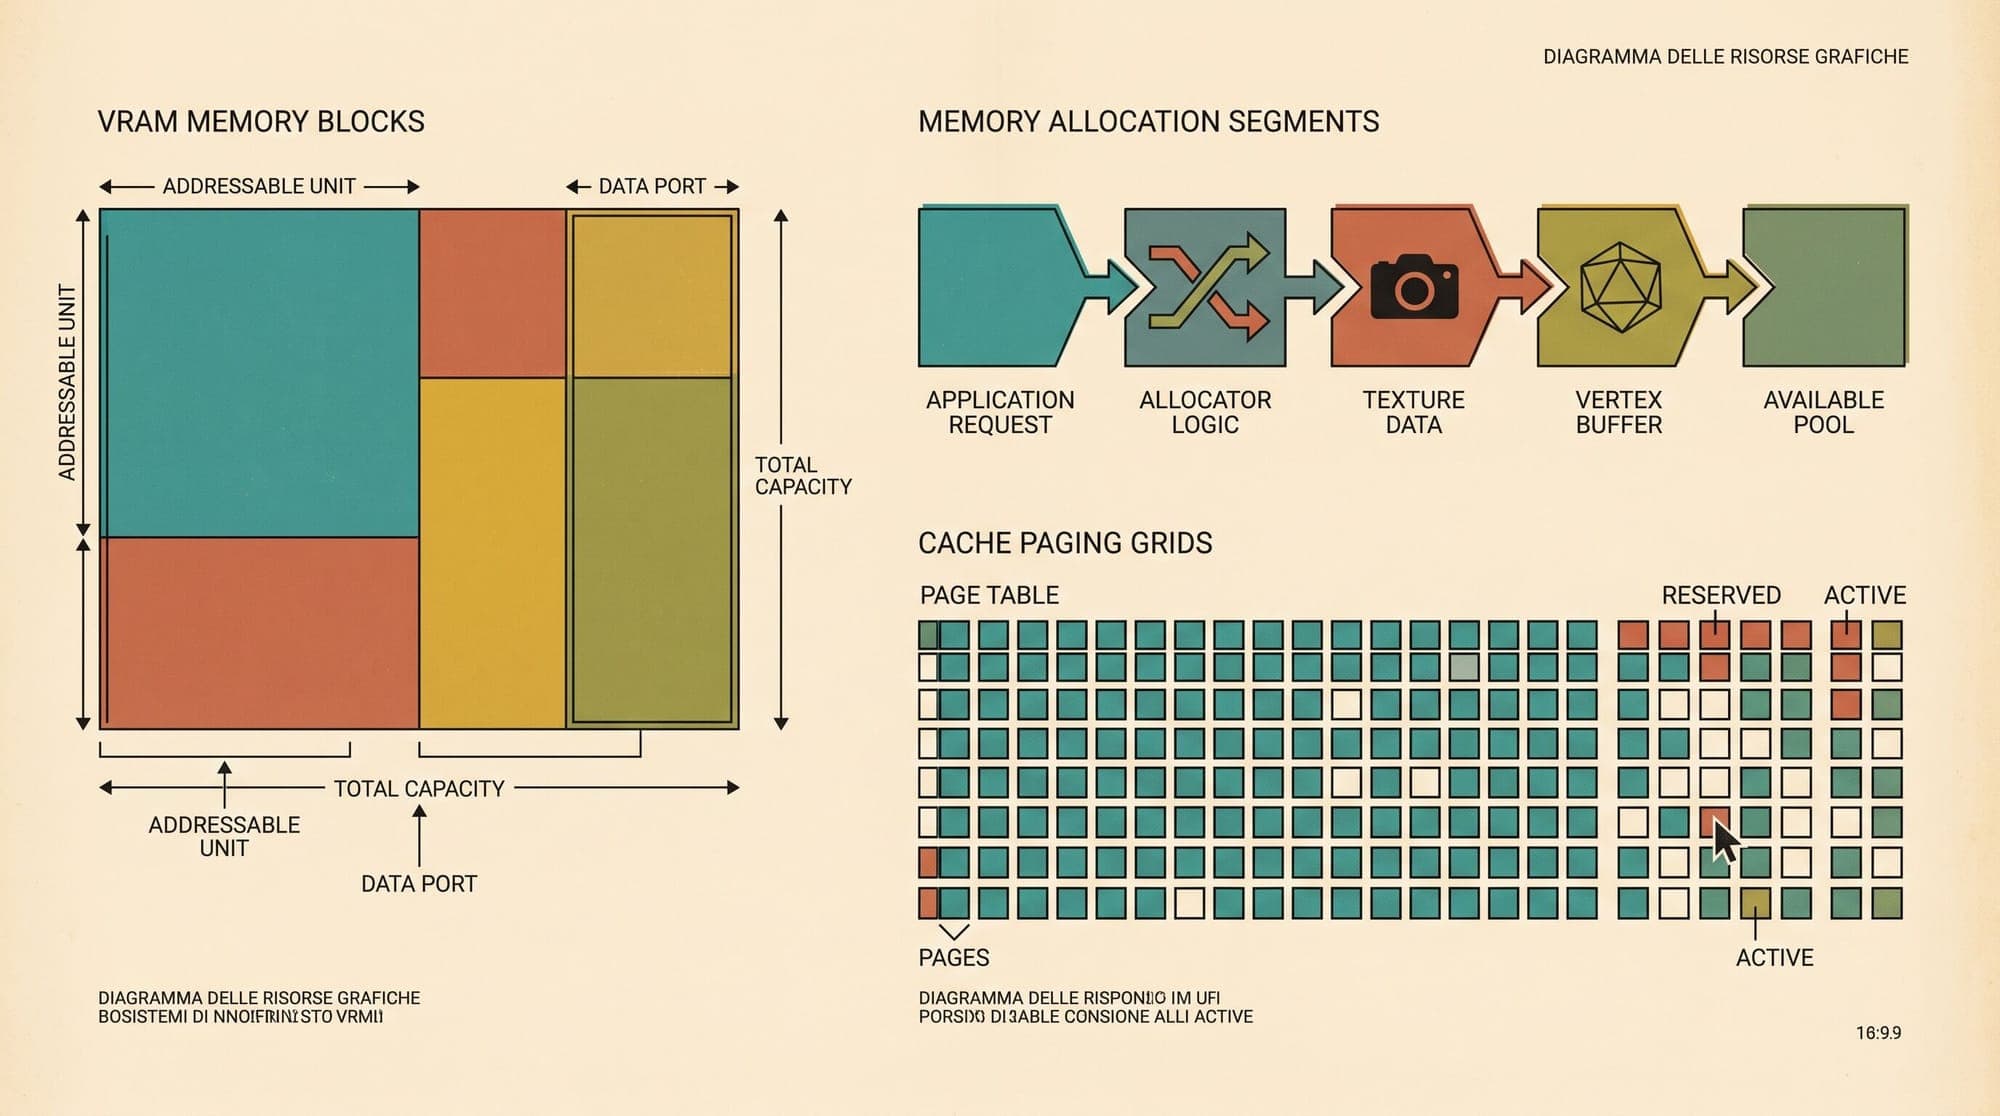
    In high-throughput large language model serving, memory is the primary constraint governing latency, batch concurrency, and context length. While model parameter footprints are static and easily calculated, runtime GPU memory (VRAM) dynamics are governed by low-level caching allocators, dynamic key-value (KV) cache allocation pools, transient activation spikes, and memory fragmentation. When an inference worker crashes with torch.cuda.OutOfMemoryError, default system diagnostics such as nvidia-

    LLM
    6 min read
  3. Weight Tying in Large Language Models: Mathematical Foundations, Geometric Bottlenecks, and Modern Architectural Trade-Offs

    Weight Tying in Large Language Models: Mathematical Foundations, Geometric Bottlenecks, and Modern Architectural Trade-Offs In autoregressive language models, the embedding layer at the input and the unembedding projection layer at the output serve as the two bridges between discrete vocabulary tokens and the continuous hidden representation space. In the foundational Transformer architecture (Vaswani et al., 2017) and early generative models like GPT-2 (Radford et al., 2019), the weights of th

    AI
    8 min read
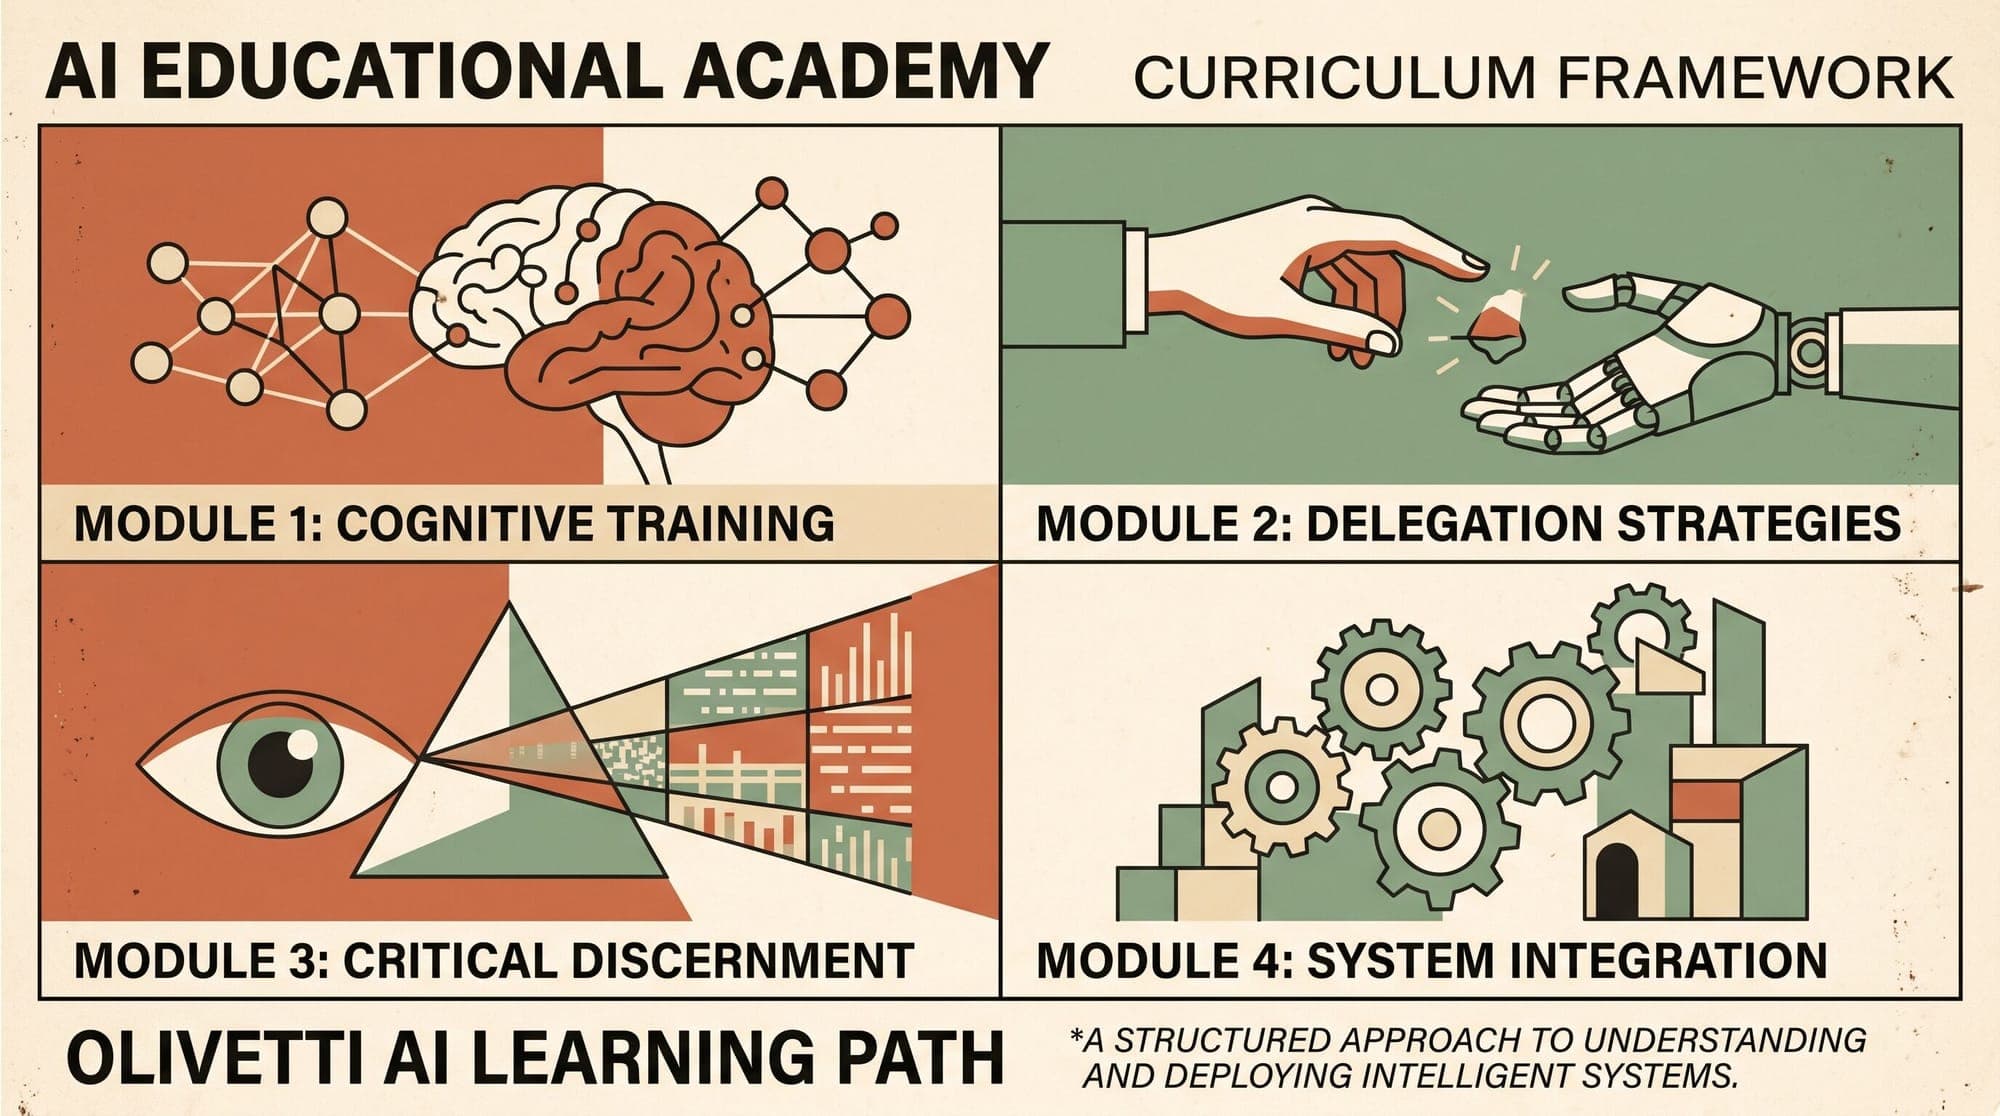
  4. Anthropic Launches Claude Academy and 4D AI Fluency Framework for Workforce Training

    Anthropic has launched Claude Academy, an interactive training platform aimed at standardizing how individuals and enterprise teams learn, deploy, and evaluate AI systems. Available via academy.claude.com and directly inside the Claude profile interface, the program couples tool-specific training modules with a foundational curriculum designed to cultivate systematic AI interaction patterns. The initiative comes as enterprise adoption shifts from ad-hoc prompting toward autonomous agent workflo

    Anthropic
    2 min read
  5. Semantic Drift and Data Distribution Monitoring in Production LLM Systems: Embedding Shift Detection, Output Entropy Tracking, and Quality Decay Metrics

    Semantic Drift and Data Distribution Monitoring in Production LLM Systems: Embedding Shift Detection, Output Entropy Tracking, and Quality Decay Metrics Large language model applications rarely fail with loud runtime crashes once deployed. Instead, production systems suffer from silent performance decay caused by data distribution shifts. User queries evolve, real-world domain vocabularies change, retrieval corpora expand, and upstream model providers quietly alter model weights or system promp

    AI
    7 min read
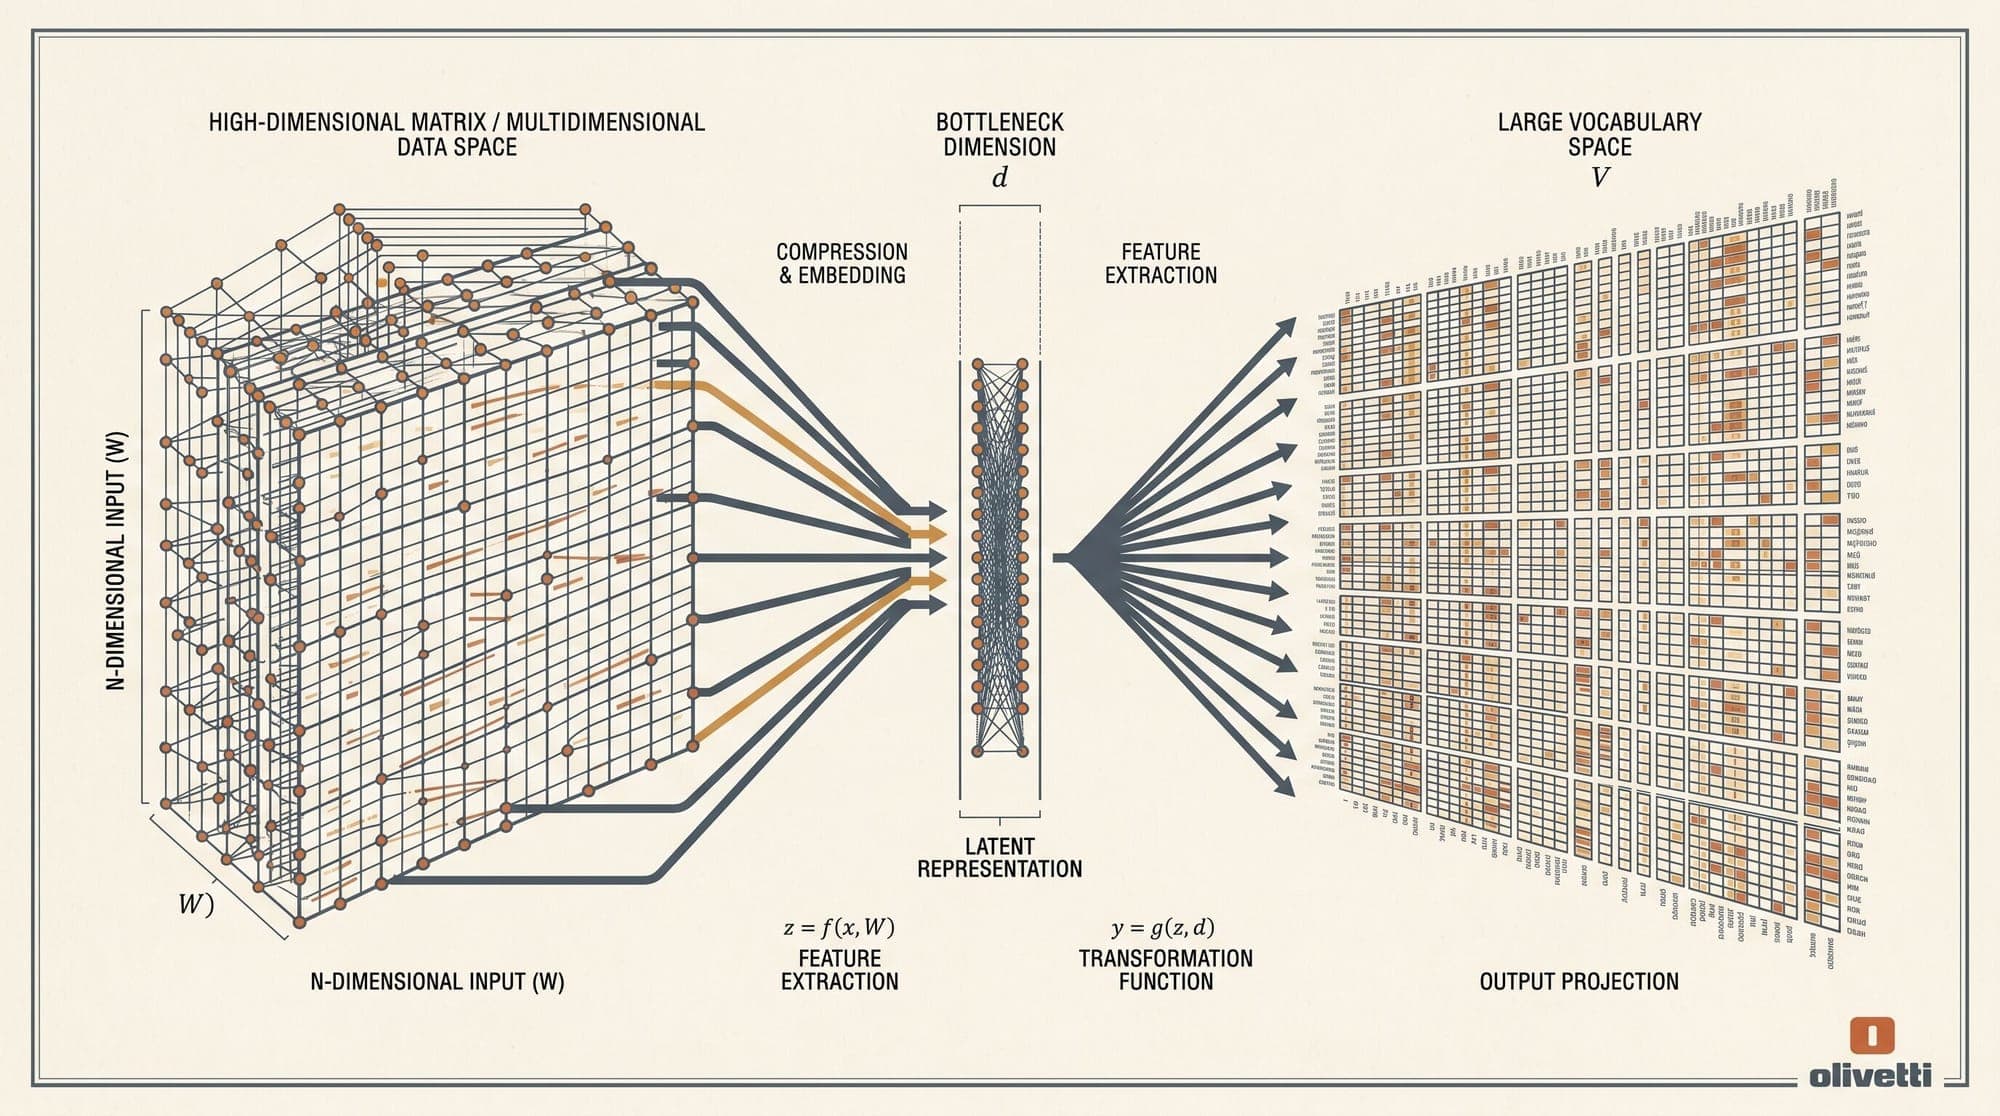
  6. The Softmax Bottleneck in Large Language Models: Matrix Factorization Bounds, High-Rank Token Distributions, and Mixture of Softmaxes

    Autoregressive language models predict probability distributions over vocabulary tokens conditioned on preceding text. In standard Transformer architectures, the model computes a hidden state vector $h_c \in \mathbb{R}^d$ for a given context $c$, projects it into vocabulary space using a linear unembedding matrix $W \in \mathbb{R}^{V \times d}$, and applies the softmax function to normalize the resulting logits into probabilities. While computationally convenient, this formulation imposes a fun

    AI
    8 min read
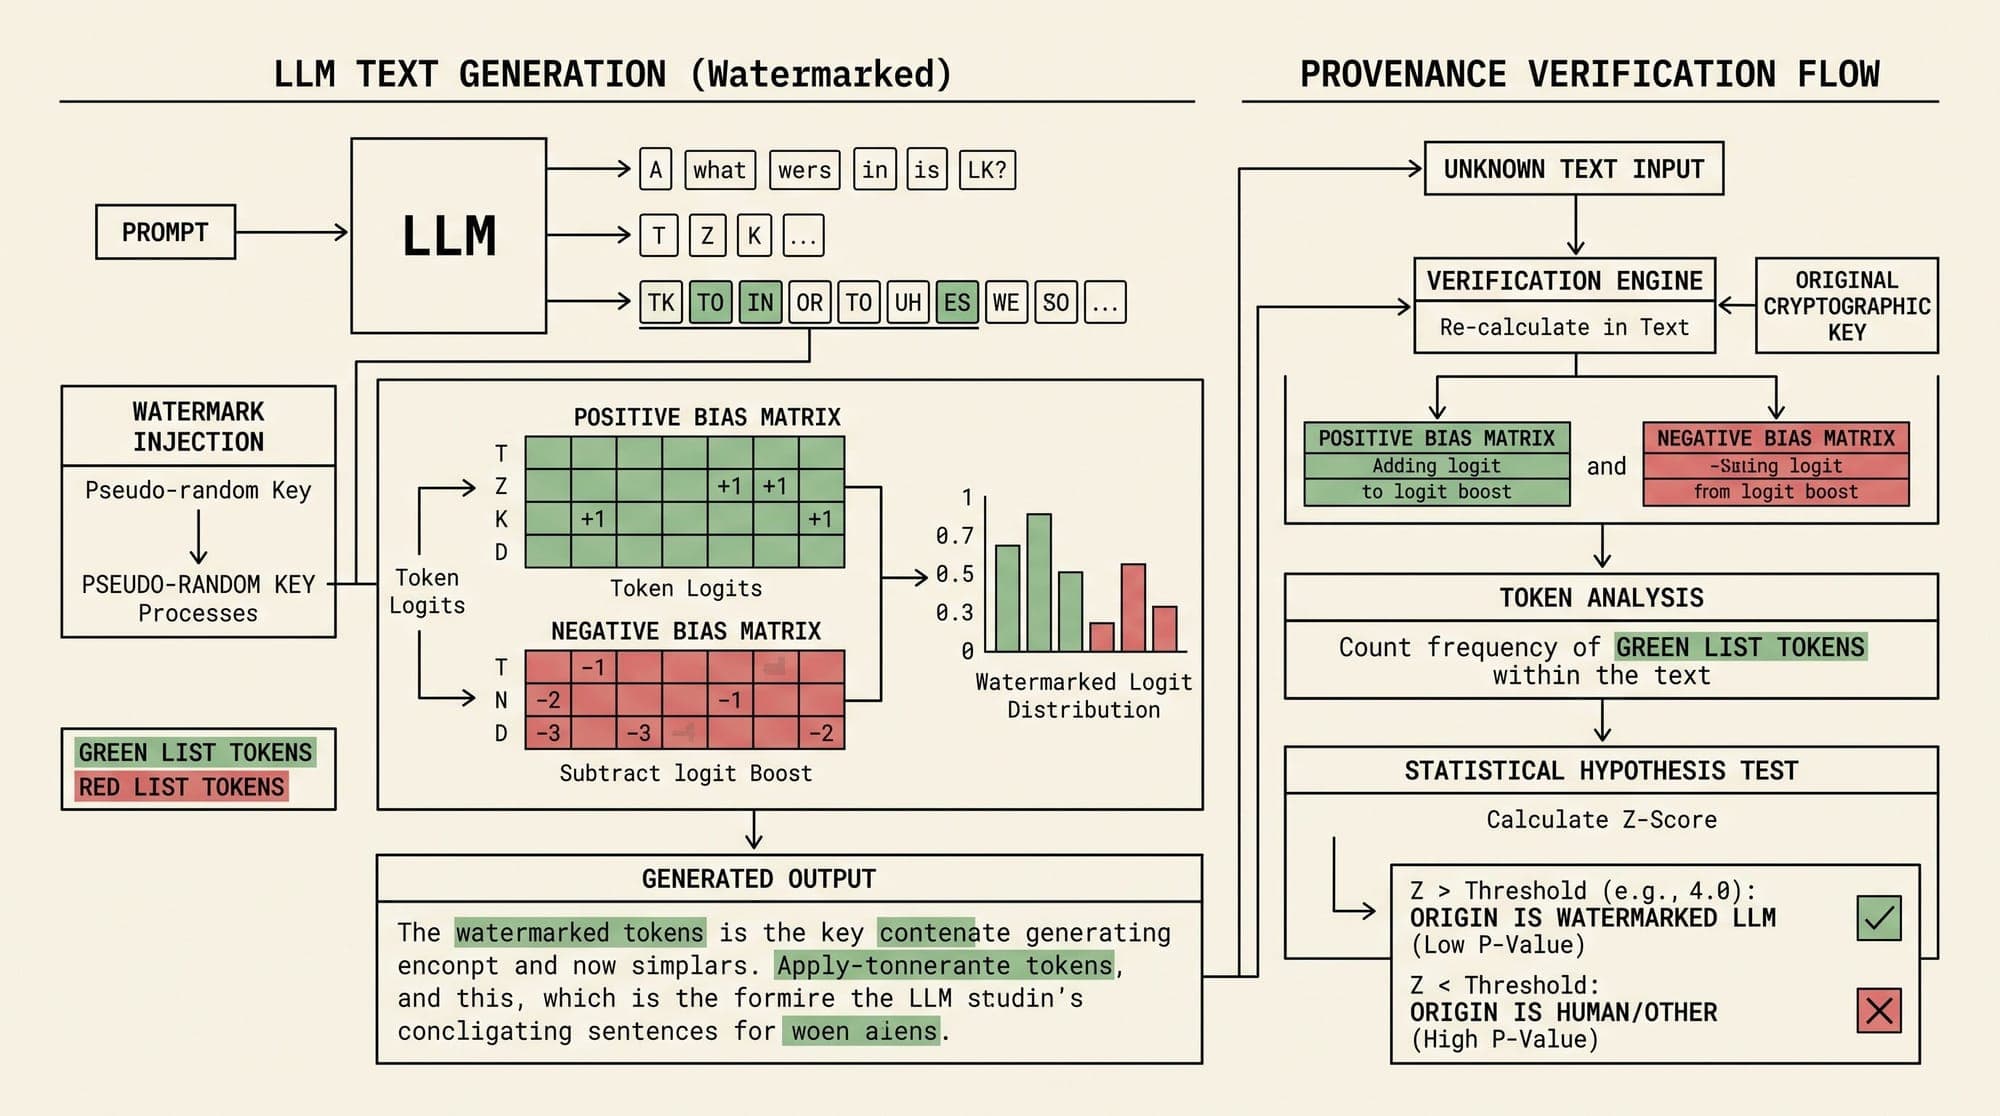
  7. LLM Text Watermarking in Production: Statistical Logit Biasing, Cryptographic Signatures, and Evasion Vectors

    As regulatory frameworks such as Article 50 of the EU AI Act enforce machine-generated content provenance, text watermarking has transitioned from academic theory to a core component of production LLM serving stacks. Unlike post-hoc classifiers that evaluate perplexity or burstiness and suffer from high false-positive rates on formal or non-native writing, generation-time watermarks embed imperceptible statistical or cryptographic signals directly into the token sampling process. When engineere

    AI
    5 min read
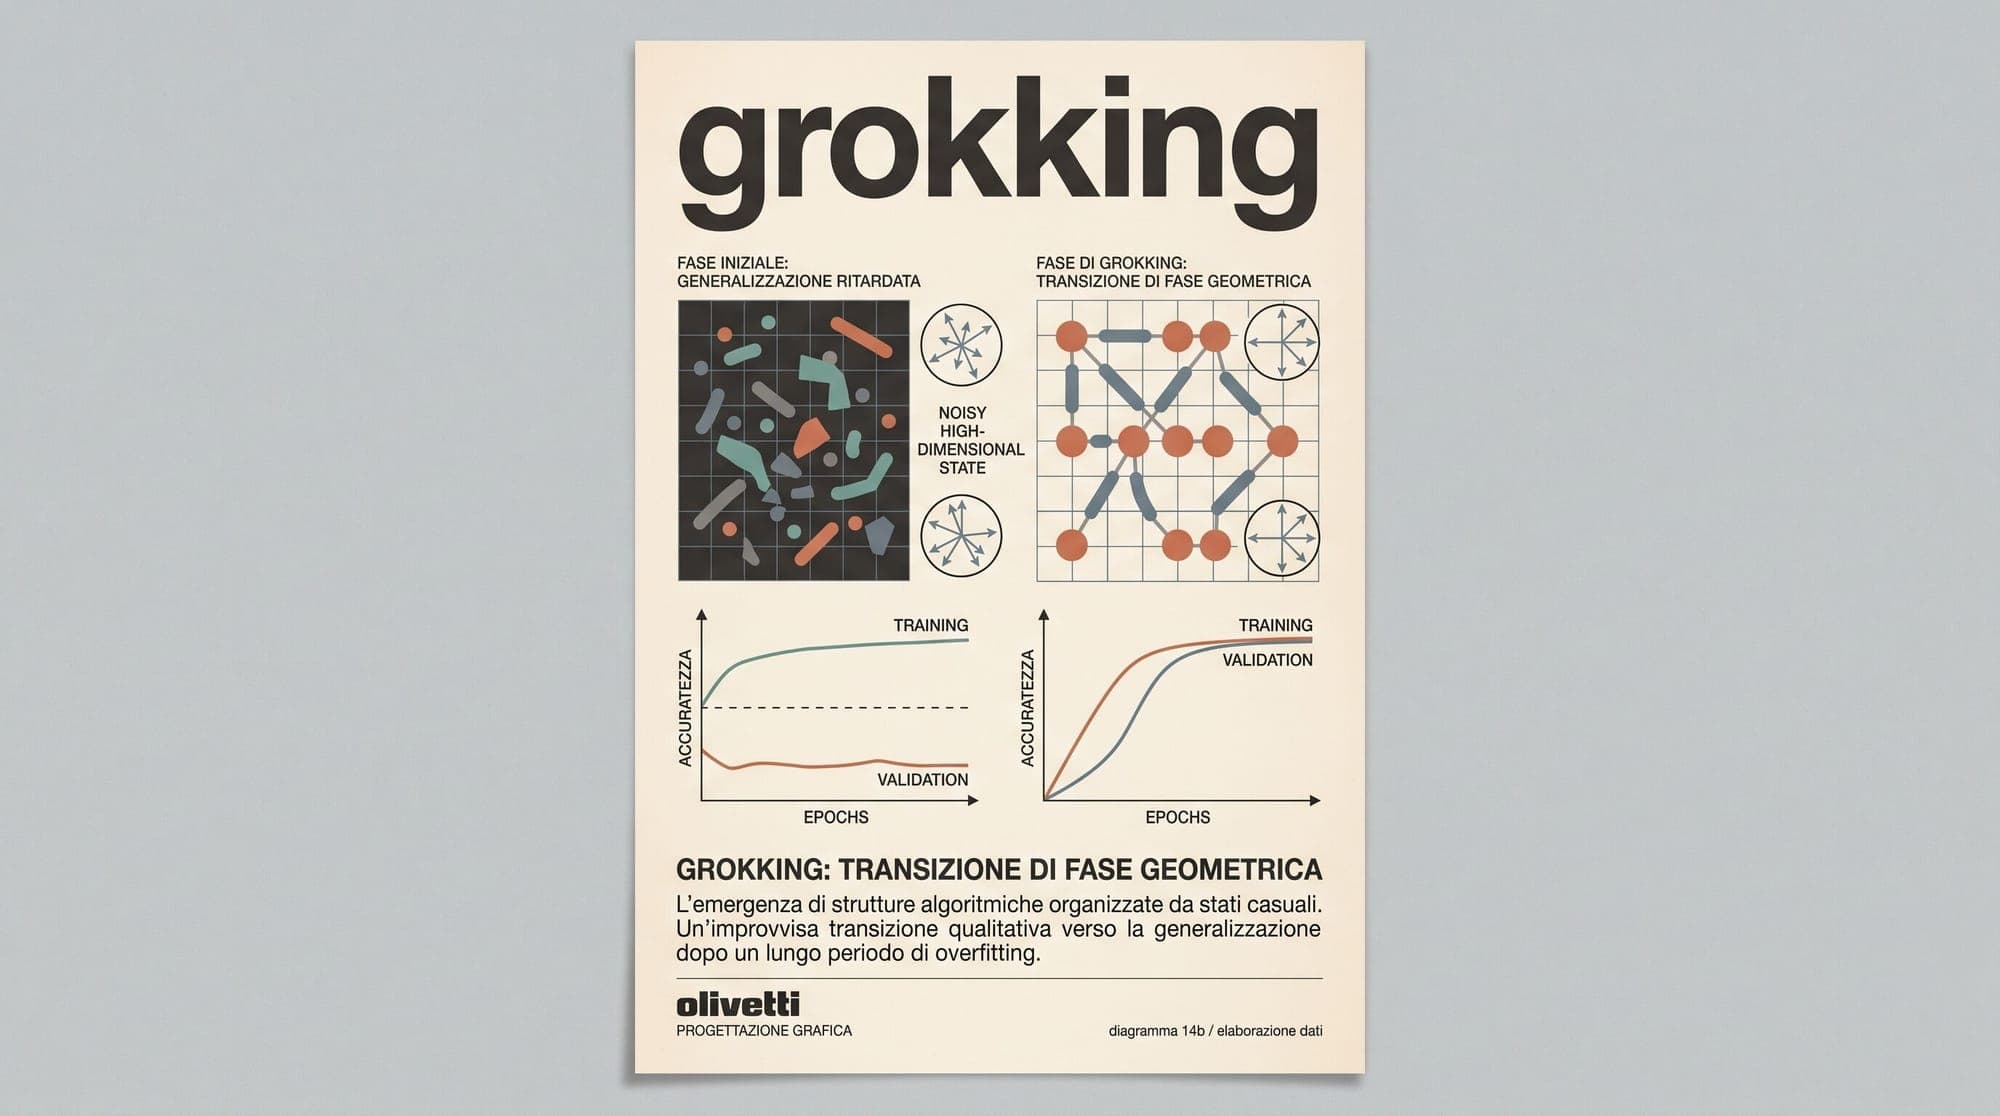
  8. Grokking in Large Language Models: How Weight Decay and Circuit Efficiency Drive Delayed Generalization

    Grokking in Large Language Models: How Weight Decay and Circuit Efficiency Drive Delayed Generalization In standard machine learning paradigms, model generalization closely tracks training loss: as an optimizer minimizes loss on training data, performance on held-out validation data improves in tandem until the model begins to overfit. In 2022, researchers at OpenAI observed a phenomenon that inverted this assumption: small neural networks trained on algorithmic tasks achieved near-zero trainin

    AI
    7 min read
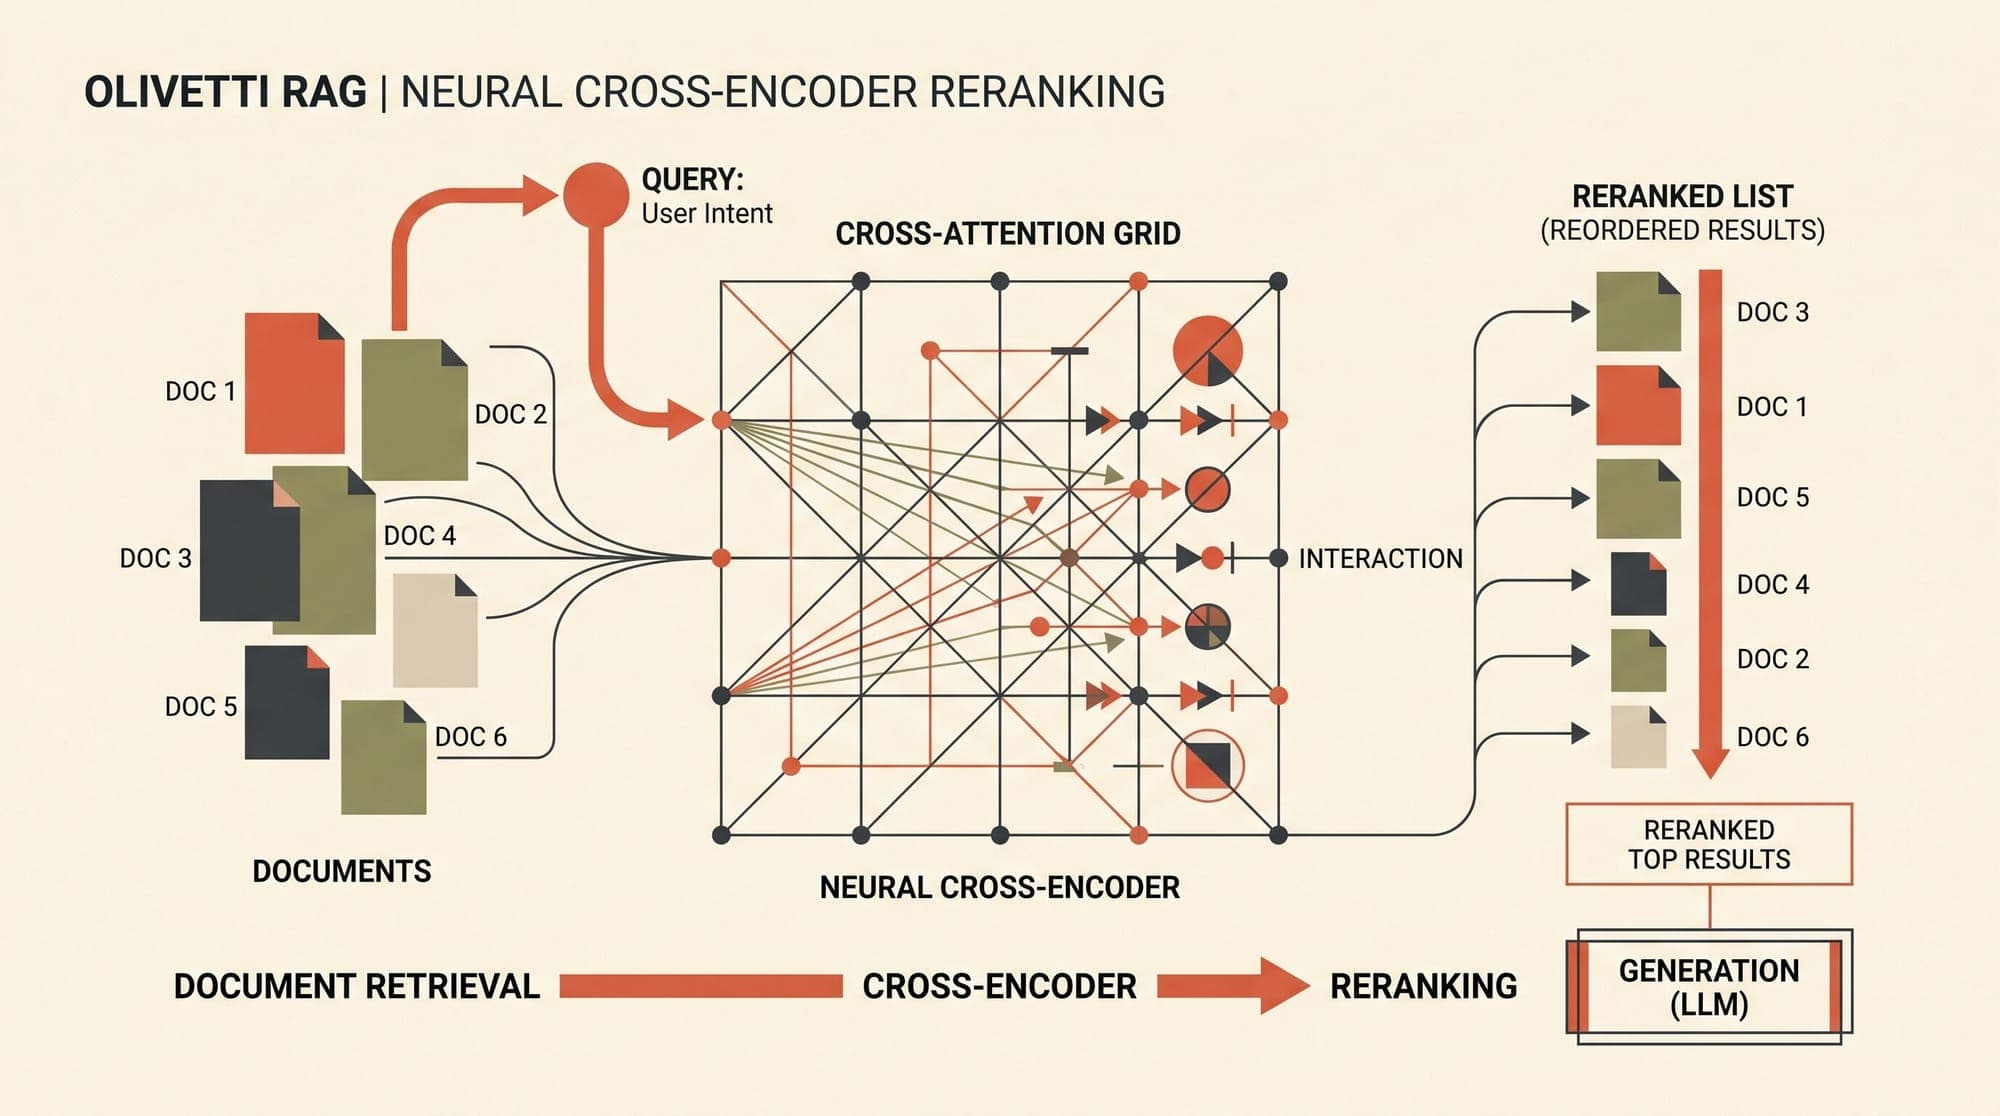
  9. Cross-Encoder Rerankers in Production RAG: Architecture, Score Calibration, Latency Budgets, and Model Trade-Offs

    Retrieval-Augmented Generation (RAG) systems in production frequently suffer from a fundamental precision failure: vector search surfaces the correct chunk somewhere in the top 50 candidates, but fails to place it in the top 3 positions required for high-fidelity LLM synthesis. When irrelevant or tangential chunks lead the context window, generation quality degrades through hallucinations, lost-in-the-middle context neglect, and inflated inference costs. Cross-encoder rerankers serve as the sta

    RAG
    9 min read
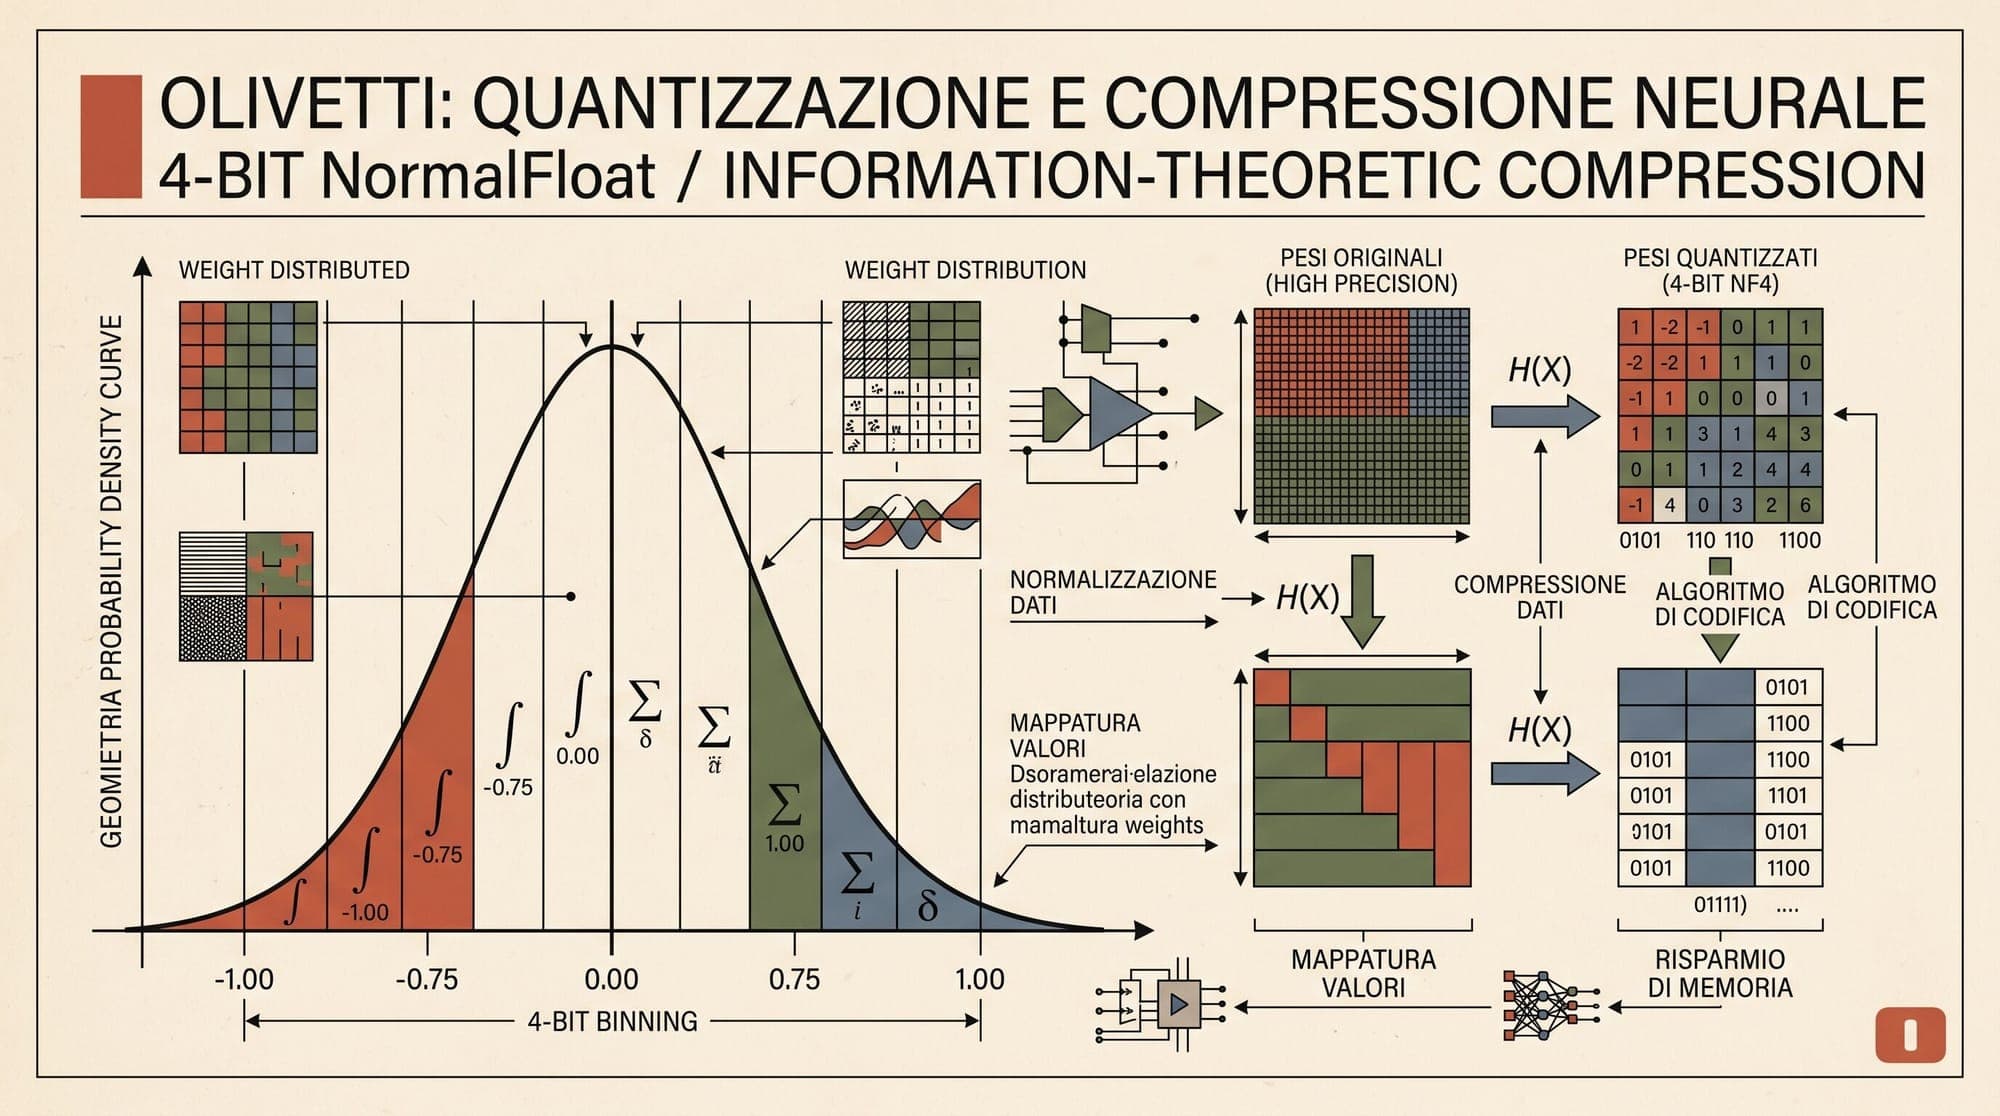
  10. NormalFloat (NF4) and Double Quantization: The Information-Theoretic Foundations of QLoRA

    Fine-tuning large language models under full 16-bit precision is governed by strict memory scaling laws. For a standard 65-billion parameter transformer model, storing weights in 16-bit BrainFloat (BF16) or Float16 (FP16) requires 130 GB of GPU memory. During training with standard first-order adaptive optimizers such as AdamW, each parameter requires an additional 2 bytes for gradients and 8 bytes for FP32 optimizer states (4 bytes for first-moment momentum and 4 bytes for second-moment varianc

    AI
    10 min read
  11. Rank Collapse in Transformer Architectures: Why Pure Attention Decays Doubly Exponentially and How Residuals Restore Expressivity

    Rank Collapse in Transformer Architectures: Why Pure Attention Decays Doubly Exponentially and How Residuals Restore Expressivity The foundational premise of the Transformer architecture is that self-attention acts as a dynamic routing engine, computing pairwise affinities across sequence positions to contextualize representations. However, theoretical analysis reveals an underlying instability: stripped of its auxiliary components, a pure self-attention network rapidly destroys its own express

    AI
    8 min read
  12. Stealth Model 'Ox Alpha' Surfaces with 1M Multimodal Context and 100 Trillion Daily Token Allocation

    An anonymous frontier model named "Ox Alpha" has launched across OpenRouter and the OpenCode developer environment, offering free access backed by a reported 100 trillion tokens per day in serving capacity. The model features a 1,048,576-token context window with native multimodal support spanning text, image, and video inputs. The unannounced release follows a pattern of stealth evaluations across AI model aggregators, where frontier labs deploy pre-release checkpoints to collect blind compara

    LLM
    2 min read
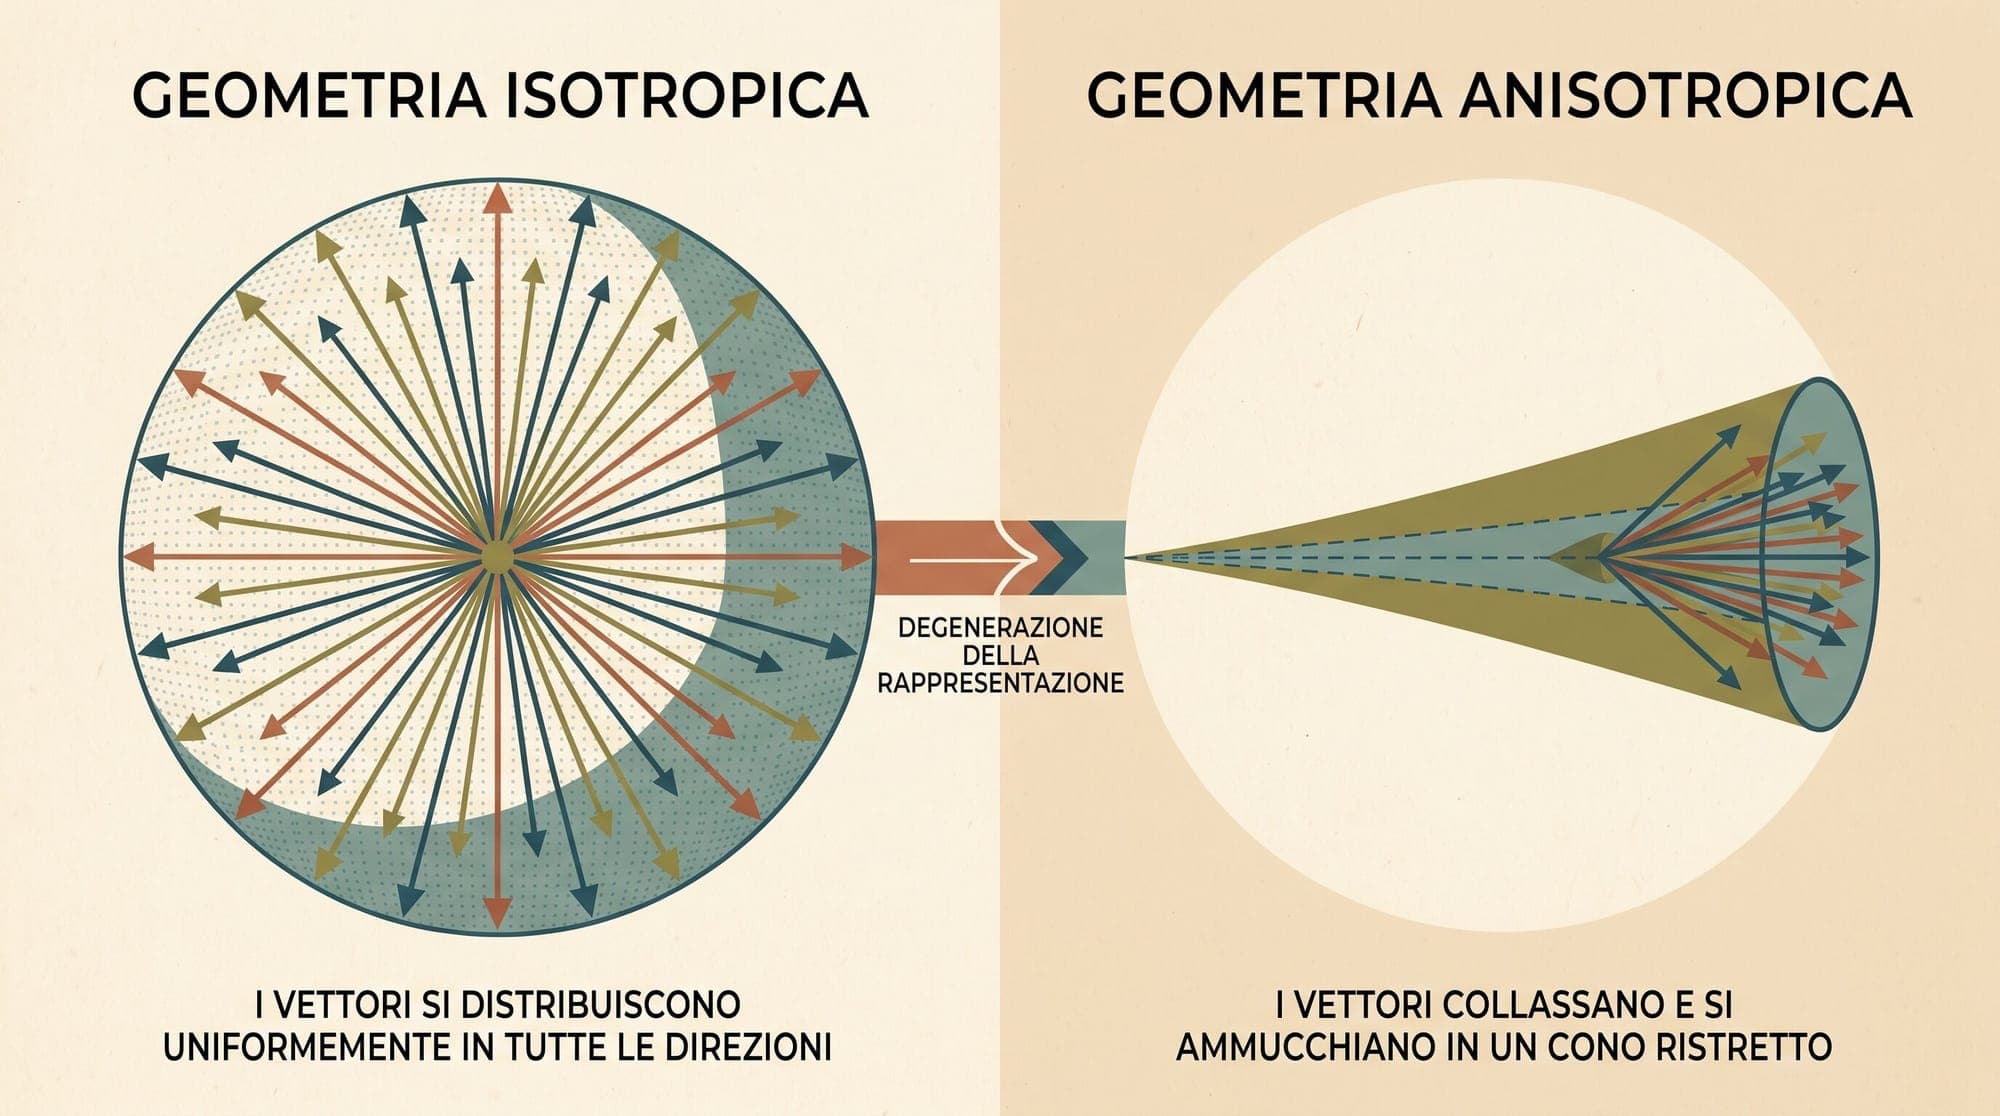
  13. Representation Degeneration and Anisotropy in Large Language Models: Why Embeddings Collapse into Narrow Cones

    In neural language modeling, high-dimensional vector spaces are expected to distribute token and sequence representations uniformly across their ambient dimensions. A space that utilizes all available geometric directions provides maximal representational capacity, allowing subtle semantic and syntactic differences between tokens to be resolved cleanly. Empirical analysis across architectures from BERT and GPT-2 to modern frontier foundation models reveals the opposite behavior: learned token a

    AI
    9 min read
  14. Circuit Breakers and Graceful Degradation in Production AI Systems: Architecture, Failure State Machines, Fallback Cascades, and Dead-Letter Queues

    Circuit Breakers and Graceful Degradation in Production AI Systems: Architecture, Failure State Machines, Fallback Cascades, and Dead-Letter Queues Running LLM inference and multi-agent workflows in production introduces failure dynamics distinct from traditional microservice architectures. While standard REST APIs typically fail with deterministic status codes and predictable latency profiles, generative AI applications face multi-dimensional failure vectors: provider outages, regional rate li

    AI
    7 min read
  15. Superposition and Polysemanticity in Neural Networks: How High-Dimensional Geometry and Sparsity Allow LLMs to Store More Features Than Dimensions

    Superposition and Polysemanticity in Neural Networks: How High-Dimensional Geometry and Sparsity Allow LLMs to Store More Features Than Dimensions In neural network interpretability, one of the most persistent puzzles has been the phenomenon of polysemantic neurons: individual neurons in large language models that activate for seemingly unrelated concepts. A single hidden unit in an MLP layer might fire in response to Python syntax errors, academic citations, and geographic place names. For ye

    AI
    7 min read
  16. Embedding Model Migration in Production: Dual-Indexing, Vector Adapters, and Zero-Downtime Re-Indexing Architectures

    Upgrading embedding models in production retrieval-augmented generation (RAG) and semantic search platforms is often mischaracterized as a routine model bump. When engineering teams replace a legacy embedding model such as OpenAI text-embedding-ada-002 or BAAI bge-large with a modern successor like text-embedding-3-large or Cohere embed-v3, the underlying mathematical coordinate space changes entirely. Because dense vectors generated by distinct neural networks live on incompatible manifolds, v

    AI
    6 min read
  17. Perplexity and Bits-Per-Byte in Large Language Models: Mathematical Foundations, Tokenizer Dependency, and Compression Benchmarks

    Perplexity and Bits-Per-Byte in Large Language Models: Mathematical Foundations, Tokenizer Dependency, and Compression Benchmarks Evaluating autoregressive large language models requires metrics that quantify predictive confidence across text sequences. The standard objective during pre-training is the minimization of empirical risk under a cross-entropy loss function. Exponentiating this loss yields Perplexity (PPL), a foundational metric dating back to statistical speech recognition and n-gra

    AI
    9 min read
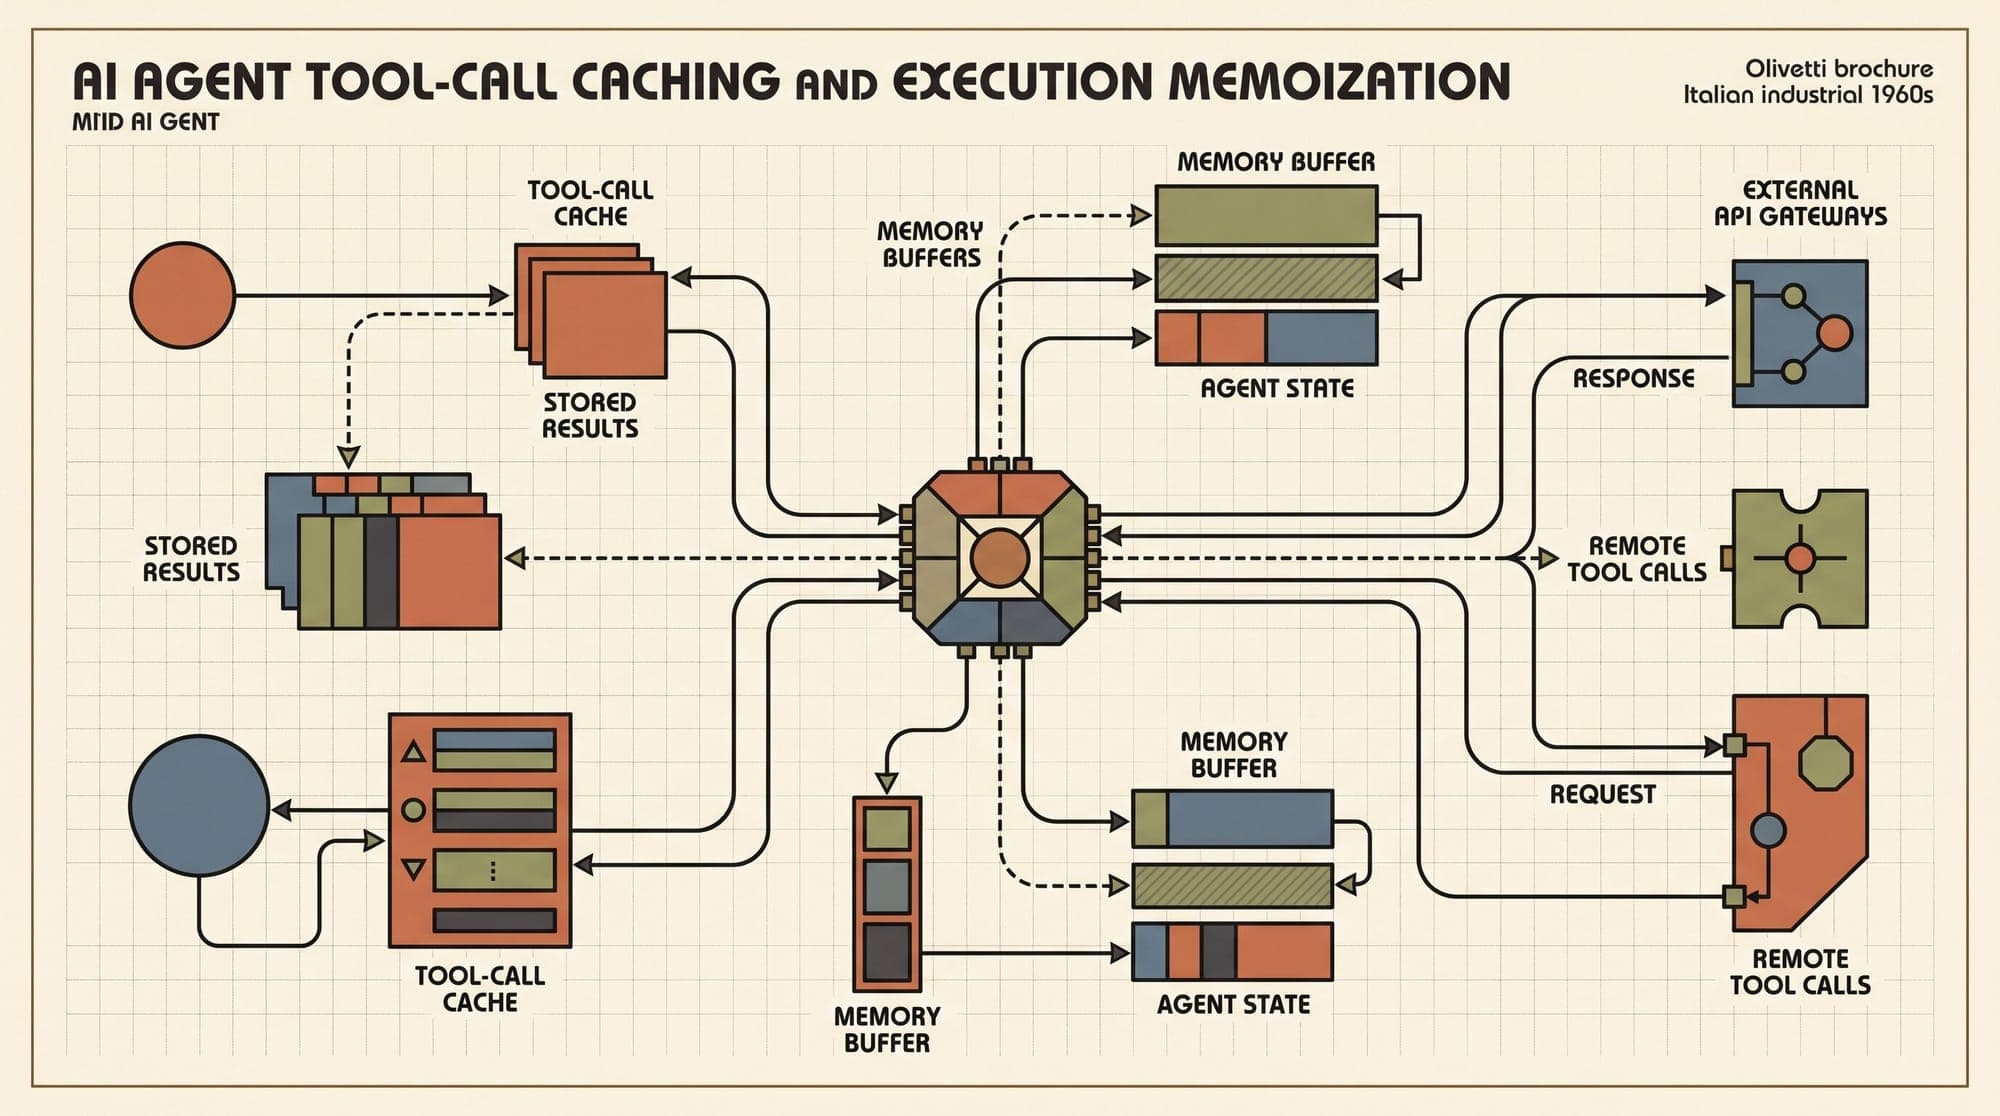
  18. Tool-Call Caching in Production AI Agents: Architecture, State Invalidation, and Latency Economics

    In multi-turn agentic architectures such as ReAct, plan-and-solve swarms, and autonomous coding runtimes, large language models spend significant time waiting on external tool execution. While prompt caching and prefix KV-cache reuse have reduced inference costs for repeated prompt contexts, they do not optimize the downstream execution layer. When an agent queries a database, scrapes a webpage, executes a sandboxed bash command, or retrieves embeddings, external tool latency frequently accounts

    AI
    6 min read
  19. Arithmetic Intensity and the Roofline Model: Why LLM Generation Is Memory-Bound and Prefill Is Compute-Bound

    Arithmetic Intensity and the Roofline Model in Large Language Models: Why Generation Is Memory-Bound and Prefill Is Compute-Bound Every optimization in modern large language model (LLM) serving exists to solve a single hardware reality: running a Transformer model is not one computational problem, but two completely distinct workloads operating on opposite sides of a physical performance barrier. When an LLM processes a prompt during the prefill phase, it saturates modern GPU Tensor Cores, ope

    AI
    9 min read
  20. Agent Memory Engines in Production: Comparing Mem0, Zep, and Letta Architecture, Graph Stores, and Retrieval Latency

    Large language models are inherently stateless functions. Every invocation begins with an empty memory register, relying entirely on the tokens packed into its context window. In production multi-turn applications, naive context management strategies quickly collapse: appending raw conversational logs inflates inference costs and eventually hits hard context limits, while standard semantic vector search (retrieval-augmented generation) lacks temporal awareness, treats contradictions blindly, and

    AI
    7 min read