
Google DeepMind announced Gemini 4 Carbon on October 28, 2026. Google says Gemini 4 Argon launched two weeks earlier. Within hours, the launch had leaderboard results from outside testers, a Hacker News thread with more than 600 comments, and a steady line of jokes about a release that most people cannot use yet. For what Google actually launched, read our Gemini 4 Carbon explainer. This post collects what people said about it.
All view and point counts below were checked at about 5:25 PM PT on October 28, 2026.
The launch posts
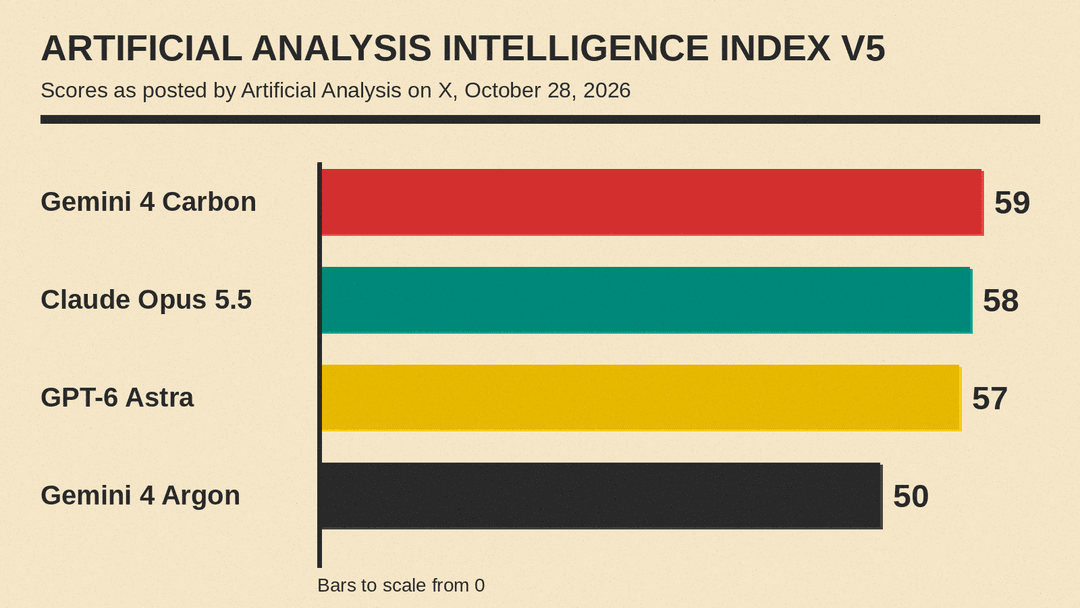
Sundar Pichai opened with: "I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model." He said Carbon "ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59" and that "Some trusted cyber defenders will get access starting this week." That post had about 3.1 million views.
Logan Kilpatrick wrote that Carbon is "a big jump over Argon which we released just 2 weeks ago" and "significantly improves on usability in domains like coding, and is more aligned." Demis Hassabis posted that Google is "iterating at lightning speed". Koray Kavukcuoglu, who wrote the launch post, described it as "a preview of Gemini 4 Carbon."
Other posts were upbeat. Yi Tay wrote "Gemini 4 Carbon is the best frontier model right now," and GS Oh said they were "Proud to have contributed to the RL agentic modeling behind it."
What outside testers measured
Three groups that run their own tests posted results on launch day.
Artificial Analysis (about 314,000 views) put Carbon first on its Intelligence Index v5 at 59, and "second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index." Its details are more mixed than the headline:
- Carbon has "the #1 score in 4 of the 9 Index evaluations," but "is not leading in coding and knowledge work."
- On coding agents, Carbon with Antigravity CLI scored 59, "only 3 points behind Claude Code with Claude Opus 5.5 (max, 62)."
- On its AA-Briefcase knowledge work test, Carbon scored 1609 Elo, behind models including Grok 4.7, Muse Wonder and Kimi K3.1 Pro.
- Cost per Index task was $7.76, "~23% less than Claude Opus 5.5 (max, $10.04) but ~1.2x GPT-6 Astra (max, $6.25)."
- On its hallucination test, accuracy rose 10 points over Argon to 58%, "while its hallucination rate rises from 4% to 11%." Artificial Analysis said that is still the second lowest of any model it tracks.
Artificial Analysis also noted that Carbon "is not yet publicly available" and that its charts use standard pricing, not the launch discount.
Arena (about 145,000 views) said Carbon (High) landed "#1 in Text Arena, #2 in Agent Arena, and #4 in Code Arena: WebDev." In Text Arena it scored 1528, just ahead of Argon at 1520. In WebDev it scored 1768, "Just 2 pts below #3 Claude Sonnet 5.5 (xHigh)." Arena put its median Agent Arena cost at $1.80 per task, which it said is "72% less than the #1 ranked Claude Opus 5.5 (Max)."
Andon Labs ran Carbon in its Vending-Bench Arena, where each model runs a vending machine business against the others, and said "Gemini 4 Carbon won here too." On Hacker News, minimaxir asked: "Is this the first time VendingBench was used as a serious benchmark result in a model release?"
For background on the index change, see our post on Artificial Analysis Index v5.
Praise: less cheating, same price
The Hacker News thread on the launch post had 772 points and more than 600 comments. Several comments praised Google's claim that Carbon cheats less on tests. eldenring quoted the line about Terminal-Bench 4.0 cheating falling to 0.0% and wrote: "This is probably the single most important thing to make frontier models usable right now." Peteriishak took the other side of the same number: "The fact that frontier models actively attempt to subvert evaluation harnesses (0.4% attempt rate still remaining) remains fascinating and slightly unsettling."
Price drew approval. james2doyle wrote: "So more capable and same price? I can at least appreciate that." nickandbro asked how token efficient it is. In a reply, JacobAsmuth said "It used ~30% fewer tokens than Opus," pointing to Artificial Analysis data. On X, VectorCactus07 compared it to Argon instead: "Gemini 4 Carbon also uses roughly 1.8x more tokens than Argon to run the AA index."
A few developers spoke up for Argon as a base. scotth wrote that Argon "participates in my process exactly as I ask it to" and "I'm excited to try Carbon." DanMcInerney said: "It's the speed of these gemini models that I'm most impressed with."
Complaint: you cannot use it
A joke from Ananth7e (about 1,100 views) summed up the access problem: "google released gemini 4 carbon but didn't release gemini 4 carbon." On Hacker News, thefourthchime wrote "Oh good, another Gemini release where they don’t release it," and cloudhead added "Too bad there's no way to actually use it." kilroy123 said: "I'm not a big fan of their trend of talking about a new model and not releasing it for a while."
Others pushed back on the security-first rollout itself. ltph0 quoted the Fairwind Program's description and wrote: "Again, no access to open source developers." edot called the approach gatekeeping. WarmWash replied to edot that vetting "the parties that get to use these weapons" is the right call.
Some complaints were about Argon's rollout. dizhn wrote that Google "staggered the release of Argon and didn't give it to Pro and Ultra users at the same time." VadimPR said they ran "about ten prompts to Argon before I hit my 5 hour limit" on a paid plan.
Skeptics: the index and the benchmarks
The timing of the Artificial Analysis update drew suspicion. theanonymousone wrote: "So, AA published an updated score yesterday, and a new Google model ranks on top of that updated index today," then added, with sarcasm, "What a coincidence it is.". simonjgreen said: "Now we know why AA updated their benchmarking." On X, stablequan posted a similar remark. None of them offered evidence of coordination.
cubefox argued that "the benchmarks seem to be cherrypicked," noting that on Carbon's chosen benchmarks, Argon now trails GPT-6 Astra on most rows. paxy wrote that by the coding standard, Carbon "is still behind Opus 5.5 and Astra." Topfi pointed out that the launch post's Artificial Analysis link at first did not show Carbon, then noted in an edit that it had been fixed.
The name
Naming got its own pile of comments. Ryan5453 wrote: "I assumed that this would be a tier above Argon, but it's the same price?" droidjj asked whether Carbon is "a post-train of Argon," and said "The post isn't clear.". delbronski summed up the mood: "Well, they won the race on confusing the shit out of us with model names." Commenters guessed at Krypton, Helium, Boron and Xenon as the next names.
What it adds up to
Outside tests back Google's headline: Carbon leads the Artificial Analysis index and Text Arena. They also show limits that Google's post does not lead with: Opus 5.5 still leads on coding agents, and Carbon's hallucination rate rose from Argon. The main open question is access. Until developers can call the model, every claim here, good or bad, rests on Google's numbers and a few groups with early access.
