MiniCPM-OCR 1.0: OpenBMB's 1.3B Open OCR Model
OpenBMB's Apache 2.0 MiniCPM-OCR 1.0 reads scans, tables and formulas at 1.2 pages per second on one GPU, and a 2B Jev model scores OCR output for review.
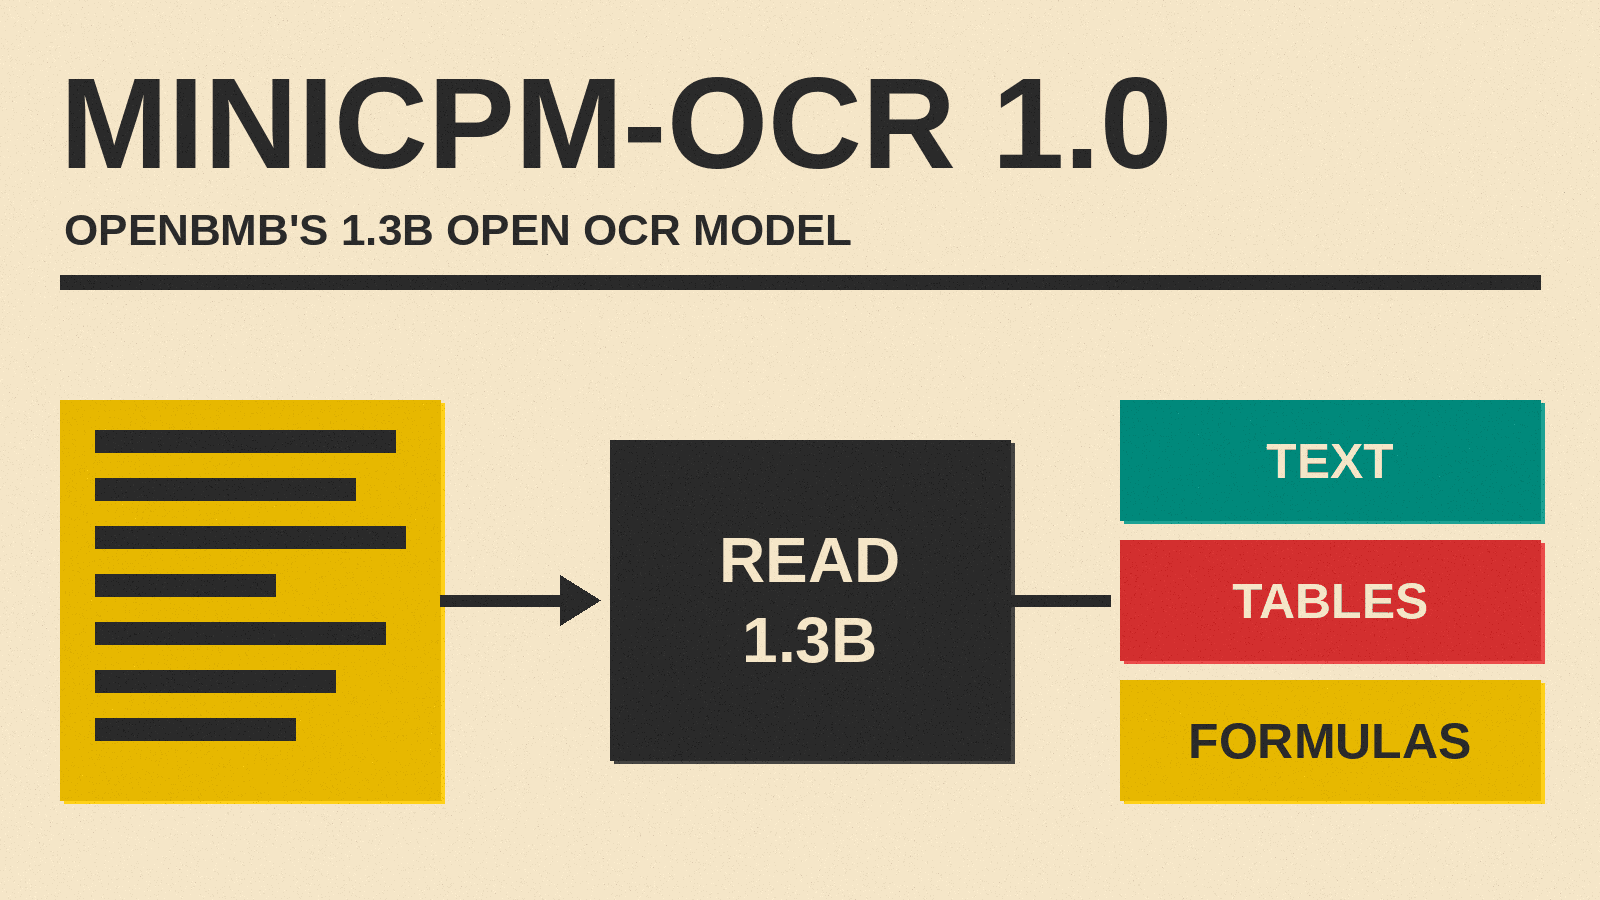
OpenBMB's Apache 2.0 MiniCPM-OCR 1.0 reads scans, tables and formulas at 1.2 pages per second on one GPU, and a 2B Jev model scores OCR output for review.
Canva Brush, released October 29, 2026, is a vision-language model that edits Canva designs from a prompt. How it works, Canva's claims and how to try it.
Multimodal AI works with text, images, audio and video. How CLIP, LLaVA, Chameleon and GPT-4o are built, the three main designs, and where they still fail.
Baidu released Unlimited OCR 2 under the MIT license. The 3B mixture-of-experts model uses a new sparse attention to keep memory flat as documents grow. What it does, Baidu's own benchmark numbers against Qwen, Gemini and Kimi, and the limits Baidu admits.
OpenBMB's MiniCPM-V 4.7 is an Apache 2.0 vision model in 35B-A3B and 1B sizes. A new expert-scheduling method streams MoE weights from flash, and OpenBMB reports up to 20.51 tokens per second on an iPhone. Here is how it works, how it scores, and how to run it.
Cohere Parse is a 2.3B vision language model that turns enterprise documents into Markdown for RAG, at $1.50 per 1,000 pages. Specs, scores, costs and limits.
Liquid AI has released LFM2.5-VL-3B, a roughly three billion parameter vision-language model designed to run on phones, laptops, and other edge hardware instead of in a data center. The model pairs the LFM2.5-2.6B text backbone with a SigLIP2 NaFlex image encoder. Unlike many recent models, it does not reason step by step. It answers directly, which keeps latency low for real-time and on-device use, and it handles a 32,000 token context. What it is built to do Liquid says the release adds fo
Liquid AI has released LFM2-VL-3B, a 3 billion parameter vision-language model designed to run on edge hardware rather than in a data center. It is the largest model in the company’s LFM2-VL family, which previously topped out at 1.6B parameters, and is available now under the LFM Open License on Hugging Face and through Liquid AI’s LEAP platform. The model pairs Liquid AI’s densest text backbone, LFM2-2.6B, with a SigLIP2 400M NaFlex vision encoder. That combination lets it take in images at t