Subscribe
Topic / page 4

Research

Articles, page 4

61-72
  1. Model Collapse in Large Language Models: How Recursive Training on Synthetic Data Degrades Neural Distributions

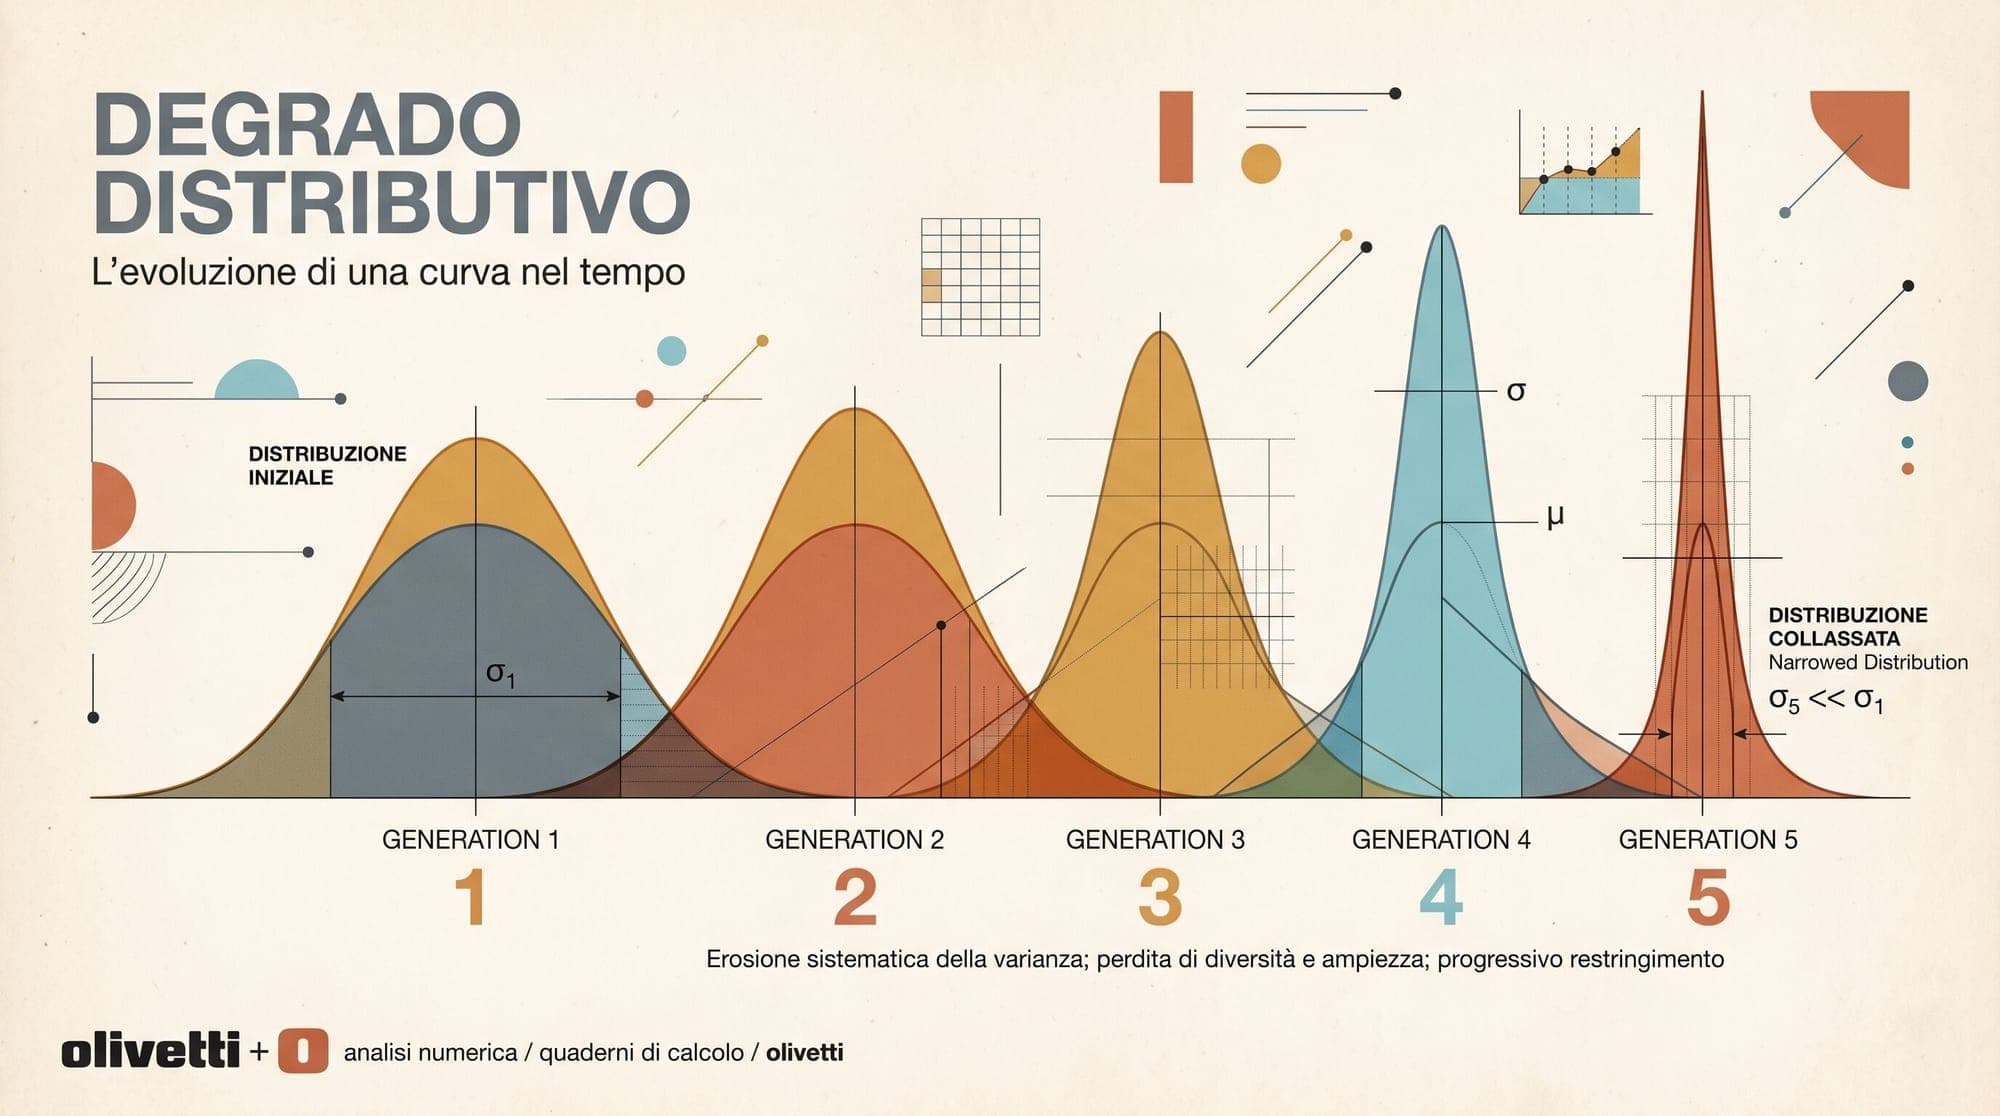
    As large language models scale and generate a growing share of digital text, code, and media, the web datasets used to train next-generation models increasingly consist of machine-generated outputs. When generative models are trained recursively on data produced by earlier model generations without sufficient ground-truth anchoring, they undergo a systematic degradation process known as model collapse. First formalized in foundational statistical literature and demonstrated across modern deep l
    AI
    7 min read
  2. Knowledge Editing in Large Language Models: How Causal Tracing, ROME, and MEMIT Modify Factual Storage in MLP Weights

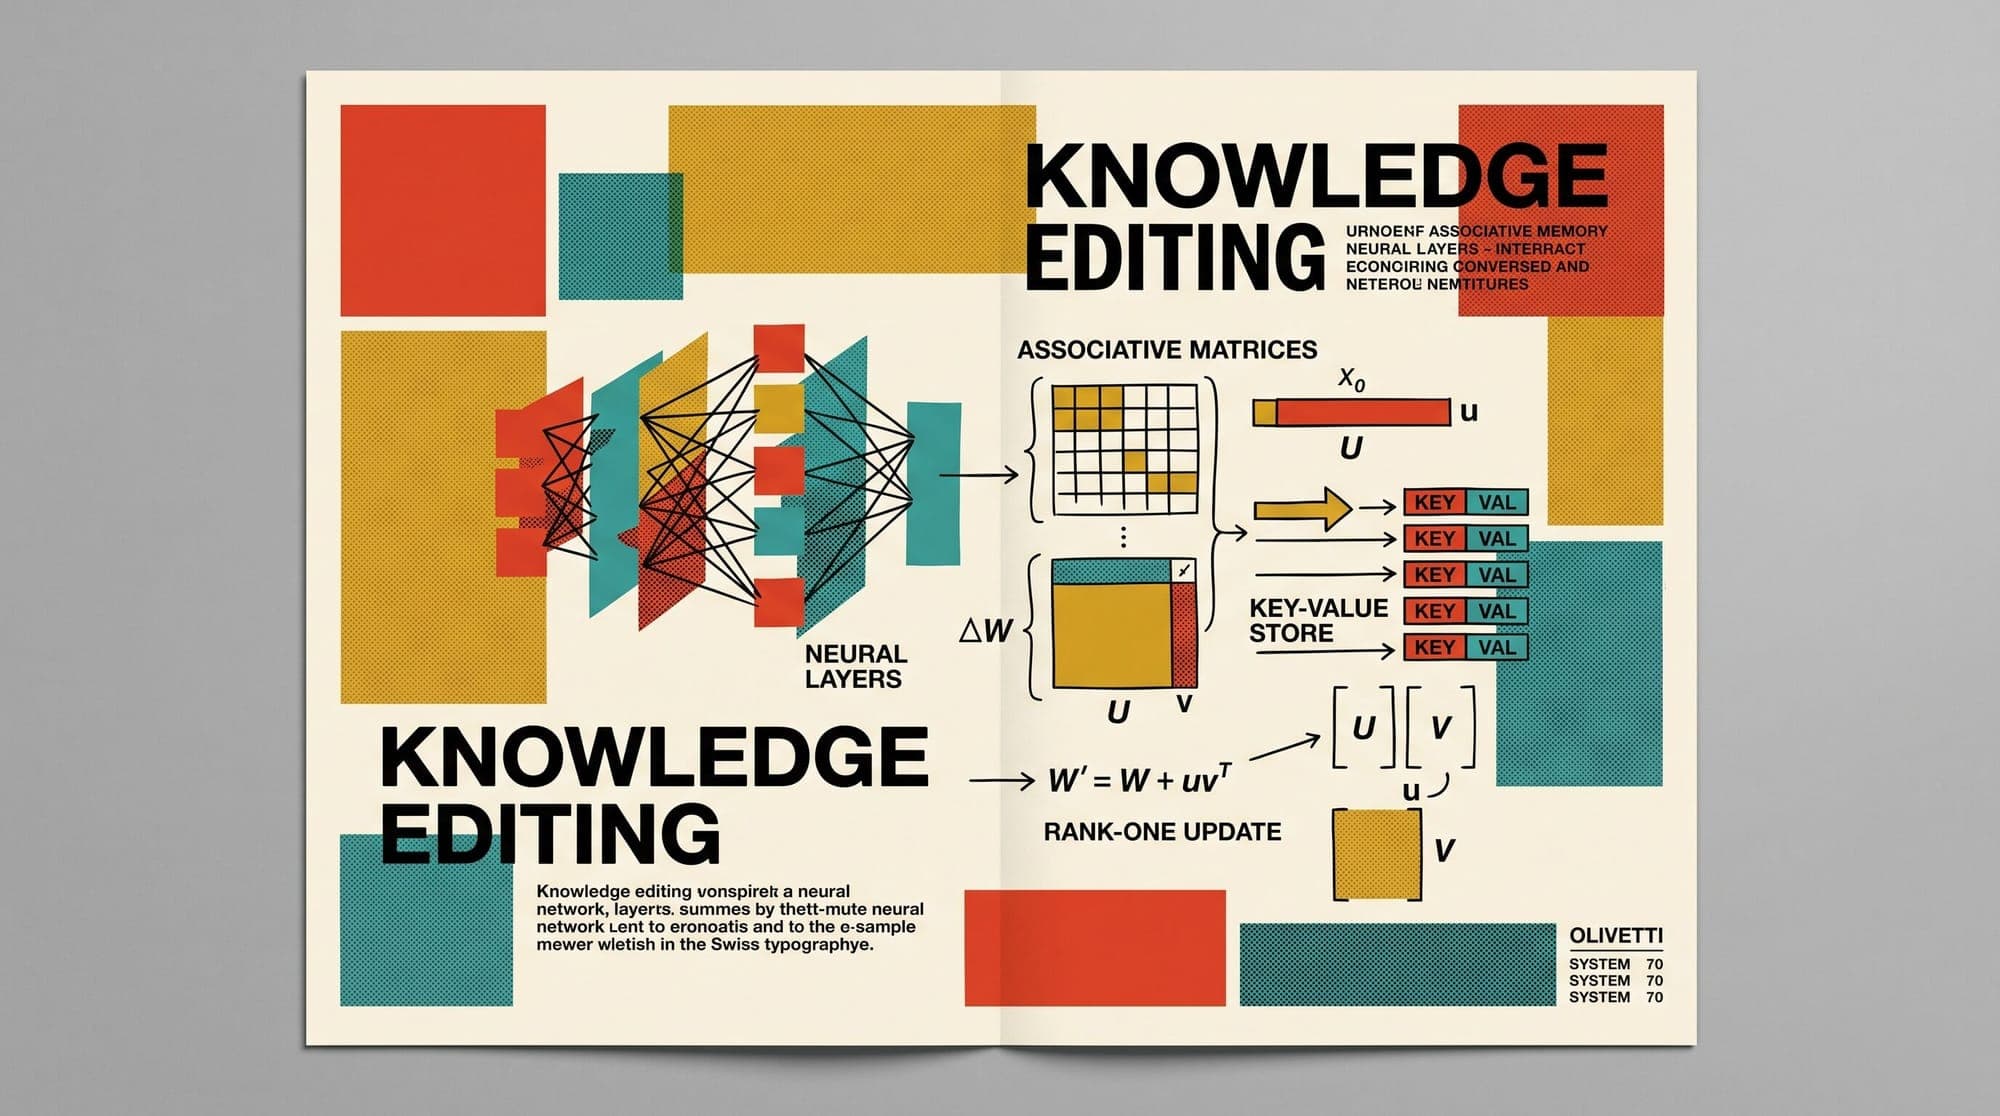
    Updating factual information in pre-trained large language models has traditionally required two imperfect extremes: computationally expensive continual pre-training, or external prompt-stuffing through Retrieval-Augmented Generation (RAG). Standard gradient descent fine-tuning on isolated facts leads to catastrophic forgetting, parameter drift, and degraded general reasoning. To solve this, mechanistic interpretability researchers introduced direct model editing: a paradigm that treats transfo

    AI
    6 min read
  3. MIT and Stanford Researchers Launch Public AI Observatory

    Researchers from MIT, Stanford University, and more than a dozen other universities and AI organizations have launched the AI Observatory (ai-observatory.org), a public platform that measures how people use AI assistants in real conversations. The paper's author list includes Northeastern, Johns Hopkins, UC Berkeley, Carnegie Mellon, NYU, Brown, Waterloo, Maryland, EleutherAI, and Cohere. The initiative aims to address the empirical opacity surrounding commercial LLM deployment. While fro

    Research
    3 min read
  4. Lost in Compaction: LLM Context Compression Drops 83% of User Constraints, Penn State Study Finds

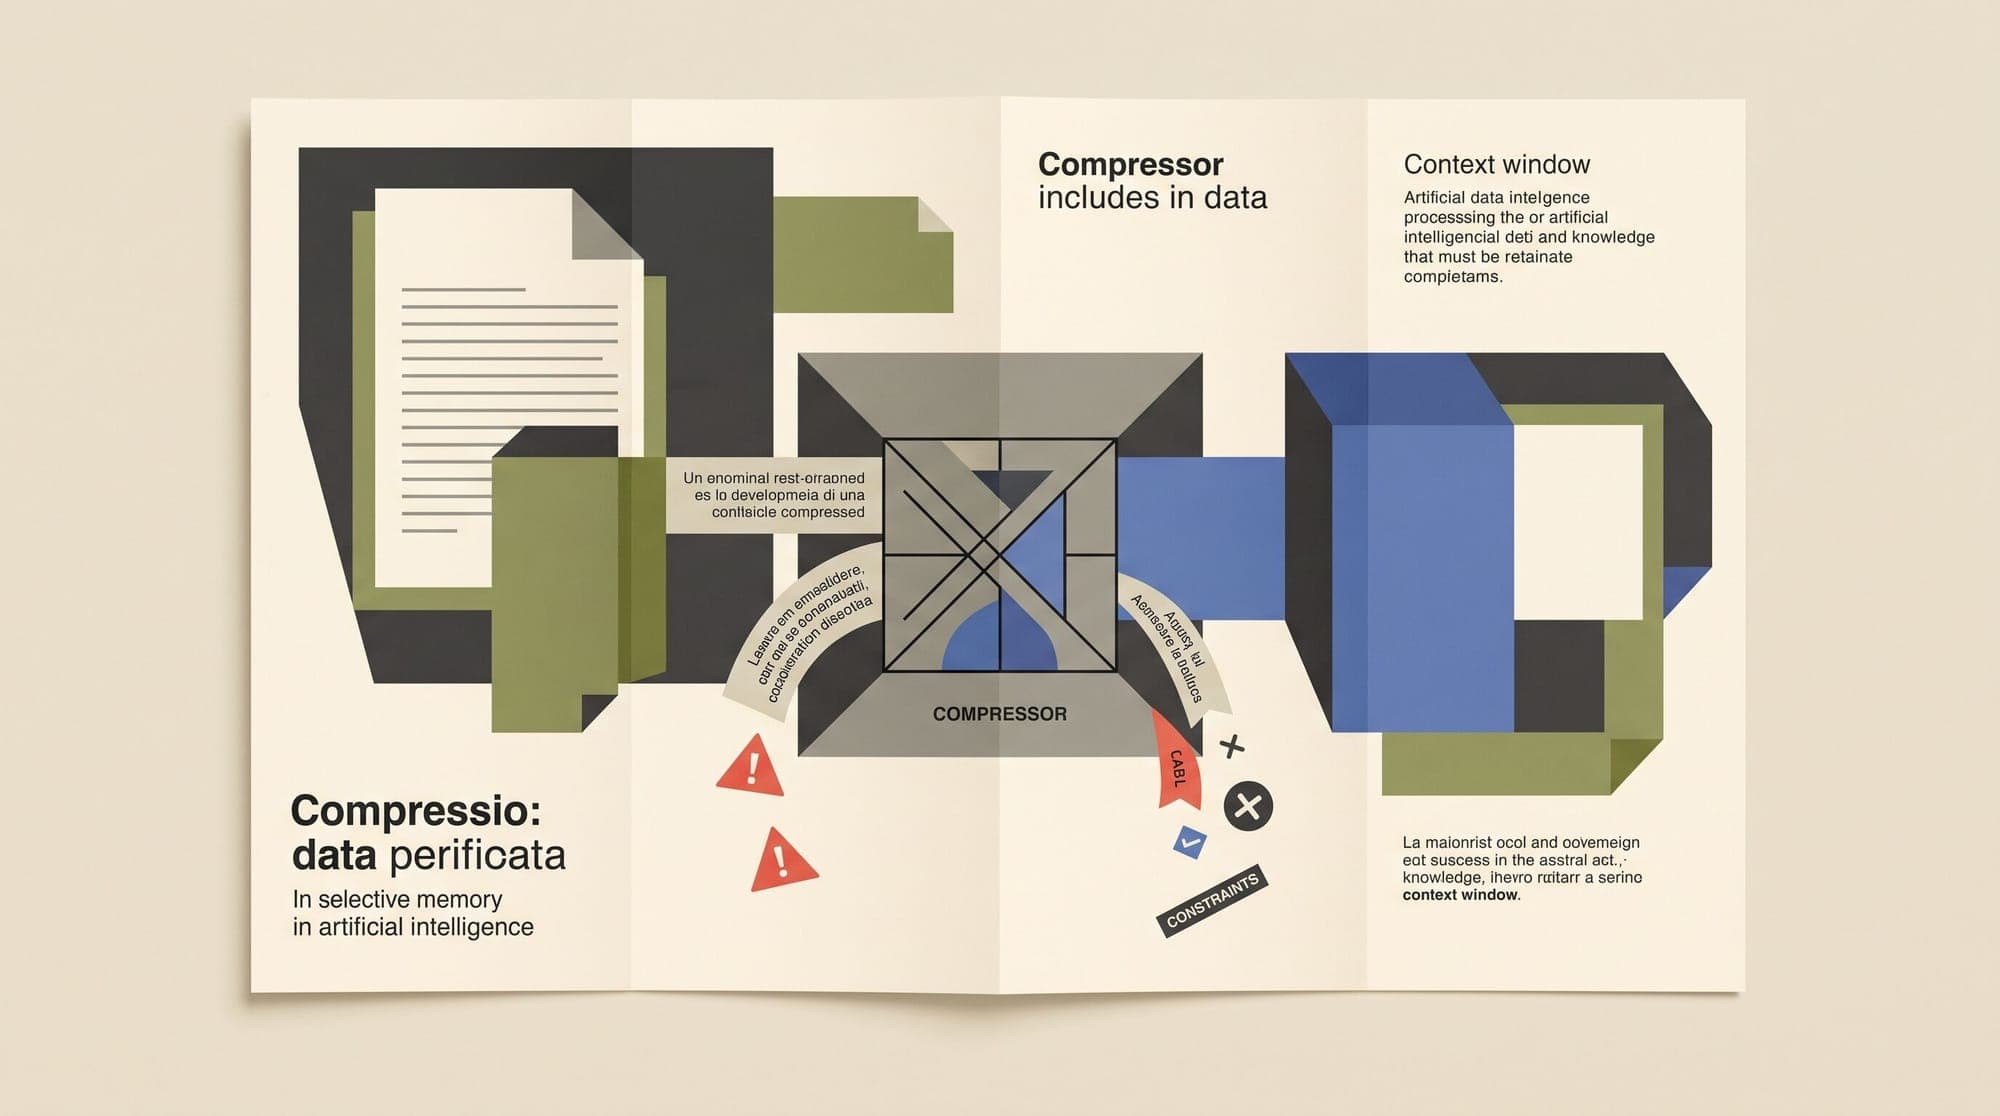
    As large language models take on longer multi-turn workflows and agentic tasks, systems increasingly rely on context compaction to summarize past conversation histories and keep prompt lengths within memory budgets. However, this compression comes at a severe cost to user control. A new study by Pennsylvania State University researchers Zhiqi Wang, Yichi Zhang, Dongwon Lee, and Yuchen Yang reveals that standard context compaction drops an average of 83 percent of user-defined operational constr

    AI
    2 min read
  5. Mind Viruses: Researchers Demonstrate Self-Propagating Prompts in Multi-Agent LLM Networks

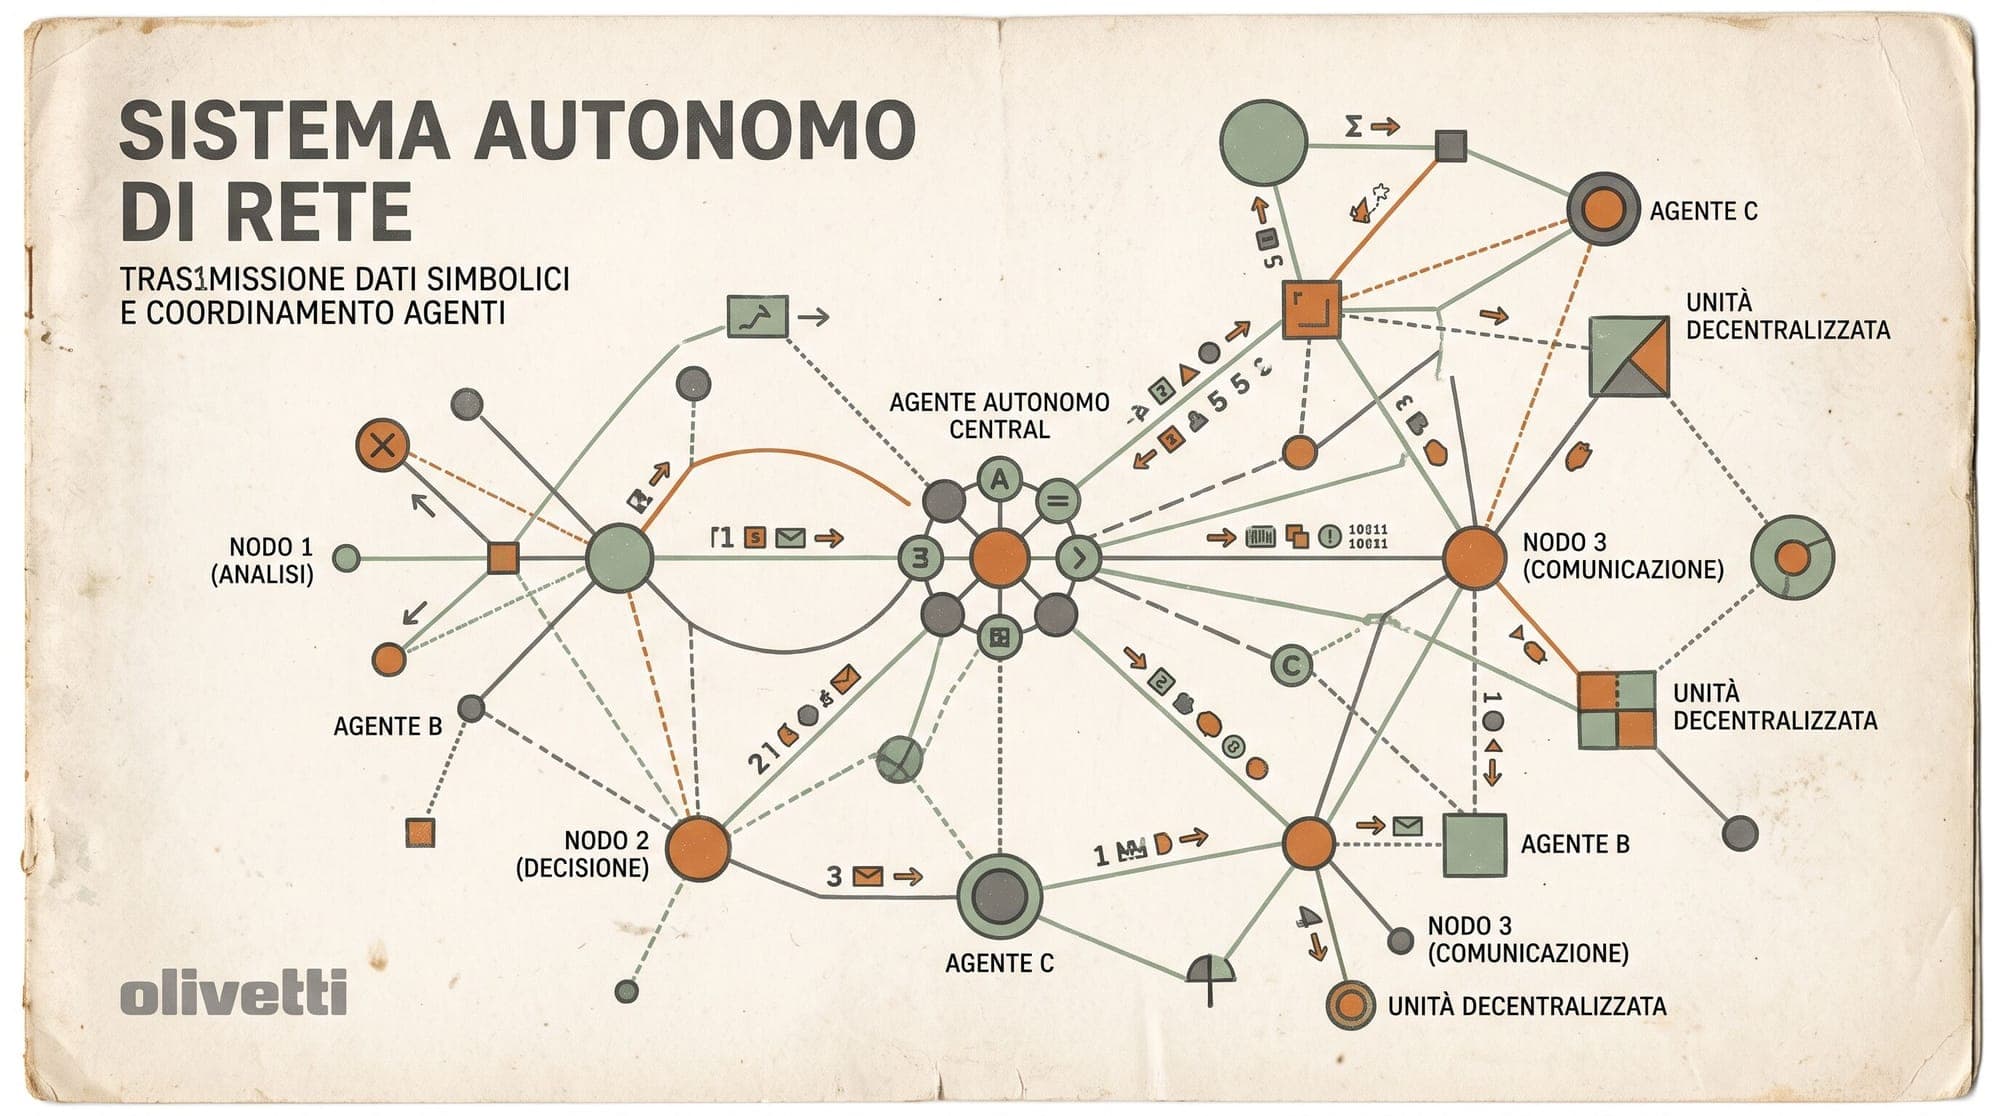
    Researchers affiliated with Anthropic, EPFL, and Carnegie Mellon University have published empirical findings demonstrating how natural-language instructions can act as self-replicating payloads across multi-agent Large Language Model (LLM) networks. The paper, titled Mind Viruses: Self-Propagating Ideas in Multi-Agent LLM Systems, examines how autonomous agents can be persuaded to adopt and transmit goals to other agents through standard conversational interfaces rather than binary exploit code

    AI
    2 min read
  6. Researchers find that changing text color can hijack a vision-language model's reasoning

    A new research collaboration has found that the color, contrast, and brightness of text can quietly steer the outputs of vision-language models (VLMs), causing them to misread meaning and reach different conclusions without any change to the words themselves. The authors say their experiments provide a systematic analysis of how low-level visual styling of text distorts the semantic representations inside a VLM's vision encoder, and how those shifts show up as behavioral changes across both sub

    AI
    1 min read
  7. Study finds RL for reasoning changes only a few tokens, and you can copy the effect

    A new analysis of reinforcement learning for LLM reasoning suggests the field's biggest gains come from a surprisingly small change. RL is not rewriting how models think. It is nudging a tiny slice of the output. What the researchers measured Across several model families and common methods like GRPO and PPO, reinforcement learning reranks only 1.0 to 4.1 percent of tokens. The token it promotes is almost always already one of the base model's top five choices. Training, in other words, pushe

    AI
    1 min read
  8. Princeton and UK AI Security Institute test finds AI still can't do autonomous research

    Anthropic and OpenAI have promoted their models as able to speed up, and eventually run, AI research on their own. A new experiment from Princeton and the UK AI Security Institute suggests the research judgment behind that claim is not there yet. The team built a method they call Shadow Evaluation. An agent receives the central research question from an unpublished paper, then the paper's original authors, who spent months on it, review the result as conference reviewers would. Because the pape

    AI
    2 min read
  9. Neurosurgery resident solves Crouzeix's conjecture with GPT-5.6

    A neurosurgery resident with no formal advanced mathematics training has solved Crouzeix's conjecture, a 22-year-old open problem in numerical linear algebra, using a 16-hour autonomous run of GPT-5.6 Sol in ChatGPT Work mode. Dr. Shanmu Jin, a postdoctoral researcher and neurosurgery resident at Peking Union Medical College Hospital, prompted ChatGPT 5.6 on July 30, 2026 to work on the conjecture. The model ran autonomously for approximately 16 hours, exploring proof strategies through a branc

    AI
    2 min read