
A new research collaboration has found that the color, contrast, and brightness of text can quietly steer the outputs of vision-language models (VLMs), causing them to misread meaning and reach different conclusions without any change to the words themselves.
The authors say their experiments provide a systematic analysis of how low-level visual styling of text distorts the semantic representations inside a VLM's vision encoder, and how those shifts show up as behavioral changes across both subjective tasks like sentiment analysis and objective tasks like question answering.
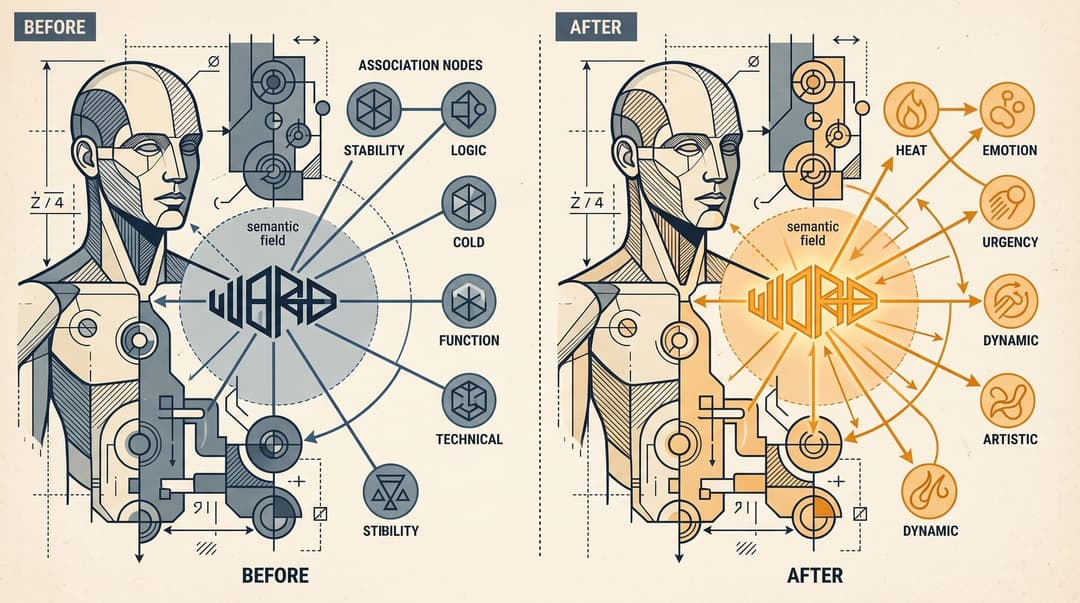
In one illustration from the project, the word bad rendered in green shifts the model's internal representation toward a more positive interpretation, even though the text is unchanged. The effect is analogous to how humans react differently when negative things are colored positively and positive things negatively.
Why it matters
The researchers describe the finding as a critical, previously underexplored vulnerability in VLMs and discuss its implications for the robustness and safety of VLM pipelines. Because many businesses now route search traffic and retrieval through LLMs and vision models, styling-based attack surfaces are increasingly attractive.
The work builds on earlier findings that Western color conventions (red for danger, green for safe) also dominate in Asian vision-language models, suggesting the bias is embedded across model families. The project page provides interactive examples of the effect.
Sources
Changing Font Colors Can Hijack AI Reasoning - Unite.AI, Aug 17, 2026: https://www.unite.ai/changing-font-colors-can-hijack-ai-reasoning/
Color bias in VLMs (project site): https://kohsukeide.github.io/color-bias-vlm/
