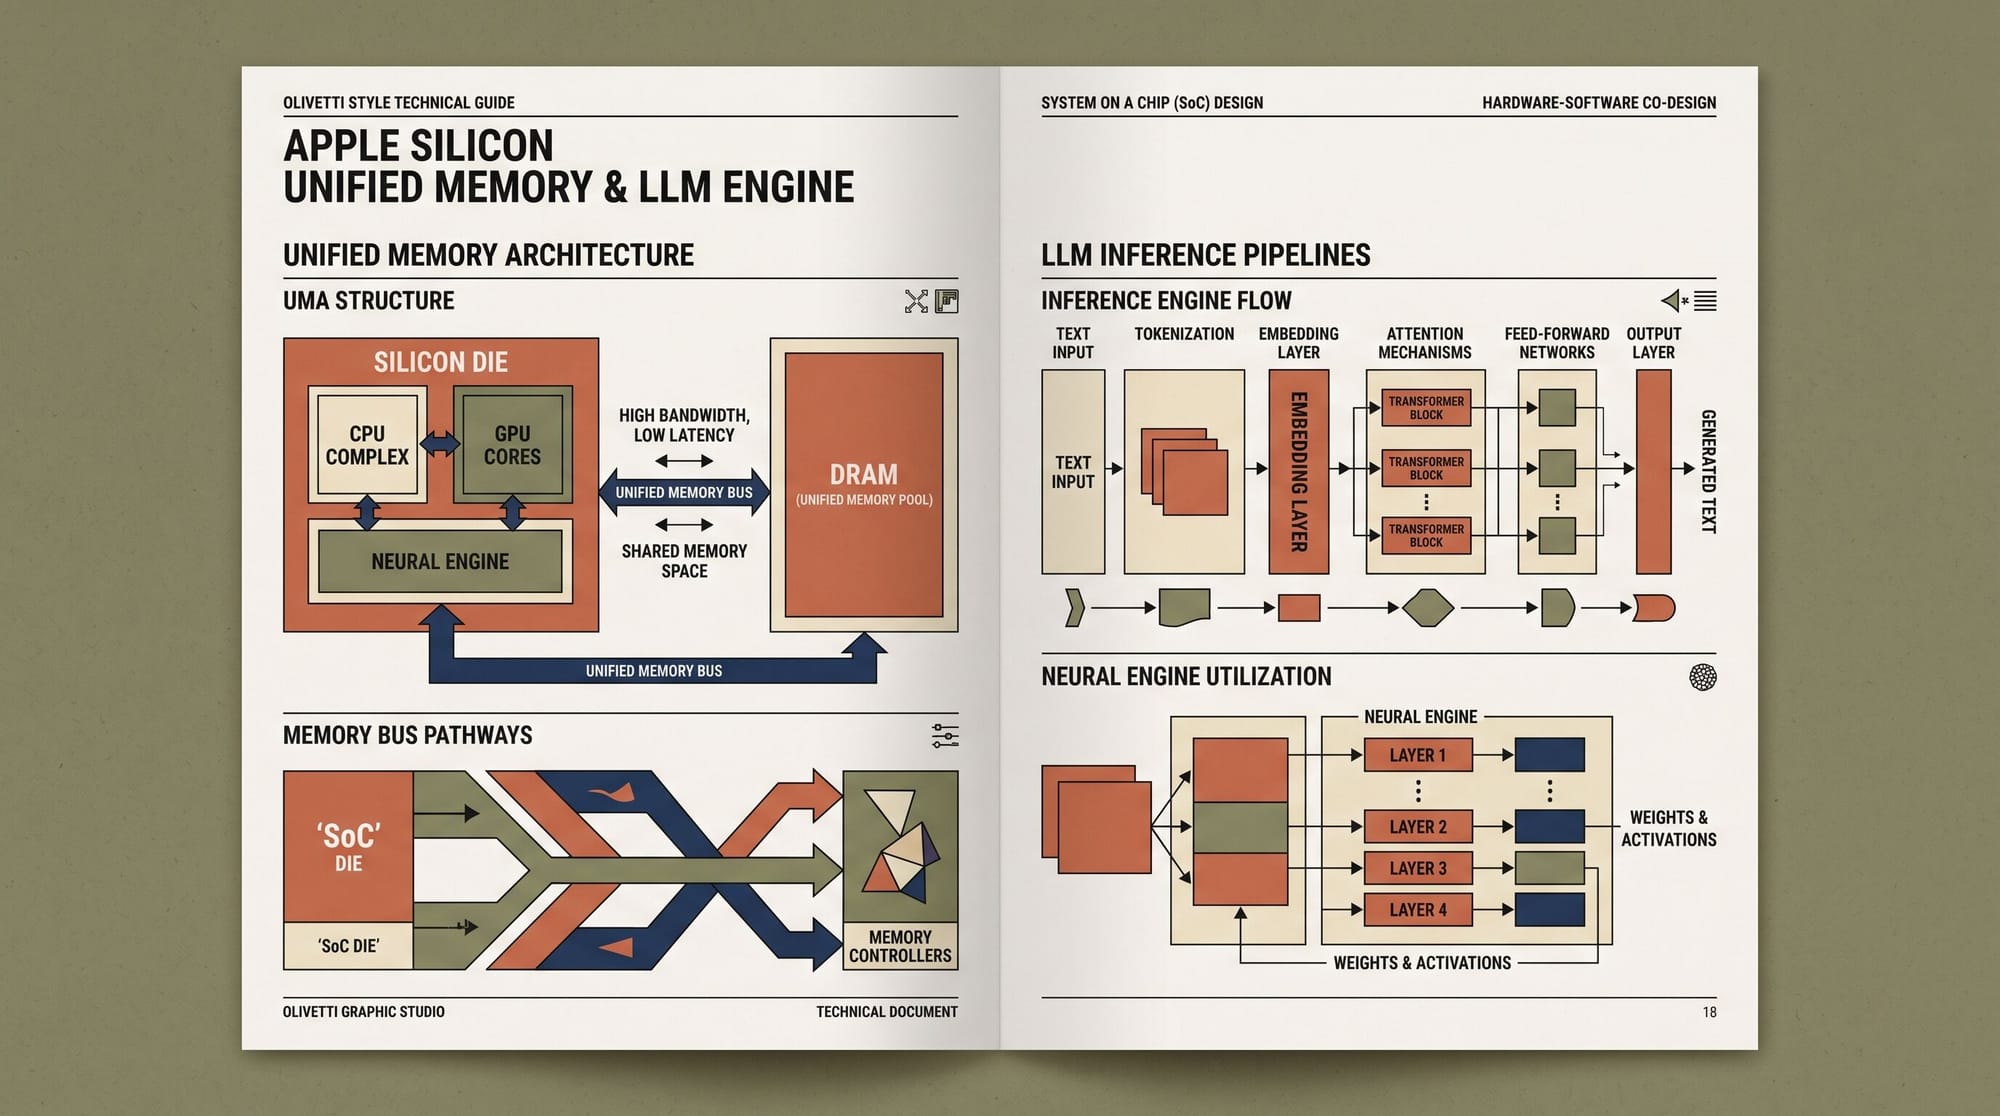
Local LLM Inference on Apple Silicon: Architecture, Unified Memory, and Serving Benchmarks for MLX, llama.cpp, and Ollama
How unified memory and memory bandwidth set local LLM speed on Apple silicon, and how MLX, llama.cpp and Ollama compare in published benchmarks.