
Deep neural networks have long been treated as uninterpretable black boxes. In transformer language models, individual neurons in the residual stream and multilayer perceptron (MLP) layers rarely map to singular, human-understandable concepts. Instead, individual neurons exhibit polysemanticity: a single neuron might fire for Python syntax, medical terminology, and Korean dialogue without an obvious shared semantic foundation.
For the math, see Sparse Autoencoders (SAEs) and Mechanistic Interpretability: Mathematical Foundations.
Mechanistic interpretability research explains this phenomenon through the superposition hypothesis. Because the real world contains vastly more concepts and semantic features than a language model has physical dimensions in its hidden layers, neural networks compress features into non-orthogonal linear combinations across dimensions. Sparse Autoencoders (SAEs) use unsupervised dictionary learning to unpack these superimposed activations, projecting dense representations into high-dimensional, sparse feature spaces where individual components become monosemantic.
The Superposition Hypothesis and Polysemanticity
The linear representation hypothesis posits that neural networks represent semantic concepts as linear directions in activation space. However, as formalized by Elhage et al. (2022) in Toy Models of Superposition, models face an information bottleneck:
- Dimensional Bottleneck: A model layer with dimension can represent at most orthogonal vectors.
- Feature Sparsity: Most semantic concepts are sparse in natural language; only a small subset of features are present in any given context window.
- Non-Orthogonal Packing: By allowing slight interference (cross-talk) between features, a model can represent features within a -dimensional space.
While superposition maximizes parameter efficiency during pre-training, it renders raw neuron activations uninterpretable to human observers. Examining neuron activations directly provides only entangled combinations of disparate concepts.
Mathematical Formulation of Sparse Autoencoders
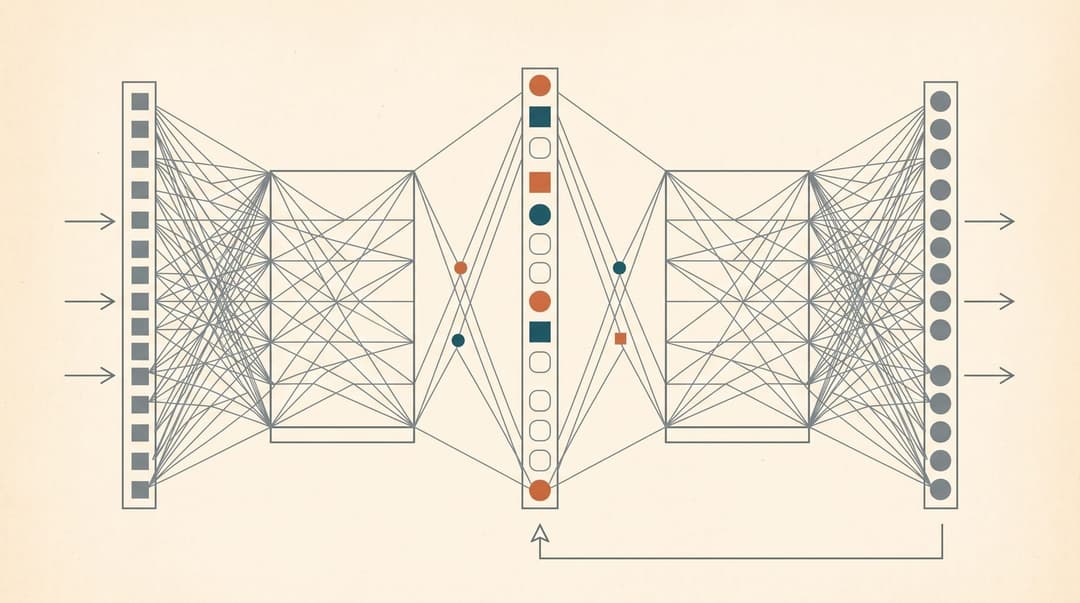
A Sparse Autoencoder is an unsupervised neural network with an overcomplete hidden layer trained to reconstruct the intermediate activations of a frozen language model.
Given an internal activation vector extracted from the transformer residual stream or MLP output:
1. Encoder Mapping
The encoder projects the -dimensional activation vector into a higher-dimensional latent dictionary of size , where (with expansion factor typically ranging from to ):
f(x) = ReLU(W_enc * (x - b_dec) + b_enc)Where:
- is the learned encoder weight matrix.
- is the encoder bias.
- is the geometric center of the activation distribution (decoder bias).
- The non-linearity ensures non-negative feature activations.
2. Decoder Reconstruction
The decoder reconstructs the original activation vector as a linear combination of feature dictionary vectors:
x_hat = W_dec * f(x) + b_decWhere:
- is the dictionary matrix whose columns represent individual feature directions.
- Each column vector is constrained to unit norm () to prevent arbitrary feature scale shifts between encoder and decoder weights.
3. Loss Function and Sparsity Penalty
Standard Sparse Autoencoders are trained using a combined objective of reconstruction fidelity and sparsity regularization:
L(x) = ||x - x_hat||_2^2 + λ * ||f(x)||_1The mean squared error () ensures the autoencoder faithfully reconstructs the transformer's internal state. The penalty () forces most latent feature activations to zero, ensuring that only a small number of monosemantic dictionary vectors explain the activation on each token.
Architectural Evolutions in Dictionary Learning
Standard -penalized SAEs suffer from systematic optimization challenges that have spurred several architectural refinements:
Top-K Sparse Autoencoders
In Scaling and Evaluating Sparse Autoencoders, Gao et al. (2024) demonstrated that penalties introduce shrinkage bias: the regularization constantly penalizes feature magnitudes, causing the autoencoder to systematically underestimate activation values.
Top-K SAEs eliminate the loss entirely. Instead, they apply a TopK activation function directly to the pre-activations:
f(x) = TopK(W_enc * (x - b_dec) + b_enc, k)By explicitly retaining only the highest activations per token and setting all other components to zero, Top-K SAEs decouple sparsity enforcement from activation magnitude estimation, producing superior reconstruction-sparsity Pareto frontiers and simplifying hyperparameter tuning.
JumpReLU and Gated SAE Architectures
To address false positive activations without shrinking true signal, Rajamanoharan et al. (2024) introduced JumpReLU Sparse Autoencoders. JumpReLU applies a learned, discontinuous threshold to each latent dimension:
JumpReLU(z, θ) = z if z > θ else 0By training with straight-through estimators, JumpReLU SAEs achieve higher reconstruction fidelity at equivalent sparsity levels compared to vanilla ReLU autoencoders.
Monosemanticity, Scaling, and Causal Steering
When trained on production models, SAE latents map directly to coherent semantic concepts. In Towards Monosemanticity and Scaling Monosemanticity, Anthropic demonstrated dictionary learning across small transformers and production models such as Claude 3 Sonnet.
Key findings include:
- Semantic Coherence: Individual features activate exclusively for precise conceptual domains, including security vulnerabilities (e.g., buffer overflows, SQL injection), geographical landmarks, bias indicators, and abstract reasoning patterns.
- Multilingual Generalization: Concept features often activate across languages for the same underlying semantic meaning (e.g., a "bridge" feature activating for English, Spanish, and Chinese references).
- Causal Feature Steering: Intervening on latent activations validates that features are causally active rather than passive correlations. Artificially clamping a feature's activation magnitude during generation directly steers the model's output toward that specific topic, while suppressing safety-critical features can eliminate specific toxic or deceptive behaviors.
Operational Bottlenecks and Limitations
Deploying and training Sparse Autoencoders at scale presents distinct engineering hurdles:
Dead Latents
During training, a substantial fraction of dictionary features can become dead, meaning their pre-activations never cross the activation threshold across the training corpus. Addressing dead latents requires specialized techniques such as neuron resampling, ghost gradients, or warm-start initializations.
Feature Splitting
As the dictionary expansion factor scales from to , features do not simply multiply; they split into hierarchical sub-concepts. A broad "programming" feature in a small SAE divides into specialized features for Python error handling, memory allocation in C, and async functions in TypeScript in a larger SAE. Managing this feature hierarchy requires multi-scale interpretability tooling.
Downstream Reconstruction Loss
Replacing true internal activations with reconstructed activations in a running transformer results in a measurable increase in cross-entropy loss. While state-of-the-art SAEs recover over 90% to 95% of model loss, the remaining reconstruction error currently limits their direct use as zero-overhead runtime guardrails.
Summary
Sparse Autoencoders provide a principled, unsupervised methodology for resolving superposition in deep neural networks. By transforming entangled polysemantic neurons into overcomplete, sparse, and monosemantic dictionaries, SAEs establish a rigorous foundation for safety auditing, mechanistic interpretability, and causal steering in modern large language models.
Sources
- Towards Monosemanticity: Decomposing Language Models with Dictionary Learning (Bricken et al., 2023)
- Scaling Monosemanticity: Extracting Interpretable Features from Claude 3 Sonnet (Templeton et al., 2024)
- Scaling and Evaluating Sparse Autoencoders (Gao et al., 2024)
- Toy Models of Superposition (Elhage et al., 2022)
- Jumping Ahead: Improving Reconstruction Fidelity with JumpReLU Sparse Autoencoders (Rajamanoharan et al., 2024)
