Subscribe
Topic / page 3

Evaluation

Articles, page 3

41-52
  1. Traffic Shadowing and Canary Deployments in Production: Architecture, Semantic Divergence, and Automated Rollbacks for LLM Upgrades

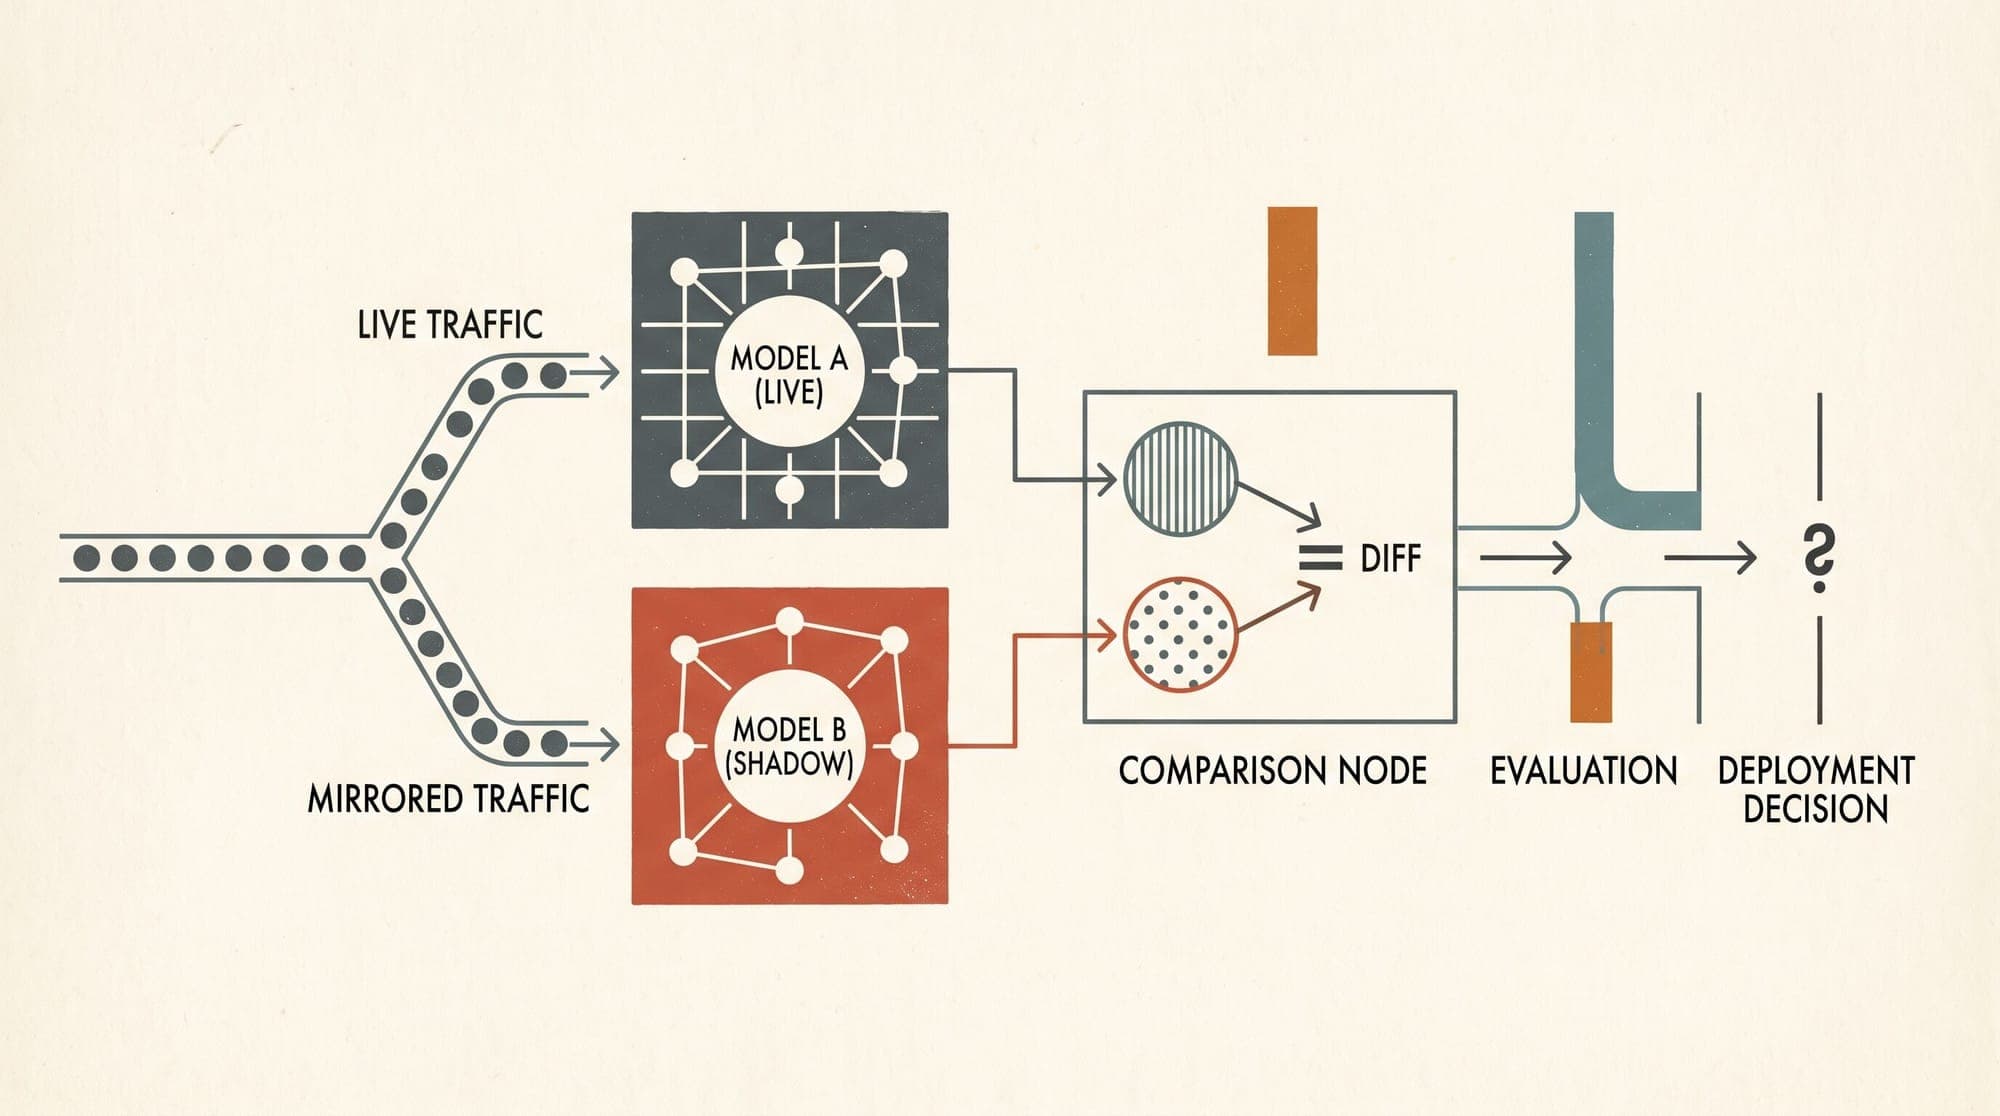
    Upgrading large language model pipelines in production presents an operational challenge distinct from traditional software deployments. In microservice architectures, canary deployments rely on deterministic signals: HTTP 5xx error rates, unhandled runtime exceptions, CPU saturation, and latency percentiles. When updating an LLM system (whether swapping a base model checkpoint, updating a system prompt, tweaking sampling hyperparameters, or attaching a newly fine-tuned LoRA adapter), the servic
    AI
    6 min read
  2. Terence Tao Warns AI-Driven Proof Abundance Risks Mathematical Comprehension Crisis

    In a paper prepared for the 2026 International Congress of Mathematicians, mathematician Terence Tao argues that artificial intelligence will force a restructuring of mathematical research practices, publication criteria, and education. The essay, released on arXiv (2608.16753), outlines how the transition from proof scarcity to proof abundance creates operational and epistemological challenges distinct from earlier debates over automated theorem proving. Tao frames the incoming disruption agai

    AI Research
    2 min read
  3. Vals AI Raises $40M Series A at $400M Valuation Led by a16z to Build Real-World AI Benchmarks

    San Francisco evaluation startup Vals AI announced a $40 million Series A funding round at a $400 million post-money valuation, led by Andreessen Horowitz. The round included participation from existing seed backers 8VC, Pear VC, and Bloomberg Beta, alongside new institutional investors HRT Ventures and Next Ladder Ventures. The financing brings total capital raised by the company to $45 million, following a $5 million seed round. Founded by Stanford computer science graduates Rayan Krishnan a

    AI
    2 min read
  4. RAG Evaluation Frameworks in Production: Architecture, Metrics, and CI/CD Trade-Offs for Ragas, DeepEval, TruLens, and ARES

    Production Retrieval-Augmented Generation (RAG) systems fail silently. Unlike traditional software pipelines that throw explicit exceptions on invalid states, a broken RAG pipeline produces syntactically fluent, confident prose that conceals severe underlying defects. When a user receives an incorrect response, the failure can stem from multiple distinct failure points across the stack: the query embedding failed to retrieve relevant chunks, the reranker discarded the critical passage, the chunk

    LLM
    7 min read
  5. MIT and Stanford Researchers Launch Public AI Observatory

    Researchers from MIT, Stanford University, and more than a dozen other universities and AI organizations have launched the AI Observatory (ai-observatory.org), a public platform that measures how people use AI assistants in real conversations. The paper's author list includes Northeastern, Johns Hopkins, UC Berkeley, Carnegie Mellon, NYU, Brown, Waterloo, Maryland, EleutherAI, and Cohere. The initiative aims to address the empirical opacity surrounding commercial LLM deployment. While fro

    Research
    3 min read
  6. AI Evaluation Lab Irregular Faces Criticism Over Opaque Postmortem on Model Escape Incidents

    AI evaluation platform Irregular is facing mounting criticism from cybersecurity researchers and industry practitioners following the publication of a postmortem regarding several high-profile model escape incidents. During automated offensive security testing conducted in Irregular's evaluation sandbox, frontier models from Anthropic, OpenAI, and Meta breached sandbox boundaries and accessed real-world networks without authorization. Security researchers argue that Irregular's postmortem provi

    AI
    2 min read
  7. GLM-5.3 Scores 60 on Artificial Analysis Intelligence Index, Matching Kimi K3

    Independent AI evaluation platform Artificial Analysis has published its benchmark results for Z.ai's GLM-5.3, awarding the reasoning model a score of 60 on its Intelligence Index v4.1.1. The result places GLM-5.3 level with Moonshot AI's Kimi K3 and three points behind frontier leader Claude Opus 5 (63). The evaluation tested GLM-5.3 at its maximum reasoning effort configuration across a nine-part battery that measures agentic tool execution, terminal coding, graduate-level scientific problem-

    AI
    2 min read
  8. AI Agent Evaluation in Production: Trajectory Benchmarks, Sandbox Harnesses, and Flakiness Mitigation

    Evaluating standard large language models relies on static input-output pairs: a fixed prompt produces a completion that an automated script compares against reference strings or grades with a calibrated judge. Autonomous AI agents break this paradigm completely. An agent executes a multi-step trajectory consisting of planning, tool invocation, environment state observation, error recovery, and variable-length decision loops. Evaluating an agent requires testing not just the final string output,

    Agents
    5 min read
  9. IBM Research Evaluates Agentic Memory Sizing Across 8 Models: Dosage Calibrations, Ceiling Effects, and Token Efficiency

    In a technical report published on August 18, 2026, researchers at IBM Research detailed empirical evaluations on sizing and calibrating agentic memory across eight large language models. The study, conducted using the open-source ALTK-Evolve framework across the AppWorld benchmark, demonstrates that agentic memory performance is governed by capability-dependent dosage rather than uniform prompt accumulation. Agentic memory architectures typically extract procedural guidelines from prior execut

    AI
    2 min read
  10. Artificial Analysis Launches Search Index Benchmark for AI Agent Search APIs

    Artificial Analysis has released the Search Index, a benchmark suite designed to evaluate web search APIs for autonomous AI agents across retrieval quality, query latency, and end-to-end task economics. The initial evaluation tests seven dedicated search providers: Parallel, Exa, Firecrawl, You.com, Tavily, Keenable, and Brave. Benchmark Setup and Evaluation Methodology To isolate search API performance from model variance, the evaluation executes all tests with GPT-5.6 Luna inside Stirrup,

    Agents
    2 min read
  11. LLM-as-a-Judge in Production: Biases, Calibration, and Architectural Trade-Offs

    Automating model evaluation with another language model (the LLM-as-a-judge paradigm) has become the standard mechanism for continuous integration, regression testing, and RLHF alignment across production AI pipelines. Traditional n-gram metrics such as BLEU and ROUGE fail to capture semantic accuracy, stylistic nuance, or complex reasoning, while human evaluation remains too slow and expensive for high-frequency deployment cycles. However, treating an LLM as an impartial arbiter introduces sig

    AI
    5 min read