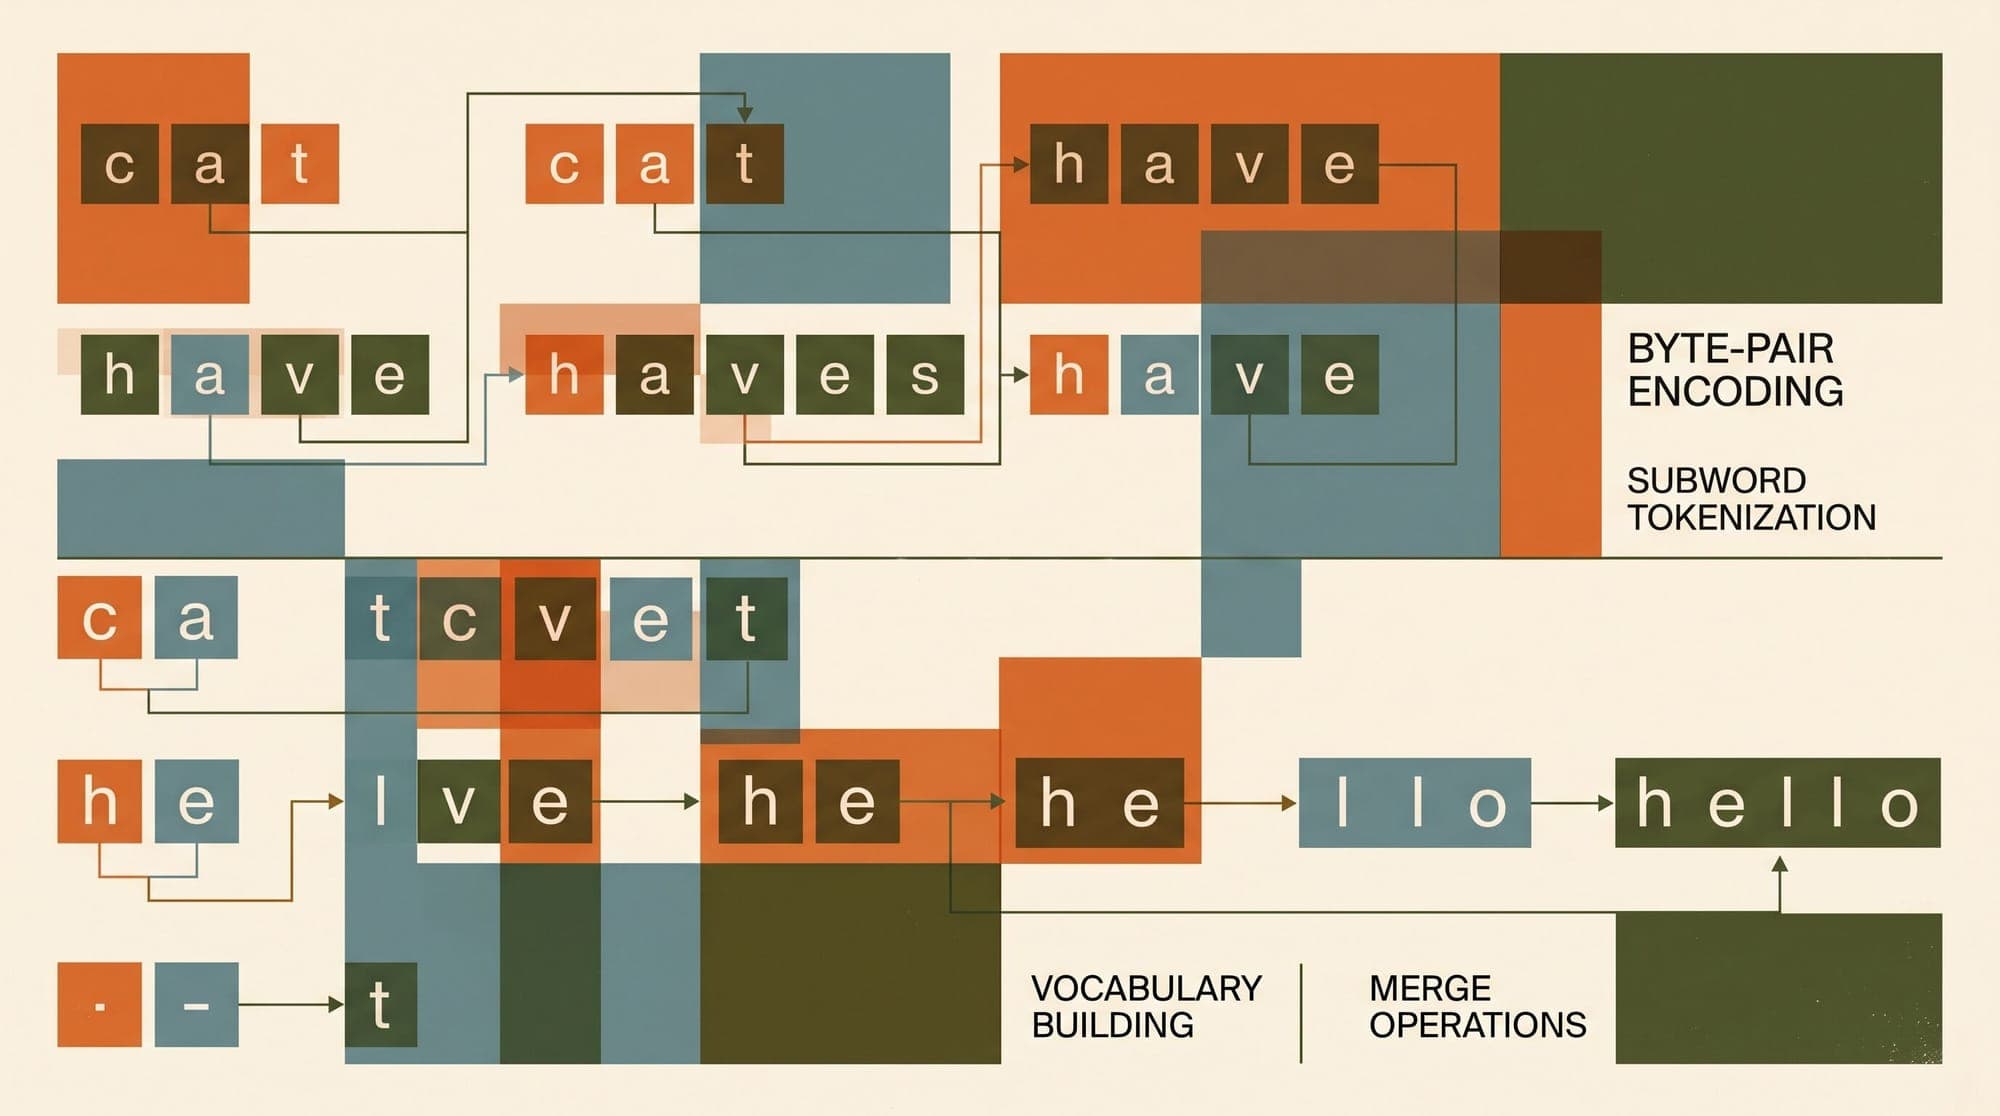
Byte-Pair Encoding (BPE) and Modern Subword Tokenization: Mathematical Foundations, Merge Dynamics, Byte-Level Encodings, and Vocabulary Compression Mechanics
Tokenization is the discrete boundary interface between raw textual sequences and the continuous vector representations of autoregressive large language models. Before an attention block computes a single inner product or a feed-forward network applies an activation function, an input string must be mapped into an ordered sequence of discrete integer identifiers drawn from a finite vocabulary $V$. The design and mathematical properties of this mapping govern key operational characteristics of l