
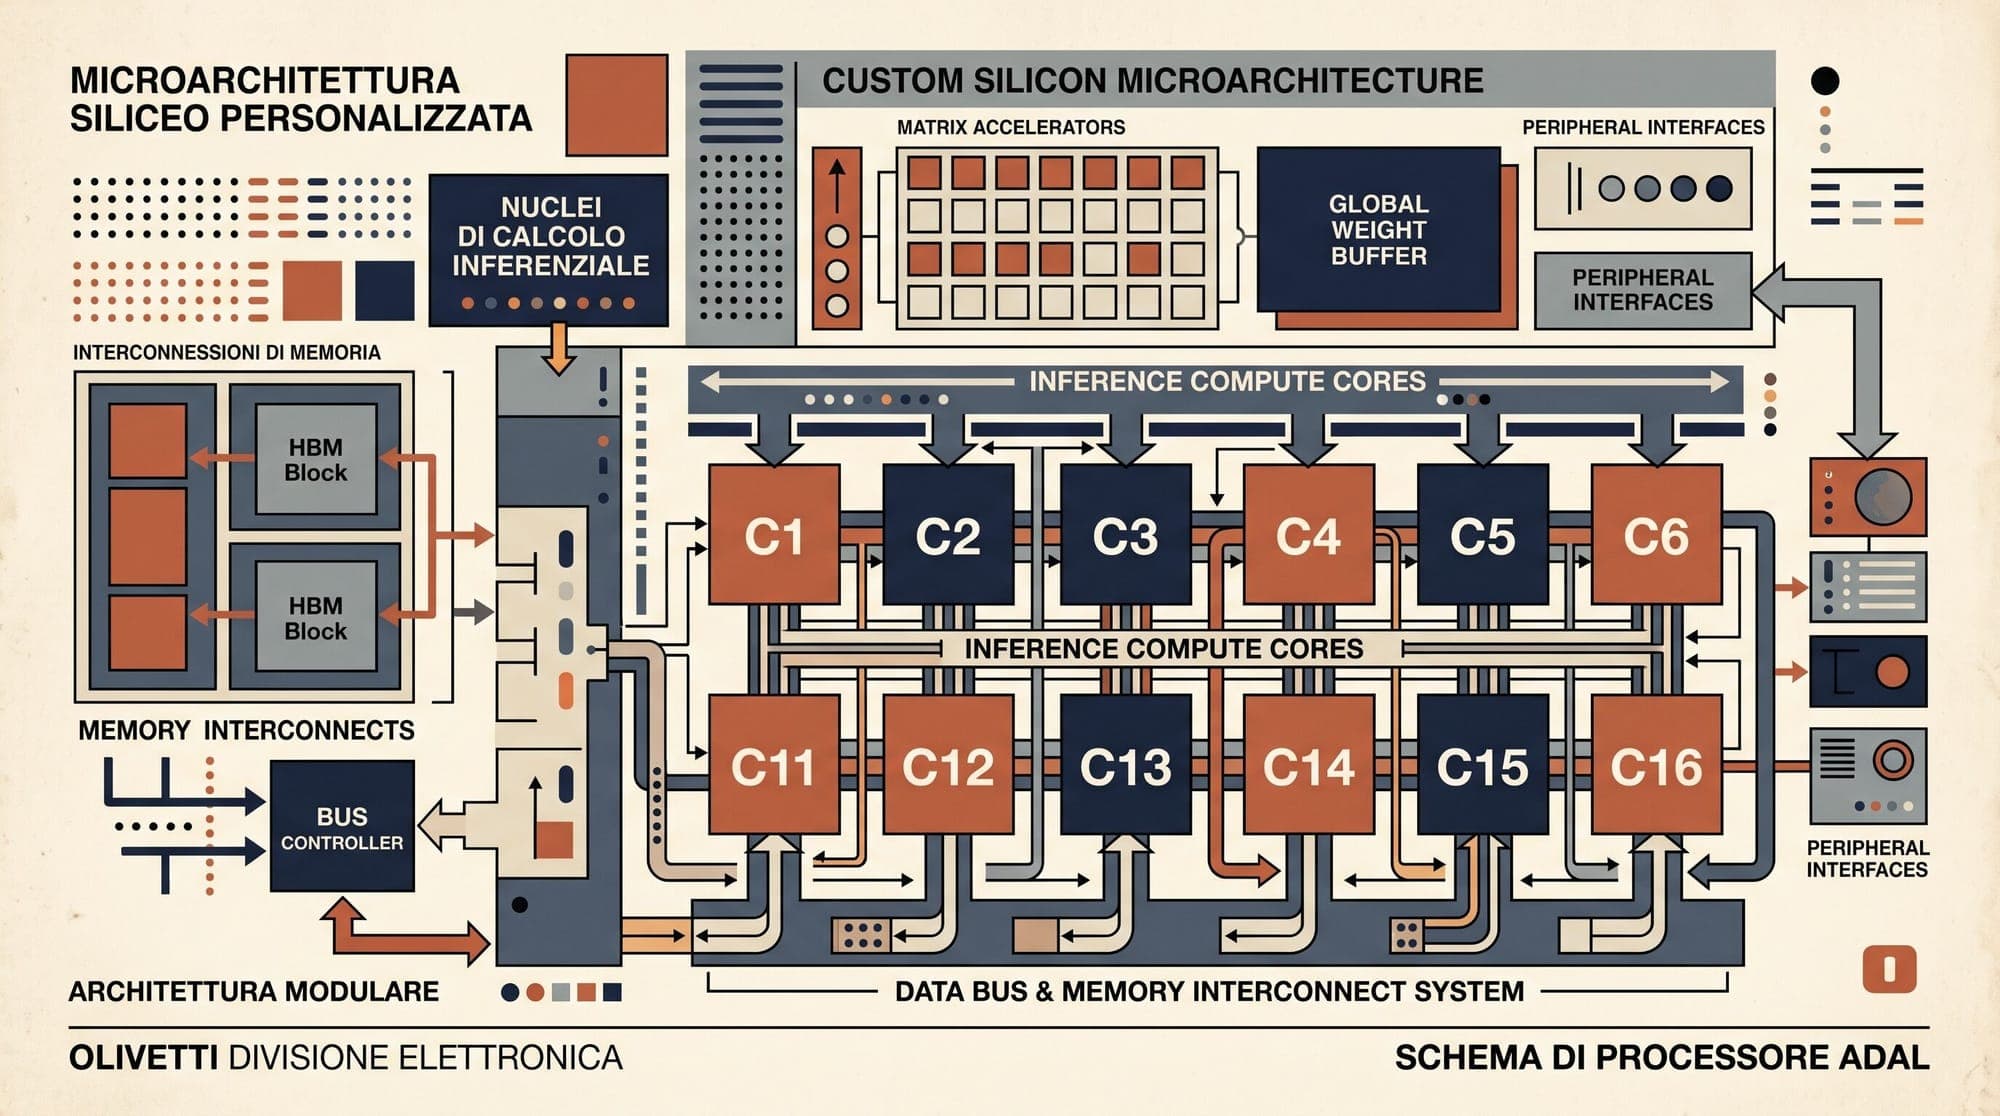
OpenAI presented the first architecture and benchmark disclosures for its custom inference chip, code-named Jalapeño, during the 37th Hot Chips conference. In published test data and technical disclosures, OpenAI reported that Jalapeño achieves 1.5x to 1.9x higher performance per watt and 1.7x to 3.6x lower end-to-end latency compared to Nvidia Blackwell GB200 and GB300 systems on production LLM workloads.
Developed in co-design partnership with Broadcom, Jalapeño represents OpenAI's initial hardware deployment aimed at reducing dependence on merchant GPU silicon for production inference serving.

Architectural Specifications and Power Envelope
Jalapeño was architected specifically for frontier autoregressive and mixture-of-experts (MoE) token generation workloads. Rather than adopting a rigid fixed-function ASIC layout, OpenAI designed a programmable architecture tailored to memory bandwidth bottlenecks and low-batch interactive serving.
Key hardware parameters disclosed by OpenAI include:
- Thermal Design Power (TDP): Rated at 700W maximum package power, with tested production runs maintaining sustained consumption at or below 550W.
- Serving Efficiency: 1.5x to 1.9x higher token throughput per watt at peak system capacity versus Nvidia GB200/GB300 baselines.
- Interactive Latency: 1.7x to 3.6x lower time-to-first-token (TTFT) and inter-token latency across multi-turn conversational evaluations.
- Interactive Workload Scaling: 2.1x to 4.1x performance advantages on bursty, low-concurrency user traffic profiles.
OpenAI highlighted that these latency and efficiency gains were recorded on native execution pipelines without mandating aggressive speculative decoding or disaggregated prefill-decode server topologies.
Model-Assisted Kernel Compilation via Astra and Codex
A central element of the Jalapeño hardware bring-up was the automated generation of low-level compute kernels using OpenAI's internal GPT-Astra and Codex models.
According to OpenAI's technical presentation:
- Kernel Synthesis: Automated model pipelines wrote, tested, and optimized specialized assembly and low-level kernels for dense attention and sparse MoE routing blocks.
- Performance Speedup: AI-generated kernel implementations operated 1.5x to 1.8x faster than kernels written by human performance engineers.
- Model Porting: The automated kernel pipeline enabled OpenAI to port three unscheduled open-weight foundation model architectures to full performance on Jalapeño within two months.
Datacenter Roadmap and Silicon Iterations
OpenAI stated that initial datacenter deployments of Jalapeño hardware will commence before the end of 2026. These systems will handle internal inference workloads and production API traffic alongside existing GPU infrastructure.
The organization confirmed that its second-generation processor (Gen 2) is currently in advanced physical design, with architectural research underway for third-generation silicon (Gen 3).



