
Google made Gemini 4 Argon generally available on October 13, in the Gemini API and AI Studio, for Pro and Ultra subscribers in the Gemini app and AI Mode in Search, and for Ultra subscribers in Google Antigravity. The launch price is $2 per million input tokens and $10 per million output tokens. Google Cloud's post says that rises to $4 and $20 after November 30. This roundup covers developer reactions on Hacker News, X and blogs from the October 13 launch through October 19. The loudest topics are the price, a hallucination score people keep citing, and usage limits that run out fast.
Most of the discussion sits in the Hacker News launch thread, which had 1,466 points and 1,045 comments when we checked, and in a long tail of X posts about quotas in Antigravity and the Gemini app.
Price: cheap for now, then Opus money
The most-cited summary of the price came from simonw on Hacker News:
"Pricing is interesting. At launch Argon is the same price as GPT-6 Sol, half the price of Claude Opus 5.5 and 1/5th the price of Claude Fable 5.1 and GPT-6 Astra. But on December 1st Argon doubles in price - so it will be the same price as Opus 5.5."
The list prices back him up. OpenAI's rate card puts GPT-6 Astra at $10 input and $50 output per million tokens, and GPT-6 Sol and GPT-6.1 Sol at $2 and $10. Anthropic lists Claude Opus 5.5 at $4 and $20. Some people were annoyed that the post-promo price wasn't easier to find. damsta asked: "Couldn't you just say what the price will be after the introductory period and when it'll take effect?" On X, @Cozy2054934 put it plainly: "Run your own evals on it before December, not after."
Plenty of people still read it as a bargain. gigatexal wrote: "Going to take a lot for me to move from subsidized Claude opus 5.5 … this Google model is very cheap though."
Praise: writing, explanations, and a Google-is-back mood
The warmest reviews were about answers and prose, not code. svara ran recent research questions through Argon that they had first asked Claude: "This is a clear step change, I'm genuinely amazed. Its answers are to-the-point, logically structured, clearly written." Macuyiko called it "Very fun model to spar with, clever, intelligent. On par with Opus 5.5 but without the Claudism's and more of a Sol type of conversation."
protoman3000 praised the writing and was blunt about the code: "Of all models I like to write with Gemini the most." Then, at the end: "The code is bad though." Even @Gegam245074, whose first-impressions thread was mostly negative, said Argon "holds an incredibly lively conversation, sometimes indistinguishable from a real person".
Some coders came away happy too. @SeHozaifa wrote that "The model is crazy good for coding, but the usage limit runs out way too fast."
Complaint one: usage limits
At launch, Argon in Antigravity was for Ultra subscribers only, not Google AI Pro. That set the tone. dcchambers wrote: "I can use Opus 5.5 and Sol/Astra on the $20 Anthropic and OpenAI plans." redox99 was shorter: "Only available in the $100 plan, and it's worse than Opus 5.5? Why would you ever buy this?"
Once Pro users got access, the complaints shifted to how quickly the quota drained. A Tell HN post by bb88 was titled "Google Argon on a Pro subscription is worthless" and said "one prompt which took 5 minutes of clock time, used 50% of the resources of a Pro account for the 5 hour window." blurbleblurble went further up the price ladder: "I tried it out and ran out of weekly usage on a $200 plan within a day."
On X, @naveen_saradhi_ posted "WHAT? GEMINI 4 ARGON usage limit , with 3 prompts weekly limit 16% wipe out , anyone have the same issue?" and got 267 likes. @_Dev_Arora__ compared plans directly: "Preliminary number show you get about 17x the usage with Opus 5.5 and about 7x the usage with GPT-6 Astra if you have Claude Pro plan or ChatGPT Plus plan." @Aditya_cuz00 summed up the mood: "gemini argon: weekly quota gone in 1 hour".
Reddit tells the same story. Tech City Authority collected r/GeminiAI reports of single Argon prompts on the High thinking setting using 16% to 48% of a Pro user's allowance. It noted these are individual, unverified reports.
Two explanations are going around. Google's Logan Kilpatrick said on launch day that "Argon is as \"big model smell\" as it comes, so limited on our ability to serve it widely". @sususu9998 suspects a metering bug: "Google Antigravity has a quota accounting bug on Gemini 4 Argon: it ignores the 95% implicit cache discount and bills cached tokens as 100% full input, draining the $200/mo Ultra weekly limit ~7x faster than it should." That is one user's analysis of their own telemetry. Google hasn't confirmed it. @StatsWire later reported that Antigravity "just pushed a global weekend quota reset across all Gemini 4 Argon and Gemini 3.8 Flash pools."
Complaint two: is the hallucination score real?
Argon's best-known number is a 15% hallucination rate on Artificial Analysis's AA-Omniscience benchmark. It comes up all over X. @Cozy2054934 called it "the lowest of any model scoring 45+." @ANMOLSAINII added the caveat that most replies picked up: "But its accuracy was 50%." @gnotnuk put the skeptical version briefly: "the secret to not hallucinating is saying less".
Many hands-on reports didn't match the number. @Gegam245074, in a thread with 349 likes, wrote: "Hallucinations haven't gone anywhere." @Workerbee3d1 compared it with Opus 5.5 on a work project and reported "the standard hallucinations, like confidently pointing to code that didn't exist", plus a worse problem: "At one point it even wrote a test that couldn't possibly fail, and flat-out admitted to doing it when I asked." @MartinezSo25073 wrote: "I think its weird how they said it has a low hallucination rate."
Not everyone disagreed. @v79842 described an auditor Argon built that "'approved' a quote that didn't exist", and still concluded: "Still, Gemini 4 hallucinates a lot less and continues to impress."
Tests people ran
Independent results are mixed. Argon does well on knowledge and vision tasks and trails Opus 5.5 and GPT-6 Astra on several coding tests.
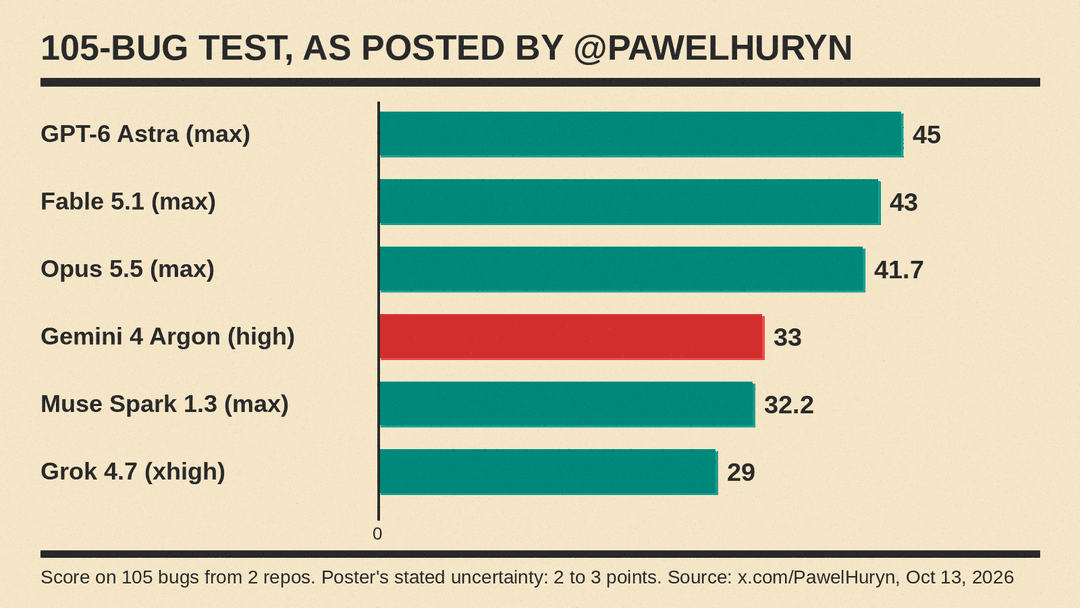
- @PawelHuryn ran 105 bugs from two repos that "frontier models missed in Q1 2026." His reported scores: GPT-6 Astra (max) 45, Fable 5.1 (max) 43, Opus 5.5 (max) 41.7, Gemini 4 Argon (high) 33, Muse Spark 1.3 (max) 32.2, Grok 4.7 (xhigh) 29. He gives the uncertainty as 2 to 3 points and still wrote "Looks like the Google is back."
- @bidyut_io tested one feature in a production Python backend, with GPT-6 Astra as judge: "opus 5.5 (extra high): 77/100 gemini 4 argon (high): 59/100".
- ariwilson ran 11 small bug fixes from their own projects. Argon "solved 10 of 11", but a median run cost "$0.52 vs $0.18 for Sonnet and $0.09 for Sol". They added: "It thinks a ton, ~24k output tokens a run vs ~3k for Sonnet."
- @homoudalmonawer pointed out two results that don't agree. Argon "scored 21% on Every's senior-engineer benchmark," while "Cursor put it at 52.8% on CursorBench at default effort, on par with Opus 5.5."
- dom96 posted an adversarial programming language test: Claude Opus 5.5 58.7%, Gemini 4 Argon 47.1%, Claude Fable 5.1 46.7%.
- chriddyp of Plotly ran a 23-question data analytics exam and reported the "Same price and score as Opus 5.5", while cheaper models reached "about the same results but for ~1/10th the cost."
- @ultralytics said Argon "ranked #1 in auto-annotation accuracy with 0.565 mAP50" across 36 object detection datasets. simedw reported "0.504 mAP zero-shot" on a COCO object detection benchmark.
Open questions
- Is the quota problem a bug, a policy, or a capacity limit? Google hasn't said how many Argon prompts any plan includes, and it hasn't answered the cache-billing theory in public.
- Does the hallucination score hold up in agent work? The 15% figure comes from a knowledge benchmark. The worst reports come from coding agents that claim work is done when it isn't.
- Is it worth it after December 1? At $4 and $20, Argon costs the same as Opus 5.5 per token. Several testers say it also uses more tokens per task.
Why it matters
Argon is Google's first Gemini 4 model, and developers are clearly willing to switch. Many said they would move work from Claude or ChatGPT if the limits allowed it. So far the reactions are less about raw capability and more about access. People like the writing and the knowledge answers, they disagree about the coding, and they agree the usage limits are too tight. For anyone choosing a model this month, the practical advice from the threads matches @Cozy2054934's: test it on your own work while the launch price lasts, and watch how fast it uses your quota.
Sources
- Google: Gemini 4 Argon is now available for everyone
- Google Cloud: Gemini 4 Argon available on Google Cloud
- Anthropic: Claude Opus 5.5
- OpenAI: ChatGPT rate card
- Hacker News: Gemini 4 Argon launch thread
- Hacker News: Tell HN: Google Argon on a Pro subscription is worthless
- Tech City Authority: Gemini 4 Argon users say limits run out after a few prompts
- The Batch: Argon, a low-hallucination model built for knowledge work
- Artificial Analysis: Gemini 4 Argon model page
- @PawelHuryn on X: 105-bug test
- @Gegam245074 on X: first impressions
- @OfficialLoganK on X: serving capacity
- @sususu9998 on X: quota accounting report
